TL;DR:摘要:
A good data foundation that is ready for use by AI agents is essential when it comes to getting more accurate and efficient AI answers for your business questions. The AI Readiness Score measures how prepared your data is for AI-powered features like Cortex Code (CoCo) and CoWork, and provides concrete recommendations on how to improve your readiness. Run /ai-readiness-score in CoCo CLI or Snowsight in Cloud agents mode to try it.若要让 AI 针对您的业务问题提供更准确、更高效的回答,构建一个可供 AI 智能体直接使用的良好数据基础至关重要。“AI 就绪度评分”(AI Readiness Score)用于衡量您的数据为 Cortex Code (CoCo) 和 CoWork 等 AI 功能所做的准备程度,并提供改进就绪度的具体建议。您可以在 CoCo CLI 或 Cloud 智能体模式下的 Snowsight 中运行 /ai-readiness-score 来进行尝试。
Two factors that lead to AI readiness实现 AI 就绪的两个要素
We found that AI readiness boils down to two measurable dimensions:我们发现,AI 就绪度归结为两个可衡量的维度:
1. Are there good data assets for AI to use? We call these consumption-ready (CR) tables, the analyst-facing data sets that are actively queried, return results quickly, and contain fresh data. We identify them from behavioral signals: read volume, user diversity, BI tool consumption, query latency and data freshness.1. 是否存在可供 AI 使用的优质数据资产?我们将其称为“消费就绪”(CR)表,即分析师直接使用、查询活跃、结果返回迅速且数据新鲜的数据集。我们通过行为信号来识别它们:读取量、用户多样性、BI 工具消费情况、查询延迟和数据新鲜度。
2. Can AI find those tables and query them correctly? This is where semantic views come in. Semantic views encode the metadata AI needs to query your data correctly: primary keys, table relationships, business metrics, column descriptions and verified example queries. Without this semantic layer, AI is more likely to be guessing the table names, column names and the way to conduct joins and aggregations.2. AI 能否找到这些表并正确查询它们?这就是语义视图(Semantic views)的作用所在。语义视图编码了 AI 正确查询您的数据所需的元数据:主键、表关系、业务指标、列描述和经验证的示例查询。如果没有这一语义层,AI 更容易在猜测表名、列名以及如何进行连接和聚合时出错。
A high AI Readiness score means both conditions are satisfied: the right tables exist and AI has the structured metadata to use them correctly.高 AI 就绪度评分意味着这两个条件都已满足:既存在合适的表,AI 又拥有可正确使用这些表的结构化元数据。
How the score works评分原理
The AI Readiness Score combines three subdimensions:AI 就绪度评分结合了三个子维度:
| Dimension | What it measures |
|---|---|
| Demand Coverage | What percentage of your analytical queries land on consumption-ready tables (vs. raw/pipeline tables)? |
| Semantic View Coverage | What fraction of your consumption-ready tables have at least one semantic view defined over them? |
| Semantic View Quality | How complete are your semantic views — do they include primary keys, relationships, metrics, descriptions, and verified queries? |
The composite score combines demand coverage and SV readiness (itself a combination of coverage and quality) into a single 0–100 score. The scoring is designed so that a zero in any dimension — say, no semantic views at all — pulls the overall score down sharply.综合评分将需求覆盖率和语义视图(SV)就绪度(本身是覆盖率和质量的组合)合并为一个 0 到 100 的分数。评分设计使得任何一个维度的分数为零(例如完全没有语义视图),都会大幅拉低总分。
For consumption-ready table identification, we score tables on four behavioral dimensions (activity, consumption breadth, speed and freshness) and require that all conditions are reasonably satisfied. A table with millions of reads but 10-minute query times still won't qualify — the scoring penalizes any single weak dimension rather than letting strong dimensions mask it.对于消费就绪表的识别,我们根据四个行为维度(活跃度、消费广度、速度和新鲜度)对表进行评分,并要求所有条件都得到合理满足。一个拥有数百万次读取但查询时间长达 10 分钟的表仍无法达标——评分机制会惩罚任何单一的薄弱维度,而不是让强项掩盖弱项。
Semantic view quality is assessed across nine signals that measure how much structured metadata AI has to work with — from basic properties like primary keys and relationships to richer signals like verified example queries and descriptive column comments.语义视图质量通过九个信号进行评估,这些信号衡量 AI 可利用的结构化元数据量——从主键和关系等基本属性,到经验证的示例查询和描述性列注释等更丰富的信号。
How to improve your data如何改进您的数据
A score alone isn't useful. The framework classifies each schema's primary gap — the single dimension most limiting its AI readiness — and generates prioritized recommendations:仅有分数是不够的。该框架会对每个架构的主要短板(即限制其 AI 就绪度的最核心维度)进行分类,并生成优先改进建议:
| Primary Gap | What it means | Action |
|---|---|---|
| Build CR tables | Most analytical traffic hits raw or pipeline tables — AI has no suitable targets. | Improve table design in high-traffic schemas. For example, create pipelines to create aggregated tables. |
| Create semantic views | Consumption-ready tables exist but AI can't reason over them effectively. | Build your first semantic views on the highest-read tables. That helps AI to query from the right table with the right columns. |
| Expand SV coverage | Some semantic views exist but most CR tables remain uncovered. | Extend semantic view coverage on the most frequently queried tables that are not yet covered. |
| Improve SV quality | Semantic views are in place but structurally incomplete. | Enrich the existing semantic views. Add join relationships between tables, define business metrics (for example, SUM(revenue), COUNT(DISTINCT user_id)), and add verified queries: curated Q&A examples that directly validate AI output. |
Each recommendation surfaces the specific schemas, tables or semantic views to act on, ranked by analytical read volume so you tackle the highest-impact items first.每项建议都会列出需要处理的具体架构、表或语义视图,并按分析读取量进行排序,以便您优先解决影响最大的项目。
Does it work?它有效吗?
We tested the framework on our own internal analytics database — dozens of schemas, thousands of tables and the relative rankings align with the team's understanding of these schemas.我们在自己的内部分析数据库上测试了该框架——涵盖数十个架构、数千个表,其相对排名与团队对这些架构的理解是一致的。
One schema, containing SaaS connector metrics, initially scored 39/100. It had seven consumption-ready tables with strong analytical demand but zero semantic views. The framework's top recommendation was straightforward: create semantic views for these tables. After building SVs covering six of the seven tables, the score jumped to 82/100, along with better experiences using AI agents to answer business questions.其中一个包含 SaaS 连接器指标的架构最初评分为 39/100。它有七个消费就绪表,分析需求强劲,但没有任何语义视图。该框架给出的首要建议非常直接:为这些表创建语义视图。在为七个表中的六个构建了语义视图后,分数跃升至 82/100,同时使用 AI 智能体回答业务问题的体验也得到了改善。
Try it yourself亲自尝试
The AI Readiness Score is available as a CoCo skill. See here for more details.AI 就绪度评分作为一项 CoCo 技能提供。详情请见此处。
Skills are reusable workflows that extend CoCo's capabilities; invoke them with a slash command. Run it from the CLI or Snowsight in Cloud agents mode with /ai-readiness-score.技能是扩展 CoCo 功能的可复用工作流;通过斜杠命令调用它们。在 CLI 或 Cloud 智能体模式下的 Snowsight 中运行 /ai-readiness-score 即可。
Once the skill is invoked, it will first ask you to choose how much query history to scan, from a quick 10% sample for a fast preview to a full scan for maximum accuracy.调用该技能后,它首先会要求您选择扫描的查询历史范围,从用于快速预览的 10% 样本到用于最大准确性的全量扫描。
It then scans your account_usage schema to identify all actively read tables, scores each one for consumption readiness, and evaluates semantic views. Runtime scales with your account's query activity. In our internal testing on a large, active development account (~43,000 tables), this was completed in 30–40 minutes on a Medium warehouse; a 2X-Large warehouse reduced that by roughly 15%. Accounts with lower query volumes should see proportionally shorter runtimes.随后,它会扫描您的 account_usage 架构以识别所有被活跃读取的表,对每一张表进行消费就绪度评分,并评估语义视图。运行时间取决于您账户的查询活跃度。在我们对一个大型活跃开发账户(约 43,000 张表)的内部测试中,在中型仓库(Medium warehouse)上耗时 30-40 分钟;使用 2X-Large 仓库可缩短约 15% 的时间。查询量较小的账户运行时间会相应缩短。
Note that you need a role that has access to the views in account_usage. Also, part of the semantic view metadata (verified queries) is retrieved using SHOW commands, which means the results are role-dependent. Users with broader privileges will see more semantic views and get a more complete picture of their account's readiness.请注意,您需要拥有可访问 account_usage 中视图的角色。此外,部分语义视图元数据(经验证的查询)是通过 SHOW 命令检索的,这意味着结果取决于角色权限。拥有更广泛权限的用户将能看到更多的语义视图,并获得关于其账户就绪度的更完整视图。
When the analysis is done, the skill produces a self-contained HTML report that you can share with your team. Results are cached so subsequent runs complete quickly.分析完成后,该技能会生成一份独立的 HTML 报告,您可以与团队共享。结果会被缓存,以便后续运行能快速完成。
We'd love to hear how your account scores and which improvements move the needle most for your team.我们很期待了解您的账户评分情况,以及哪些改进对您的团队影响最大。
Example output输出示例
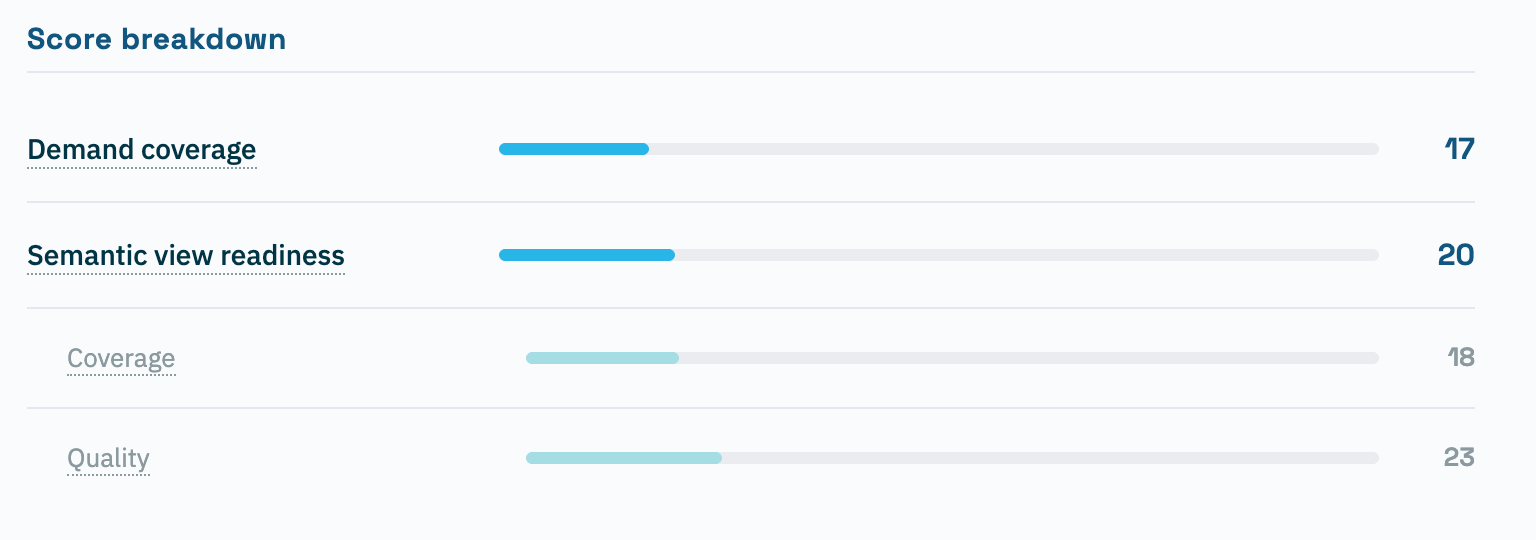
Below is an example report generated by the skill. The Score Breakdown section shows your composite score decomposed into its two primary dimensions, Demand Coverage and Semantic View Readiness, with SV Readiness further broken down into Coverage and Quality subscores, so you can see exactly where the gap is.以下是该技能生成的报告示例。“评分细分”(Score Breakdown)部分展示了您的综合评分如何分解为“需求覆盖率”和“语义视图就绪度”这两个主要维度,其中“语义视图就绪度”进一步细分为“覆盖率”和“质量”子分数,以便您准确找出差距所在。
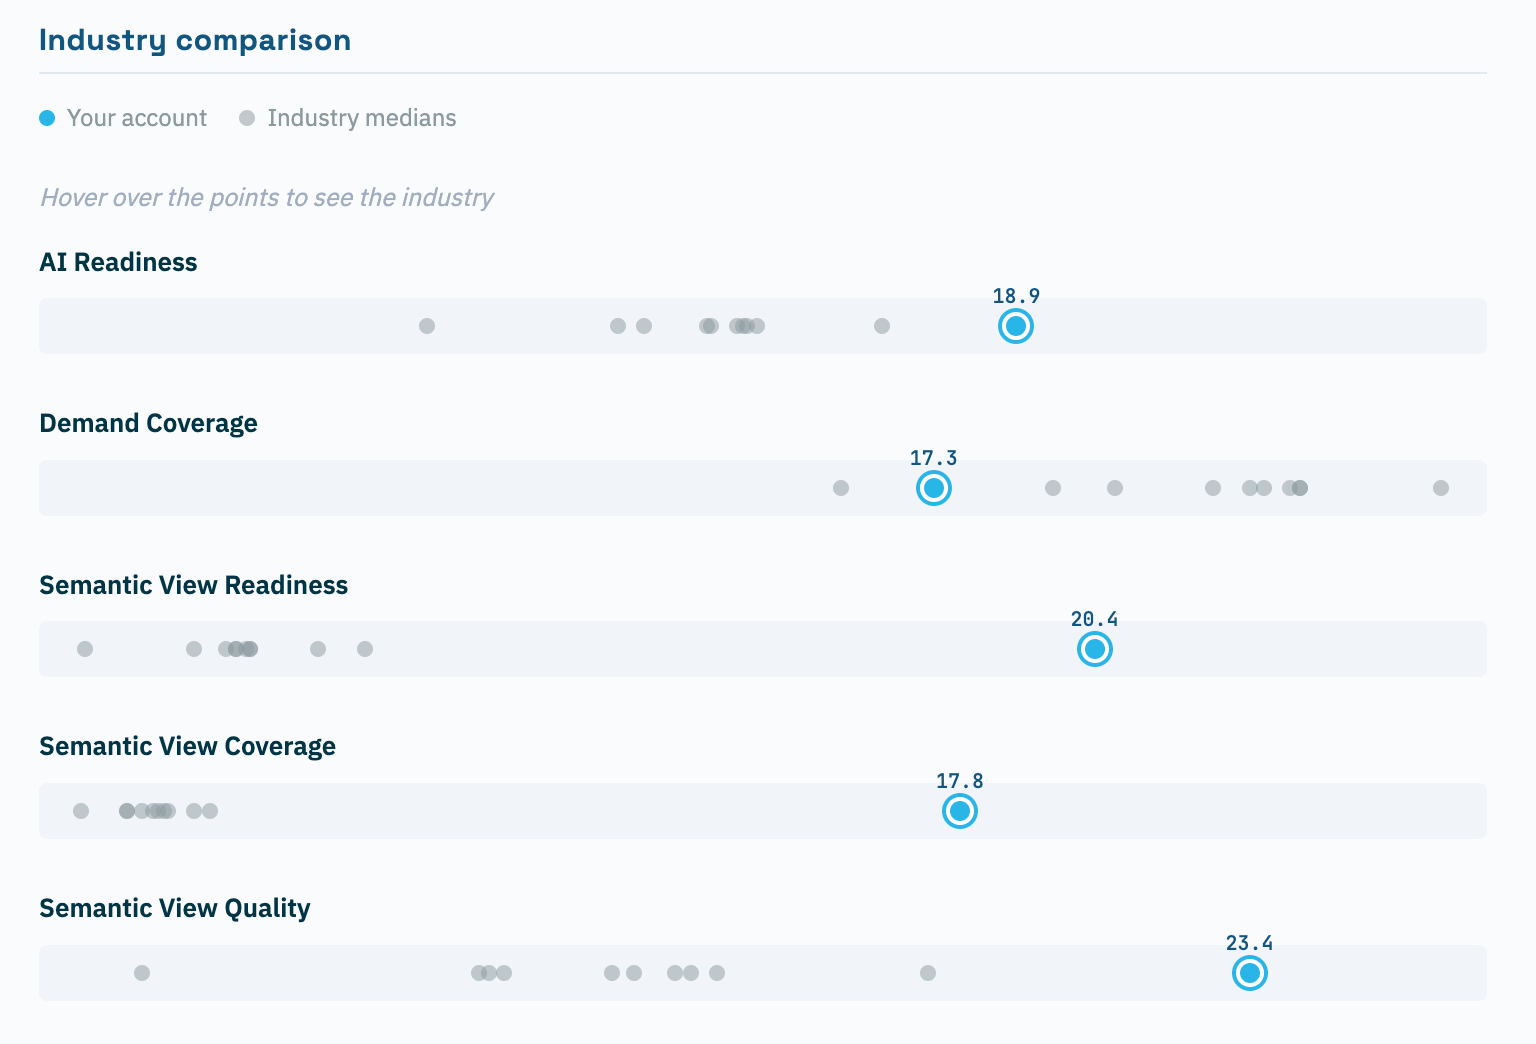
The Industry Comparison chart plots your account (blue) against the distribution of industry medians (gray), giving you a sense of where you stand relatively across each dimension.“行业对比”(Industry Comparison)图表将您的账户(蓝色)与行业中位数分布(灰色)进行对比,让您了解自己在各个维度上的相对位置。
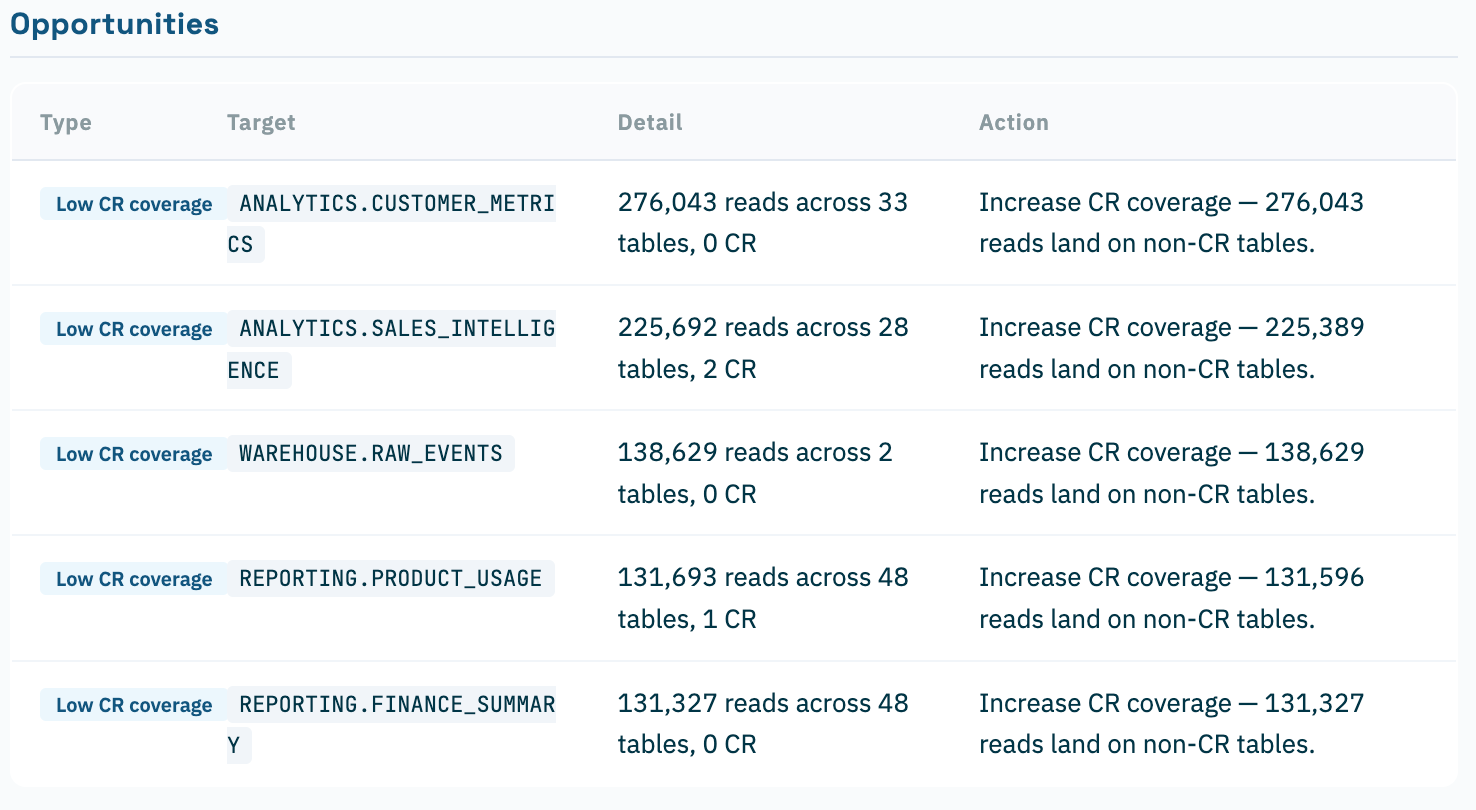
Finally, the Opportunities table is where the report gets actionable: It lists the specific schemas and tables ranked by analytical read volume, along with the gap type and a recommended action. In this example, the top opportunities are schemas with high read traffic but low CR table coverage — meaning most of those analytical queries are landing on tables that aren't suitable for AI, and that's where to focus first.最后,“机会”(Opportunities)表是报告中可操作性最强部分:它列出了按分析读取量排序的具体架构和表,以及差距类型和建议的操作。在此示例中,首要机会是那些读取流量高但 CR 表覆盖率低的架构——这意味着大多数分析查询都落在了不适合 AI 的表上,这正是您首先需要关注的地方。
Appendix附录
Data sources数据源
The skill queries the following views from SNOWFLAKE.ACCOUNT_USAGE:该技能查询 SNOWFLAKE.ACCOUNT_USAGE 中的以下视图:
| View | Used for |
|---|---|
ACCESS_HISTORY |
Per-table read counts, read-only detection, distinct user counts |
QUERY_HISTORY |
Query type, execution time, error filtering, warehouse detection |
SESSIONS |
Client application name (BI tool classification) |
TABLES |
DDL freshness (last_altered) |
SEMANTIC_VIEWS |
List of live semantic views |
SEMANTIC_TABLES |
Table-level signals: primary keys, unique keys, distinct ranges, synonyms |
SEMANTIC_DIMENSIONS |
Dimension-level synonyms and comments |
SEMANTIC_FACTS |
Fact-level synonyms and comments |
SEMANTIC_METRICS |
Metric existence, synonyms, and comments |
SEMANTIC_RELATIONSHIPS |
Relationship presence between tables |
Verified query counts are retrieved via SHOW SEMANTIC VIEWS commands, which are role-scoped: users with different roles will see different semantic views and may get different verified query counts. For the most accurate results, run the skill with a role that has visibility into all semantic views in your account.经验证的查询计数是通过 SHOW SEMANTIC VIEWS 命令检索的,该命令受限于角色:拥有不同角色的用户将看到不同的语义视图,并可能获得不同的经验证查询计数。为获得最准确的结果,请使用有权查看账户中所有语义视图的角色来运行该技能。
Improving a semantic view: before and after改进语义视图:前后对比
The SV quality score is built from nine signals. Here is a synthetic example showing how to go from a minimal semantic view to a well-enriched one.语义视图质量评分由九个信号构成。以下是一个合成示例,展示了如何从一个极简的语义视图转变为一个内容丰富的视图。
Before — minimal, low-quality score:改进前——极简,低质量评分:
This view scores low: no primary key, no relationships, no metrics, no synonyms, no verified queries and no column descriptions.该视图评分较低:没有主键、没有关系、没有指标、没有同义词、没有经验证的查询,也没有列描述。
After — enriched, high-quality score:改进后——丰富,高质量评分:
Each addition maps to a quality signal: primary key, synonyms, relationships, metrics, verified queries, and column comments all contribute to the score. Of these, verified queries carry the most weight — they are curated question-and-answer pairs that directly validate AI output. Even two or three verified queries per semantic view meaningfully improve the quality score.每一项添加都对应一个质量信号:主键、同义词、关系、指标、经验证的查询和列注释都会对分数做出贡献。其中,经验证的查询权重最高——它们是直接验证 AI 输出的精选问答对。即使每个语义视图只有两到三个经验证的查询,也能显著提高质量评分。