Jul 28, 2026/26 min readData Engineering
An Architect's Guide to Multi-Engine Lakehouses: What's Solved and What Isn't

Everyone in the data industry has heard the lakehouse pitch by now. Store your data once in an open format; attach any engine to it, depending on the job; swap compute in and out as requirements evolve; and retire the endless cycle of ETL between siloed systems. The benefits, when this is working, are concrete: no data duplication or synchronization headaches; the freedom to use specialized engines for different workloads rather than forcing everything through one tool; governance over a single copy of data, rather than auditing access sprawled across multiple systems; and meaningful insurance against the future. When your data is in an open format, new engines, vendor acquisitions, pricing changes and better tools for specific workloads all become compute decisions, not data migrations. It's a compelling vision. We completely agree with it.数据行业的每个人现在都听过“湖仓一体”(lakehouse)的推介:将数据以开放格式存储一次;根据任务需求挂载任意引擎;随着需求演变灵活切换计算资源;并终结在孤立系统间进行 ETL 的无尽循环。当这一模式运作良好时,其益处是实实在在的:没有数据重复或同步带来的头痛问题;可以自由地为不同工作负载使用专用引擎,而不必强迫所有任务都通过单一工具处理;能够对单一数据副本进行治理,而非在多个系统中审计分散的访问权限;并为未来提供了有效的保障。当数据采用开放格式时,新的引擎、供应商收购、定价变更以及针对特定工作负载的更优工具,都将成为计算层面的决策,而非数据迁移。这是一个令人信服的愿景,我们完全认同。
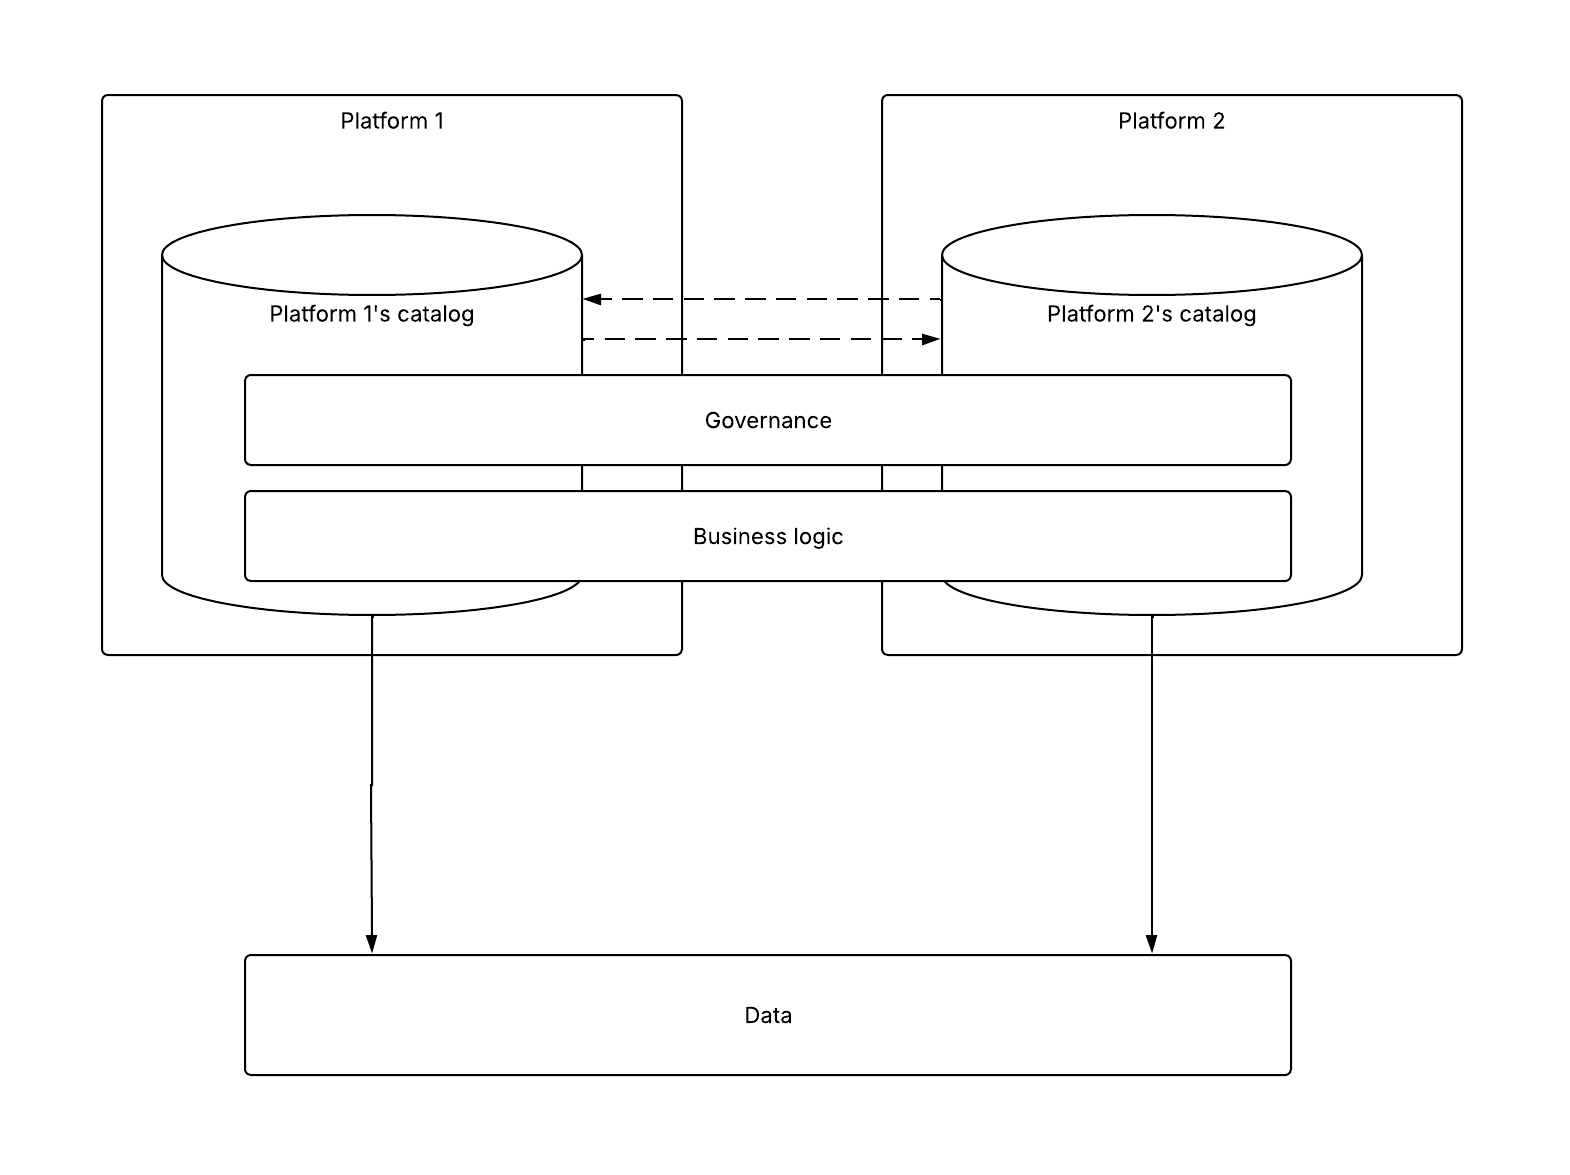
And the good news is that the industry has made real, meaningful progress toward it. For the first time, we can genuinely see that the era of siloed systems — where every new tool means a new pipeline and another copy of the data to maintain — is approaching its end. The promise of storing data once and having multiple engines read it is exactly why organizations are investing so seriously in lakehouse architectures right now. Thanks to Apache Iceberg™ and the broader open table format ecosystem, true data portability is possible. That's not a small thing. As Figure 2 shows, the shift from fully siloed platforms, with their own separate data stores, to a world where data is shared and engines sit on top of a common foundation significantly reduces the pains of data architectures that are based on copying data all the time.好消息是,整个行业已朝着这个愿景取得了切实且重大的进展。我们第一次真正看到,孤立系统时代——即每一个新工具都意味着一条新流水线和另一份需要维护的数据副本——正走向终结。存储一次数据并由多个引擎读取的承诺,正是各机构目前如此认真投资湖仓架构的原因。得益于 Apache Iceberg™ 和更广泛的开放表格式生态系统,真正的数据可移植性已成为可能。这意义重大。如图 2 所示,从拥有各自独立数据存储的完全孤立平台,转向数据共享且引擎构建于通用基础之上的世界,显著减轻了基于频繁数据复制的数据架构所带来的痛苦。
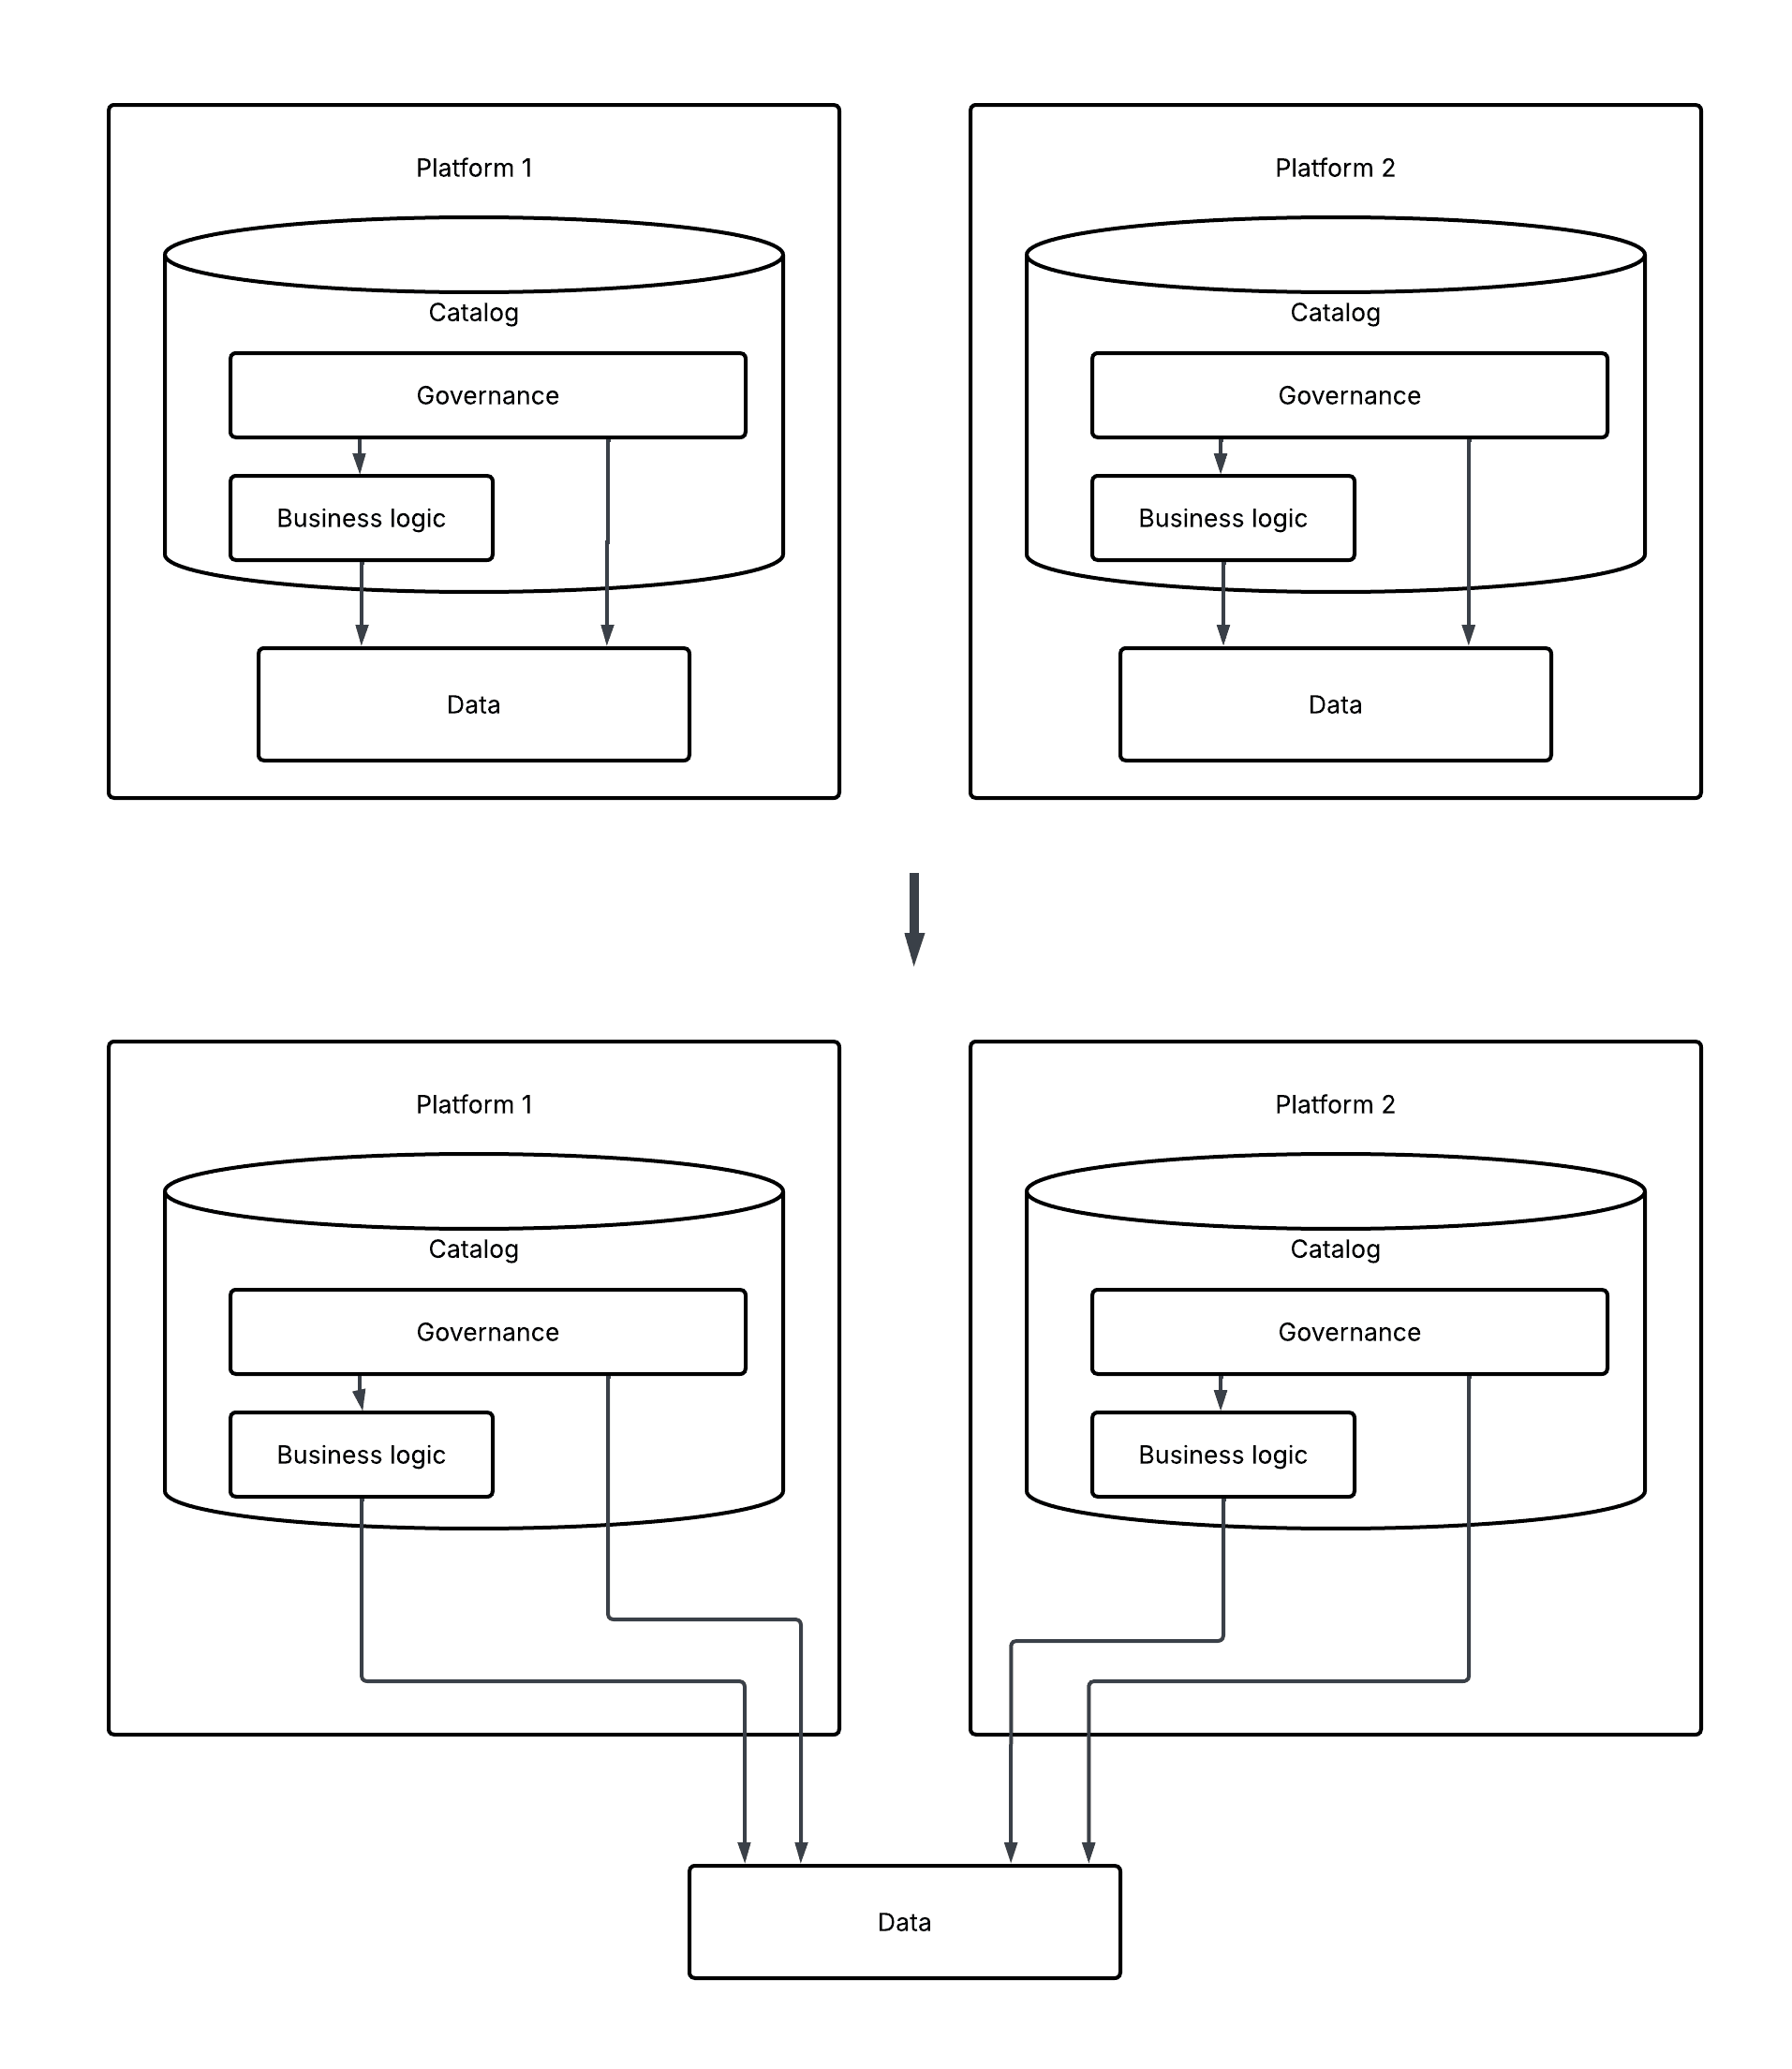
Apache Iceberg has been a driving force in making this possible. Because of its open specification, vendor-neutral project governance and broad cross-vendor adoption, it has become the de facto industry standard. Even Databricks, the creator of Delta Lake, has embraced Iceberg into its roadmap, spending up to a reported nearly $2 billion to acquire Tabular, a company founded by Iceberg's original creators. That move should only underscore the importance of Iceberg to the future of data lakehouses.Apache Iceberg 一直是实现这一目标的驱动力。凭借其开放规范、供应商中立的项目治理以及广泛的跨供应商采用,它已成为事实上的行业标准。即便是 Delta Lake 的创建者 Databricks,也将 Iceberg 纳入了其路线图,据报道斥资近 20 亿美元收购了由 Iceberg 原始创建者成立的 Tabular 公司。这一举动足以凸显 Iceberg 对数据湖仓未来的重要性。
The real beauty of Iceberg, however, is that it is governed by the Apache Software Foundation (ASF) and not by any single company. With contributors from various organizations, including Bloomberg, Databricks and Snowflake, the Project Management Committee (PMC) oversees the development of Iceberg, with all members having equal votes (and veto rights) to decide what code gets merged. This helps ensure that the project is controlled fairly, since the PMC is held accountable to the ASF board. This also largely explains why Iceberg has seen such widespread adoption across the industry. As a community-driven project, it includes a governance structure that helps ensure that development benefits the ecosystem as a whole rather than one company's interests; it gets us closer to that aforementioned ideal state. As the old saying goes: If you want to go fast, go alone; if you want to go far, go together.然而,Iceberg 真正的魅力在于它由 Apache 软件基金会(ASF)治理,而非受控于任何单一公司。项目管理委员会(PMC)由来自包括 Bloomberg、Databricks 和 Snowflake 在内的多家机构的贡献者组成,负责监督 Iceberg 的开发,所有成员拥有平等的投票权(及否决权)来决定合并哪些代码。这有助于确保项目得到公平管控,因为 PMC 对 ASF 董事会负责。这也很大程度上解释了为何 Iceberg 能在行业内获得如此广泛的采用。作为一个社区驱动的项目,它包含了一套治理结构,有助于确保开发成果造福整个生态系统,而非服务于某一家公司的利益;这使我们更接近前述的理想状态。正如那句老话所言:独行快,众行远。
And yet, despite all the progress, the ecosystem has not yet converged on ways to satisfy all the production requirements for full interoperability1. The challenge is that full interoperability hasn't been fully solved, decisions with trade-offs have to be made, which are neither easily identified nor well-documented. Organizations typically only identify gaps during implementation or after they've made significant architectural commitments that aren't easy to unwind. That's why when vendors say that interoperability is fully solved, it's important to question and validate their claims.然而,尽管取得了诸多进展,生态系统尚未就满足完全互操作性所需的全部生产要求达成一致。挑战在于完全互操作性尚未被彻底解决,必须做出权衡取舍,而这些权衡既不容易识别,也没有详尽的文档记录。机构通常只有在实施过程中,或在做出难以撤销的重大架构承诺后,才会发现其中的差距。因此,当供应商声称互操作性已完全解决时,质疑并验证其说法至关重要。
At Snowflake, we are committed to helping the multi-engine lakehouse become a reality for our customers. As we work with Apache Iceberg for data interoperability, Apache Polaris for governance interoperability and Apache Ossie (incubating) for semantic interoperability to work toward this vision, we want to help teams understand what is solved, what isn't, and how to avoid painful mistakes as they embark on this journey.在 Snowflake,我们致力于帮助客户实现多引擎湖仓。随着我们通过 Apache Iceberg 实现数据互操作性、通过 Apache Polaris 实现治理互操作性、通过 Apache Ossie(孵化中)实现语义互操作性来推进这一愿景,我们希望帮助团队理解哪些问题已解决,哪些尚未解决,以及在开启这一旅程时如何避免痛苦的错误。
The problems we cover in this blog series aren't inherently lakehouse problems, or even multi-engine lakehouse problems. Rather, they are simultaneous multi-engine access problems. If you remove that requirement for a given data set, most of these problems go away. Whether to allow simultaneous multi-engine access in your architecture isn't a binary choice; it can be a per-workload or per-data set cost-benefit analysis, and the answer will be different for different parts of your architecture. It will also change over time as these problems get solved. For example, for workloads or data sets where the cons of simultaneous multi-engine access outweigh the pros, you can store everything in Iceberg format but restrict access to a single engine — whether that is Snowflake or any other that meets your requirements. Then, once the community solves the problems that led you to determine the cons outweigh the pros for that workload or data set, no migration will be needed. Your data is already in Iceberg format, so you can just open up additional engines to access it. We'll cover this in more depth later in this blog (see: The pragmatic path forward).本系列博客所讨论的问题并非湖仓架构所特有,甚至不完全是多引擎湖仓的问题。相反,它们是“并发多引擎访问”带来的问题。如果你为特定数据集移除了这一要求,大多数问题便会迎刃而解。在架构中是否允许并发多引擎访问并非二选一的决策;它可以是针对每个工作负载或每个数据集的成本效益分析,对于架构的不同部分,答案可能各不相同。随着这些问题的解决,答案也会随时间而改变。例如,对于那些并发多引擎访问的弊大于利的工作负载或数据集,你可以将所有内容存储为 Iceberg 格式,但限制仅由单一引擎访问——无论是 Snowflake 还是其他符合你要求的引擎。此后,一旦社区解决了导致你判定弊大于利的问题,便无需进行任何迁移。你的数据已是 Iceberg 格式,因此你可以直接开放额外的引擎进行访问。我们将在本博客后文更深入地探讨这一点(参见:务实的前进路径)。
This post, along with three more deep-dive examinations in this series, is meant to highlight the gaps in the ecosystem today and then identifies specific strategic architectural decisions that data teams need to make in order to power production-ready, multi-engine environments. Our goal is to help organizations like yours avoid the pitfalls of discovering these issues too late and provide you with a practical guide to interoperability. In each section, we assess the current maturity of interoperability and any problem areas that the ecosystem hasn't fully solved, provide helpful guidance, and introduce questions to pressure test your architectural decisions.本文以及本系列中的另外三篇深度分析文章,旨在强调当前生态系统中的差距,并确定数据团队为驱动生产就绪的多引擎环境所需做出的具体战略性架构决策。我们的目标是帮助像贵机构这样的组织避免因发现问题太晚而陷入困境,并为你提供一份实用的互操作性指南。在每一部分中,我们都会评估当前的互操作性成熟度以及生态系统尚未完全解决的问题领域,提供有益的指导,并提出一些问题来压力测试你的架构决策。
The specific claims in this series are tied to publicly verifiable evidence — community mailing lists, open spec PRs, documented engine behaviors — and we'd encourage you to challenge any of it, as long as you take into account the state of the ecosystem at the time of writing and the velocity of change happening daily. Our aim is to distill these discussions into an actionable and pragmatic guide you can use to make architectural decisions.本系列中的具体主张均关联至可公开验证的证据——社区邮件列表、开放规范 PR、已记录的引擎行为——我们鼓励你挑战其中的任何观点,只要你考虑到撰写时生态系统的状态以及每日发生的快速变化。我们的目标是将这些讨论提炼为一份可操作且务实的指南,供你在做出架构决策时参考。
What is a multi-engine lakehouse?什么是多引擎湖仓?
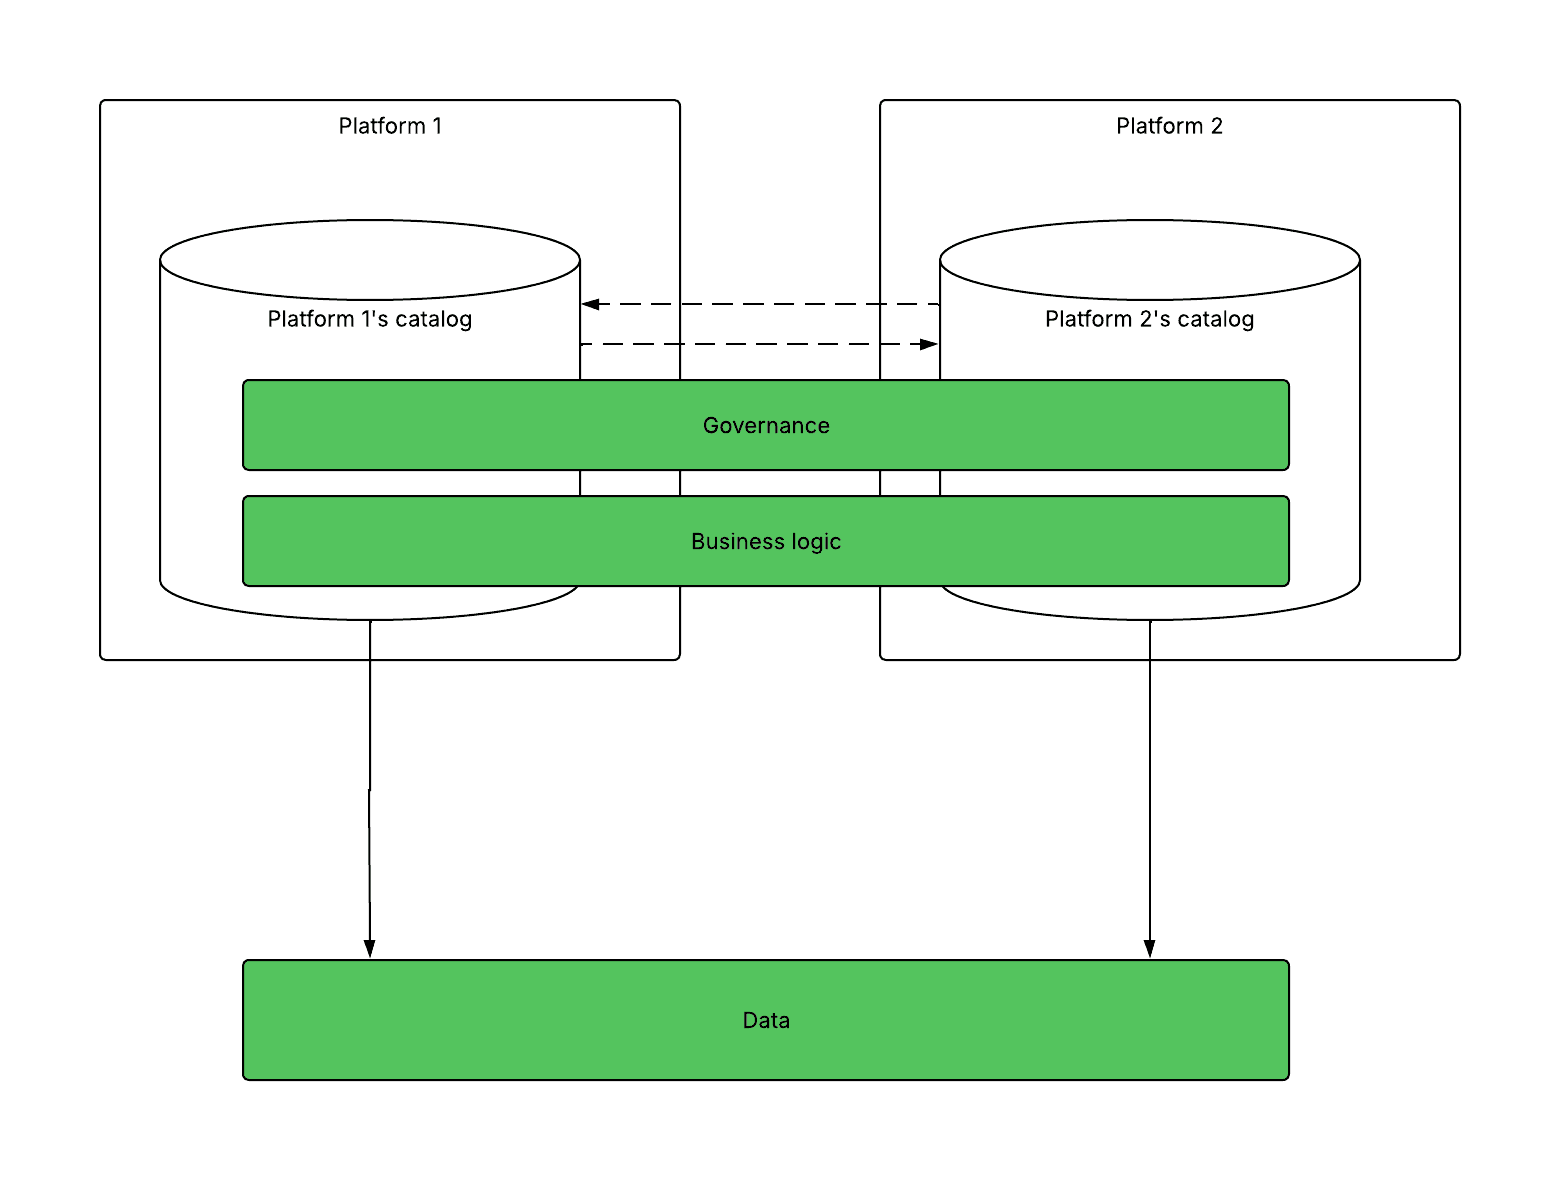
A multi-engine lakehouse is an architecture that stores data once, in an open format, and lets multiple compute engines read and write to that data directly. It is effectively unbundling a database or data platform. For most of their 50-year history, databases have been a self-contained bundle: table storage, the query engine, transactions, governance and everything else, fused into a single, closed unit you bought and operated as one thing. A lakehouse pulls that unit apart, starting with the storage layer. But a database is much more than table storage. It bundles in numerous other capabilities that the industry has learned are essential in the history of using relational databases, such as ACID transactions, fine-grained access control and governance, query optimization, indexing and metadata management.多引擎湖仓是一种将数据以开放格式存储一次,并允许多个计算引擎直接读写该数据的架构。它实际上是对数据库或数据平台的“解耦”。在过去 50 年的大部分时间里,数据库一直是一个自包含的整体:表存储、查询引擎、事务、治理及其他一切功能被融合进一个单一的、封闭的单元中,你作为一个整体进行购买和运营。湖仓架构将这一单元拆解开来,首先从存储层开始。但数据库不仅仅是表存储。它还捆绑了行业在关系型数据库使用史上公认必不可少的众多功能,如 ACID 事务、细粒度访问控制与治理、查询优化、索引及元数据管理。
In this blog series, we organize the capabilities of data platforms into three categories: data interoperability, business logic interoperability and governance interoperability. They all need to be fully interoperable before the lakehouse vision is truly realized. But each has shortcomings that need to be addressed.在本系列博客中,我们将数据平台的功能分为三类:数据互操作性、业务逻辑互操作性以及治理互操作性。在湖仓愿景真正实现之前,它们都需要具备完全的互操作性。但每一类都有亟待解决的缺陷。
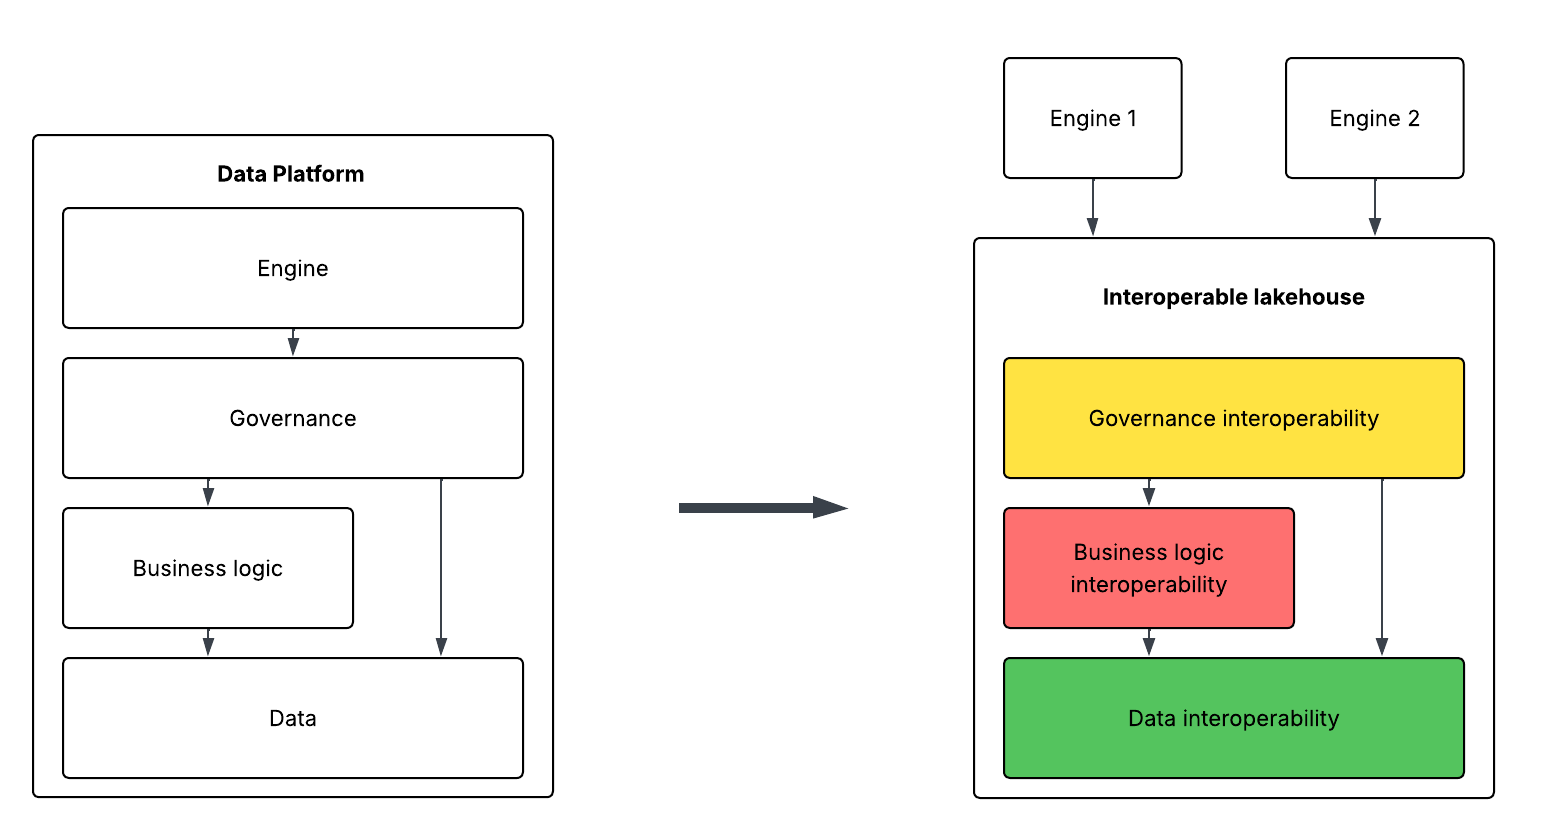
Data interoperability: Furthest along, with some gaps数据互操作性:进展最快,但仍有差距
Of the three dimensions, data interoperability is in the best shape and is mostly solved. Apache Iceberg, paired with the Iceberg REST Catalog (IRC) as the access layer, has largely addressed the structural problem of sharing data across engines. Most major engines can read and write to Iceberg tables today, and the REST Catalog spec provides a vendor-neutral way to manage table metadata. This is genuinely broad: Spark, Trino, Dremio, Flink and others have mature Iceberg read and write support today, and the REST Catalog spec gives them a vendor-neutral way to manage table metadata. That's real and meaningful progress and is the community's achievement.在三个维度中,数据互操作性状况最好,基本已得到解决。Apache Iceberg 搭配 Iceberg REST Catalog (IRC) 作为访问层,已在很大程度上解决了跨引擎共享数据的结构性问题。目前大多数主流引擎都能读写 Iceberg 表,且 REST Catalog 规范提供了一种供应商中立的方式来管理表元数据。这确实非常广泛:Spark、Trino、Dremio、Flink 等目前都具备成熟的 Iceberg 读写支持,而 REST Catalog 规范为它们提供了一种供应商中立的表元数据管理方式。这是切实且重大的进展,也是社区的成就。
But, again, it is "mostly solved," and it's worth understanding what isn't solved yet. Iceberg v3 introduced important capabilities — native semi-structured type support, improved deletion tracking, row lineage — but v3 isn't an all-or-nothing proposition. When a vendor says it "supports v3," you need to ask which specific features it supports and verify those against your actual requirements. This will also likely be the case with v4. Also, upgrading a table from v2 to v3 is a one-way door, specified in the function upgradeFormatVersion. You can't do it until every engine interacting with that table can handle the baseline v3 format, and v3 support across the ecosystem is still uneven.但同样,这只是“基本解决”,理解哪些尚未解决至关重要。Iceberg v3 引入了重要功能——原生半结构化类型支持、改进的删除跟踪、行血缘——但 v3 并非非黑即白。当供应商声称其“支持 v3”时,你需要询问其具体支持哪些功能,并根据你的实际需求进行验证。v4 版本很可能也是如此。此外,将表从 v2 升级到 v3 是一条单行道,在 upgradeFormatVersion 函数中有明确规定。除非与该表交互的每个引擎都能处理基础的 v3 格式,否则你无法进行升级,而目前生态系统对 v3 的支持仍不均衡。
There's also a subtler, frequently overlooked problem: performance consistency across engines. Iceberg is intentionally unopinionated about file hygiene. That means without central enforcement, different write pipelines — especially in decentralized organizations — will produce inconsistent file sizes, row group sizes and column statistics configurations. What's optimal for one engine can be suboptimal for another, and the debugging can be nontrivial because degradation tends to show up gradually and at scale, or when someone suddenly changes a setting on the writing engine.此外还有一个更微妙且常被忽视的问题:跨引擎的性能一致性。Iceberg 有意不对文件整理(file hygiene)做强制规定。这意味着如果没有中心化执行,不同的写入流水线——尤其是在去中心化组织中——会产生不一致的文件大小、行组大小和列统计信息配置。对一个引擎最优的配置可能对另一个引擎并非最优,且调试过程可能相当复杂,因为性能下降往往是逐渐显现的,或者是在达到一定规模时,又或是当有人突然更改了写入引擎的设置时才会出现。
A concrete example: The Iceberg SDK's write.metadata.metrics.max-inferred-column-defaults setting defaults to 100, meaning full column statistics are only written for the first 100 columns for engines that don't override this setting. Spark uses this default, since it extends a class in the Iceberg Java library implementation that uses this default, and Spark doesn't apply any overriding of this value out-of-the-box. A query that changes to now filter on column 101 instead of column 100 can degrade badly, and the problem is often hard to catch until it's already affecting users. This is addressable regardless of engine: While the Iceberg library has this as a default, your write jobs on many engines can change this default when writing. The trade-off is that this is opt-in and operational, so someone is responsible for setting this configuration properly. Snowflake's Iceberg writer takes an opinionated view and defaults to writing column statistics for all columns. It also provides an AUTO file size setting, which can be overridden at the database, schema or table level if you need to tune based on what you know. This opinionated stance works well for the most common read-heavy patterns, though it trades off write throughput and metadata size in exchange.一个具体的例子:Iceberg SDK 的 write.metadata.metrics.max-inferred-column-defaults 设置默认为 100,这意味着对于未覆盖此设置的引擎,仅会为前 100 列写入完整的列统计信息。Spark 使用了此默认值,因为它扩展了 Iceberg Java 库实现中使用了该默认值的类,且 Spark 开箱即用时并未覆盖此值。如果查询改为过滤第 101 列而非第 100 列,性能可能会严重下降,且这个问题往往很难在影响用户之前被发现。无论使用何种引擎,这都是可以解决的:虽然 Iceberg 库有此默认值,但你在许多引擎上的写入作业可以在写入时更改此默认值。权衡之处在于,这是可选且需要运维操作的,因此必须有人负责正确设置此配置。Snowflake 的 Iceberg 写入器采取了明确的观点,默认会为所有列写入列统计信息。它还提供了 AUTO 文件大小设置,如果你需要根据已知情况进行调整,可以在数据库、模式或表级别进行覆盖。这种明确的立场对于最常见的读取密集型模式效果良好,尽管它以牺牲写入吞吐量和元数据大小为代价。
Disaster recovery and cross-region access add another wrinkle. Standard object storage replication breaks the usability of Iceberg tables because file references in Iceberg metadata use absolute paths. According to the vote thread on the dev mailing list, the v4 spec will include a feature to support relative paths, which would eliminate this problem entirely by storing paths relative to the table's base location (though you'll still have to handle incrementalization for data replication). However, for now, production-ready, vendor-agnostic solutions aren't there yet for most architectures. Snowflake provides a replication and failover solution that addresses these issues for Snowflake-managed Iceberg tables.灾难恢复和跨区域访问增加了另一个复杂点。标准的对象存储复制会破坏 Iceberg 表的可用性,因为 Iceberg 元数据中的文件引用使用的是绝对路径。根据开发邮件列表上的投票线程,v4 规范将包含一个支持相对路径的功能,通过存储相对于表基础位置的路径来彻底消除此问题(尽管你仍需处理数据复制的增量化问题)。然而,就目前而言,对于大多数架构,生产就绪且供应商无关的解决方案尚未成熟。Snowflake 提供了一种复制和故障转移解决方案,可为 Snowflake 管理的 Iceberg 表解决这些问题。
Separately, and worth calling out explicitly: All engines reading from Iceberg tables should ideally be co-located in the same cloud region as the storage. Cross-region reads incur egress costs, degrade query performance, increase compute costs and expand your security surface in ways that are easy to underestimate at architecture time.另外,值得明确指出的是:所有读取 Iceberg 表的引擎理想情况下都应与存储位于同一云区域。跨区域读取会产生流出成本、降低查询性能、增加计算成本,并以架构设计时容易低估的方式扩大你的安全攻击面。
Key questions to pressure-test your data interoperability:压力测试数据互操作性的关键问题:
- Are all your engines, platforms and catalogs IRC-compliant bidirectionally — that is, not just inbound or outbound, but in both directions, as well as for read vs. read and write?你所有的引擎、平台和目录是否在双向上都符合 IRC 标准——即不仅是入站或出站,而是双向,且涵盖读对读以及读对写?
- Which specific Iceberg v2 and v3 features does each engine in your architecture actually support, and have you mapped that against your requirements, rather than assuming the "supports v3" marketing claim meets your needs?你架构中的每个引擎实际上支持哪些具体的 Iceberg v2 和 v3 功能?你是否已根据自身需求进行了映射,而不是假设“支持 v3”的营销声明就能满足你的需求?
- How are you handling disaster recovery and cross-region access for tables that need it, given that standard object storage replication breaks Iceberg's absolute path references?鉴于标准的对象存储复制会破坏 Iceberg 的绝对路径引用,你如何处理需要灾难恢复和跨区域访问的表?
This is a top-level view of the data interoperability terrain. The deep dive covers the full Iceberg v3 feature support breakdown across engines; specific BC/DR approaches and their trade-offs; ML workload considerations, including wide tables and vector formats; and write pipeline configuration guidance.以上是数据互操作性领域的宏观概览。深度分析部分涵盖了跨引擎的 Iceberg v3 功能支持明细;具体的 BC/DR 方法及其权衡;ML 工作负载考量,包括宽表和向量格式;以及写入流水线配置指南。
Read our full deep dive on data interoperability →阅读我们关于数据互操作性的完整深度分析 →
This is where teams most reliably get caught off-guard. Shared storage is only part of what you're unbundling when you move to a lakehouse. Another part is business logic (that is, views, UDFs, stored procedures, metric definitions). And here, there is no complete, widely adopted standard. That is not for a lack of attempts but because existing efforts, such as Iceberg Views, Substrait and Ossie, haven't yet achieved the technical comprehensiveness and cross-engine adoption needed to be reliable architectural dependencies. For anyone making production architecture decisions today, the practical effect is the same as having no standard. However, we recommend understanding these projects and their trajectories so you don't make architectural decisions that box you out of using these projects once their business logic interoperability capabilities mature.这是团队最容易措手不及的地方。当你转向湖仓架构时,共享存储只是你解耦的一部分。另一部分是业务逻辑(即视图、UDF、存储过程、指标定义)。在这里,目前还没有完整且被广泛采用的标准。这并非因为缺乏尝试,而是因为现有的工作(如 Iceberg Views、Substrait 和 Ossie)尚未达到作为可靠架构依赖项所需的技术全面性和跨引擎采用率。对于当今做出生产架构决策的任何人来说,实际效果等同于没有标准。然而,我们建议了解这些项目及其发展轨迹,以免做出架构决策,从而在这些项目的业务逻辑互操作性功能成熟后将自己排除在外。
What this means in practice is that any metric or transformation defined in one engine must be manually redefined in every other engine accessing that data. There's no synchronization mechanism and no feedback loop that tells you when those definitions have drifted. The CFO gets different revenue numbers from two dashboards pointed at the same Iceberg table because the definitions quietly diverged months ago, and nobody caught it. This isn't theoretical; it's actually happening now. Companies like Airbnb and LinkedIn have already encountered this problem at scale, and they have built entire internal frameworks to address it — Minerva at Airbnb and Coral at LinkedIn (discussed later in this section) being two well-documented examples. You don't build and operate a whole framework to solve a theoretical problem. But those organizations have an army of engineers who can build and, critically, maintain these systems indefinitely. For most organizations this is a build-versus-buy decision that skews heavily toward buy; the ongoing maintenance burden alone tends to outweigh the initial build cost.在实践中,这意味着在一个引擎中定义的任何指标或转换,都必须在访问该数据的每个其他引擎中手动重新定义。没有同步机制,也没有反馈回路告诉你这些定义何时出现了偏差。首席财务官从指向同一个 Iceberg 表的两个仪表板中得到了不同的收入数字,因为定义在几个月前悄然分歧,且无人察觉。这并非理论推演,而是正在发生的事实。像 Airbnb 和 LinkedIn 这样的公司已在大规模场景下遇到过这个问题,并构建了完整的内部框架来解决它——Airbnb 的 Minerva 和 LinkedIn 的 Coral(本节后文将讨论)就是两个记录详尽的例子。你不会为了解决一个理论问题而去构建和运营一个完整的框架。但这些组织拥有大量工程师,他们可以构建并至关重要的是无限期地维护这些系统。对于大多数组织而言,这是一个偏向于“购买”而非“构建”的决策;仅持续的维护负担往往就超过了初始构建成本。
Iceberg Views exist and represent a step in the right direction, but the current implementation is essentially a metadata container: It basically stores the SQL text and the dialect it was written in (a few other properties too, but the main components are those fields). There's no translation layer between dialects, and behavioral variance between SQL engines is real. Null ordering, type casting, tie-breaking in window functions all differ across engines in ways that can produce subtly wrong results that are hard to catch without deliberate cross-engine regression testing. This is not impossible to address, but it's not automatic and definitely not out of the box.Iceberg Views 确实存在,代表了朝着正确方向迈出的一步,但当前的实现本质上是一个元数据容器:它基本只存储了 SQL 文本及其编写所用的方言(还有少量其他属性,但主要组成部分就是这些字段)。方言之间没有翻译层,且 SQL 引擎之间的行为差异是真实存在的。空值排序、类型转换、窗口函数中的平局判定,在各引擎间都存在差异,这些差异可能产生微妙的错误结果,如果不进行刻意的跨引擎回归测试,很难发现。这并非无法解决,但绝非自动完成,也绝非开箱即用。
Ossie, formerly Open Semantic Interchange which had initial contributions from organizations such as Snowflake, Salesforce, dbt Labs and others, was born from a real problem: Every tool in the stack was interpreting business metrics differently, eroding trust in AI-driven insights before they could get off the ground. Donated to the Apache Software Foundation (ASF) and now undergoing incubation, Ossie is a meaningful step for metrics and semantic definitions, though it's worth noting that it still doesn't address the broader scope of business logic objects, such as UDFs, stored procedures and procedural logic, which remain outside its purview. Transformation tools like dbt and SQLMesh can generate per-engine SQL from a higher-level spec, and they're worth exploring. The longer-term solution to the broader problem is likely something like an interoperable intermediate representation (IR) — a single, engine-agnostic representation of logic that gets adapted to each engine's dialect, similar to what LinkedIn built internally with Coral or what the Substrait project is working toward.Ossie(前身为 Open Semantic Interchange,最初由 Snowflake、Salesforce、dbt Labs 等机构贡献)诞生于一个现实问题:堆栈中的每个工具对业务指标的解读方式各不相同,在 AI 驱动的洞察发挥作用之前就侵蚀了对其的信任。Ossie 已捐赠给 Apache 软件基金会(ASF)并正在进行孵化,它是指标和语义定义的重要一步,但值得注意的是,它仍未解决更广泛的业务逻辑对象范畴,如 UDF、存储过程和过程逻辑,这些仍在其覆盖范围之外。像 dbt 和 SQLMesh 这样的转换工具可以从更高级别的规范生成针对各引擎的 SQL,值得探索。该问题的长期解决方案很可能类似于一种可互操作的中间表示(IR)——一种单一的、引擎无关的逻辑表示,可适配到每个引擎的方言中,类似于 LinkedIn 内部构建的 Coral 或 Substrait 项目正在努力的方向。
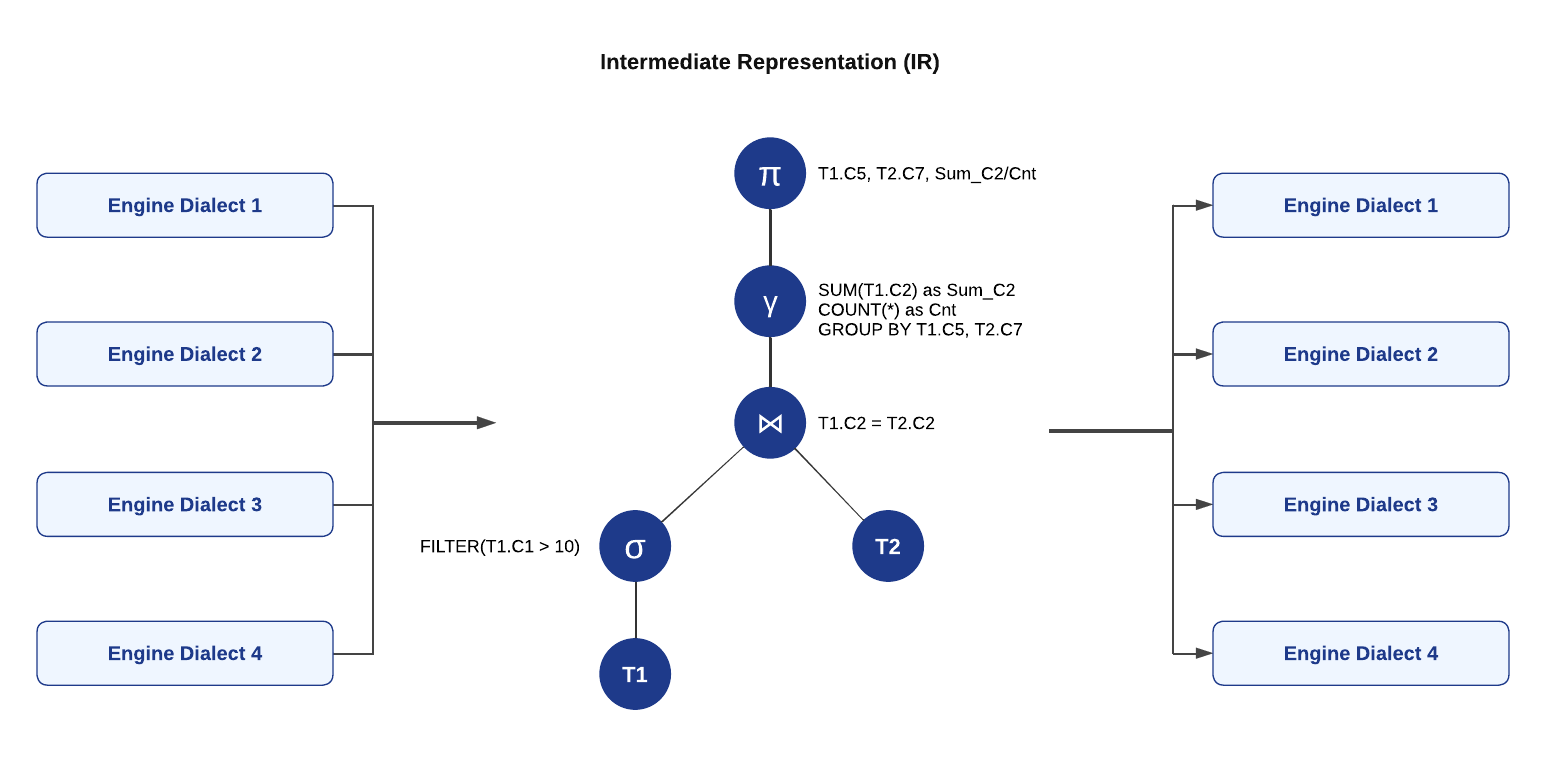
There's also an accountability gap that doesn't get discussed enough. In a single-engine world, there's one vendor to call when something produces the wrong answer. In a multi-engine world, debugging "why do these two engines produce different results from the same table" is a cross-vendor support problem — slower to resolve, ambiguous in ownership and costly when it surfaces in a downstream business decision.此外还有一个讨论不足的问责差距。在单引擎世界中,当出现错误答案时,只有一个供应商可以联系。在多引擎世界中,调试“为什么这两个引擎对同一个表产生不同的结果”是一个跨供应商支持问题——解决速度慢、责任归属模糊,且当问题出现在下游业务决策中时成本高昂。
Note that, while this is the least mature dimension of interoperability, there is a pretty good workaround available that addresses most of the problems: physicalize the business logic as part of a pipeline. That pipeline would compute the result of the business logic and write the results of that computation to a physical table so all engines inherently get the same answer. This workaround isn't free from trade-offs, however. We cover the possible workarounds and trade-offs in more depth in the business logic interoperability deep dive blog.请注意,虽然这是互操作性中最不成熟的维度,但有一个相当好的变通方案可以解决大多数问题:将业务逻辑物理化为流水线的一部分。该流水线会计算业务逻辑的结果,并将计算结果写入物理表,从而确保所有引擎都能得到相同的答案。然而,这种变通方案并非没有权衡。我们将在业务逻辑互操作性深度分析博客中更深入地探讨可能的变通方案及其权衡。
Key questions to pressure-test your business logic interoperability:压力测试业务逻辑互操作性的关键问题:
- What's your plan for assessing current business logic that hasn't been physicalized into a table and, for that logic, modifying your environment to now physicalize it so multiple engines are guaranteed to have the exact same logic applied?你对于评估尚未物理化为表的现有业务逻辑有何计划?对于该逻辑,你是否有计划修改环境以实现物理化,从而确保多个引擎必然应用完全相同的逻辑?
- For any business logic you can't physicalize into a table — active users, recognized revenue, churn — how do you detect when definitions diverge across engines, and what's your reconciliation process?对于任何无法物理化为表的业务逻辑(如活跃用户、已确认收入、流失率),你如何检测定义在各引擎间何时出现分歧?你的对账流程是什么?
- When two engines produce different results from the same Iceberg table and neither vendor can reproduce the issue independently, what is your escalation path, and have you mapped that cross-vendor accountability before you're in production?当两个引擎对同一个 Iceberg 表产生不同结果,且没有任何一个供应商能独立复现该问题时,你的升级路径是什么?在进入生产环境之前,你是否已明确这种跨供应商的问责机制?
The section above captures the core problem. The deep dive goes further — covering the Iceberg Views and UDF specs in detail, Ossie in depth, transpilation approaches and their trade-offs, the potential use of dbt and SQLMesh to mitigate gaps, and concrete guidance on which architecture patterns hold up for which use cases.以上部分抓住了核心问题。深度分析将进一步深入——详细涵盖 Iceberg Views 和 UDF 规范、深入探讨 Ossie、转译方法及其权衡、dbt 和 SQLMesh 在缓解差距方面的潜在用途,以及针对哪些架构模式适用于哪些用例的明确指导。
Read our full deep dive on business logic interoperability →阅读我们关于业务逻辑互操作性的完整深度分析 →
Governance interoperability: The highest stakes治理互操作性:风险最高
Object-level access control is largely addressed. The catalog-vended, temporary scoped credential pattern — where the catalog holds long-lived storage credentials and issues short-lived tokens to engines when access is allowed — works well and is broadly supported. Most engines and platforms support this, but unfortunately, not all.对象级访问控制已基本解决。由目录分发的临时作用域凭证模式——即目录持有长期存储凭证,并在允许访问时向引擎颁发短期令牌——运作良好且得到广泛支持。大多数引擎和平台都支持此模式,但不幸的是,并非全部。
Fine-grained access control (FGAC), on the other hand, is a different story. Row- and column-level security is not fully standardized across platforms yet. If you define a row filter or column mask in one engine's catalog, there's no standard mechanism that guarantees another engine will apply the same policy when it reads that table that works well in all situations. Teams end up duplicating policies across platforms, which increases maintenance overhead and, more importantly, creates opportunities to introduce enforcement gaps — the kind that only surface during a compliance audit.另一方面,细粒度访问控制(FGAC)则完全是另一回事。行级和列级安全尚未在各平台间实现完全标准化。如果你在一个引擎的目录中定义了行过滤器或列掩码,目前没有标准机制能保证另一个引擎在读取该表时会应用相同的策略,且在所有情况下都能良好运作。团队最终会在各平台间重复定义策略,这不仅增加了维护开销,更重要的是,创造了引入执行差距的机会——这类问题往往只在合规审计期间才会暴露。
Snowflake is actively working with the communities to solve this by helping lead ongoing discussions in both the Iceberg and Apache Polaris projects around things like standardizing how to pass around FGAC rules as well as using the scan plan API in the IRC spec as a near-term mitigation. These are viable paths forward, but they each have pros and cons. Where one approach may make more sense for a given situation, a different approach could make more sense for a different situation (for example, small data set with infrequent changes with simple FGAC policies vs. large data set with frequent changes with complex FGAC policies). Furthermore, they're not yet production-ready in a consistent, vendor-agnostic way. There are additional approaches, such as defining them in a single system and having that system translate those policies and push them to each engine, that each have pros and cons.Snowflake 正在积极与社区合作,通过在 Iceberg 和 Apache Polaris 项目中牵头进行持续讨论来解决此问题,内容包括标准化如何传递 FGAC 规则,以及在短期内利用 IRC 规范中的扫描计划 API(scan plan API)作为缓解措施。这些都是可行的前进路径,但各有优劣。在某种情况下某种方法可能更有意义,而在另一种情况下则可能采取不同方法(例如,数据量小、变更频率低且 FGAC 策略简单的场景,对比数据量大、变更频繁且 FGAC 策略复杂的场景)。此外,它们尚未以一致的、供应商无关的方式达到生产就绪状态。还有其他方法,例如在一个系统中进行定义,并让该系统转换这些策略并推送到每个引擎,这些方法也各有优劣。
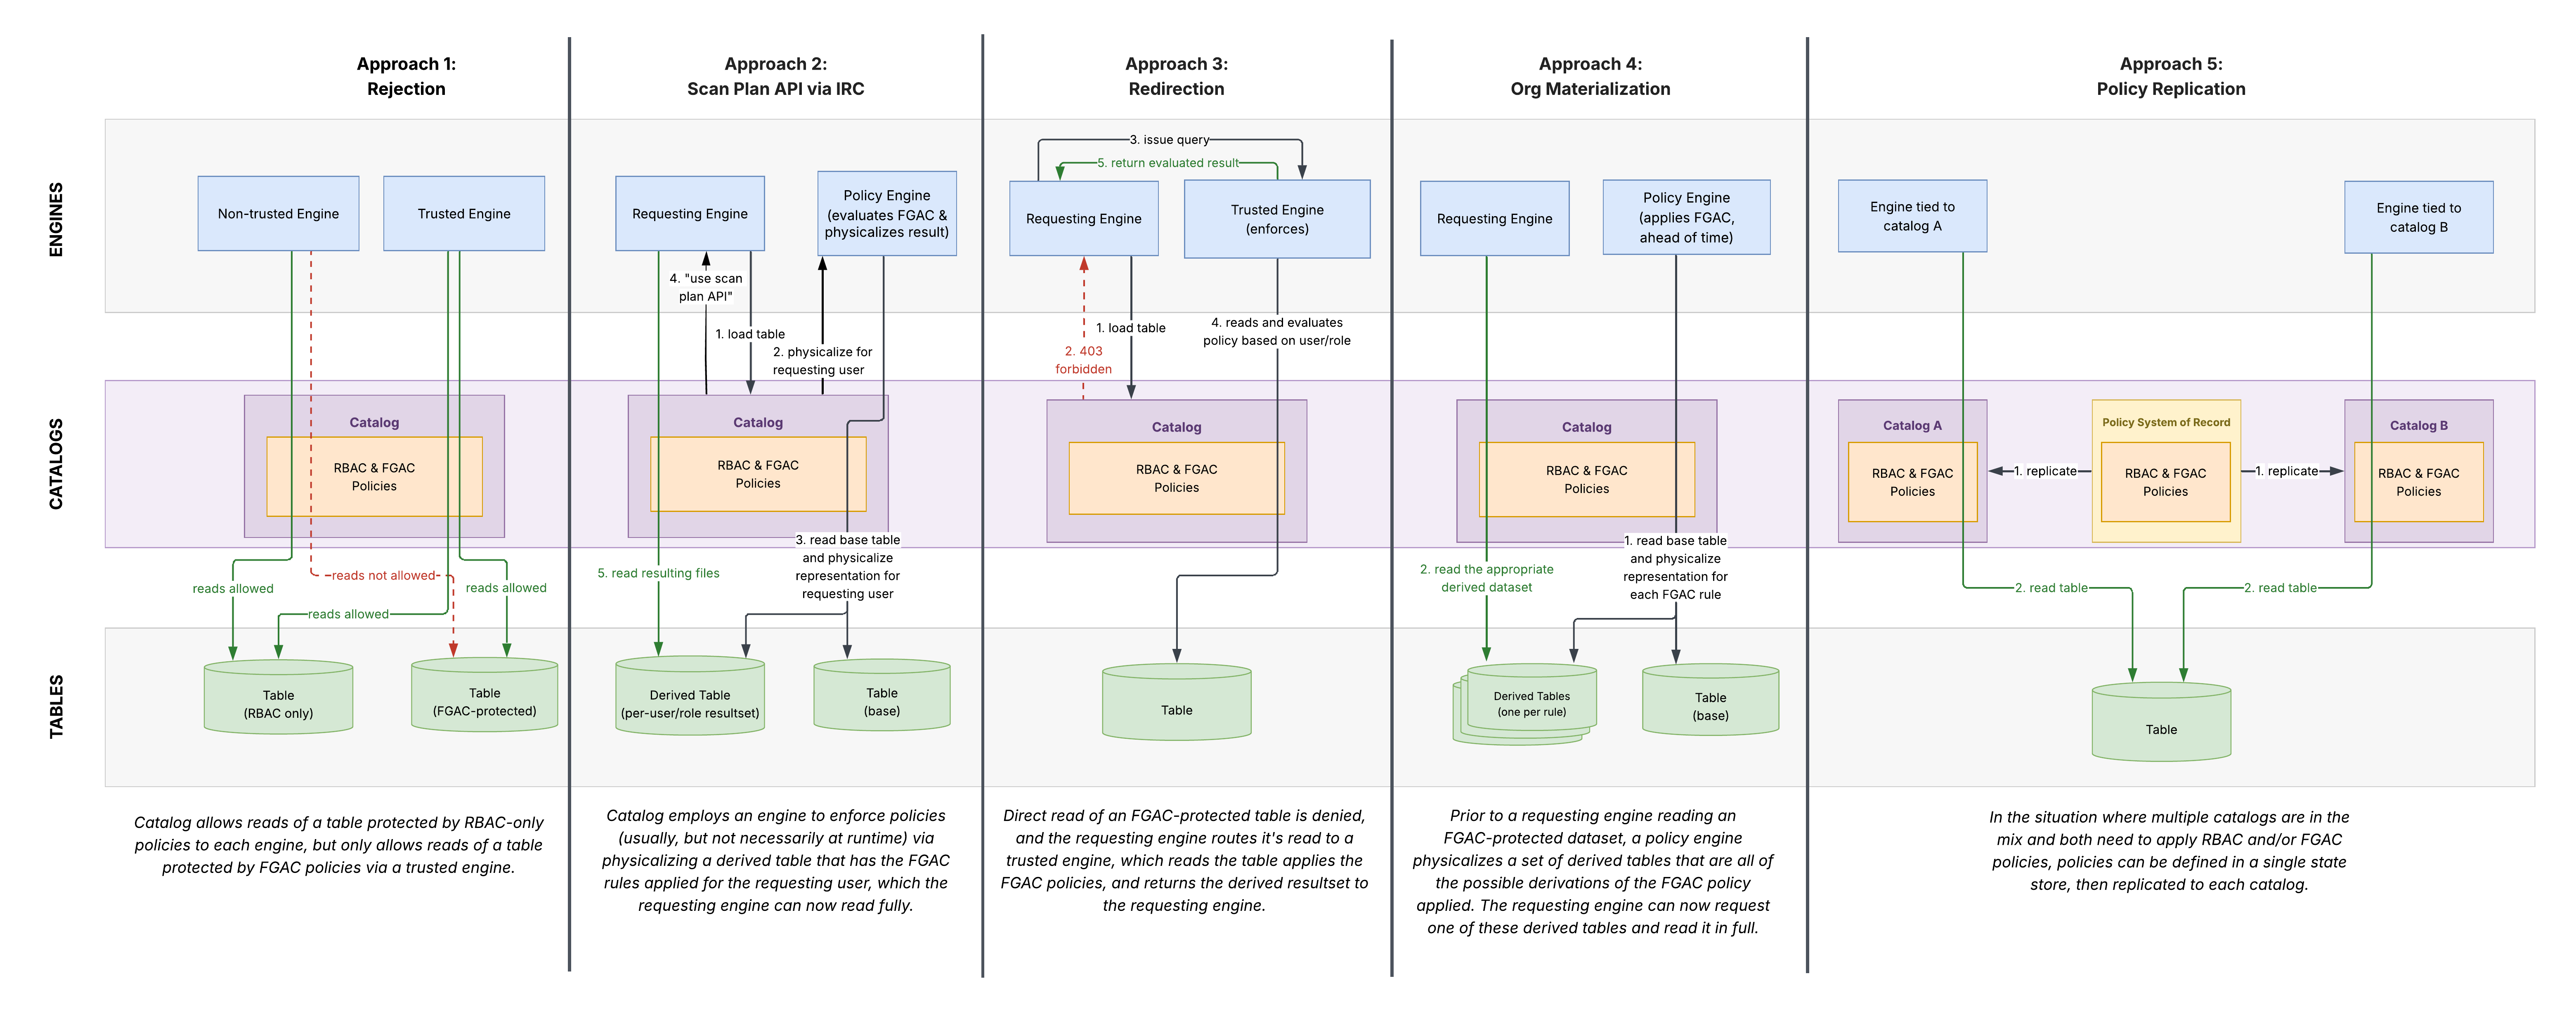
Catalog federation complicates things further. Most multi-vendor deployments today rely on a cache-and-async-refresh model where a local catalog treats itself as the source of truth and periodically syncs from the remote. The consequence: Policies defined in your source catalog can be bypassed by a federated catalog operating from a stale state. There are, however, ways to narrow this window, including just-in-time refresh, which Snowflake recently implemented. But fresh metadata only closes the staleness and revocation-lag gap; it doesn't get a federated engine to enforce a policy it was never given. That harder work is splitting into two efforts in the Iceberg and Polaris communities, with contributors from multiple vendors: read restrictions, the nearer-term piece that lets any IRC-speaking engine enforce the row filters and column masks defined in your catalog (Iceberg PR #13879), and policy exchange, which sequences behind read restrictions to sync the policy definitions between catalogs so even engines bound to their own catalog enforce them (Polaris PR #2048).目录联合(Catalog federation)使情况进一步复杂化。目前大多数多供应商部署依赖于“缓存加异步刷新”模型,即本地目录将自身视为事实来源,并定期从远程同步。后果是:在源目录中定义的策略可能会被处于陈旧状态的联合目录所绕过。然而,有一些方法可以缩小这一窗口,包括即时刷新,Snowflake 最近已实现此功能。但新鲜的元数据只能缩小陈旧感和撤销延迟的差距;它无法让联合引擎执行从未被赋予的策略。这项更艰巨的工作正在 Iceberg 和 Polaris 社区中分裂为两项工作,由来自多个供应商的贡献者参与:读取限制(read restrictions),这是较短期的部分,允许任何支持 IRC 的引擎执行目录中定义的行过滤器和列掩码(Iceberg PR #13879);以及策略交换(policy exchange),它在读取限制之后进行,用于在目录间同步策略定义,以便即使是绑定到自身目录的引擎也能执行这些策略(Polaris PR #2048)。
Lineage is another casualty — fragmented across catalogs, with no standard mechanism to produce an end-to-end picture of data flow across engine boundaries. There is progress being made on this front with OpenLineage emerging as the de facto standard; however, it's generally still up to customers today to wire it all together. Snowflake's Horizon Context automates this work for you, ingesting lineage events from your broader data estate.血缘(Lineage)是另一个受害者——它在各目录间碎片化,且没有标准机制来生成跨引擎边界的数据流端到端全景图。随着 OpenLineage 逐渐成为事实上的标准,这一领域正在取得进展;然而,目前通常仍由客户自行将其串联起来。Snowflake 的 Horizon Context 可为你自动完成这项工作,摄取来自你更广泛数据资产的血缘事件。
Data classification tags are another area where standardization remains incomplete. While there are emerging proposals in the open source community around basic label interoperability across catalogs, these are early-stage and don't yet address the richer tag semantics that most governance frameworks require — specifically, inheritance hierarchies that propagate classifications downstream through derived and dependent objects. There is currently no standard protocol for propagating full tag definitions and their inheritance behavior across catalog federation boundaries.数据分类标签是另一个标准化仍未完成的领域。虽然开源社区中出现了关于跨目录基本标签互操作性的初步提案,但这些尚处于早期阶段,且尚未解决大多数治理框架所需的更丰富标签语义——特别是通过派生和依赖对象向下传播分类的继承层次结构。目前尚无标准协议可在目录联合边界间传播完整的标签定义及其继承行为。
Transactional consistency across catalogs is difficult to guarantee. Atomic commit across two independently governed catalogs with no shared transaction coordinator is a fundamental distributed-systems problem that no current catalog federation protocol addresses.跨目录的事务一致性难以保证。在没有共享事务协调器的情况下,跨两个独立治理的目录实现原子提交,是一个基础的分布式系统问题,目前没有任何目录联合协议能够解决。
Audit trails are an underappreciated oversight in all of this. In a single-engine environment, you can answer, "Which users accessed this sensitive table and what exactly did they read?" In a multi-engine environment with catalog federation and service accounts, the storage layer often sees only a shared IAM role that's effectively a service account. This is documented behavior: For AWS, cloud storage audit logs record the IAM principal that accessed the data, not the human user who initiated the query. There's currently no broadly adopted standard mechanism to correlate that access back to a specific user or query, which makes holistically answering a compliance audit question a build-it-yourself problem. There are ways to solve this, such as query log aggregation across platforms and/or adding trace IDs, which we will discuss in more detail in the governance interoperability deep dive post.审计追踪是所有这一切中被低估的疏漏。在单引擎环境中,你可以回答:“哪些用户访问了这个敏感表,他们到底读取了什么?”而在具有目录联合和服务账户的多引擎环境中,存储层往往只能看到一个共享的 IAM 角色,它实际上是一个服务账户。这是已记录的行为:对于 AWS,云存储审计日志记录的是访问数据的 IAM 主体,而非发起查询的人类用户。目前没有被广泛采用的标准机制将该访问关联回特定用户或查询,这使得全面回答合规审计问题成为一个需要自行构建的问题。有一些方法可以解决此问题,例如跨平台查询日志聚合和/或添加追踪 ID,我们将在治理互操作性深度分析文章中更详细地讨论。
Snowflake's Horizon Catalog now provides audit logging for external engine access to Iceberg tables through the IRC, capturing catalog-level access events tied to authenticated identities — a meaningful step toward answering the compliance question. Correlating those catalog events back to a specific human user or query still depends on the identity model your external platforms enforce and whether they pass user-level context to the catalog. The IRC spec does not define the mechanism by which engines can send the SQL query or logic to the catalog when an engine makes a request to read a table. Therefore, if you need the SQL or the logic other engines executed for the audit log, you still need to build some log aggregation mechanism yourself. Horizon's audit logging has implemented what is possible today, and engineers working at Snowflake continue to engage with the Iceberg and Polaris communities across many features to make governance more interoperable.Snowflake 的 Horizon Catalog 现在通过 IRC 为外部引擎访问 Iceberg 表提供审计日志记录,捕获与已认证身份关联的目录级访问事件——这是回答合规性问题的重要一步。将这些目录事件关联回特定人类用户或查询,仍取决于你外部平台所强制执行的身份模型,以及它们是否将用户级上下文传递给目录。IRC 规范并未定义引擎在请求读取表时向目录发送 SQL 查询或逻辑的机制。因此,如果你需要审计日志中包含其他引擎执行的 SQL 或逻辑,你仍需自行构建某种日志聚合机制。Horizon 的审计日志已实现了目前可能实现的功能,Snowflake 的工程师们继续在许多功能上与 Iceberg 和 Polaris 社区合作,以使治理更具互操作性。
Key questions to pressure-test your governance interoperability:压力测试治理互操作性的关键问题:
- When each engine in your architecture accesses storage, does it do so exclusively through catalog-vended, short-lived scoped credentials, or do any engines require long-lived credentials that bypass the catalog entirely? And does that hold in both directions: when the catalog is the source of truth for a table and when it's the consumer for a table?当架构中的每个引擎访问存储时,它是仅通过目录分发的、短期作用域凭证进行访问,还是有任何引擎需要绕过目录的长期凭证?在目录作为表的真实来源以及作为表的消费者时,这两种方向是否均成立?
- If a row- or column-level security policy is defined on a table in one engine's catalog, what is your mechanism for guaranteeing that another engine in your architecture enforces the same policy — and how would you detect a violation if it didn't?如果在一个引擎的目录中对表定义了行级或列级安全策略,你通过什么机制保证架构中的另一个引擎执行相同的策略——如果未能执行,你如何检测到违规?
- If a compliance team asks which users accessed a sensitive table last month and what exactly they read — including access through service accounts and federated catalogs — can you answer that question with a verifiable audit trail?如果合规团队询问上个月有哪些用户访问了敏感表以及他们具体读取了什么——包括通过服务账户和联合目录的访问——你能否提供可验证的审计追踪来回答该问题?
There's considerably more ground to cover here than this summary allows. The deep dive goes through each FGAC approach in detail — such as scan plan API, leaf permutation materialization and trusted engine patterns. We also examine the catalog federation models and their trade-offs, approaches to cross-engine audit logging, and practical guidance for different combinations of workload attributes and compliance requirements.此处涵盖的内容远多于本摘要所能容纳的范围。深度分析将详细介绍每种 FGAC 方法——如扫描计划 API、叶子排列物化(leaf permutation materialization)和受信任引擎模式。我们还将探讨目录联合模型及其权衡、跨引擎审计日志记录方法,以及针对不同工作负载属性和合规要求组合的实践指导。
Read our full deep dive on governance interoperability →阅读我们关于治理互操作性的完整深度分析 →
The pragmatic path forward务实的前进路径
The multi-engine lakehouse is where the industry is headed, and we're committed to making it real — not just as a beneficiary of the outcome, but as an active builder of the foundation. Snowflake is a founding contributor to Apache Polaris and Apache Ossie (incubating), employing many PMC and PPMC members, respectively, to those projects. The company also employs several PMC members for Apache Iceberg. Snowflake is helping to drive specific proposals in all of these communities, aimed to close many of the gaps this series describes. We're not pointing out problems from the sidelines; we're writing the specs and shipping the implementations. That's also why we can be direct about what isn't solved yet: We're close enough to the work to know exactly where the hard edges are.多引擎湖仓是行业的发展方向,我们致力于使其成为现实——不仅作为成果的受益者,更是基础的积极构建者。Snowflake 是 Apache Polaris 和 Apache Ossie(孵化中)的创始贡献者,并为这些项目分别聘用了多名 PMC 和 PPMC 成员。公司还聘用了多名 Apache Iceberg 的 PMC 成员。Snowflake 正在帮助推动所有这些社区中的具体提案,旨在弥补本系列所描述的许多差距。我们不是在场边指点问题;我们是在编写规范并交付实现。这也是我们能直言哪些问题尚未解决的原因:我们足够贴近工作,确切知道难点在哪里。
These gaps aren't permanent constraints. They're engineering problems with active proposals, real implementers and viable paths to resolution. And because the work is happening in community-governed, vendor-neutral projects, the solutions are designed to benefit the entire ecosystem — which is precisely the point.这些差距并非永久性的限制。它们是具有活跃提案、真正实现者和可行解决路径的工程问题。由于这些工作是在社区治理、供应商中立的项目中进行的,因此解决方案旨在造福整个生态系统——这正是重点所在。
The path from "problem recognized" to "proposed in the spec" to "implemented by all the vendors you rely on" takes time. And in the meantime, organizations wanting to go the multi-engine lakehouse route now get hurt from either the gaps themselves or having to maintain complex workarounds.从“识别问题”到“规范中提出”再到“由你所依赖的所有供应商实现”的路径需要时间。在此期间,想要走多引擎湖仓路线的机构会因这些差距本身,或不得不维护复杂的变通方案而受损。
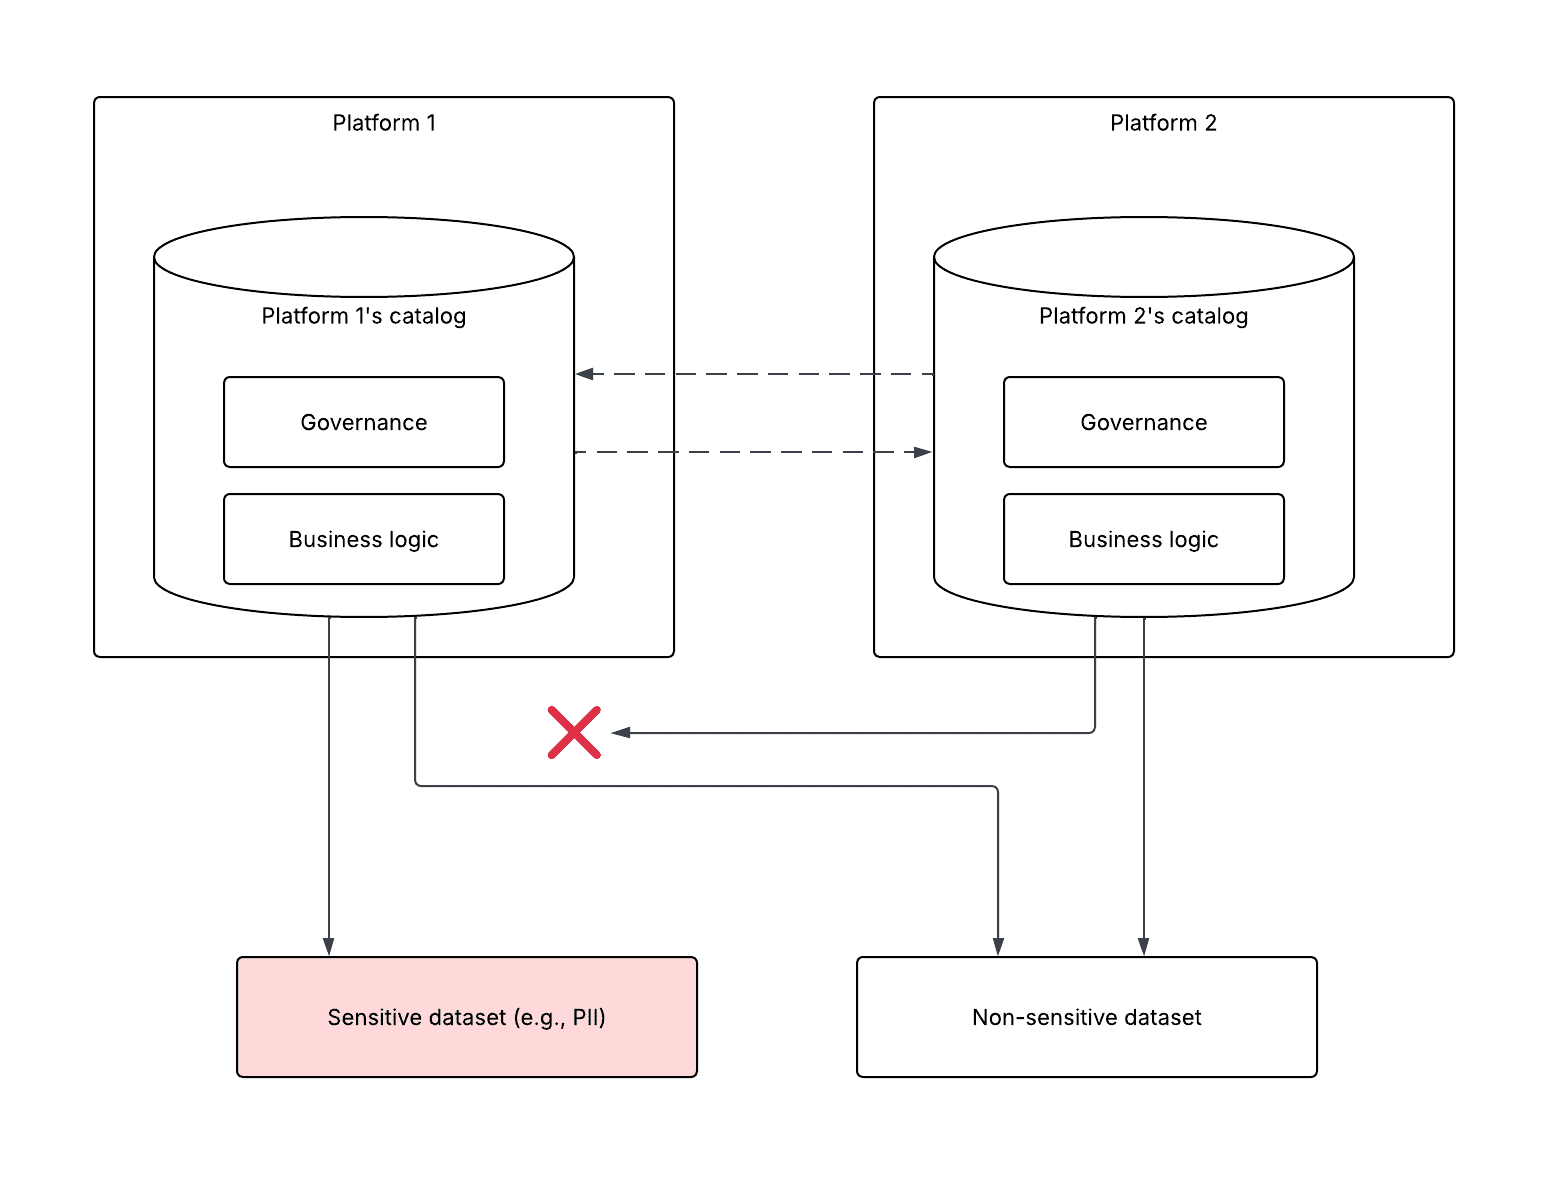
Again, it is worth reiterating that these are problems caused by simultaneous multi-engine access. Single-engine lakehouses, or even multi-engine lakehouses that don't allow simultaneous multi-engine access to a given data set, do not inherently present these issues. And simultaneous multi-engine access in your architecture isn't an all-or-nothing proposition; it can be a per-workload or per-data-set decision, based on cost-benefit analysis, which will be different for different parts of your architecture, and also change over time as these problems get solved. But this is still worth understanding, because simultaneous multi-engine access is where the ecosystem is heading. Being able to point the best engine for each job, increasingly including AI and agentic workloads, at a single copy of data without first copying it into a different system only gets more valuable over time. The point isn't to avoid it; it's to adopt it deliberately where the payoff is there today, and expand as the community solves the rest.再次重申,这些问题是由并发多引擎访问引起的。单引擎湖仓,甚至是不允许对特定数据集进行并发多引擎访问的多引擎湖仓,本身并不存在这些问题。而在你的架构中,并发多引擎访问并非非黑即白;它可以是基于成本效益分析,针对每个工作负载或每个数据集的决策。对于架构的不同部分,决策会各不相同,且随着这些问题的解决,决策也会随时间而改变。但这仍然值得理解,因为并发多引擎访问是生态系统的发展方向。能够为每项工作(日益包括 AI 和代理工作负载)指定最佳引擎,并指向单一数据副本,而无需先将其复制到不同系统中,其价值只会随时间增加。重点不是回避它,而是在目前有回报的地方审慎采用,并随着社区解决其余问题而逐步扩展。
For large, less-sensitive analytical data sets where multiple teams legitimately need different compute tools, multi-engine access today is often worth it, and the workarounds are manageable. For curated data sets with strict compliance requirements, complex privacy policies or high-stakes business logic, the answer today is usually to store the data in Iceberg for future flexibility, while restricting all access to a single, governed engine (whether that's Snowflake or any other engine that meets your governance requirements) where your policies and logic live in one place. Open storage, curated access. Then, once the community solves the problems that apply to that data set or workload, no migration is needed. Your data is already in Iceberg format, so you can just open up additional engines to access it.对于多个团队确实需要不同计算工具的大型、非敏感分析数据集,目前多引擎访问通常是值得的,且变通方案也是可控的。对于具有严格合规要求、复杂隐私策略或高风险业务逻辑的精选数据集,目前的答案通常是将数据存储在 Iceberg 中以备未来灵活性,同时将所有访问限制在单一的、受治理的引擎(无论是 Snowflake 还是任何其他符合你治理要求的引擎)中,在此处你的策略和逻辑集中于一处。开放存储,精选访问。此后,一旦社区解决了适用于该数据集或工作负载的问题,便无需迁移。你的数据已是 Iceberg 格式,因此你可以直接开放额外的引擎进行访问。
When evaluating which platform to centralize on, there's a principle that cuts through much of the noise: In an ecosystem that isn't yet fully settled, bet on platforms with a demonstrated record of genuine investment in the open standards you're building on — not just stated commitment, but verifiable participation. The community-governed nature of ASF projects like Apache Iceberg and Apache Polaris tends to signal that a platform actively co-governing the standard has its incentives structurally aligned with yours in a way that proprietary or single-vendor-driven alternatives can't replicate. This standard applies to every vendor, including Snowflake. The IRC compliance analysis is one concrete example of where stated and actual support diverge. The open source branding pattern is another; if no vendor lock-in is important to you and if a commercial offering has an open source counterpart, validate that the hosted version has meaningful parity, and apply the portability test: How easily can you move from the hosted offering to the open source one and still leverage the specific capabilities important to you? That answer tells you more than any marketing claim. Test the specific capabilities your architecture requires in your own environment, with your own data and access patterns that are representative of what you will need to do in production, before committing to any path.在评估以哪个平台为中心时,有一个原则可以穿透大部分噪音:在一个尚未完全定型的生态系统中,押注于那些在所构建的开放标准上有着切实投资记录的平台——不仅仅是口头承诺,而是可验证的参与。像 Apache Iceberg 和 Apache Polaris 这样由 ASF 治理的项目,其社区治理性质往往标志着一个积极共同治理标准的平台,其激励机制在结构上与你的一致,这是专有或单一供应商驱动的替代方案无法复制的。此标准适用于包括 Snowflake 在内的每一家供应商。IRC 合规性分析就是声明支持与实际支持出现分歧的一个具体例子。开源品牌模式是另一个例子;如果你认为避免供应商锁定很重要,且商业产品有开源对应版本,请验证托管版本是否具有实质性的对等性,并应用可移植性测试:你从托管产品迁移到开源产品,并继续利用对你重要的特定功能有多容易?这个答案比任何营销声明都更能说明问题。在承诺任何路径之前,请在自己的环境中测试架构所需的特定功能,使用你自己的数据和访问模式,这些数据和模式应代表你在生产中需要执行的操作。
The pragmatic approach: Adopt Iceberg to prevent storage lock-in, and allow simultaneous multi-engine access where the benefits outweigh the costs — but be deliberate about that call per workload or per data set. Factor in the full total cost of ownership (TCO); the people cost of implementing and maintaining workarounds is often where the real delta shows up, and it's easy to undercount in an initial architecture assessment. Reassess every six to 12 months, anchored to three things: what your specific requirements and timelines actually demand, how community progress on the open standards is tracking and what your vendors' timelines are for supporting those standards. Apache Iceberg and Apache Polaris are generally where these problems are being solved in a community-governed, vendor-agnostic way — which is exactly why they're more likely to achieve the broad adoption in engines and vendor offerings that makes the long-term bet worthwhile.务实的方法:采用 Iceberg 以防止存储锁定,并在收益大于成本的地方允许并发多引擎访问——但要针对每个工作负载或每个数据集审慎做出决定。将总拥有成本(TCO)考虑在内;实施和维护变通方案的人力成本往往是真正差异所在,且在初始架构评估中容易被低估。每六到十二个月重新评估一次,锚定三件事:你的具体需求和时间表实际要求什么,社区在开放标准方面的进展如何,以及你的供应商支持这些标准的时间表是什么。Apache Iceberg 和 Apache Polaris 通常是这些问题以社区治理、供应商无关方式得到解决的地方——这正是它们更有可能在引擎和供应商产品中获得广泛采用,从而使长期押注变得值得的原因。
- The interoperability challenges described in this series are inherent to the multi-engine pattern, not specific to Iceberg. Any architecture that decouples compute from storage and runs multiple SQL engines against shared data — regardless of whether that data is in Apache Iceberg, Delta Lake or Apache Hudi — face mostly the same behavioral divergences, governance gaps and business logic drift. The community has converged on Iceberg as the de facto standard table format where solutions are being built, which is why the concrete specs, proposals and workarounds in this series reference Iceberg and its ecosystem. The problems themselves are format-agnostic; most of the solutions in progress happen to live in the Iceberg community because that's where the community’s engineering investment is largely concentrated.本系列描述的互操作性挑战是多引擎模式固有的,并非 Iceberg 所特有。任何将计算与存储解耦并针对共享数据运行多个 SQL 引擎的架构——无论该数据是在 Apache Iceberg、Delta Lake 还是 Apache Hudi 中——都面临着大致相同的行为分歧、治理差距和业务逻辑漂移。社区已将 Iceberg 作为事实上的标准表格式,解决方案正是在此基础上构建的,这就是为什么本系列中的具体规范、提案和变通方案引用了 Iceberg 及其生态系统。问题本身与格式无关;大多数正在进行的解决方案恰好存在于 Iceberg 社区中,因为那是社区工程投资主要集中的地方。