
This article is based on the recent Weave Intelligence research report, The four levels of agentic software development in the enterprise.本文基于 Weave Intelligence 近期发布的研究报告《企业代理式软件开发的四个阶段》。
Something has shifted in the last eighteen months that I don't think has been named clearly enough yet. The conversation in enterprise software teams has moved from "should we use AI?" to "why aren't we seeing the gains everyone else is talking about?" The answer, almost every time, is the same. Procuring fancy models isn't the driver of productivity. What actually changes the equation is how well you structure your platform to make productive use of agents at scale.在过去的十八个月里,发生了一些变化,但我认为目前还没有被足够清晰地定义。企业软件团队的对话已经从“我们应该使用 AI 吗?”转变为“为什么我们没有看到大家都在谈论的那些收益?”答案几乎每次都一样。采购高大上的模型并不能驱动生产力。真正改变这一现状的是,你构建平台的结构化程度如何,以及能否大规模地高效利用代理。
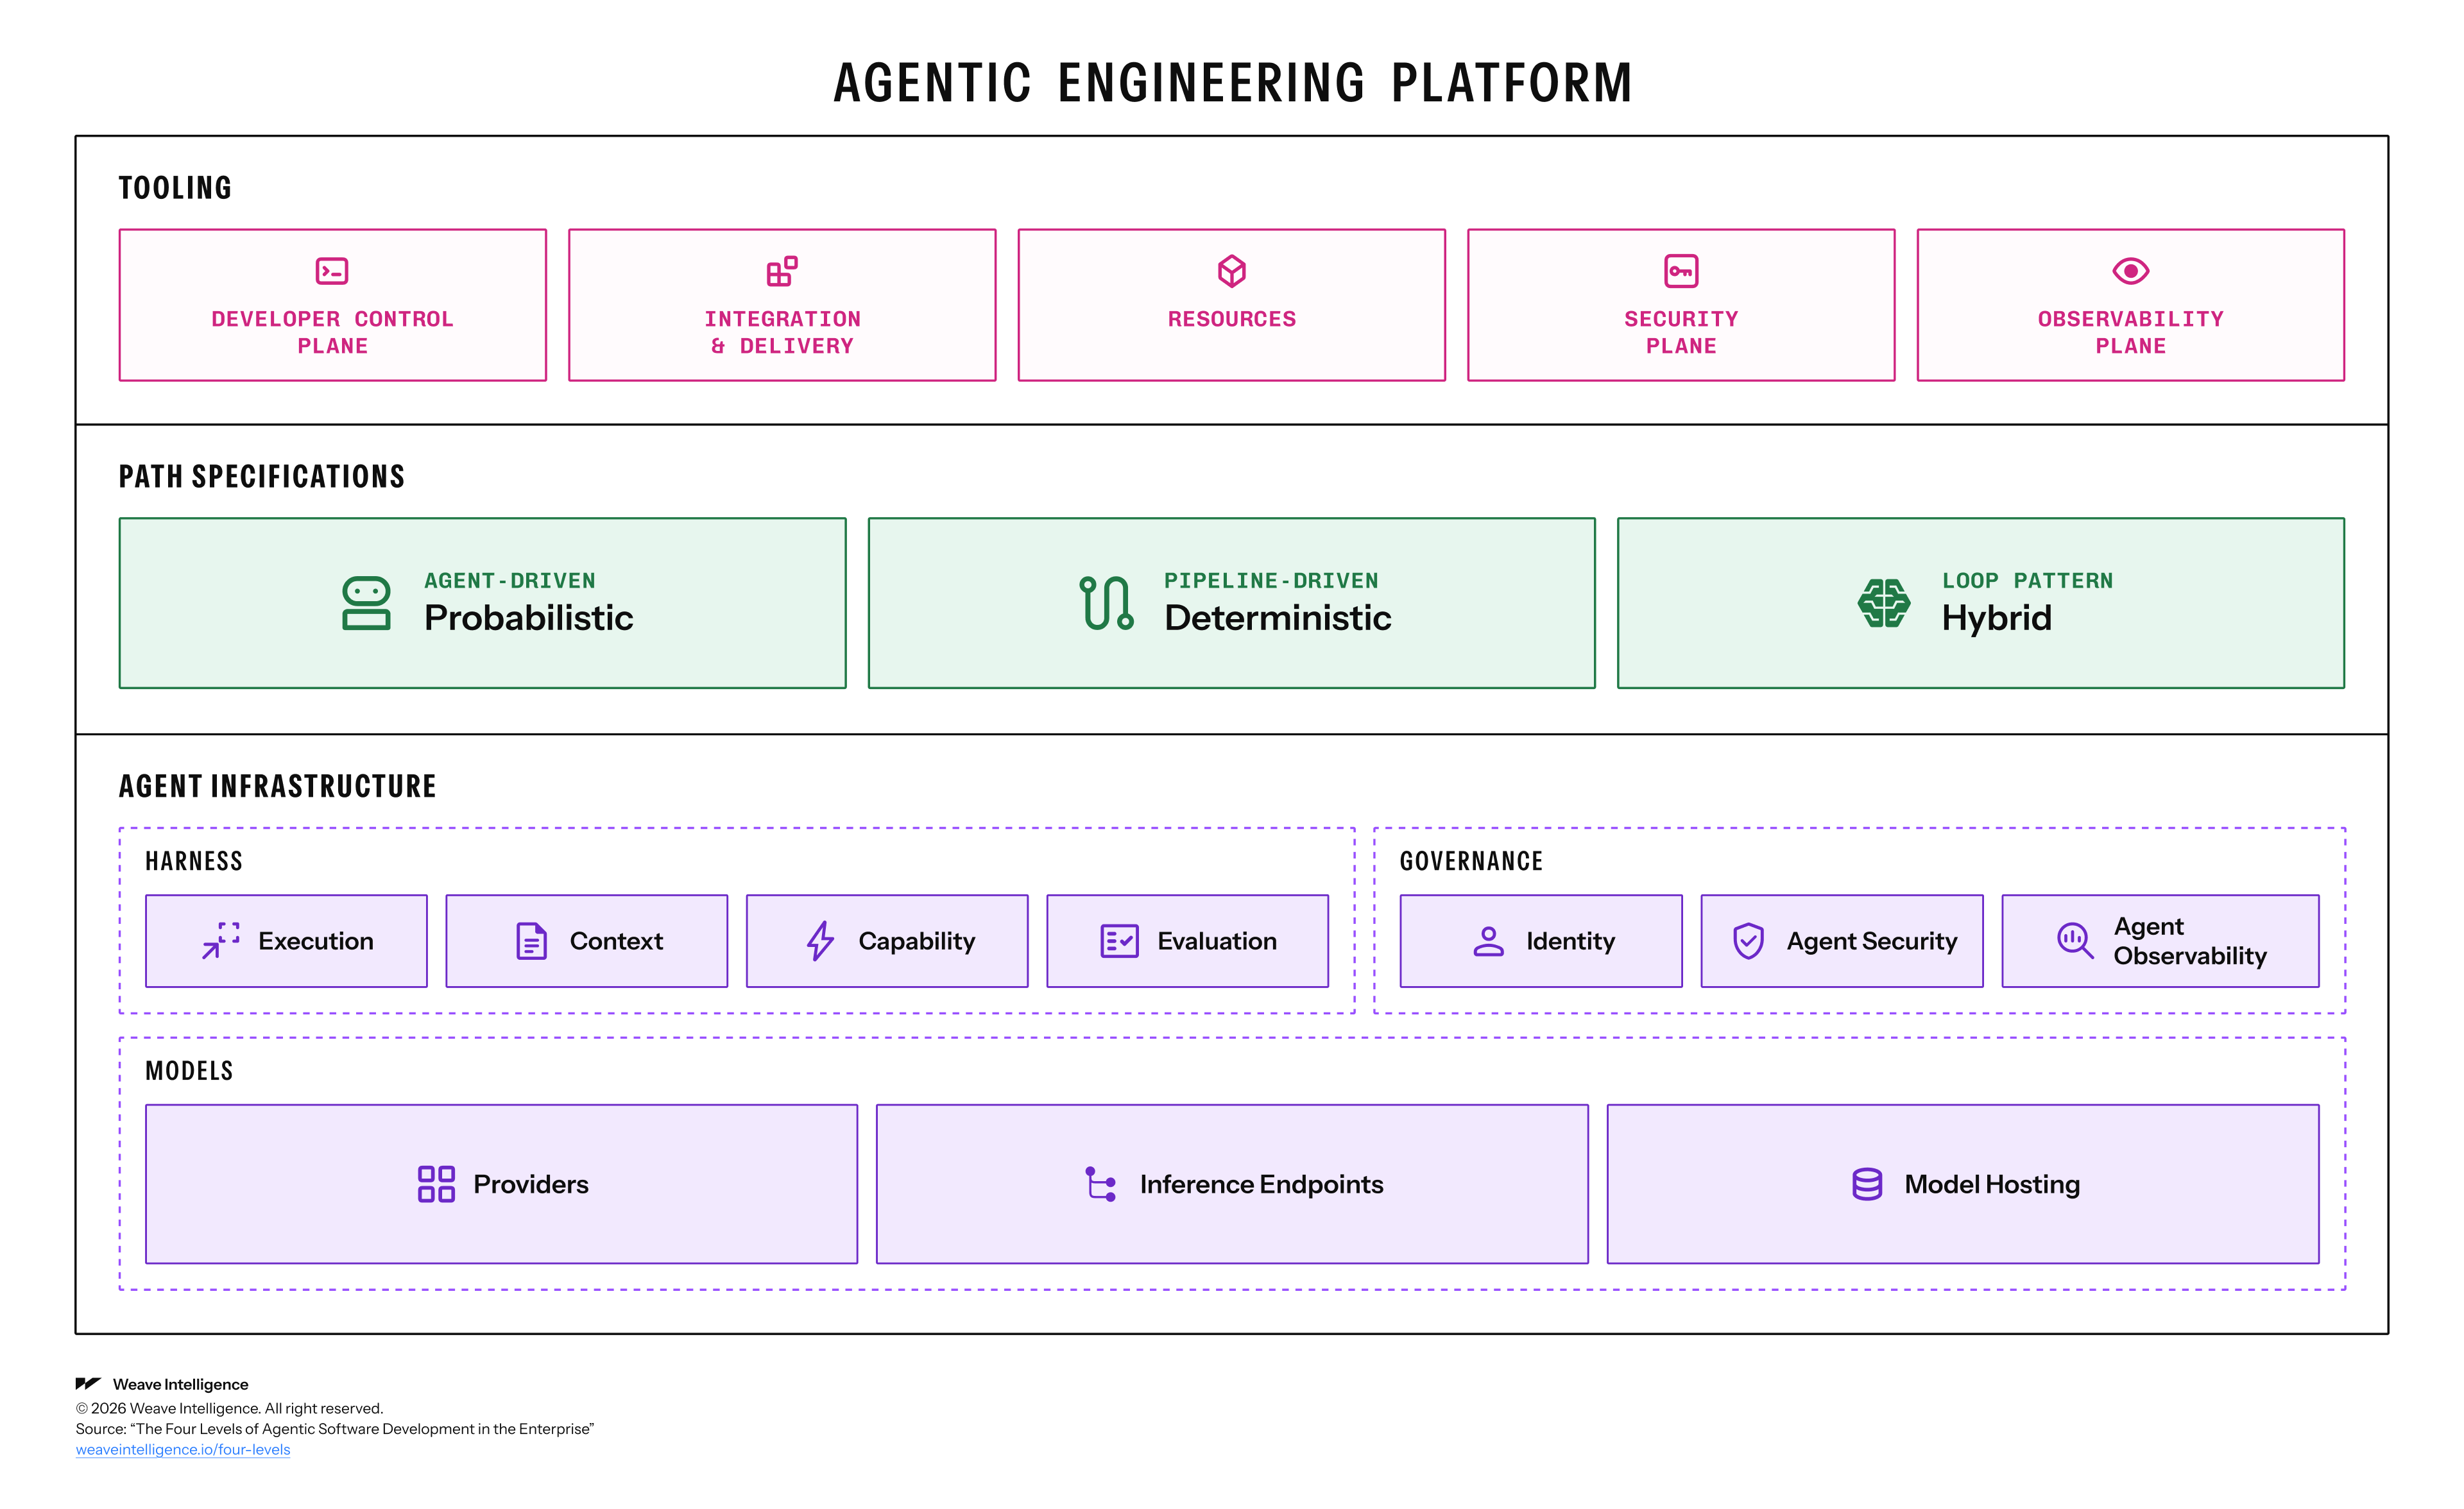
The organizations pulling ahead are not the ones with access to the best models. They are the ones who have restructured how software gets built. They have evolved their production systems to Agentic Engineering Platforms and let agents do real work, not just assist humans at the keyboard. It's hard to describe the difference between "using AI for autocomplete and a little research" and "orchestrating agents" to somebody who hasn't really felt it. But the difference in productivity is simply sparkling.那些脱颖而出的组织,并非是因为拥有最好的模型,而是因为他们重构了软件构建的方式。他们将生产系统演进为“代理工程平台”,让代理去执行真正的工作,而不仅仅是在键盘前辅助人类。对于那些尚未真正体验过的人来说,很难描述“使用 AI 进行自动补全和少量研究”与“编排代理”之间的区别。但生产力的差异是显而易见的。
The bottleneck is not model capability. Models are converging toward commodities. What separates organizations that see 30% throughput gains from those still waiting is the production system in which those models operate. An agent that cannot access your codebase reliably, runs under human credentials, has no sandboxed environment, and feeds into a validation process designed for one human-reviewed PR at a time cannot do much. The model is not the constraint. The platform is.瓶颈不在于模型能力。模型正趋于商品化。将那些实现 30% 吞吐量提升的组织与那些仍在观望的组织区分开来的,是这些模型运行所在的生产系统。一个无法可靠访问代码库、以人类身份运行、没有沙箱环境,且只能输入到那种一次处理一个人工审查 PR 的验证流程中的代理,发挥不了多大作用。限制因素不是模型,而是平台。
Over the past two years, through our research at Weave Intelligence and our advisory work with enterprise software teams, we have seen a consistent pattern emerge. There are four distinct levels of agentic development, each defined not by which AI tools you are using but by how much of the work humans still need to initiate and approve. As you move through them, the human role shifts from execution engine to reviewer to orchestrator to system designer. Understanding where your organization sits is the most important first step.在过去两年中,通过我们在 Weave Intelligence 的研究以及与企业软件团队的咨询工作,我们观察到了一种一致的模式。代理式开发分为四个明确的阶段,每个阶段的定义不在于你使用了哪些 AI 工具,而在于人类仍需发起和审批多少工作。随着你跨越这些阶段,人类的角色从执行引擎转变为审查者、编排者,最后是系统设计者。了解你的组织处于哪个阶段是迈出的最重要第一步。
The four levels四个阶段
The levels are defined by one thing: how much of the work humans still need to initiate and approve. As you move through them, the human role shifts from execution engine to reviewer to orchestrator to system designer.这些阶段由一点定义:人类仍需发起和审批多少工作。随着你跨越这些阶段,人类的角色从执行引擎转变为审查者、编排者,最后是系统设计者。

At Level 1, the human is still the execution engine. Agents assist, but humans approve everything. At Level 2, agents begin executing work in parallel, and humans verify outcomes rather than inspect every line. At Level 3, the platform runs continuously in the background, and human review becomes exception-based. At Level 4, the system initiates its own work in response to environmental signals, within guardrails set by humans.在第 1 阶段,人类仍然是执行引擎。代理提供辅助,但所有事项均需人类审批。在第 2 阶段,代理开始并行执行工作,人类验证结果而非检查每一行代码。在第 3 阶段,平台在后台持续运行,人类审查转变为基于异常的审查。在第 4 阶段,系统在人类设定的护栏内,根据环境信号自主发起工作。
Each level demands more from the underlying platform, but as we can see, none of them are achievable by choosing a better model; they require deliberate platform architecture decisions. Let’s walk through them one by one. 每个阶段都对底层平台提出了更高要求,但正如我们所见,仅靠选择更好的模型是无法实现这些阶段的;它们需要慎重的平台架构决策。让我们逐一了解。
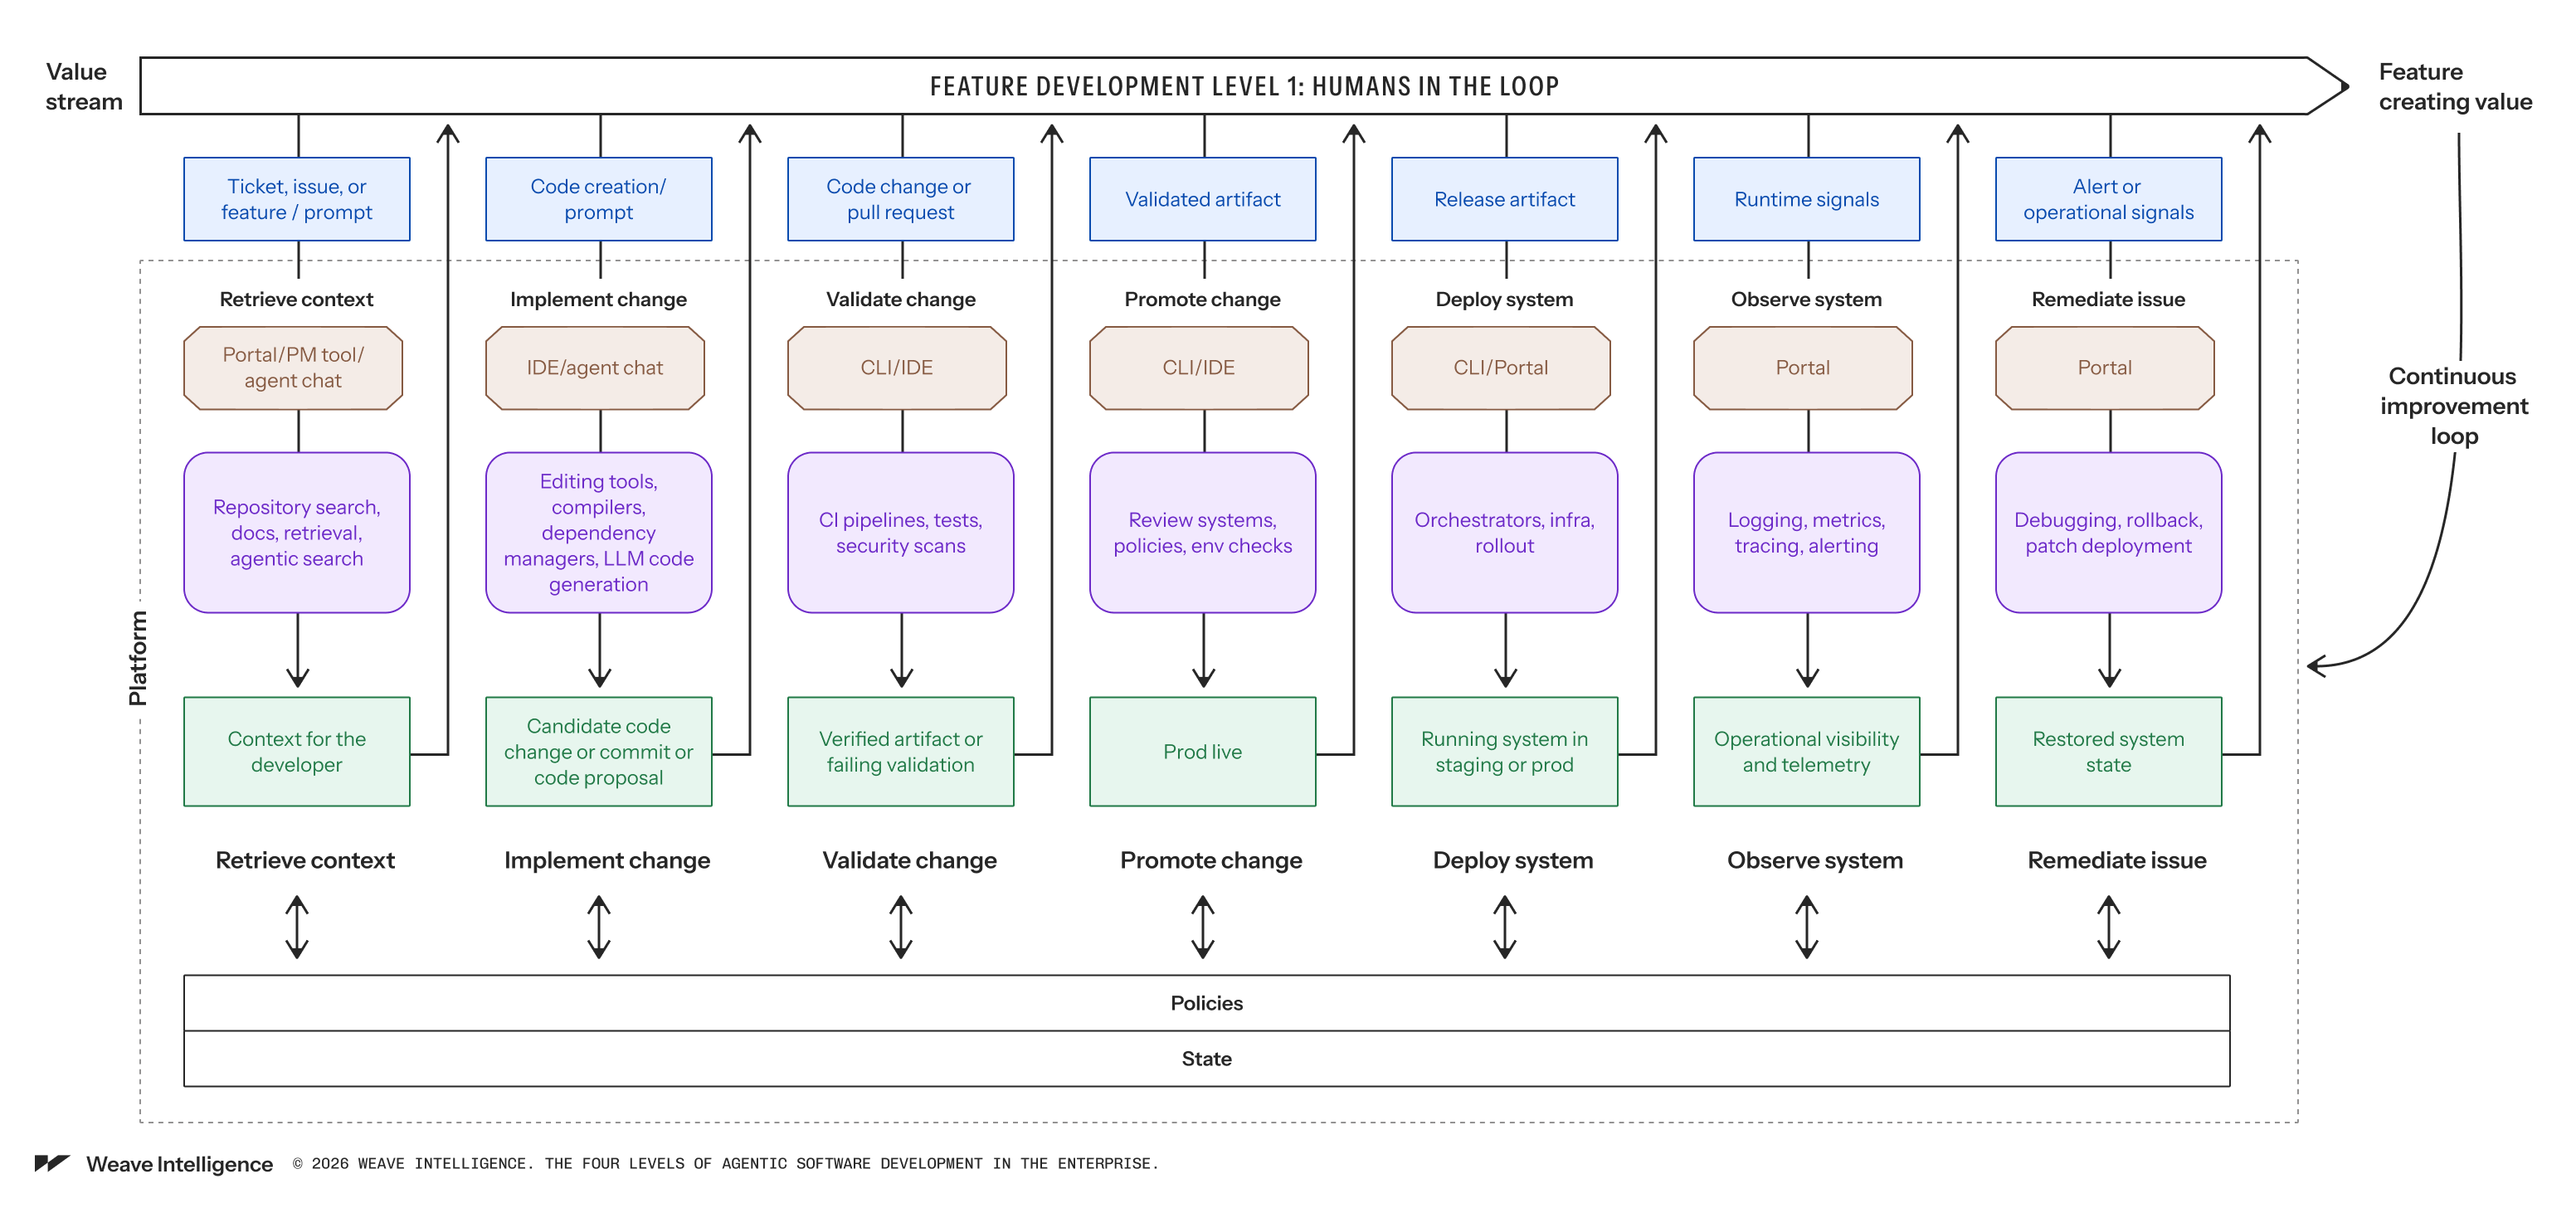
Level 1: Human in the loop第 1 阶段:人在回路 (Human in the loop)
Most enterprise software teams are here today. At that stage, agents suggest, and humans approve everything. The developer truly remains the execution engine.大多数企业软件团队目前处于这一阶段。在此阶段,代理提出建议,人类审批一切。开发人员实际上仍然是执行引擎。
In practice, this looks like AI autocomplete, prompt-driven code generation, and the use of agents to understand unfamiliar parts of the system. The developer takes the output, modifies it, and decides what to include in the codebase. The platform does not need to change to support this.在实践中,这表现为 AI 自动补全、提示词驱动的代码生成,以及使用代理来理解系统中不熟悉的部分。开发人员获取输出、修改它,并决定将什么内容包含在代码库中。平台无需为了支持这一点而进行变更。
The gains at this level are, of course, real, but they are limited. Output is still constrained by human review bandwidth, which means one person, one keyboard, one PR at a time.这一阶段的收益当然是真实的,但也是有限的。产出仍然受限于人类审查的带宽,这意味着一次只能处理一个人、一个键盘、一个 PR。
Level 2: Humans on the loop第 2 阶段:人在回路旁 (Humans on the loop)
This is where things get genuinely different, and where most organizations underestimate the platform work required.这是真正发生质变的地方,也是大多数组织低估了所需平台工作量的地方。
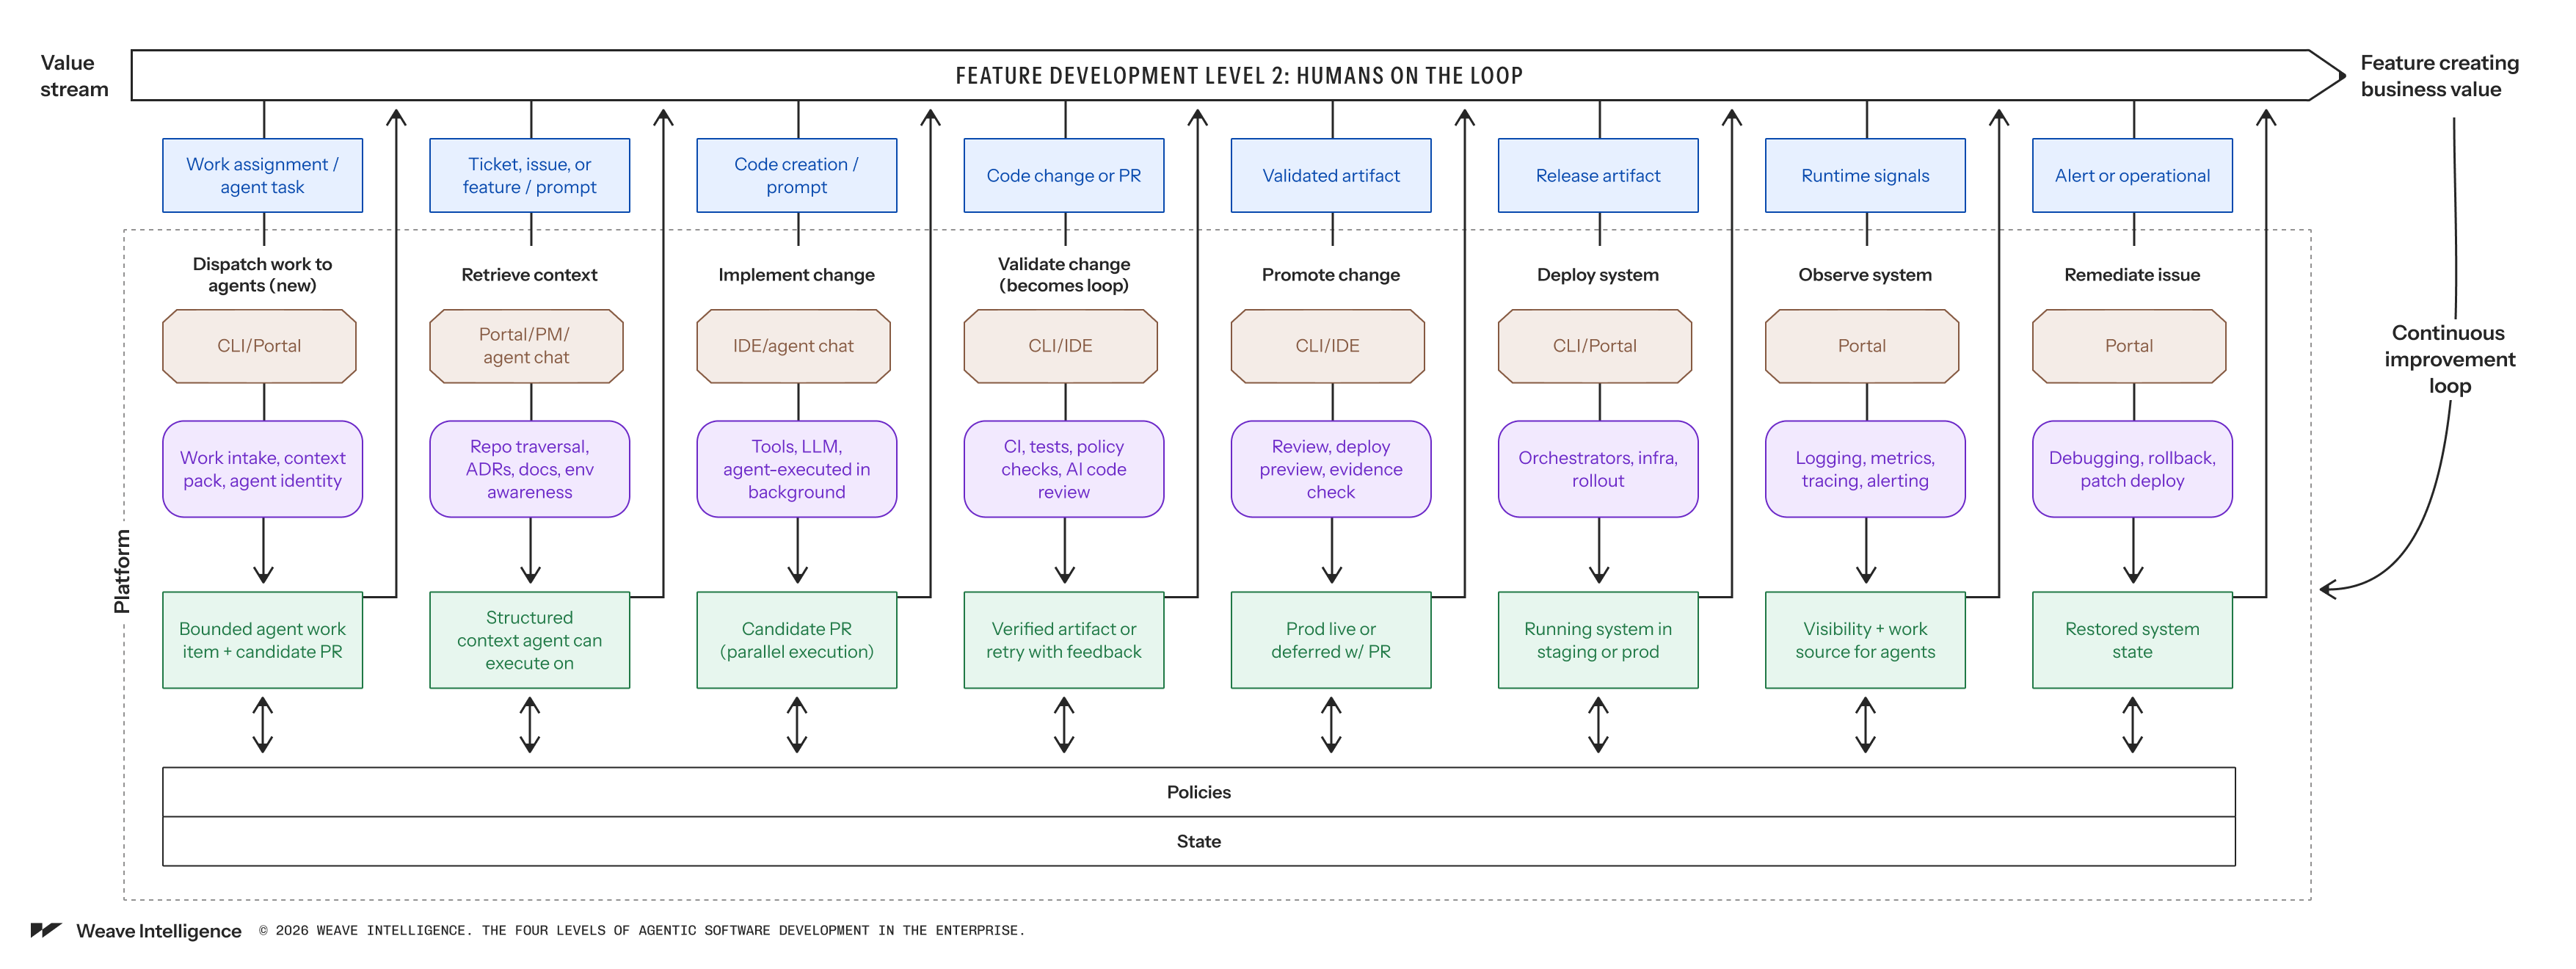
At Level 2, agents stop being a private tool on a workstation and become participants in the value stream. Humans dispatch agents to handle chunks of work on their behalf. This concretely means: Multiple agents work in parallel in the background. At all times, multiple PRs advance simultaneously, and the human is no longer the execution engine, but the human still decides what to advance.在第 2 阶段,代理不再是工作站上的私有工具,而是价值流的参与者。人类派遣代理代表他们处理部分工作。具体而言:多个代理在后台并行工作。此时,多个 PR 同时推进,人类不再是执行引擎,但人类仍然决定推进什么。
This is the first real parallelization. Not more developers, but more work items moving forward at the same time because agents are doing the execution.这是第一次真正的并行化。不是增加开发人员,而是因为代理在执行工作,使得更多工作项得以同时推进。
The platform has to change meaningfully to support this. A new golden path appears: we call it “dispatch work to agents”. The platform must now manage agent identity, provision sandboxed environments per agent session, enforce resource limits, and package context in a way that agents can actually act on. Without this infrastructure, agents collide, consume unbounded compute, and produce outputs that the system cannot safely evaluate.平台必须进行重大变革来支持这一点。一条新的黄金路径出现了:我们称之为“将工作派遣给代理”。平台现在必须管理代理身份、为每个代理会话提供沙箱环境、强制执行资源限制,并以代理能够实际操作的方式打包上下文。如果没有这种基础设施,代理会发生冲突、消耗无限计算资源,并产生系统无法安全评估的输出。
The most important structural change at Level 2 concerns validation. At Level 1, validation is a gate: a human walks a PR through CI, reviews the diff, and approves it. At Level 2, that model breaks immediately. Agents generate changes at volumes and cadences that human review cannot match. And so to support that, validation has to become a loop.第 2 阶段最重要的结构性变化涉及验证。在第 1 阶段,验证是一个关卡:人类引导 PR 通过 CI,审查差异并批准它。在第 2 阶段,该模型立即失效。代理生成的变更数量和频率是人工审查无法匹配的。因此,为了支持这一点,验证必须变成一个循环。
The agent generates a lot of output. The platform runs automated checks: tests, security scans, and policy evaluation. If the output fails, the failure is routed back to the agent, which modifies and retries—the human reviews aggregate results, not individual diffs. Instead of reading code line by line, the human is verifying behavior: does this work the way it should?代理生成大量输出。平台运行自动化检查:测试、安全扫描和策略评估。如果输出失败,失败信息会被路由回代理,代理进行修改并重试——人类审查的是汇总结果,而非单个差异。人类无需逐行阅读代码,而是验证行为:这是否按预期工作?
This shift is, in reality, harder than it sounds. It requires comprehensive automated testing, security scanning integrated into the pipeline, and policy enforcement as deterministic gates rather than manual audits. If you think about it, you have to balance the slight randomness of probabilistic systems with the somewhat dumb predictability of deterministic ones. Getting this right is what makes Level 2 sustainable instead of chaotic. Organizations that skip this work and just start dispatching agents at scale hit a wall fast: CI pipelines saturate, review queues explode, and teams lose trust in the outputs.这种转变实际上比听起来更难。它需要全面的自动化测试、集成到流水线中的安全扫描,以及作为确定性关卡而非人工审计的策略执行。如果你思考一下,你必须平衡概率系统的轻微随机性与确定性系统某种程度上的可预测性。做好这一点是使第 2 阶段可持续而非陷入混乱的关键。那些跳过这些工作而直接开始大规模派遣代理的组织会很快碰壁:CI 流水线饱和、审查队列爆炸,团队对输出失去信任。
The jump from Level 1 to Level 2 is the hardest transition in the model, and the one with the biggest payoff.从第 1 阶段到第 2 阶段的跨越是模型中最难的转型,也是回报最大的转型。
Level 3: Humans as orchestrators第 3 阶段:人作为编排者 (Humans as orchestrators)
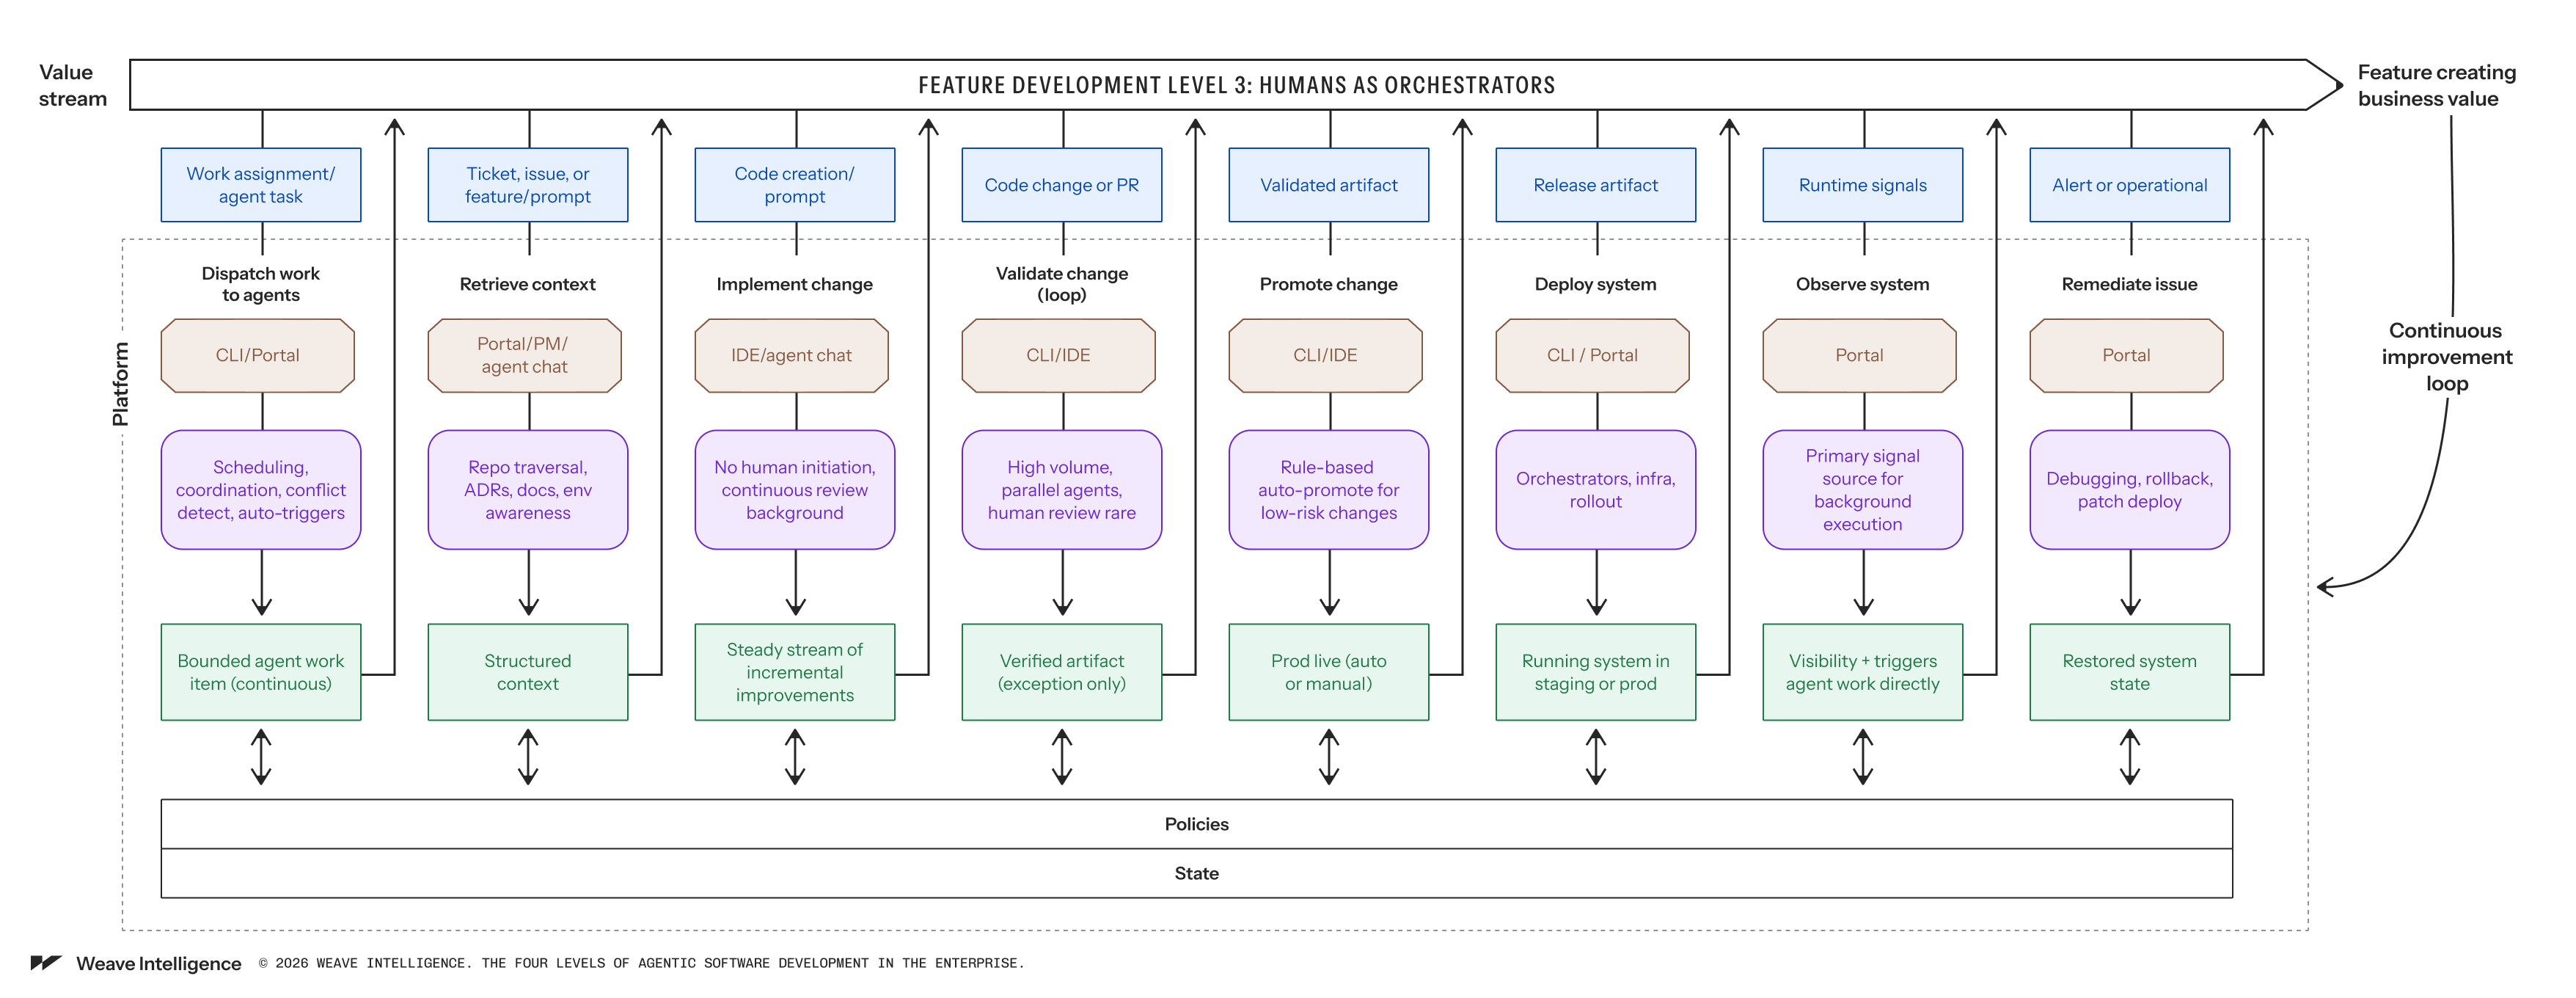
At Level 3, the platform starts to run continuously in the background. Agents no longer wait for a human to send them work. The system begins generating work based on what it observes.在第 3 阶段,平台开始在后台持续运行。代理不再等待人类发送工作。系统开始根据其观察到的情况生成工作。
A failing dependency check triggers an agent to generate a fix. A security advisory lands, and agents begin assessing exposure across the codebase and generating patches. A recurring operational anomaly is automatically routed to an agent workflow. The human defines the rules, and the platform executes them. 失败的依赖项检查会触发代理生成修复程序。安全公告发布后,代理开始评估整个代码库的风险暴露情况并生成补丁。重复出现的运营异常会自动路由到代理工作流。人类定义规则,平台执行规则。
Human review becomes exception-based. Instead of approving individual changes, humans design the policies that determine when the system may advance work on its own. Low-risk changes, dependency updates, small performance improvements, and well-understood operational fixes can be promoted automatically once validation evidence is sufficient. Humans review the exceptions and the rules, not every change.人工审查变为基于异常的审查。人类不再审批单个变更,而是设计决定系统何时可以自主推进工作的策略。低风险变更、依赖项更新、小幅性能改进和众所周知的运营修复,在验证证据充分的情况下可以自动推进。人类审查的是异常和规则,而不是每一个变更。
There are already a surprising number of organizations at Level 3, or approaching it, particularly for their frontend estates. This is not a future state. It is a present reality for teams that have done the platform work.已经有相当数量的组织处于第 3 阶段或正接近该阶段,特别是在前端领域。这并非未来状态,而是那些已经完成平台工作的团队的当前现实。
The constraint at this level shifts from review bandwidth to architectural maturity and cost management. Token economics becomes a real concern. An organization running agents continuously in the background on thousands of changes needs to govern what that costs, not just whether it is safe.这一阶段的约束从审查带宽转向了架构成熟度和成本管理。代币经济学成为一个真正的考量因素。一个在后台持续运行代理处理数千个变更的组织,需要管控其成本,而不仅仅是安全性。
Level 4: Fully autonomous第 4 阶段:完全自主 (Fully autonomous)
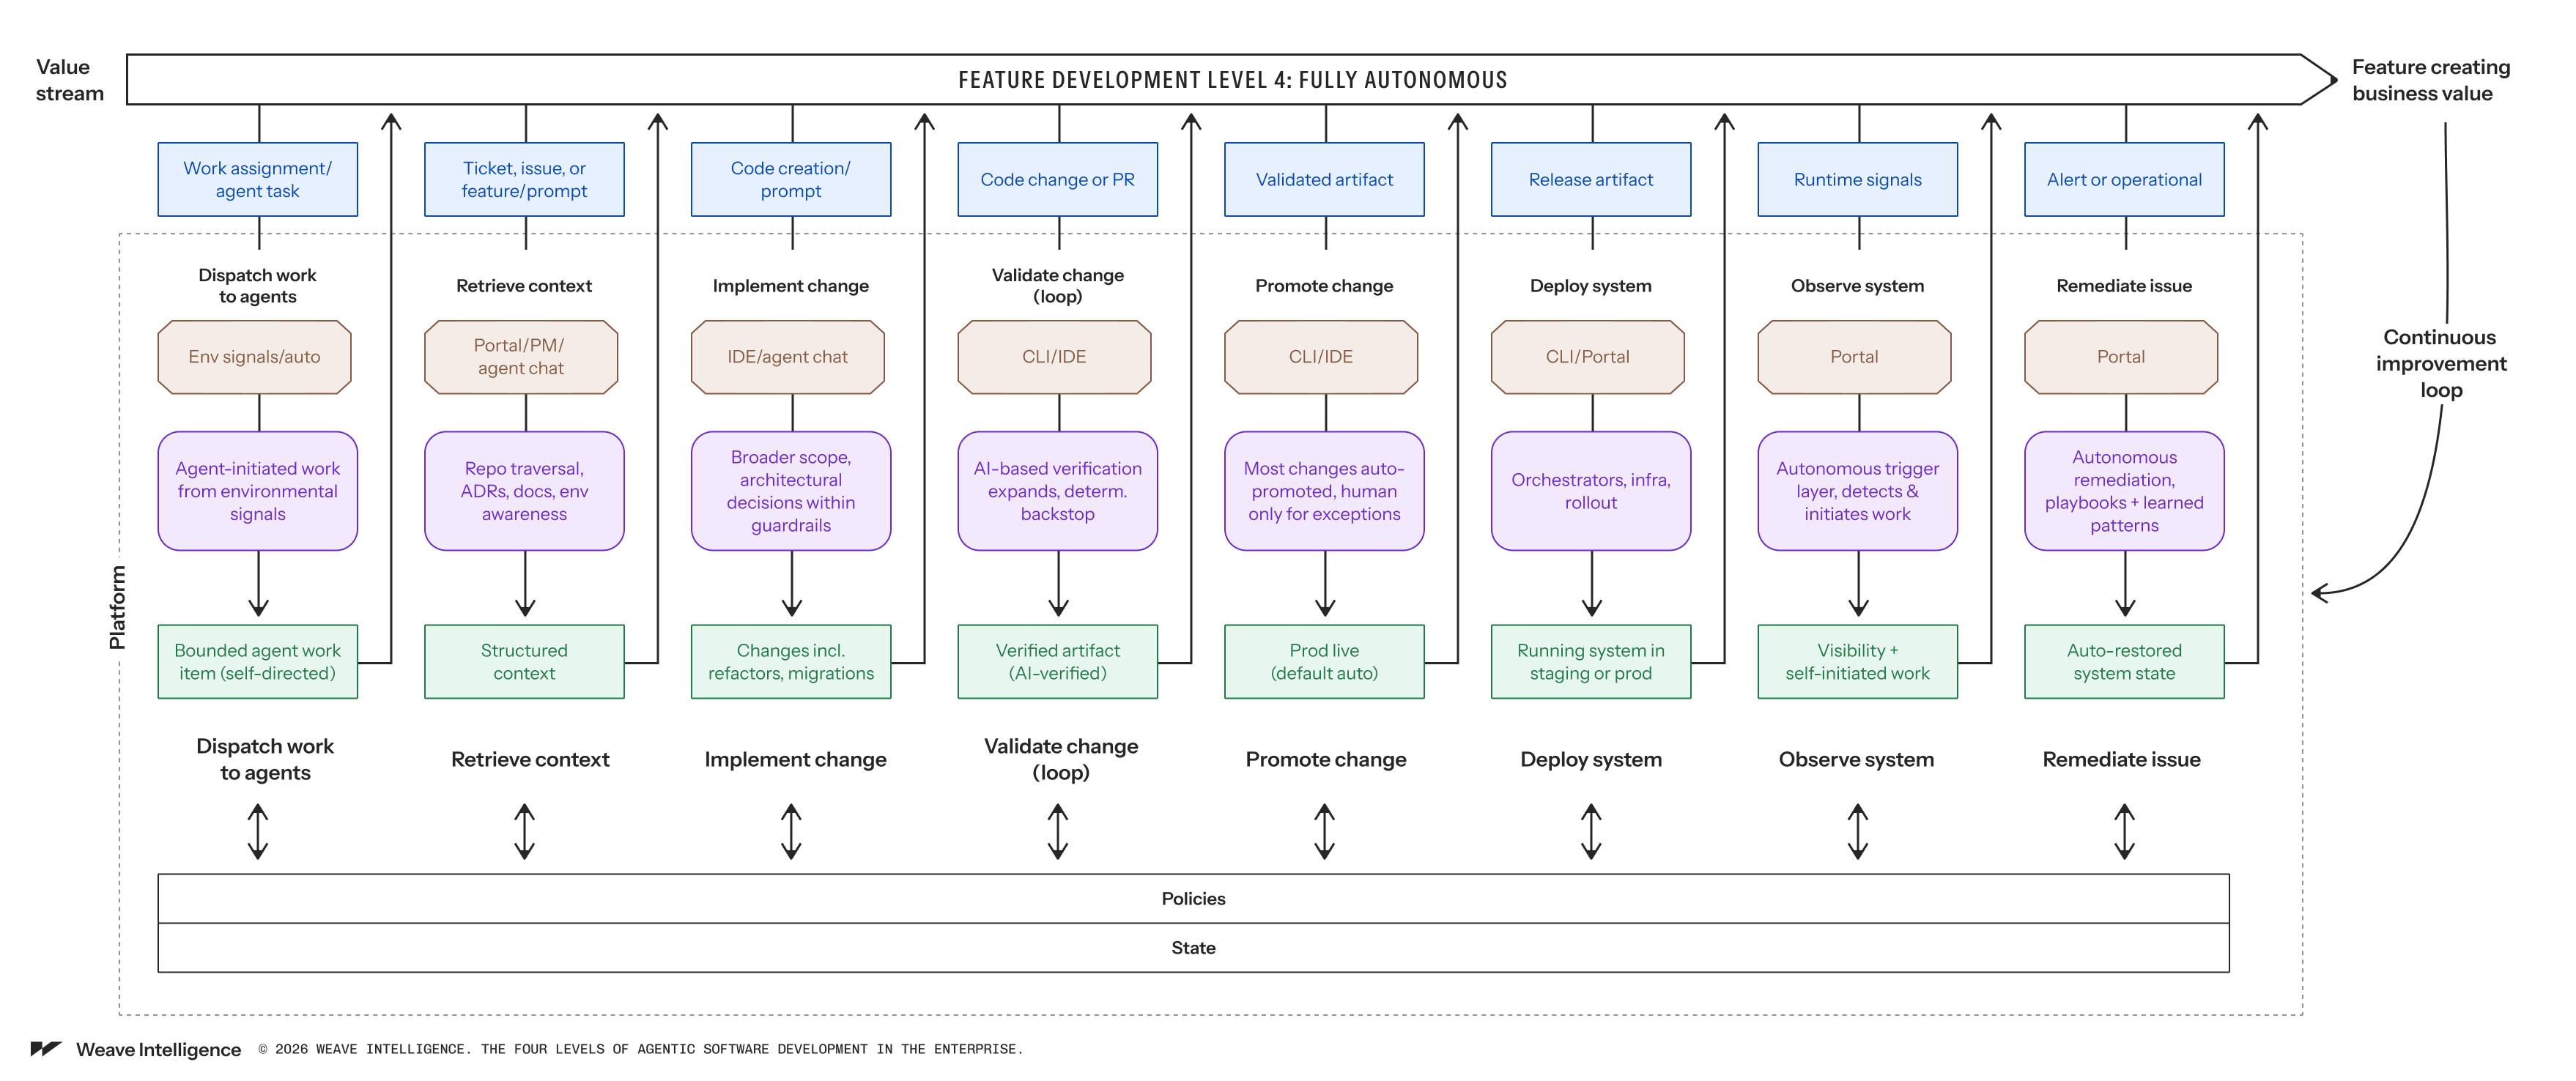
Level 4 is where the production system becomes partially self-adjusting. Agents monitor environmental signals, customer behavior, operational telemetry, security findings, cost anomalies, and initiate new paths autonomously within predefined guardrails. They open tickets, propose changes, remediate issues, and adapt configurations without waiting for a human to ask.第 4 阶段是生产系统变得部分自我调节的阶段。代理监控环境信号、客户行为、运营遥测、安全发现、成本异常,并在预定义的护栏内自主发起新路径。它们无需等待人类请求,即可开票、提出变更、修复问题并调整配置。
We want to be clear: very few organizations operate at this level today. We are aware of isolated examples, including a SaaS company where agents listen to customer calls, detect bugs mentioned in those calls, and automatically generate fixes. But we frame Level 4 as a projection of the trajectory we are observing, not a description of widespread current practice. There is, however, no technical reason we will not get there. In hindsight, it's obvious that automated trading systems can move markets at high speed. At the time that idea felt utterly absurd, we believe the same applies here. Given the deterministic nature of software, this is a question of inference, balance of power with guardrails, and a high frequency of recurring attempts. 我们需要明确一点:今天很少有组织处于这一阶段。我们知道一些孤立的例子,包括一家 SaaS 公司,其代理能够监听客户通话、检测通话中提到的错误并自动生成修复程序。但我们将第 4 阶段定位为我们观察到的轨迹的预测,而非对当前广泛实践的描述。然而,没有任何技术原因阻碍我们达到这一水平。事后看来,自动化交易系统能够高速推动市场是显而易见的。在当时,那个想法听起来极其荒谬,我们相信这里的情况也是如此。鉴于软件的确定性本质,这是一个关于推理、护栏下的权力平衡以及高频重复尝试的问题。
What makes Level 4 structurally significant is not the autonomy itself. It is what the autonomy enables: Continuous large-scale refactoring that would never get prioritized when humans have to execute every step. Or proactive security patching at the speed of CVE publication rather than quarterly cycles. Demand-responsive infrastructure adaptation without a human interpreting a dashboard first, and definitely self-improving validation loops that update their own rules based on failure patterns.第 4 阶段在结构上的意义不在于自主本身,而在于自主所带来的能力:人类必须执行每一步时永远无法优先处理的持续大规模重构;或者以 CVE 发布的速度而非季度周期进行主动安全补丁修复;无需人类先解读仪表盘即可实现的需求响应式基础设施自适应;以及根据失败模式更新自身规则的自我改进验证循环。
At Level 4, platform engineers stop thinking primarily about software development as a human workflow. They think of it as an autonomous production process that continuously adapts software to the environment inside a set of deterministic guardrails they design and own. In our high-frequency trading analogy, we’re moving from traders to system builders.
在第 4 阶段,平台工程师不再主要将软件开发视为人类工作流。他们将其视为一种自主生产过程,在他们设计和拥有的确定性护栏内,持续根据环境调整软件。用我们的高频交易类比,我们正在从交易员转向系统构建者。
Where does your organization sit?你的组织处于什么位置?
The honest answer for most enterprise teams is somewhere between Level 1 and Level 2, with some teams starting to see the edge of Level 3.对于大多数企业团队来说,诚实的回答是处于第 1 阶段和第 2 阶段之间,一些团队开始看到第 3 阶段的边缘。
The question to ask is not "which model are we using?" It is "What does our platform actually support?" If agents cannot reliably retrieve context, they are stuck at Level 1. If validation is still a single human-reviewed gate, you cannot scale to Level 2 without drowning your CI pipeline. If the platform has no concept of non-human identity, you cannot govern which agents are allowed to do what.要问的问题不是“我们在使用哪个模型?”,而是“我们的平台实际上支持什么?”如果代理无法可靠地检索上下文,它们就停留在第 1 阶段。如果验证仍然是一个单一的人工审查关卡,如果不淹没 CI 流水线,你就无法扩展到第 2 阶段。如果平台没有非人类身份的概念,你就无法管理哪些代理被允许做什么。
These are platform problems. And they are exactly the problems that platform engineers are best positioned to solve.这些都是平台问题。而这正是平台工程师最擅长解决的问题。
The organizations that understand this and act on it now are not just improving developer productivity. They are redesigning their production systems in a way that compounds. The gap between them and organizations still waiting to see how the AI landscape settles is growing every quarter.那些理解这一点并立即采取行动的组织,不仅仅是在提高开发人员的生产力。他们正在以一种能够产生复合效应的方式重塑其生产系统。他们与那些仍在观望 AI 格局如何定型的组织之间的差距,每个季度都在扩大。
If you want to learn more, check out the State of AI in Platform Engineering volume 2.如果你想了解更多,请查看《平台工程中的 AI 现状》第二卷。