The following article originally appeared on Vanishing Gradients and is being republished here with the authors’ permission本文最初发表于 Vanishing Gradients,现经作者许可在此转载。
When an AI agent can explore a dataset, choose a modeling approach, run the analysis, and explain its findings, what should the data scientist do?当人工智能代理能够探索数据集、选择建模方法、运行分析并解释其发现时,数据科学家应该做什么?
Traditionally, data scientists chose each step and implemented much of the analysis themselves. Agentic data science changes that division of work: we can delegate an investigation, including methodological choices, while shaping the question, supplying relevant expertise, and challenging the evidence it produces. For AI-native data scientists, choosing the runtime, writing reusable skills, and designing the workflows and feedback that guide the agent are part of the analytical work.传统上,数据科学家会亲自选择每一步骤并实现大部分分析。代理式数据科学改变了这种分工:我们可以在塑造问题、提供相关专业知识并质疑其产出证据的同时,将调查工作(包括方法论的选择)委托给代理。对于“AI 原生”数据科学家而言,选择运行时、编写可重用的技能,以及设计引导代理的工作流和反馈机制,都是分析工作的一部分。
This article provides a playbook for working with data science agents, from setting up an investigation to reviewing its results and carrying lessons into the next assignment. To see why that requires more than a capable model and a business question, consider an experiment we deliberately started with too little guidance. We gave Claude Opus 5.0 a modified version of the public Elliptic dataset and asked, “Build me a model to detect fraudulent nodes.” The dataset is a graph of Bitcoin transactions: each node is a transaction, and an edge represents a flow of bitcoin between transactions. Some transaction nodes carry licit or illicit labels based on the entities that created them; the rest are unlabeled. Each node has a time step indicating when its transaction was broadcast, allowing us to train on earlier time steps and test on later ones. We also wanted separate results for transactions with many connections (high-degree nodes), which mattered most in the intended application. Importantly, we renamed the columns, changed several features, and reindexed the time steps while preserving their order, making the public dataset harder for Claude to recognize.本文提供了一份与数据科学代理合作的实战手册,涵盖了从启动调查到审查结果,再到将经验应用到下一个任务的全过程。为了说明为什么这不仅仅需要一个强大的模型和一个业务问题,请考虑我们故意在指导不足的情况下开始的一个实验。我们向 Claude Opus 5.0 提供了公开 Elliptic 数据集的修改版本,并要求它:“为我构建一个检测欺诈节点的模型。”该数据集是一个比特币交易图:每个节点代表一笔交易,边代表交易间的比特币流动。一些交易节点根据其创建实体带有合法或非法的标签;其余则未加标签。每个节点都有一个时间步长,指示交易广播的时间,使我们能够在较早的时间步长上进行训练,并在较晚的时间步长上进行测试。我们还希望针对连接数较多的交易(高度节点)获得单独的结果,这在预期的应用中最为重要。重要的是,我们重命名了列、更改了几个特征,并重新索引了时间步长,同时保持了它们的顺序,这使得 Claude 更难识别出这个公开数据集。
Claude wrote the code, trained a random forest, and reported an F1 of 0.87 and ROC AUC of 0.99. It had split transactions randomly, mixing earlier and later time steps in both the training and test sets. That test did not measure how the model would perform on transactions from later time steps. Moreover, Claude also used a feature we had planted as a proxy for the fraud label (yes, we tricked it!), giving the model leaked information it would not have when scoring a new transaction. So how do we avoid these situations?Claude 编写了代码,训练了一个随机森林模型,并报告 F1 分数为 0.87,ROC AUC 为 0.99。它随机拆分了交易,在训练集和测试集中混合了较早和较晚的时间步长。该测试并未衡量模型在较晚时间步长的交易上的表现。此外,Claude 还使用了我们植入的一个作为欺诈标签代理的特征(没错,我们欺骗了它!),这给了模型它在对新交易进行评分时本不应获得的信息。那么,我们该如何避免这些情况呢?
We then supplied the guidance missing from the initial prompt: We required a temporal holdout, removed the leaking feature, supplied context about how the model would be used in production, and asked for separate reporting on the high-degree nodes that mattered most. Under the corrected evaluation, F1 was 0.70, overall recall was 0.61, and recall on high-degree nodes was 0.21.随后,我们提供了最初提示中缺失的指导:我们要求进行时间上的留存验证(temporal holdout),移除了泄露特征,提供了关于模型如何在生产环境中使用的背景信息,并要求针对最重要的高度节点进行单独报告。在修正后的评估下,F1 分数为 0.70,整体召回率为 0.61,高连接度节点的召回率为 0.21。
The key point is that “Build a fraud detector” left Claude to infer how the model would be used and what would count as success. AI-native data scientists build and direct an analytical process in which agents can investigate, receive feedback, and return evidence for review. The work begins with deciding how much of the investigation to delegate. Agentic data science is doing data science work with AI agents as teammates. Crucially, the scope of their responsibility can extend well beyond code implementation. An agent can help frame a question, explore data, test a claim, or communicate a result, provided it has the context and tools to do the work, a way to assess its progress and validate its results.关键点在于,“构建一个欺诈检测器”让 Claude 自己去推断模型将如何使用以及什么才算成功。AI 原生数据科学家构建并指导一个分析过程,代理可以在其中进行调查、接收反馈并返回证据供审查。工作始于决定委托多少调查内容。代理式数据科学就是与 AI 代理作为队友共同完成数据科学工作。至关重要的是,它们的责任范围可以远远超出代码实现。只要代理拥有完成工作所需的背景和工具,以及评估其进度和验证其结果的方法,它就可以帮助构思问题、探索数据、测试主张或传达结果。
Asking an agent to write a pandas transformation leaves you as the bottleneck, responsible for deciding every next operation. Asking it to investigate a change in customer behavior gives it larger analytical responsibility. It can inspect a result, form another question, choose a method, and continue. The interaction becomes a conversation about the investigation rather than a sequence of requests for code.要求代理编写 pandas 转换代码会将你置于瓶颈位置,你需要负责决定每一个后续操作。而要求它调查客户行为的变化则赋予了它更大的分析责任。它可以检查结果、提出另一个问题、选择方法并继续进行。互动变成了关于调查本身的对话,而不是一系列的代码请求。
The question may be descriptive (what happened?), diagnostic (why did it happen?), predictive (what might happen next?), or prescriptive (what should we do?). The fraud model is predictive; the pricing investigation later in this article is diagnostic and causal. Across these kinds of work, we need to specify the question and intended use, then verify that the evidence supports the answer.问题可以是描述性的(发生了什么?)、诊断性的(为什么会发生?)、预测性的(接下来可能会发生什么?)或规范性的(我们应该怎么做?)。欺诈模型是预测性的;本文稍后提到的定价调查则是诊断性和因果性的。在这些工作中,我们需要明确问题和预期用途,然后验证证据是否支持结论。
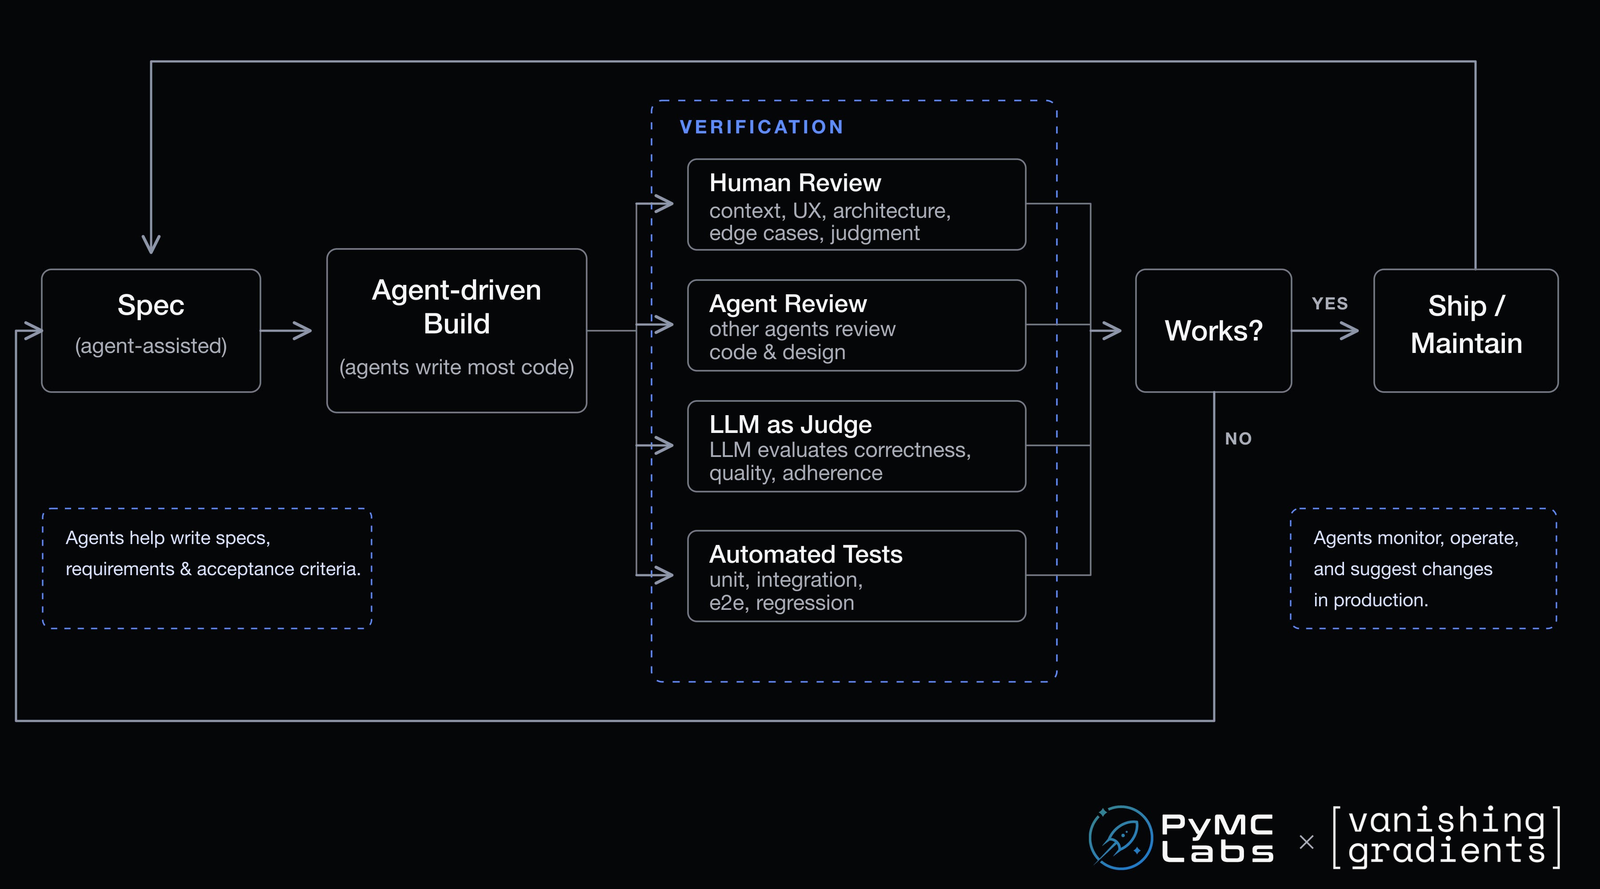
The following five practices are key to agentic data science:以下五种实践是代理式数据科学的关键:
- Frame the investigation.1. 构思调查框架。
- Equip the agent for the assignment.2. 为代理配备任务所需资源。
- Organize the work through bounded experiments, competing analyses, or both, according to the question.3. 根据问题,通过有界实验、竞争性分析或两者结合来组织工作。
- Review the result independently.4. 独立审查结果。
- Preserve evidence and turn reviewed lessons into reusable expertise.5. 保存证据,并将审查后的经验转化为可重用的专业知识。
The first two practices set up the work. The third determines how the investigation proceeds; the fourth tests its claims. Evidence is captured throughout, and the fifth practice carries reviewed lessons into future assignments.前两种实践用于设定工作。第三种决定了调查的进行方式;第四种测试其主张。证据在整个过程中被捕获,第五种实践则将审查后的经验带入未来的任务中。
As in agentic software engineering, the agentic data scientist’s two central responsibilities are specification and verification. Specify the question, intended use, and evidence the agent should produce; then verify that its analysis supports the conclusion. Agents can help with both, while the data scientist remains responsible for judging the question and the evidence.正如在代理式软件工程中一样,代理式数据科学家的两个核心职责是规范(specification)和验证(verification)。明确问题、预期用途和代理应产出的证据;然后验证其分析是否支持结论。代理可以协助完成这两项工作,而数据科学家则负责判断问题和证据。
1. Frame the investigation with the agent1. 与代理共同构思调查框架
Start by discussing the assignment with the agent. Supply the intended use and organizational context, then let it inspect the data and propose an approach. Method selection can be part of its responsibility. Your intervention matters when a proposal changes the question, rests on a questionable assumption, or needs information the agent cannot obtain. Predicting fraud and deciding which flagged entities to investigate, for example, require different evidence about errors and their consequences. A brainstorming skill such as those in Superpowers can help structure that conversation before you turn it into a task prompt.首先与代理讨论任务。提供预期用途和组织背景,然后让它检查数据并提出方法。方法选择可以成为其职责的一部分。当提案改变了问题、建立在可疑假设之上,或者需要代理无法获取的信息时,你的干预就至关重要。例如,预测欺诈并决定调查哪些被标记的实体,需要关于错误及其后果的不同证据。像 Superpowers 中那样的头脑风暴技能可以帮助你在将其转化为任务提示之前构建对话结构。
A useful specification records that shared understanding. It states the decision, relevant constraints, and evidence the investigation should produce. It need not prescribe every step. In the fraud example, “classify transactions from later time steps using only information available when each is scored” matters more than “use a random forest.” The former defines the analytical task, while the latter selects one possible implementation.一份有用的规范记录了这种共识。它陈述了决策、相关约束以及调查应产出的证据。它不需要规定每一个步骤。在欺诈示例中,“使用仅在评分时可用的信息对较晚时间步长的交易进行分类”比“使用随机森林”更重要。前者定义了分析任务,而后者只是选择了一种可能的实现方式。
You can specify what the investigation must establish without specifying the answer you want. “Determine whether the data support a recommendation” leaves room for an inconclusive result. “Keep trying until you find an effect” does not.你可以指定调查必须确立的内容,而无需指定你想要的答案。“确定数据是否支持某项建议”为不确定的结果留出了空间。而“不断尝试直到你发现某种影响”则不然。
Turn that discussion into a short analytical brief to give the agent as its task prompt. For an assignment like our fraud example, a starting version could read:将讨论转化为简短的分析简报,作为任务提示提供给代理。对于像我们欺诈示例这样的任务,初始版本可以是:
TASK PROMPT:
Question: Can we identify fraudulent nodes as they enter the network?
Use: Support investigation, with separate reporting on high-degree nodes.
Available information: Only inputs known when the node is scored.
Agent discretion: Explore data, propose eligible features, choose models.
Return to me: Unclear feature provenance, changes to the target or
population, or a trade-off that requires an operational decision.
Deliverable: Reproducible analysis, temporal evaluation, subgroup errors,
and a recommendation that states what the evidence cannot establish.
Review it with the agent before the investigation proceeds. If exploration reveals that the evidence cannot answer the question, revise the brief explicitly; do not quietly substitute an easier question.在调查进行前与代理一起审查简报。如果探索发现证据无法回答问题,请明确修改简报;不要默默地替换成一个更简单的问题。
The deliverable may still be a notebook, model, or report prepared outside a production service. You can begin in the workspace where you already do that work.交付物仍然可以是生产服务之外准备的笔记本、模型或报告。你可以从你已经在进行此类工作的空间开始。
2. Equip the agent for the assignment2. 为代理配备任务所需资源
The task prompt tells the agent what to investigate. It also needs to know how the project works, reach the data, run the analysis, and check the result. The harness is the system around the language model that allows this: its tools, runtime, context, permissions, and feedback from its actions. Its runtime is the environment that executes those actions. A language model alone cannot inspect a warehouse, run a simulation, or recover an interrupted statistical model fit. The environment must make those operations possible and return useful evidence about what happened.任务提示告诉代理要调查什么。它还需要知道项目如何运作、如何获取数据、如何运行分析以及如何检查结果。Harness(支撑系统)是围绕语言模型的系统,使其能够实现这些功能:包括工具、运行时、上下文、权限以及对其操作的反馈。运行时是执行这些操作的环境。仅靠语言模型无法检查仓库、运行模拟或恢复中断的统计模型拟合。环境必须使这些操作成为可能,并返回关于发生了什么的有用证据。
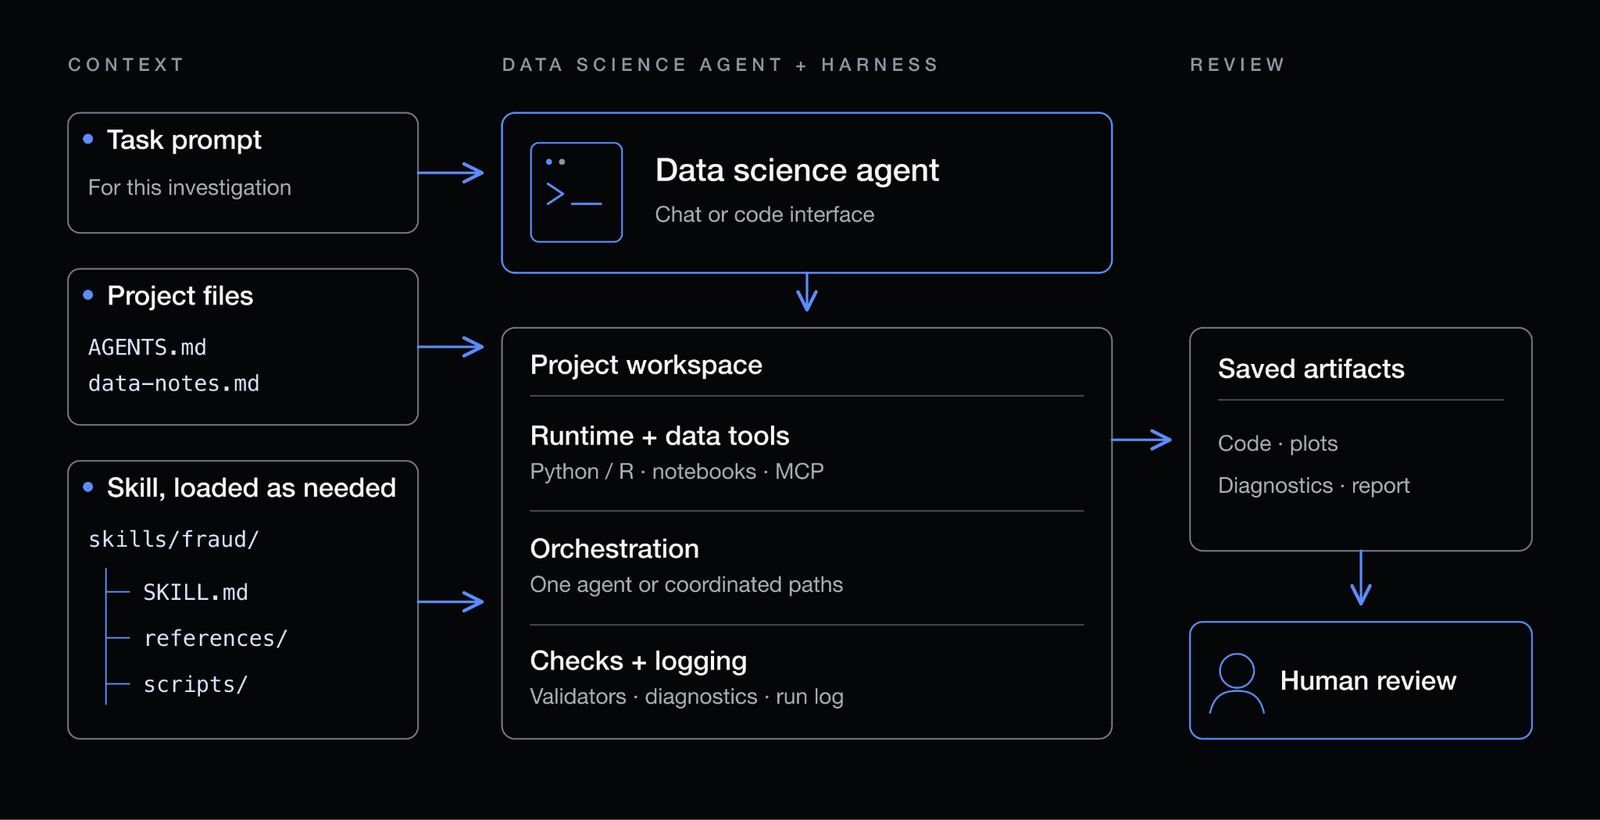
Runtime choices are analytical choices as well as engineering choices. Can the agent execute Python or R with the libraries the task needs? Can a long-running fit continue after an interactive session ends? Which scientific libraries should the agent use? Can the agent inspect plots, or does it only see the code that produced them? Can you reproduce the environment in which it reported a result?运行时选择既是分析选择,也是工程选择。代理能否使用任务所需的库执行 Python 或 R?长时间运行的拟合能否在交互式会话结束后继续?代理应该使用哪些科学库?代理能否检查图表,还是只能看到生成图表的代码?你能否重现它报告结果时的环境?
An existing agent runtime may provide most of this. Configuring it means deciding what belongs in Markdown, what needs a tool, and what should be checked by a small script. In an investigation like the fraud example, Markdown can hold the brief and data definitions, while a Python script could check that the appropriate temporal validation split is executed. A CSV data extract may be enough for exploration; if the agent needs data warehouse access, a tool exposed through an MCP server can provide it with appropriately scoped, read-only credentials. A sentence in a prompt cannot enforce that access limit.现有的代理运行时可能已经提供了大部分功能。配置它意味着决定哪些内容放在 Markdown 中,哪些需要工具,哪些应该由小脚本检查。在像欺诈示例这样的调查中,Markdown 可以保存简报和数据定义,而 Python 脚本可以检查是否执行了适当的时间验证拆分。CSV 数据提取可能足以进行探索;如果代理需要访问数据仓库,通过 MCP 服务器暴露的工具可以为其提供适当范围的只读凭据。提示中的一句话无法强制执行该访问限制。
Take the same care with outputs. Ask the agent to preserve the data reference, code, environment, assumptions, and diagnostics behind its report. A chat transcript is a poor substitute for a runnable analysis. Review becomes much harder when the only surviving artifact is a confident paragraph about what the agent says it did.对输出也要同样小心。要求代理保留其报告背后的数据引用、代码、环境、假设和诊断信息。聊天记录无法替代可运行的分析。如果唯一留存的产物是关于代理自称做了什么的自信段落,那么审查将变得非常困难。
Execution is only part of the problem. An agent may know how to fit a model and still misunderstand what the columns mean. It may find five revenue tables and choose the wrong one. A schema rarely explains which customers were eligible for an offer, when a measurement changed, or why the team stopped using an apparently reasonable metric. This is where agent skills and domain knowledge enter. A skill packages instructions and resources for a type of analytical work. It might contain a modeling approach, example code, required diagnostics, and guidance on when to ask for help. Data documentation supplies the organizational meaning: canonical definitions, table grain, known limitations, and the history needed to interpret a result.执行只是问题的一部分。代理可能知道如何拟合模型,但仍然误解列名的含义。它可能找到五个收入表并选择了错误的一个。模式(schema)很少解释哪些客户有资格获得优惠、测量指标何时发生变化,或者为什么团队停止使用一个看似合理的指标。这就是代理技能和领域知识发挥作用的地方。技能将特定类型分析工作的指令和资源打包。它可能包含建模方法、示例代码、所需的诊断信息以及何时寻求帮助的指导。数据文档提供了组织层面的含义:规范定义、表粒度、已知限制以及解释结果所需的历史信息。
A useful skill is specific enough to change the agent’s behavior. “Be rigorous” gives it little to work with. A fraud-modeling skill can require the agent to establish feature availability, evaluate on later observations, and report performance on operationally important subgroups. For example:一个有用的技能必须足够具体,以改变代理的行为。“要严谨”对它几乎没有帮助。欺诈建模技能可以要求代理确定特征可用性、在较晚的观测值上进行评估,并报告操作上重要子群体的表现。例如:
For fraud prediction:

Establish what information is available when a node is scored.

Exclude features derived from subsequent investigations or labels.

Fit preprocessing on training data only.

Evaluate on later-arriving nodes and report the required degree groups.

Flag uncertainty about feature provenance before claiming performance.
These instructions leave room to choose a model. They encode reasons that some apparently successful models should be rejected. Where a requirement can be checked reliably in code, the skill can call a script that performs the check and records its result.这些指令留出了选择模型的空间。它们编码了拒绝某些看似成功模型的理由。在代码中可以可靠检查的要求,技能可以调用执行检查并记录结果的脚本。
Loading every method and every document into every assignment is unnecessary. Give the agent a way to find relevant expertise, including its scope and exceptions. A forecasting skill should not silently impose its evaluation rules on an unrelated retrospective analysis. Nor should a notebook from last year outrank an updated metric definition merely because it offers convenient code to copy.没必要将每种方法和每份文档都加载到每个任务中。给代理一种寻找相关专业知识的方法,包括其范围和例外情况。预测技能不应默默地将其评估规则强加于不相关的回顾性分析。去年的笔记本也不应仅仅因为提供了方便复制的代码,就比更新后的指标定义更重要。
To put these pieces together locally, begin with a file-and-code agent in a sandboxed project workspace, such as the following:要在本地整合这些部分,请从沙盒项目工作空间中的文件和代码代理开始,如下所示:
fraud-investigation/

  AGENTS.md                # Project instructions, where supported by the runtime

  brief.md                 # Agreed question and delegation boundaries

  data-notes.md            # Sources, column meaning, availability times

  skills/fraud.md          # The methodological guidance above

  environment.lock         # Dependency versions, in your tool’s format

  model/                   # Code the investigating agent may change

  results/                 # Experiment log, diagnostics, saved candidates

  review.md                # Acceptance decision and unresolved questions
Use a project instruction file, such as AGENTS.md in runtimes that support it, to explain which context files the agent should read and how to propose updates to them. In other runtimes, provide those instructions through the supported mechanism. Give the sandbox read access to the approved development data and write access to the model and results directories. Keep the final test data outside of the agent’s accessible workspace. The practitioner can run acceptance checks in a separate environment whose evaluator and data the investigating agent cannot modify. A different folder, or version control alone, is not an access boundary.使用项目指令文件(例如支持该功能的运行时中的 AGENTS.md)来解释代理应该读取哪些上下文文件以及如何提议更新它们。在其他运行时中,通过支持的机制提供这些指令。给沙盒分配对已批准开发数据的读取权限,以及对模型和结果目录的写入权限。将最终测试数据保留在代理可访问的工作空间之外。从业者可以在一个单独的环境中运行验收检查,该环境的评估器和数据是调查代理无法修改的。不同的文件夹或仅版本控制并不是访问边界。
Now ask the agent to inspect the inputs, identify unresolved questions, and build a baseline. Before allowing repeated experiments, rerun that baseline and examine its feature-availability record, split dates, and subgroup report. This small rehearsal checks whether the setup works all the way from instructions to evidence. A missing subgroup report points to a different problem than a failed package installation. Resolve those problems before giving the agent a longer run.现在要求代理检查输入、识别未解决的问题并构建基线。在允许重复实验之前,重新运行该基线并检查其特征可用性记录、拆分日期和子群体报告。这种小规模演练检查了设置是否从指令到证据全程有效。缺失的子群体报告比失败的包安装指向的是不同的问题。在给代理更长的运行时间之前,先解决这些问题。
3. Organize the investigation3. 组织调查
With the question framed and the agent equipped, the next choice is how to organize its work. This depends on the intent of the data science problem. For descriptive work, exploratory data analysis may proceed one question and plot at a time. Building a predictive model may support repeated experiments against a fixed evaluator; a causal question may require comparing analyses built on different assumptions.在构思好问题并配备好代理后,下一个选择是如何组织其工作。这取决于数据科学问题的意图。对于描述性工作,探索性数据分析可能一次只进行一个问题和图表的分析。构建预测模型可能支持针对固定评估器的重复实验;因果问题可能需要比较建立在不同假设基础上的分析。
In a live exploratory analysis on Show Us Your Agent Skills, Eric Ma (Moderna) uses a marimo notebook as a shared workspace with an agent. He explains the protein mutation data, asks for one plot at a time, corrects a color scale that affects interpretation, and chooses the next question from what he sees. The agent edits the notebook and renders the plots; Eric supplies the domain context, checks the artifacts, and owns the interpretation. The reason Eric needed to be in the loop was that human understanding was part of the objective function here!在“Show Us Your Agent Skills”的现场探索性分析演示中,Eric Ma (Moderna) 使用 marimo 笔记本作为与代理共享的工作空间。他解释蛋白质突变数据,一次请求一个图表,纠正影响解释的颜色比例,并根据所见选择下一个问题。代理编辑笔记本并渲染图表;Eric 提供领域背景,检查产物,并负责解释。Eric 需要参与其中的原因是,人类的理解是这里目标函数的一部分!
Use a bounded experiment loop使用有界实验循环
For predictive modeling, the autoresearcher pattern organizes the work into a repeatable loop: propose a hypothesis, change the model, evaluate it, and keep or revert the change. The agent records each result and uses it to choose the next attempt. Within the scope you give it, it can explore features and model structure as well as parameter values. This is an inner loop within a broader investigation: the data scientist frames the question and sets the evaluation, the agent searches within those boundaries, and the data scientist reviews the result (potentially using an independent agent) before deciding what to do next.对于预测建模,自动研究者(autoresearcher)模式将工作组织成一个可重复的循环:提出假设、更改模型、评估模型,并保留或撤销更改。代理记录每个结果并使用它来选择下一次尝试。在你给定的范围内,它可以探索特征和模型结构以及参数值。这是更广泛调查中的一个内循环:数据科学家构思问题并设定评估标准,代理在这些边界内搜索,数据科学家审查结果(可能使用一个独立的代理),然后再决定下一步做什么。
Define what the agent may change, protect the evaluator from those changes, and set a time or compute budget. This makes iteration a bounded task within the investigation.定义代理可以更改的内容,保护评估器免受这些更改的影响,并设定时间或计算预算。这使得迭代成为调查中的一个有界任务。
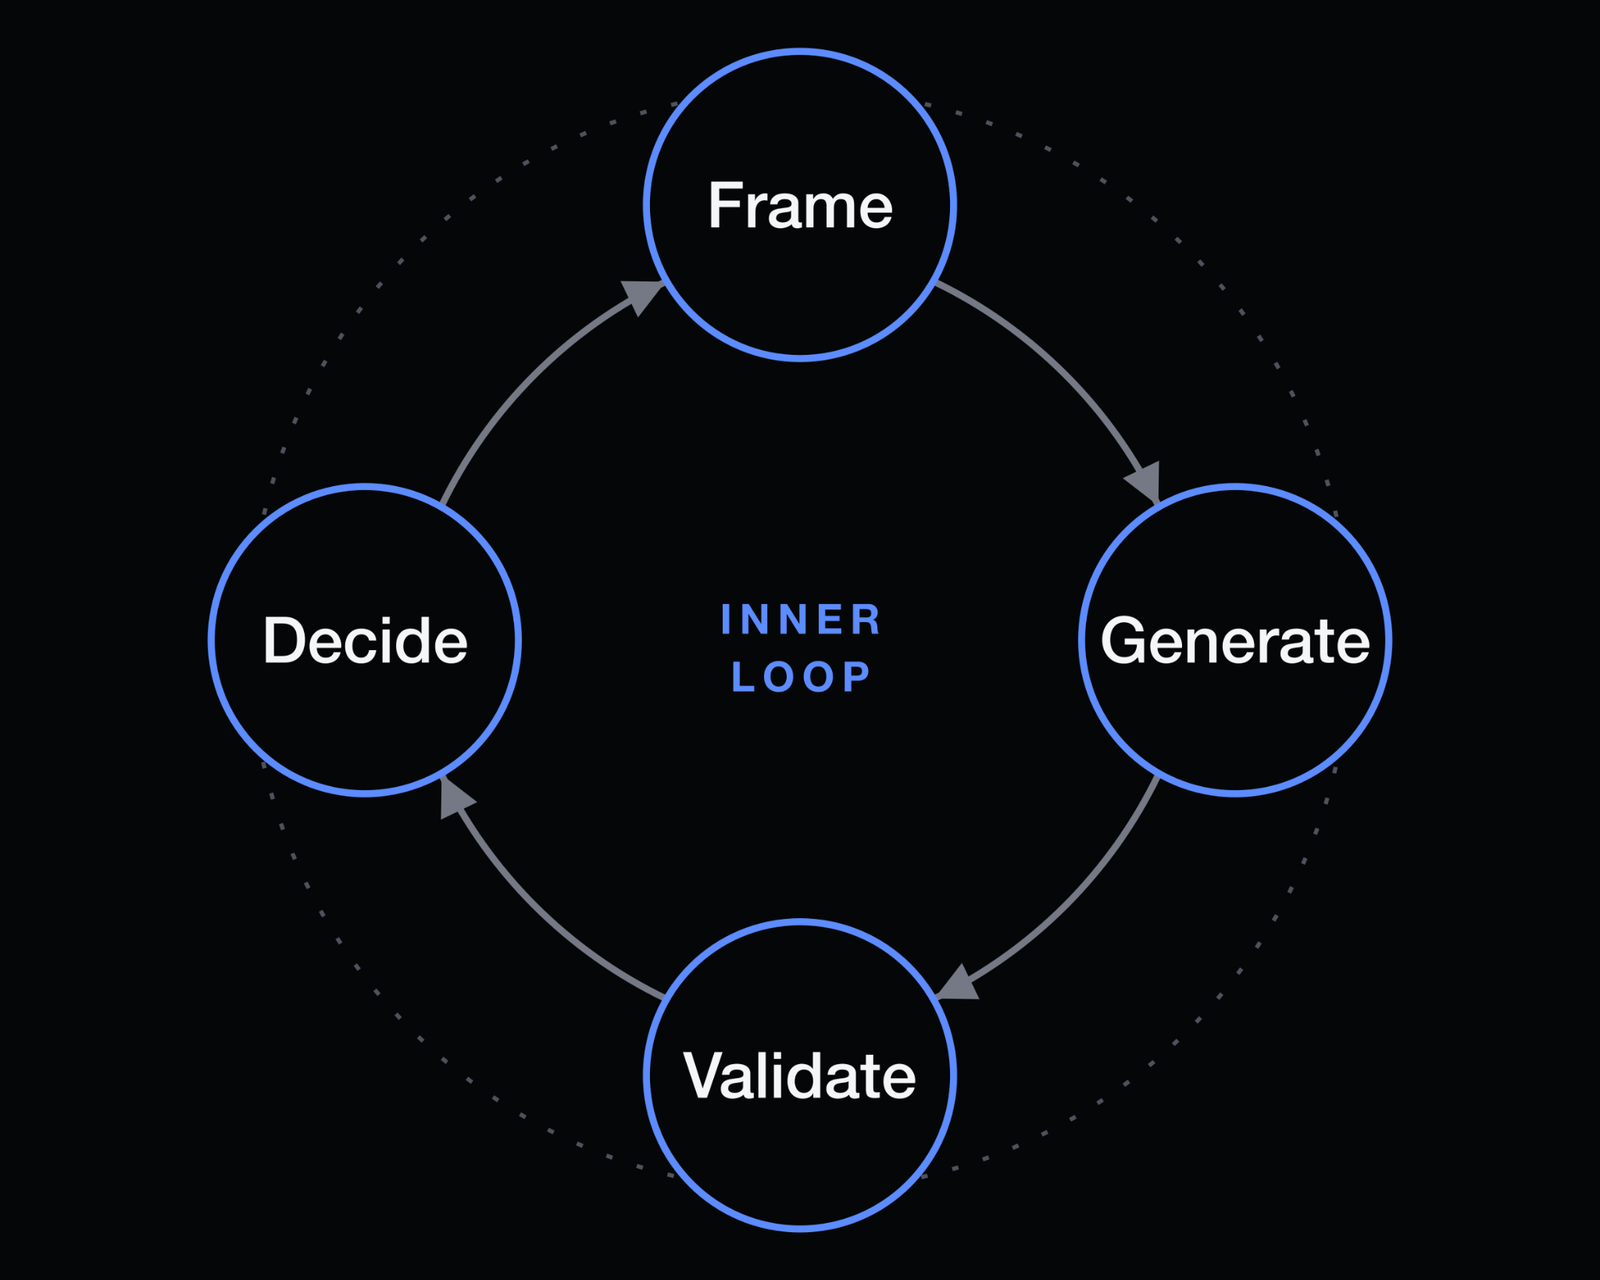
A compact experiment contract could say:一份紧凑的实验合约可以这样写:
Improve the supplied baseline within the agreed compute budget.

You may change model code and propose eligible features.

Keep the target definition, validation split, and evaluator fixed.

Record each hypothesis, change, result, and keep-or-revert decision.

Stop at the budget limit or escalate if the evaluation is unsuitable.

Return the best candidate and the experiment history for review.
In a separate exercise with its own baseline and evaluation, we used this pattern to improve a graph neural network trained on the network data from the opening example. We used lower validation loss as the rule for keeping a change; F1 for fraudulent transactions was a separate measure of the resulting classifier. The agent ran 41 experiments while the team slept and retained seven changes that reduced validation loss. On the validation set, loss fell by about 70%, and F1 for fraudulent transactions rose from about 0.72 to 0.82. The log preserved both successful changes and failed attempts, so we could examine how it reached the result.在另一个具有自己的基线和评估的练习中,我们使用这种模式改进了一个在开篇示例的网络数据上训练的图神经网络。我们使用较低的验证损失作为保留更改的规则;欺诈交易的 F1 分数是所得分类器的独立衡量指标。在团队休息时,代理运行了 41 次实验,并保留了 7 个减少验证损失的更改。在验证集上,损失下降了约 70%,欺诈交易的 F1 分数从约 0.72 上升到 0.82。日志保存了成功的更改和失败的尝试,因此我们可以检查它是如何得出结果的。
One candidate had the highest F1 for fraudulent transactions, but the agent rejected it because its validation loss was higher. That followed the selection rule we had set. The experiment history records that choice for the subsequent review.其中一个候选方案对欺诈交易的 F1 分数最高,但代理拒绝了它,因为它的验证损失较高。这遵循了我们设定的选择规则。实验历史记录了该选择,供后续审查。
The autoresearcher pattern works when an objective gives the agent useful feedback on each attempt. But some investigations turn on which assumptions to make, not which candidate scores best. Those tasks need a different way to organize the agent’s work.当目标能为代理的每次尝试提供有用反馈时,自动研究者模式非常有效。但有些调查取决于做出哪些假设,而不是哪个候选方案得分最高。这些任务需要一种不同的方式来组织代理的工作。
Investigate competing explanations调查竞争性解释
In causal work, no held-out outcome directly reveals what would have happened without an intervention. The agent needs to examine how different analyses construct and test that counterfactual.在因果工作中,没有留存结果可以直接揭示在没有干预的情况下会发生什么。代理需要检查不同的分析如何构建和测试该反事实(counterfactual)。
In a demonstration from our Master Agentic Data Science course using simulated subscription-business data, we asked: “What did the price increase cost us?” The outcome is daily conversion rate: paid conversions divided by the pool of potential subscribers. Choices about the observation window, counterfactual, exclusions, and validation produce different analytical paths. A final memo usually shows only one.在我们“掌握代理式数据科学”课程的一个使用模拟订阅业务数据的演示中,我们问:“价格上涨让我们损失了什么?”结果是每日转化率:付费转化数除以潜在订阅者池。关于观测窗口、反事实、排除项和验证的选择会产生不同的分析路径。最终的备忘录通常只显示其中一种。
Two agent runs estimated conversion roughly 16% below their no-price-increase counterfactuals, yet shipped opposing claims. Run A attributed its estimated drop to a changing pool of potential subscribers and concluded there was “no real effect,” but did not validate that explanation. Run B backtested its counterfactual, ran a placebo check, and compared six specifications. It reported a robust relative reduction of 15.6%.两次代理运行估计的转化率均比其无价格上涨的反事实低约 16%,但得出了相反的主张。运行 A 将其估计的下降归因于潜在订阅者池的变化,并得出结论称“没有实际影响”,但并未验证该解释。运行 B 对其反事实进行了回测,运行了安慰剂检查,并比较了六种规范。它报告了 15.6% 的稳健相对减少。
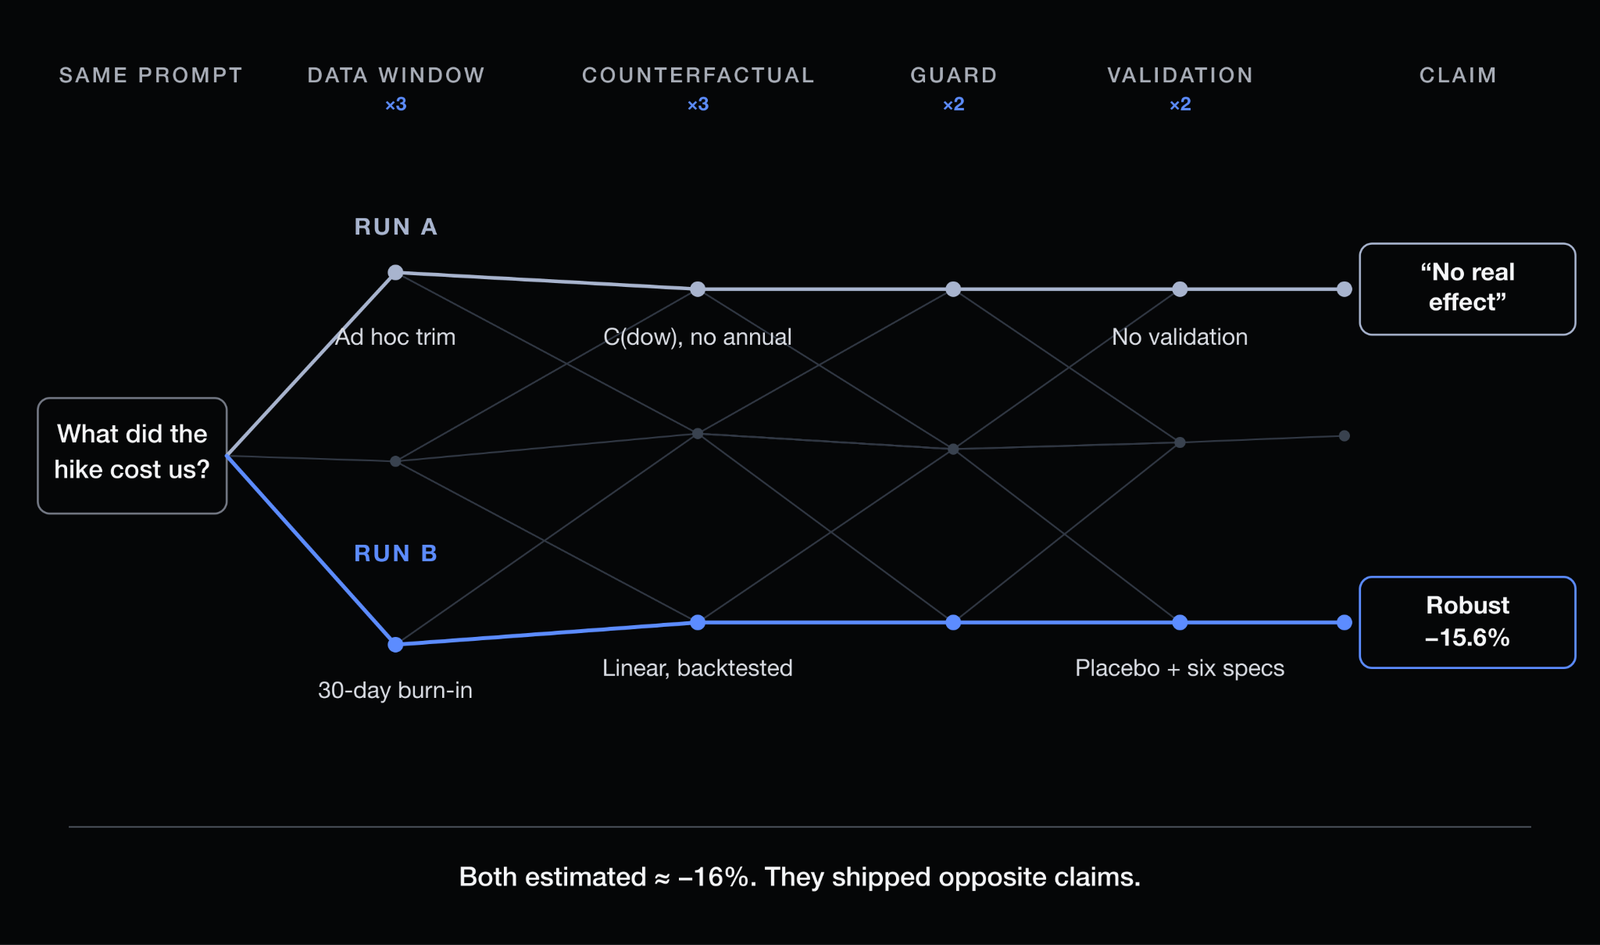
The parallel-analysis pattern has independent agents test different choices in the same investigation: one examines the observation window, another tests seasonal assumptions, and we compare their estimates, uncertainty, and diagnostics. Our Decision Lab work extends this approach across analytical paths, using checks to identify unsuitable analyses and unresolved disagreements.并行分析模式让独立代理在同一调查中测试不同的选择:一个检查观测窗口,另一个测试季节性假设,我们比较它们的估计值、不确定性和诊断信息。我们的 Decision Lab 工作将这种方法扩展到各个分析路径,使用检查来识别不合适的分析和未解决的分歧。
Both approaches give the agent feedback while it works. The fixed evaluator steers the model experiments; diagnostics help it compare causal analyses. The output is a candidate and experiment history, or a set of analyses with their assumptions and checks. Those are the materials for the next task: verifying the claim.两种方法都在代理工作时为其提供反馈。固定评估器引导模型实验;诊断信息帮助它比较因果分析。输出是一个候选方案和实验历史,或一组带有假设和检查的分析。这些是下一个任务的材料:验证主张。
4. Review the result independently4. 独立审查结果
The agentic data scientist now needs to check what that evidence supports, and a fresh agent can help. Give an independent agent reviewer the original brief, data context, code, diagnostics, and final claim. Ask it to reproduce decisive checks and challenge assumptions. In this adversarial review pattern, the agent raises objections it can substantiate; the data scientist judges whether they change the conclusion.代理式数据科学家现在需要检查证据支持什么,而一个新的代理可以提供帮助。给一个独立的代理审稿人提供原始简报、数据背景、代码、诊断信息和最终主张。要求它重现决定性的检查并质疑假设。在这种对抗性审查模式中,代理提出它能证实的问题;数据科学家判断它们是否改变了结论。
In the fraud exercise, the agent used the same validation data to guide 41 experiments, so the reported gains may partly reflect what worked on that set. Freeze the selected candidate and assess it on an untouched holdout chosen for the intended use, including errors in the groups that matter.在欺诈练习中,代理使用相同的验证数据来指导 41 次实验,因此报告的收益可能部分反映了在该集合上有效的内容。冻结选定的候选方案,并在为预期用途选择的未触及留存集上进行评估,包括在重要群体中的错误。
In the pricing exercise, a fresh reviewer challenged Run A’s conclusion. Run A attributed the estimated decline to a changing pool of potential subscribers but provided no evidence for that explanation. The reviewer found that conversion had been rising before the price increase and that placebo interventions in earlier periods did not reproduce the negative effect. Run B’s analysis, which included these validation checks, was selected in the final comparison.在定价练习中,一位新的审稿人对运行 A 的结论提出了质疑。运行 A 将估计的下降归因于潜在订阅者池的变化,但没有为该解释提供证据。审稿人发现,在价格上涨之前转化率一直在上升,并且在早期阶段进行的安慰剂干预并没有重现负面影响。包含这些验证检查的运行 B 的分析在最终比较中被选中。
Netflix’s agentic workflow for causal inference implements this division: an actor performs the analysis and diagnostics, while a critic challenges the reasoning and claims. Humans can inspect and rerun the artifacts.Netflix 用于因果推理的代理式工作流实现了这种分工:执行者进行分析和诊断,而评论者质疑推理和主张。人类可以检查并重新运行这些产物。
A fresh agent session is not necessarily an independent review if it can read the investigator’s earlier attempts through the workspace or Git history, though! For a check meant to stand on its own, give the reviewer the original brief, final artifact, and data needed for that check, while limiting access to the prior path. The full experiment trail can be examined separately when auditing how the result was reached.如果新的代理会话可以通过工作空间或 Git 历史读取调查员之前的尝试,那么它就不一定是独立审查!对于旨在独立的检查,请给审稿人原始简报、最终产物和该检查所需的数据,同时限制其对先前路径的访问。在审计结果是如何达成时,可以单独检查完整的实验路径。
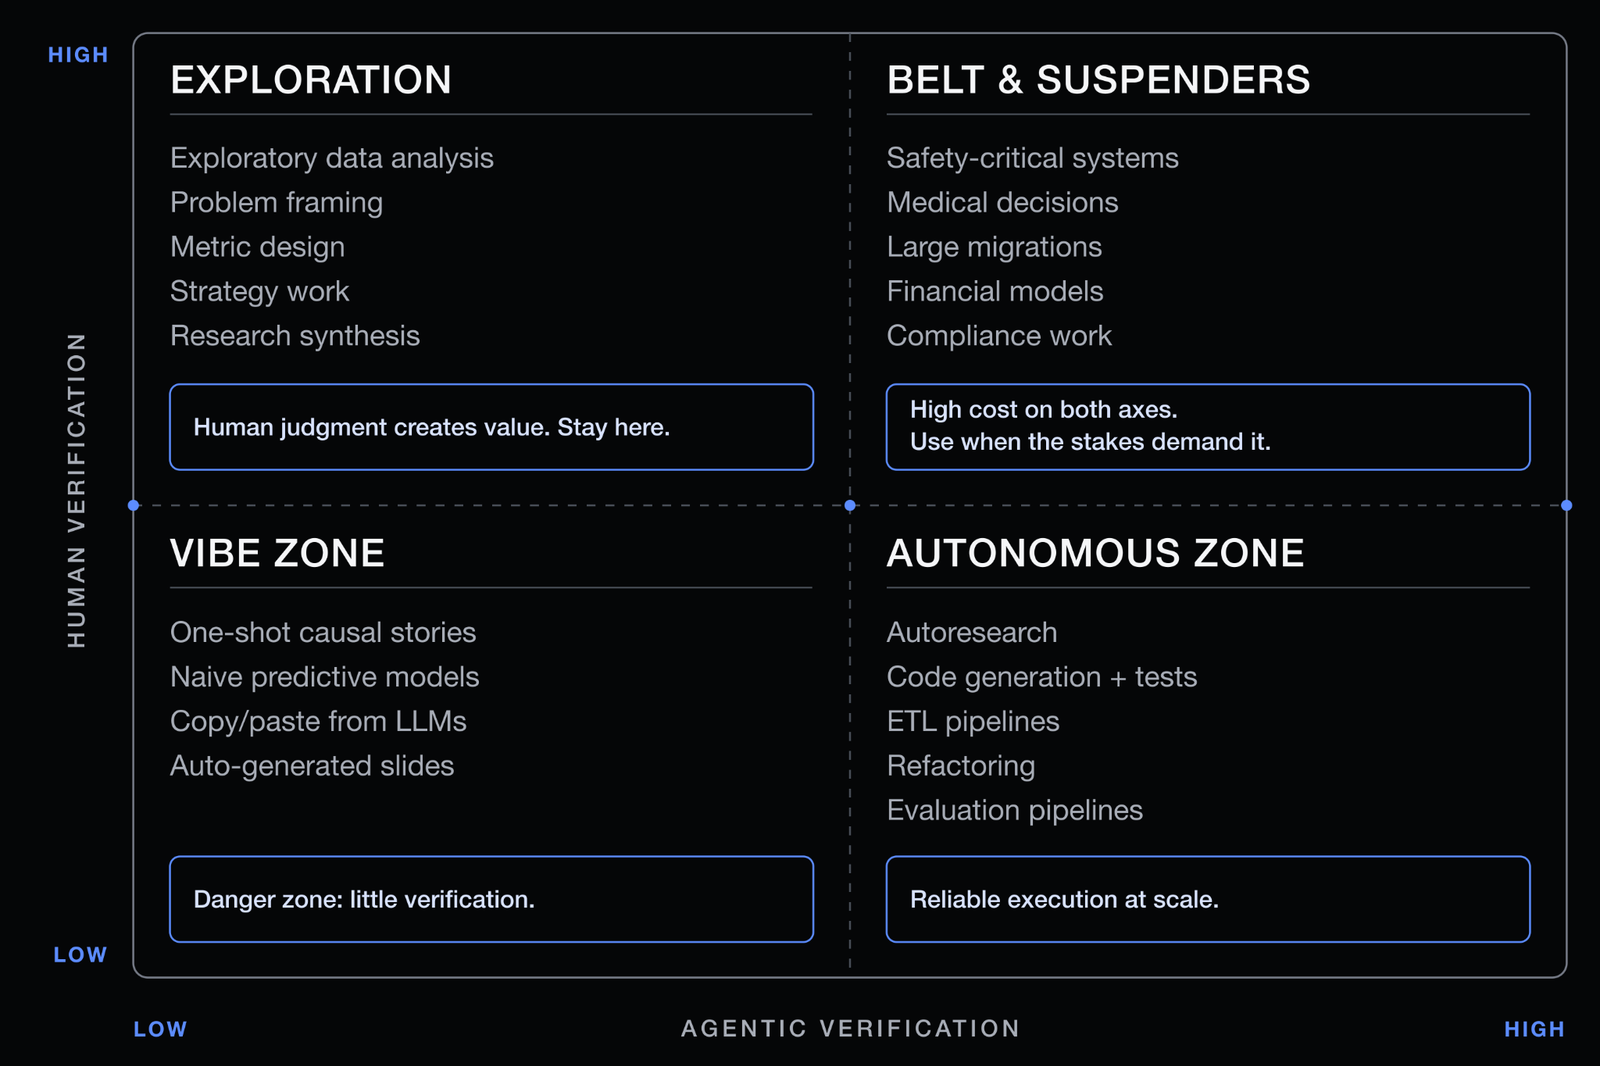
These examples call for different balances of human and agentic verification. In Eric Ma’s EDA, the agent makes plots while Eric checks them and chooses the next question. In the bounded experiment loop, a fixed evaluator checks each candidate before a person reviews the selected model. In the pricing analysis, agentic diagnostics and critique help a data scientist judge what the evidence supports.这些示例需要不同的人类和代理式验证平衡。在 Eric Ma 的 EDA 中,代理制作图表,而 Eric 检查它们并选择下一个问题。在有界实验循环中,固定评估器在人审查所选模型之前检查每个候选方案。在定价分析中,代理式诊断和批评帮助数据科学家判断证据支持什么。
The low-low quadrant leaves little basis for trusting a result (in fact, it’s “vibe data science!”). Repeatable checks can move some work toward more agentic verification, while questions that depend on domain understanding or consequential decisions continue to need human judgment.低-低象限几乎没有信任结果的基础(事实上,这是“氛围数据科学!”)。可重复的检查可以将一些工作转向更多的代理式验证,而依赖领域理解或重要决策的问题则继续需要人类判断。
5. Turn reviewed experience into reusable expertise5. 将审查后的经验转化为可重用的专业知识
The experiment loop and adversarial review both depend on an evidence trail: the saved artifacts that show what the agent did and why a conclusion survived or changed. Preserve that trail throughout each investigation, including data references, code versions, analytical choices, experiment results, diagnostics, and review findings. Keep the failed alternatives and review findings as well as the final report.实验循环和对抗性审查都依赖于证据追踪:保存的产物显示了代理做了什么,以及结论为何得以保留或改变。在每次调查中保留该追踪,包括数据引用、代码版本、分析选择、实验结果、诊断信息和审查发现。保留失败的替代方案和审查发现,以及最终报告。
This trail has a second use beyond inspecting the current result. Reviewing it with the agent can reveal missing context, recurring mistakes, or methods worth reusing. The next question is which of those lessons should change how the agent approaches a future assignment. Leaving them in a conversation makes that learning difficult to carry forward.该追踪除了检查当前结果外,还有第二个用途。与代理一起审查它可以揭示缺失的背景、反复出现的错误或值得重用的方法。下一个问题是,这些经验中哪些应该改变代理处理未来任务的方式。将它们留在对话中使得这种学习难以传承。
In the fraud example, we deliberately planted a feature that leaked the fraud label. Removing it corrected that analysis. The reusable lesson is to have the agent check proposed features for leakage: where did each feature come from, and would it be available when a new transaction is scored? That requirement can go into a fraud-modeling skill for future investigations.在欺诈示例中,我们故意植入了一个泄露欺诈标签的特征。移除它修正了该分析。可重用的经验是让代理检查提议的特征是否存在泄露:每个特征来自哪里,以及在对新交易进行评分时它是否可用?该要求可以进入欺诈建模技能,供未来调查使用。
Before making a lesson into standing guidance, we need to define where it applies. The planted feature was a problem because it carried information unavailable at scoring time, not because it predicted fraud well. The temporal split likewise fits a task involving transactions from later time steps; it is not a rule for every analysis. A skill should capture those conditions so the agent applies the lesson to the right task.在将经验转化为常设指导之前,我们需要定义它适用的范围。植入的特征之所以是个问题,是因为它携带了评分时不可用的信息,而不是因为它预测欺诈效果好。同样,时间拆分也适用于涉及较晚时间步长交易的任务;它不是每项分析的规则。技能应该捕捉这些条件,以便代理将经验应用到正确的任务中。
For example:例如:
Lesson: a feature encoded information from the fraud label.

Scope: prospective fraud prediction.

Update: require a documented source and availability time for inputs.

Evaluation: test whether the agent detects outcome-derived inputs

without rejecting legitimate signals merely because they predict well.
This is where evals enter: repeatable tasks with explicit criteria for assessing the data science agent’s behavior. Here, we evaluate how the agent conducts the analysis, not only its model’s predictive performance. The evidence trail supplies concrete failures that can become test cases for proposed changes to its skills or workflow.这就是评估(evals)发挥作用的地方:具有明确评估数据科学代理行为标准的重复任务。在这里,我们评估代理如何进行分析,而不仅仅是其模型的预测性能。证据追踪提供了具体的失败案例,这些案例可以成为对其技能或工作流提议更改的测试用例。
Keep the evals, skill versions, and results together. As reviewed assignments reveal new failure modes, expand the cases and rerun them when the agent’s setup changes. The aim is evidence that its analytical behavior improves, rather than a growing collection of instructions that merely sound sensible.将评估、技能版本和结果放在一起。随着审查后的任务揭示了新的失败模式,扩展案例并在代理设置更改时重新运行它们。目标是证明其分析行为有所改进,而不是积累一堆听起来合理的指令。
Workflow changes can accumulate in the same way. If a reviewer repeatedly catches a missing diagnostic, move that diagnostic earlier. If a separate reviewer adds cost but never changes the analysis, reconsider its role. If the agent repeatedly asks the same question about a table, improve the data context rather than supplying the answer again in chat.工作流更改可以以同样的方式积累。如果审稿人反复发现缺失的诊断信息,请将该诊断提前。如果单独的审稿人增加了成本却从未改变分析,请重新考虑其角色。如果代理反复询问关于某个表的相同问题,请改进数据上下文,而不是在聊天中再次提供答案。
A completed assignment need not always produce a new skill. A one-off constraint belongs in the project’s notes; a recurring methodological failure may justify standing guidance. That distinction keeps the next investigation from inheriting every exception encountered in the last one.完成的任务不一定总是产生新技能。一次性约束属于项目的笔记;反复出现的分析方法失败可能证明常设指导的合理性。这种区别使下一次调查不会继承上一次遇到的每一个例外。
When other people use the agents you build当其他人使用你构建的代理时
When colleagues use an agent without you mediating each request, your local knowledge has to become shared infrastructure. OpenAI’s internal data agent combines institutional context with query evaluations and existing user permissions. Meta’s Analytics Agent draws on prior analytical work and reusable guidance, exposing generated SQL alongside results. Both illustrate why earlier analyses and corrections belong in the system, not only in an analyst’s memory.当同事在没有你调解每个请求的情况下使用代理时,你的本地知识必须成为共享基础设施。OpenAI 的内部数据代理将机构背景与查询评估和现有用户权限相结合。Meta 的 Analytics Agent 利用先前的分析工作和可重用的指导,在结果旁边展示生成的 SQL。两者都说明了为什么早期的分析和修正属于系统,而不仅仅是分析师的记忆。
In your own work, you can explain an unfamiliar table or catch a misleading conclusion as it appears. When colleagues use the agent directly, that support must be built into the system. Try an assignment with a colleague and note where you need to step in. Missing context belongs in the agent’s guidance; recurring mistakes become evals; questions beyond its remit need a route to a qualified reviewer. Someone must maintain that guidance, and access controls must limit each user’s data access. The analytical principles stay the same, but the agent can no longer depend on you being present for every investigation.在你自己的工作中,你可以解释一个不熟悉的表或在误导性结论出现时捕捉它。当同事直接使用代理时,这种支持必须内置到系统中。尝试与同事一起完成一项任务,并注意你需要介入的地方。缺失的背景属于代理的指导;反复出现的错误成为评估;超出其职权范围的问题需要路由到合格的审稿人。必须有人维护该指导,并且访问控制必须限制每个用户的数据访问。分析原则保持不变,但代理不再依赖于你在每次调查中都在场。
Put the playbook to work将实战手册付诸实践
Choose a small investigation you understand well enough to challenge: a model you periodically retrain or a business metric you regularly explain. Give the agent the decision context and ask it to propose an approach. Agree on what it can decide, then let it carry the investigation far enough to produce evidence you can inspect.选择一个你足够了解以进行质疑的小型调查:一个你定期重新训练的模型,或一个你经常解释的业务指标。给代理决策背景并要求它提出方法。商定它可以决定什么,然后让它将调查进行到足以产生你可以检查的证据。
At review, pay attention to where your intervention changes the work. Did the agent need a definition only your team knows? Did a diagnostic overturn its conclusion? If that intervention would help on another assignment, make the relevant context or check available there, and test whether it helps.在审查时,注意你的干预在何处改变了工作。代理是否需要只有你团队才知道的定义?诊断信息是否推翻了其结论?如果该干预对其他任务有帮助,请使相关的上下文或检查在那里可用,并测试它是否有帮助。
AI-native data scientists use their expertise to build and direct analytical agents. They turn lessons from reviewing an analysis into skills and checks, then test whether those changes help the agent on future tasks.AI 原生数据科学家利用他们的专业知识来构建和指导分析代理。他们将审查分析的经验转化为技能和检查,然后测试这些更改是否有助于代理完成未来的任务。
The next cohort of our Master Agentic Data Science course starts Oct 6.我们“掌握代理式数据科学”课程的下一批次将于 10 月 6 日开始。