
This post is part of Epoch AI’s Gradient Updates newsletter, which shares more opinionated or informal takes on big questions in AI progress. These posts solely represent the views of the authors, and do not necessarily reflect the views of Epoch AI as a whole.本文是 Epoch AI 的 Gradient Updates 通讯的一部分,旨在分享对 AI 进展重大问题的更为主观或非正式的见解。这些文章仅代表作者个人观点,并不一定反映 Epoch AI 的整体立场。
What trends are we extrapolating?我们正在推断哪些趋势?
A common way that experts forecast AI timelines is so simple it’s hard to believe: trend extrapolation. Sure they also use numerical models that bake in things like runaway feedback loops, but the bread and butter of AI forecasting is to draw a line on a graph and extend it as far as you dare. Somehow this works well enough to be a state-of-the-art approach. However, the trends they extrapolate share a common weakness: they lean heavily on easy-to-measure things, not what we directly care about — how close AI is to doing AI research itself.专家们预测 AI 时间线时常用的一种方法简单到令人难以置信:趋势外推法。当然,他们也会使用包含失控反馈回路等因素的数值模型,但 AI 预测的核心手段还是在图表上画一条线,并尽可能远地延伸它。不知何故,这种方法效果足够好,以至于成了最先进的方法。然而,他们所外推的趋势有一个共同的弱点:它们严重依赖于易于衡量的指标,而不是我们真正关心的内容——即 AI 距离能够自主进行 AI 研究还有多远。
Many experts want to know when we’ll fully automate AI research, because this would massively speed up AI progress, kicking off an “intelligence explosion”.1 If that’s right, it’s hugely important to know how close we are. But historically, there haven’t been many points of direct evidence to point to, because full automation of AI R&D has been so hard to measure. Instead, researchers have been forced to rely on proxies.许多专家想知道我们何时能实现 AI 研究的全面自动化,因为这将极大地加速 AI 的进步,从而引发“智能爆炸”。如果事实确实如此,了解我们距离这一目标有多近就显得至关重要。但从历史上看,并没有多少直接证据可供参考,因为 AI 研发的完全自动化一直难以衡量。因此,研究人员被迫依赖代理指标。
One such proxy is in key AI inputs like compute, data, and energy. Take Situational Awareness, which extends “effective compute” five years into the future until AI research gets automated:其中一个代理指标是算力、数据和能源等关键 AI 输入。以“态势感知”(Situational Awareness)为例,它将“有效算力”向未来延伸了五年,直到 AI 研究实现自动化:
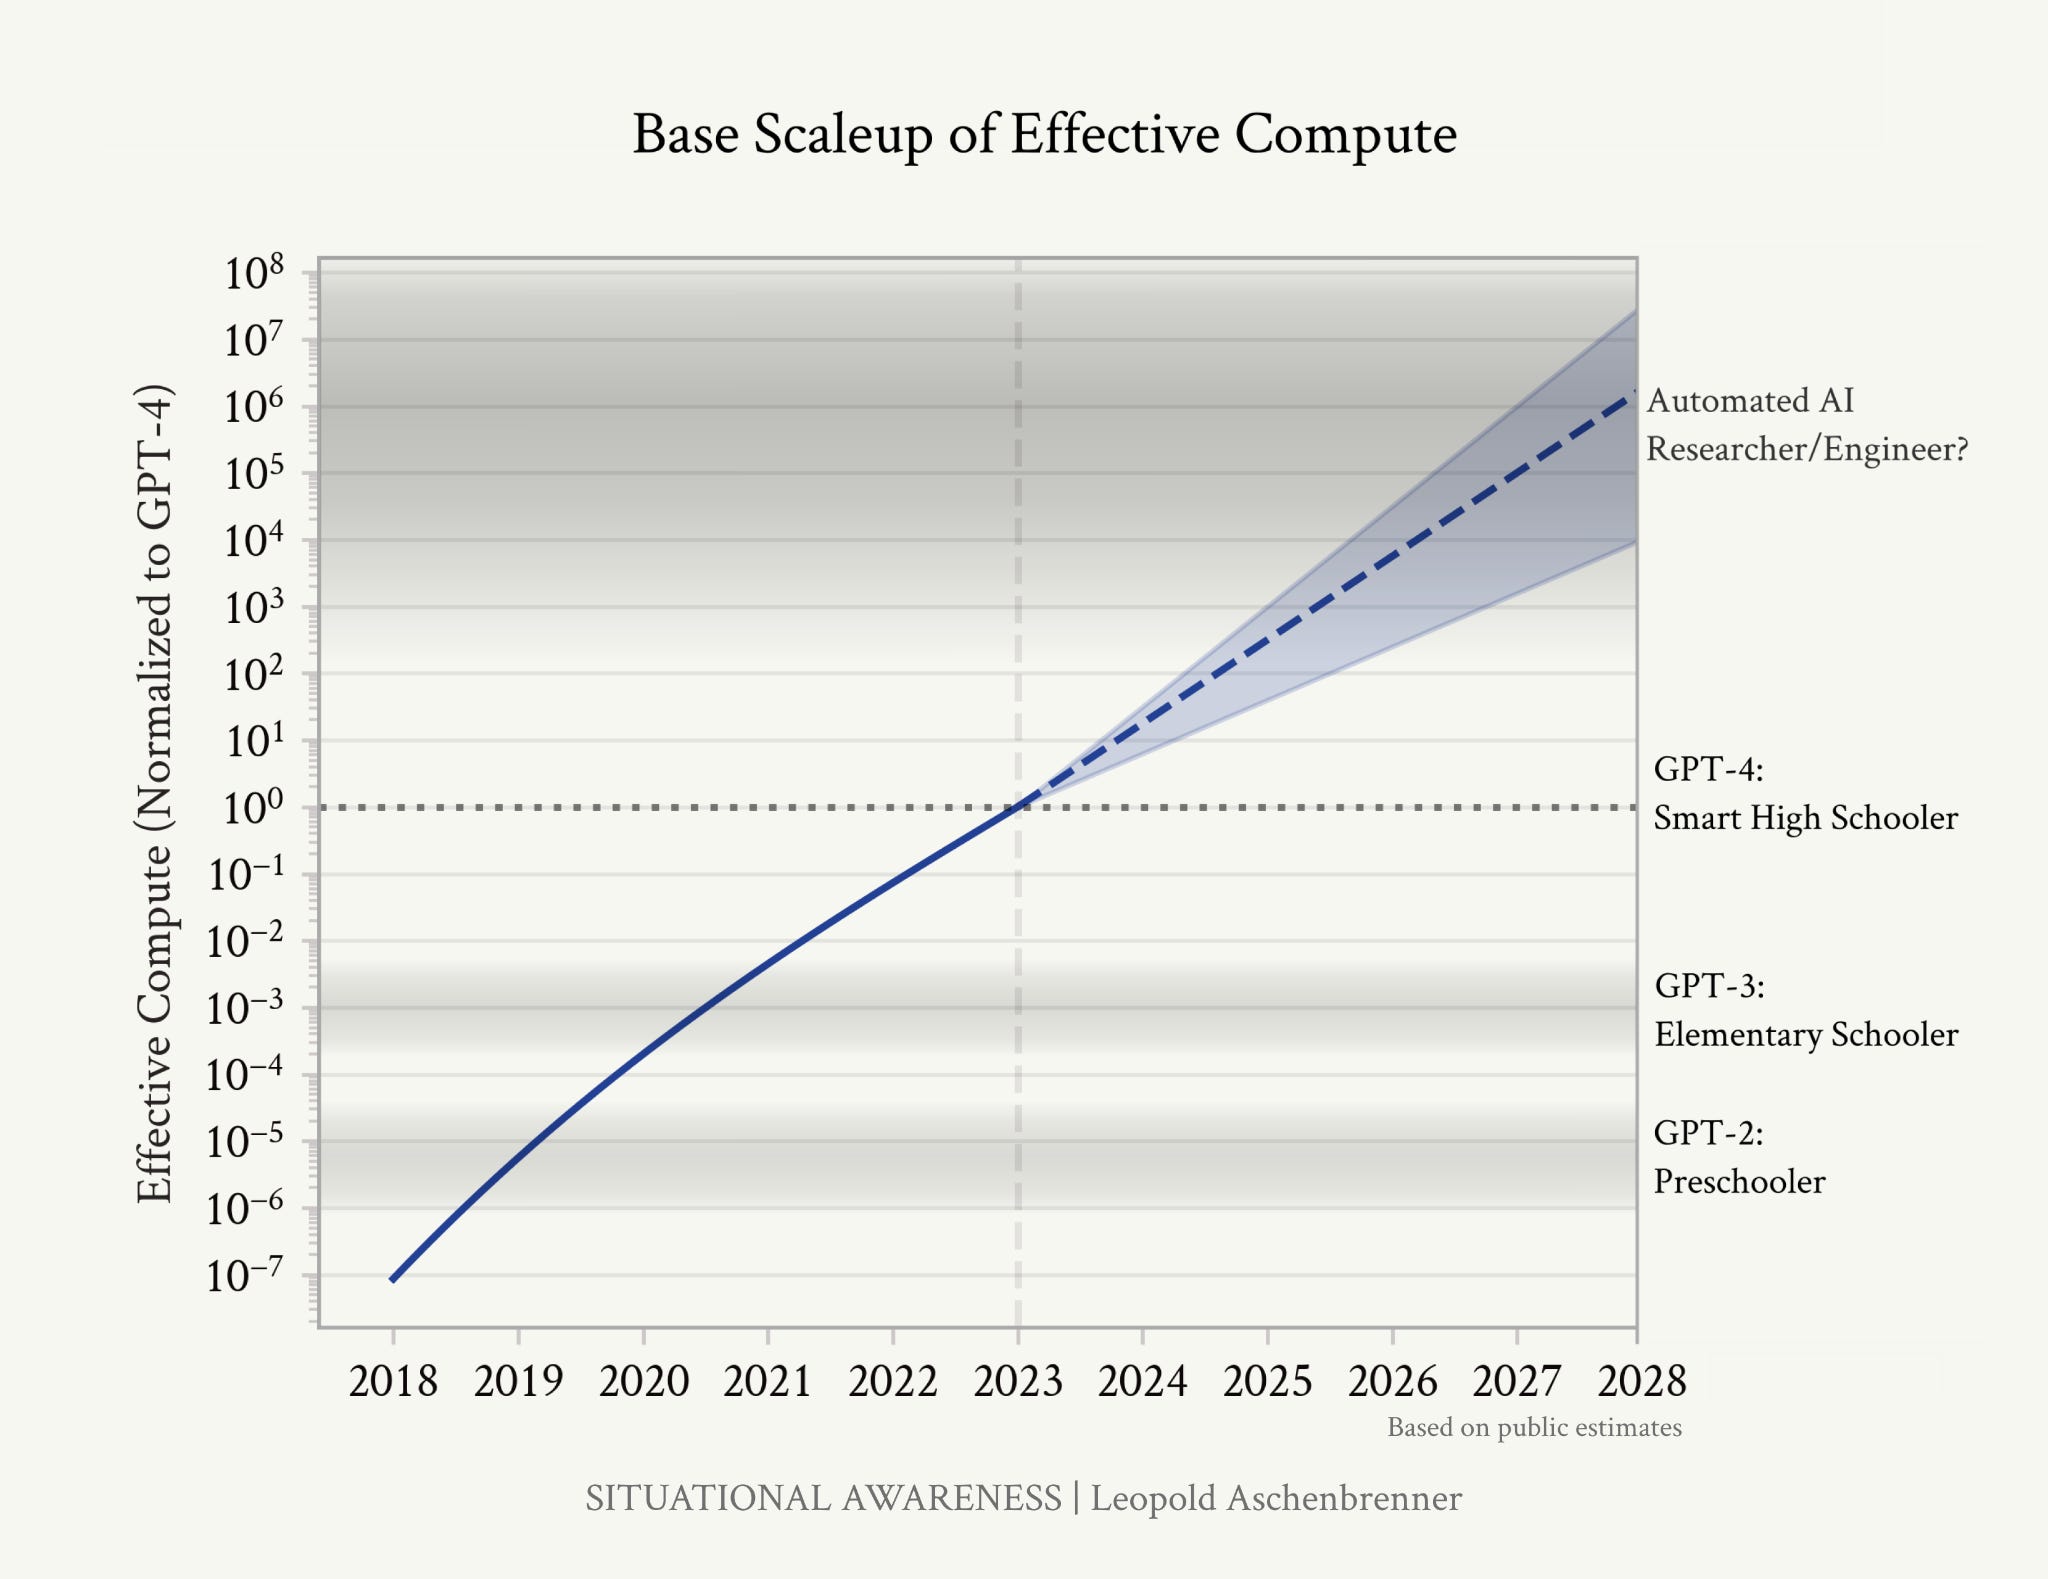
But these inputs are only rough proxies for capabilities and you need to go on “vibes” to say how much compute you need to match the world’s top AI researchers.但这些输入只是能力的大致代理,要判断需要多少算力才能媲美世界顶尖的 AI 研究人员,往往需要依靠“直觉”。
A second approach is to track the length of tasks that AIs can complete, where “length” is how long a skilled human takes. This is what METR did with their “time horizon” metric, which was then extrapolated in the famous AI 2027 scenario to forecast when AIs would become “superhuman coders”, before automating AI R&D.第二种方法是追踪 AI 能完成的任务时长,其中“时长”是指熟练人类完成该任务所需的时间。这就是 METR 使用其“时间跨度”(time horizon)指标所做的工作,该指标随后在著名的“AI 2027”情景中被外推,用于预测 AI 何时会成为“超越人类的编码者”,进而实现 AI 研发的自动化。
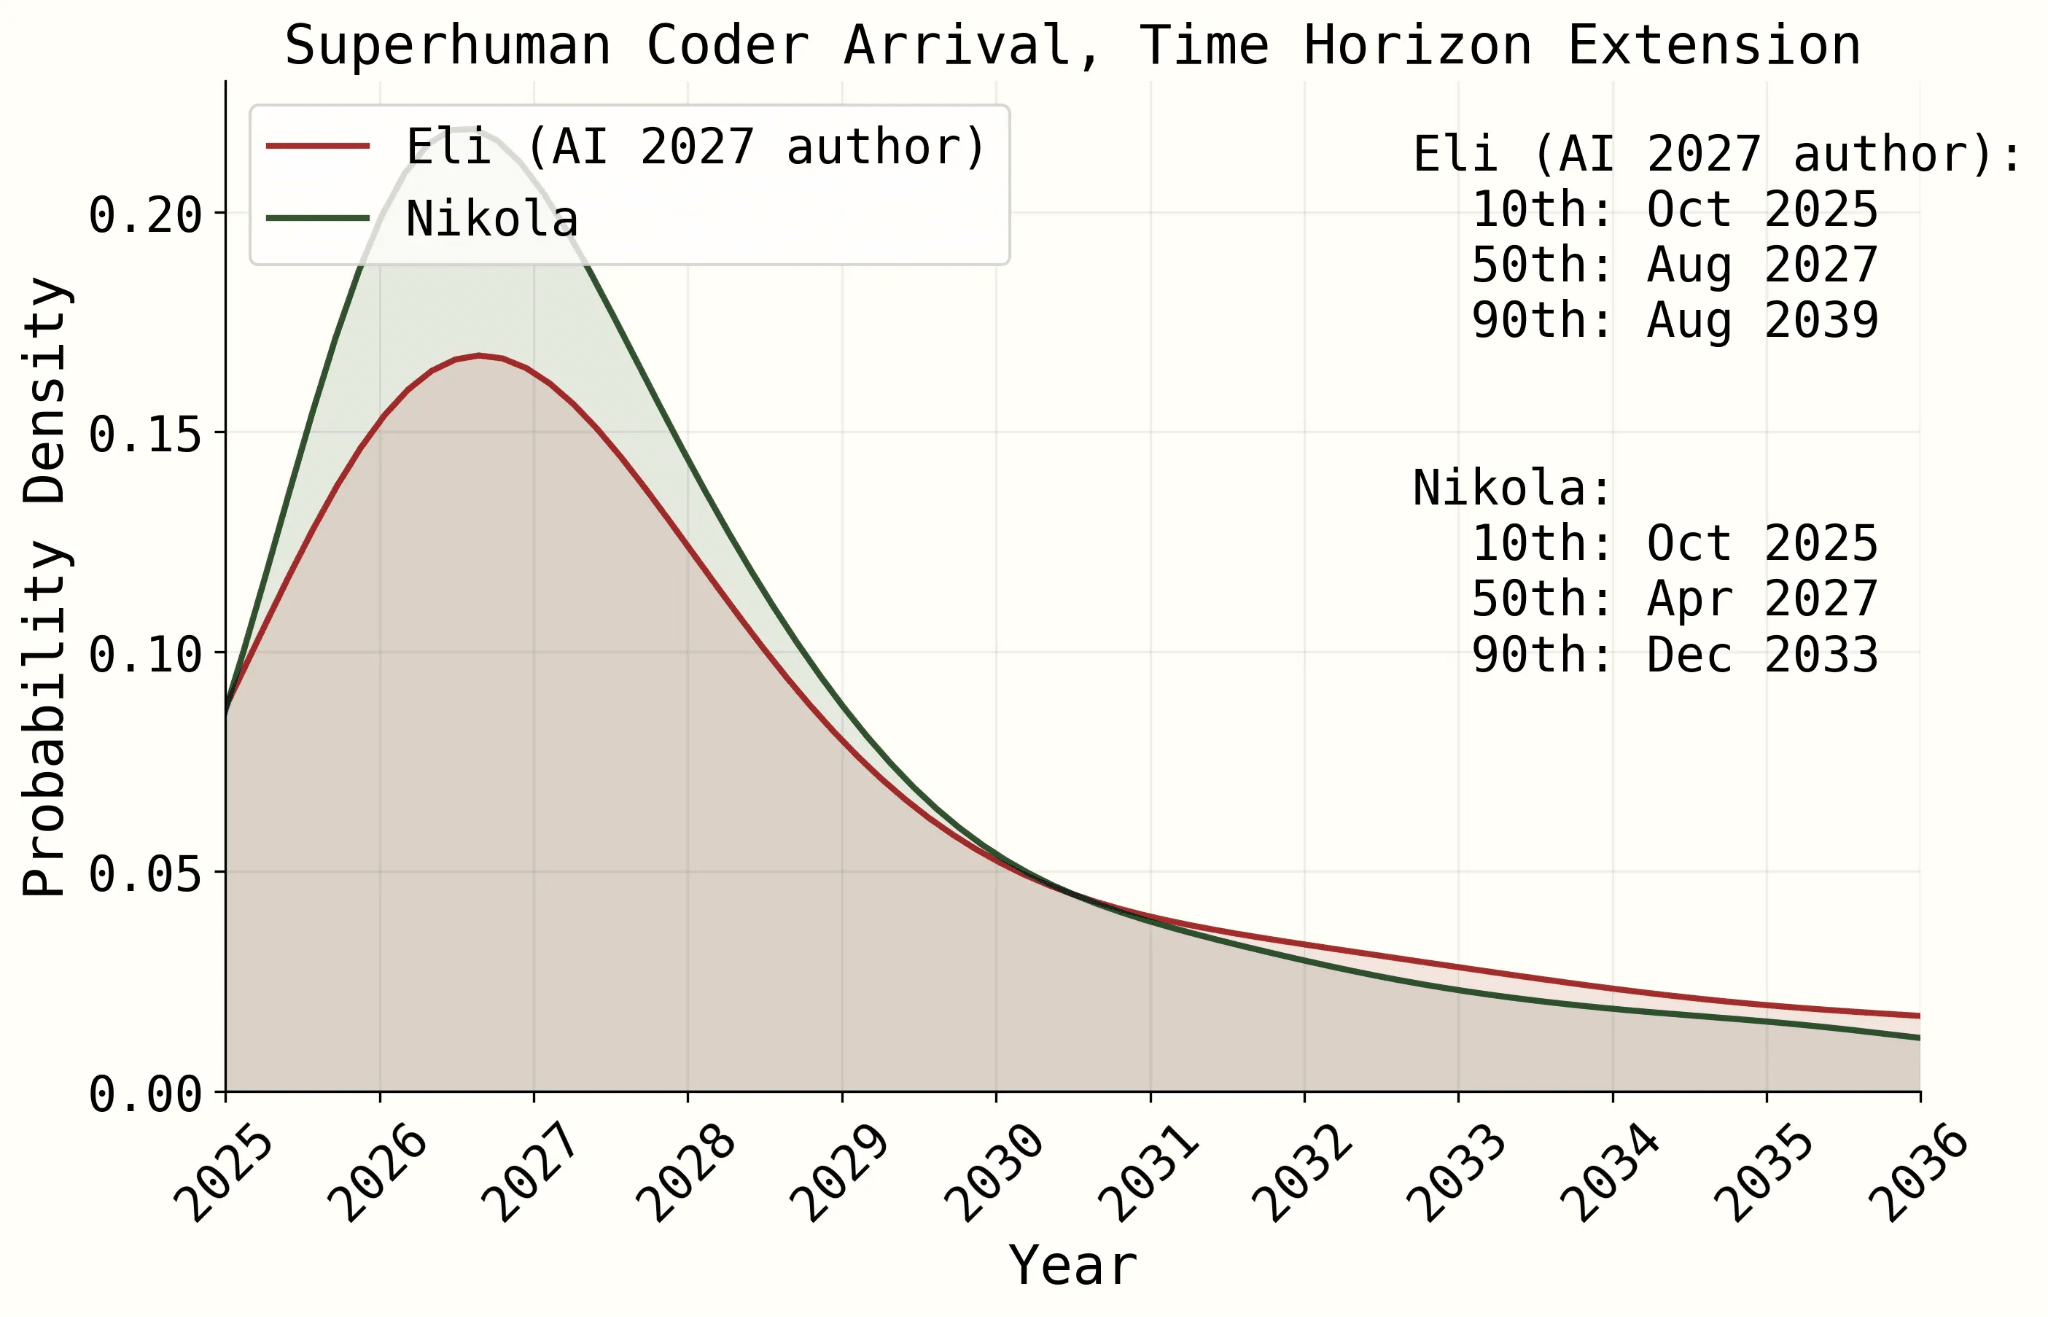
But the benchmarks used to construct METR’s time horizon miss out on many of the tasks and complexities of research. It’s one thing to be able to finetune a small GPT-2 model, and another to be able to coordinate five projects at the same time, dealing with a million lines of code, without a clear criterion for success or failure.然而,用于构建 METR 时间跨度的基准测试忽略了研究中的许多任务和复杂性。能够微调一个小型的 GPT-2 模型是一回事,而能够同时协调五个项目,处理百万行代码,且没有明确的成功或失败标准,则是另一回事。
So it would be nice to know everything that AI R&D actually consists of. Otherwise we’ll always be at risk of streetlighting (extrapolating whatever happens to be easiest to measure). We can better avoid this if we have a list of the tasks involved in AI R&D, to track what we’re aware of and what we’re not investigating.因此,如果能了解 AI 研发实际包含的所有内容将会很有帮助。否则,我们将始终面临“路灯效应”(即只外推那些最容易衡量的东西)的风险。如果我们有一份 AI 研发涉及的任务清单,就能更好地追踪我们已知的内容以及尚未深入研究的内容,从而避免这一问题。
Armed with such a list, we could better interpret the extrapolations we already have: when a benchmark score climbs, a task list tells us which parts of the job that improvement covers, and which parts it doesn’t touch. And we could build new trends to extrapolate, like the fraction of tasks that are automated, or how much uplift researchers get on each one.有了这份清单,我们就能更好地解读现有的外推结果:当基准测试分数上升时,任务清单可以告诉我们,这一改进涵盖了工作的哪些部分,又有哪些部分未被触及。我们还可以建立新的趋势来外推,例如任务自动化的比例,或者研究人员在每项任务上获得的效率提升幅度。
In this post, we present a first version of such a taxonomy with six categories spanning a frontier AI company’s research workflow, based on literature review and brainstorming. The categories are broken into over sixty tasks, each rated from 0 to 5 on how much we think current AIs automate it. The full taxonomy lives in a companion doc, which is the main artifact of this work.在本文中,基于文献综述和头脑风暴,我们提出了此类分类法的第一个版本,涵盖了前沿 AI 公司研究工作流程的六个类别。这些类别被细分为六十多个任务,每一项都根据我们认为当前 AI 对其自动化的程度进行了 0 到 5 分的评分。完整的分类法存放在配套文档中,这也是本项工作的主要成果。
We think of it as our best first attempt at developing a comprehensive taxonomy of tasks contributing to AI R&D, in order to more robustly understand and predict AI R&D automation. If we described tasks incorrectly, or missed some entirely, we’d love to hear about it and receive feedback.我们将其视为开发 AI 研发任务综合分类法的首次尝试,旨在更稳健地理解和预测 AI 研发的自动化。如果我们对任务的描述有误,或者遗漏了某些任务,我们非常希望能收到反馈。
An O*NET for AI R&DAI 研发的 O*NET
We’re not the first to want a task list like this; breaking jobs down into tasks is how economists usually track automation in the economy. The standard tool here is O*NET, which describes about 1,000 jobs in the US economy as well as the tasks and skills that people need to do them.我们并不是第一个想要这种任务清单的人;将工作分解为任务是经济学家通常追踪经济中自动化程度的方法。这里的标准工具是 O*NET,它描述了美国经济中约 1,000 种职业,以及人们完成这些工作所需的任务和技能。
Armed with O*NET, economists can then do a bunch of empirical work and forecasts about AI’s economic impacts, such as:有了 O*NET,经济学家就可以进行大量的实证研究并对 AI 的经济影响进行预测,例如:
Look at the fraction of American workers whose jobs might be heavily impacted by LLMs观察其工作可能受到大语言模型(LLM)严重影响的美国工人的比例
Estimate how AI might impact GDP growth over the next decade (however accurately or inaccurately)估计 AI 在未来十年内可能如何影响 GDP 增长(无论准确与否)
Design AI benchmarks to cover a wide range of knowledge work设计涵盖广泛知识工作的 AI 基准测试
Taxonomize how people use frontier AI models对人们使用前沿 AI 模型的方式进行分类
Predict the consequences of automating remote work预测远程办公自动化带来的后果
But while O*NET is a widely used source, it doesn’t help us track AI research automation very well — the tasks in the dataset are just way too broad and high-level. Consider the job “Computer and Information Research Scientists”, which is probably about as close as you can get to “frontier lab AI researcher” within O*NET. In this case the work tasks look like this:但是,尽管 O*NET 是一个广泛使用的来源,它并不能很好地帮助我们追踪 AI 研究的自动化——数据集中的任务太宽泛且处于高层级。以“计算机和信息研究科学家”这一职业为例,这大概是 O*NET 中最接近“前沿实验室 AI 研究员”的职业了。在这种情况下,工作任务如下:
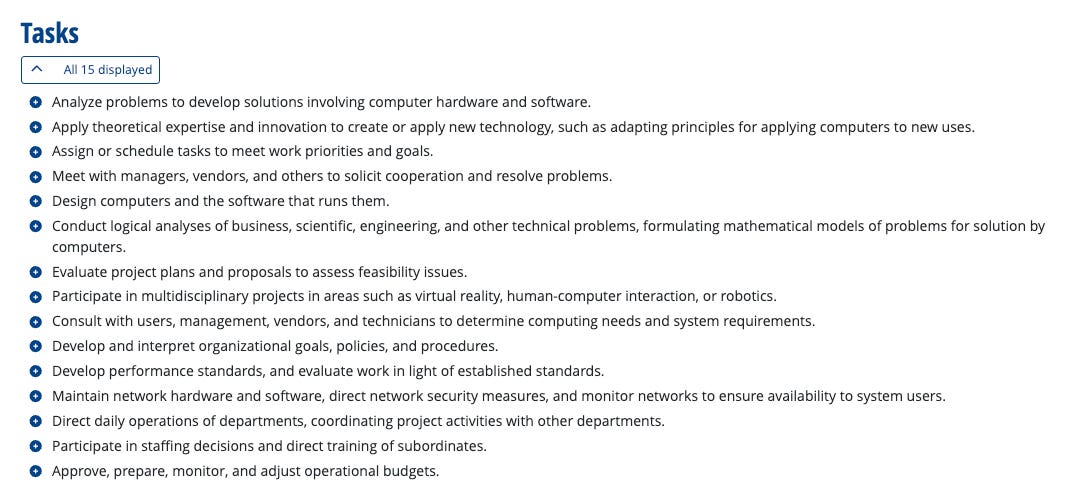
The first listed task is to “Analyze problems to develop solutions involving computer hardware and software”. But that’s really vague — what kinds of problems or solutions? What exactly does or doesn’t count as “involving computer hardware and software”? You could make the case that almost everything about an AI engineer’s job involves computer software, so it’s not a very granular description to say the least. And yet this is the most granular task description you can find in O*NET, and the same issue applies to pretty much every other task.列出的第一项任务是“分析问题以开发涉及计算机硬件和软件的解决方案”。但这非常模糊——具体是什么样的问题或解决方案?什么才算“涉及计算机硬件和软件”,什么不算?你可以说 AI 工程师的工作几乎都涉及计算机软件,所以说这是一种不够细致的描述都算是客气的。然而,这已经是你在 O*NET 中能找到的最细致的任务描述了,而同样的问题几乎适用于所有其他任务。
Part of the issue here is practical feasibility: O*NET was designed for the ambitious endeavor of mapping out the tasks in the entire US economy, before the days of LLMs. So it’s probably too much to ask for these tasks to be so granular for everything as new and niche as “frontier lab AI research”.这里的部分问题在于实际可行性:O*NET 是在 LLM 出现之前,为绘制整个美国经济中任务的宏伟目标而设计的。因此,要求这些任务对于像“前沿实验室 AI 研究”这样新兴且小众的领域做到如此细致,可能要求过高了。
That’s why our proposal is to build an O*NET for AI R&D specifically. If we keep our focus narrow, we’re in a much better position to come up with a fine-grained decomposition of an AI researcher’s job. If this works well, we could look at the fraction of tasks that are automated over time. It could also help us interpret benchmark results and how significant they are. There’s a long-standing phenomenon where AI benchmarks haven’t fully reflected the complexities of the real world, and so it’s important to juxtapose benchmark results with what’s happening on the ground.这就是为什么我们提议专门为 AI 研发构建一个 O*NET。如果我们保持专注,就能更好地对 AI 研究员的工作进行细致的分解。如果进展顺利,我们可以观察随时间推移而自动化的任务比例。它还可以帮助我们解读基准测试结果及其重要性。长期以来存在一种现象,即 AI 基准测试并未完全反映现实世界的复杂性,因此将基准测试结果与实地情况进行对比非常重要。
It could also serve as a framework for additional studies about AI’s impact. This could mean surveying AI researchers on the uplift they get on different work tasks. It could also mean classifying internal AI usage logs into different use cases, like “writing experiment code” or “deciding what experiment to run next”. This is similar to how Anthropic’s Clio system helps study real-world AI usage while preserving people’s privacy.它还可以作为进一步研究 AI 影响的框架。这意味着可以调查 AI 研究人员在不同工作任务上获得的效率提升。它还可以意味着将内部 AI 使用日志分类为不同的用例,例如“编写实验代码”或“决定下一步运行什么实验”。这类似于 Anthropic 的 Clio 系统,它在保护个人隐私的同时帮助研究现实世界中的 AI 使用情况。
More generally, an O*NET for AI R&D would help establish a common vocabulary between researchers, such as in frontier labs’ model cards. This could help model developers summarize where AI does or doesn’t help in finer detail, and help standardize information across different sources, like in METR’s most recent Frontier Risk Report.更广泛地说,一个 AI 研发的 O*NET 将有助于在研究人员之间建立共同的词汇表,例如在前沿实验室的模型卡中。这可以帮助模型开发者更精细地总结 AI 在哪些方面有帮助、在哪些方面没有帮助,并有助于标准化不同来源的信息,例如在 METR 最近的《前沿风险报告》中。
This being said, we’re not saying that an “O*NET for AI R&D is all you need” to monitor and forecast progress to automation. Even if we’re armed with a perfectly comprehensive dataset of tasks, we’d still need to measure how AI performs on each task, for example. But even still, having a task dataset would help ground the debate about AI’s actual impacts on AI research, and give us “situational awareness” about how close we might be to an intelligence explosion, supporting evidence from other sources.话虽如此,我们并不是说“AI 研发的 O*NET 就足以”监控和预测通往自动化的进程。即使我们拥有一个极其全面的任务数据集,我们仍然需要衡量 AI 在每项任务上的表现。但即便如此,拥有一个任务数据集将有助于为关于 AI 对 AI 研究实际影响的辩论奠定基础,并让我们对距离智能爆炸有多近获得“态势感知”,从而支持来自其他来源的证据。
A first proposal初步提议
So what would this “O*NET for AI R&D” actually look like? This is of course not trivial to answer — AI R&D is very messy and changes fast. But we figured we’d have an initial attempt at it and let you readers bombard us with feedback. To that end, we compiled over sixty representative tasks at frontier AI labs, accompanied by descriptions and concrete examples — see the full writeup here.那么,这个“AI 研发的 O*NET”到底是什么样的呢?当然,回答这个问题并不容易——AI 研发非常混乱且变化迅速。但我们决定进行初步尝试,并让读者们向我们提出反馈。为此,我们汇编了前沿 AI 实验室的六十多个代表性任务,并附带了描述和具体示例——请参阅此处的完整报告。
The first step was to make a big list of all the tasks currently involved in AI R&D, which we grouped into six categories, inspired by some earlier work.2 These categories correspond to different parts of the AI research cycle:第一步是列出一份 AI 研发目前涉及的所有任务的大清单,并受早期工作启发,将其分为六个类别。这些类别对应于 AI 研究周期的不同部分:
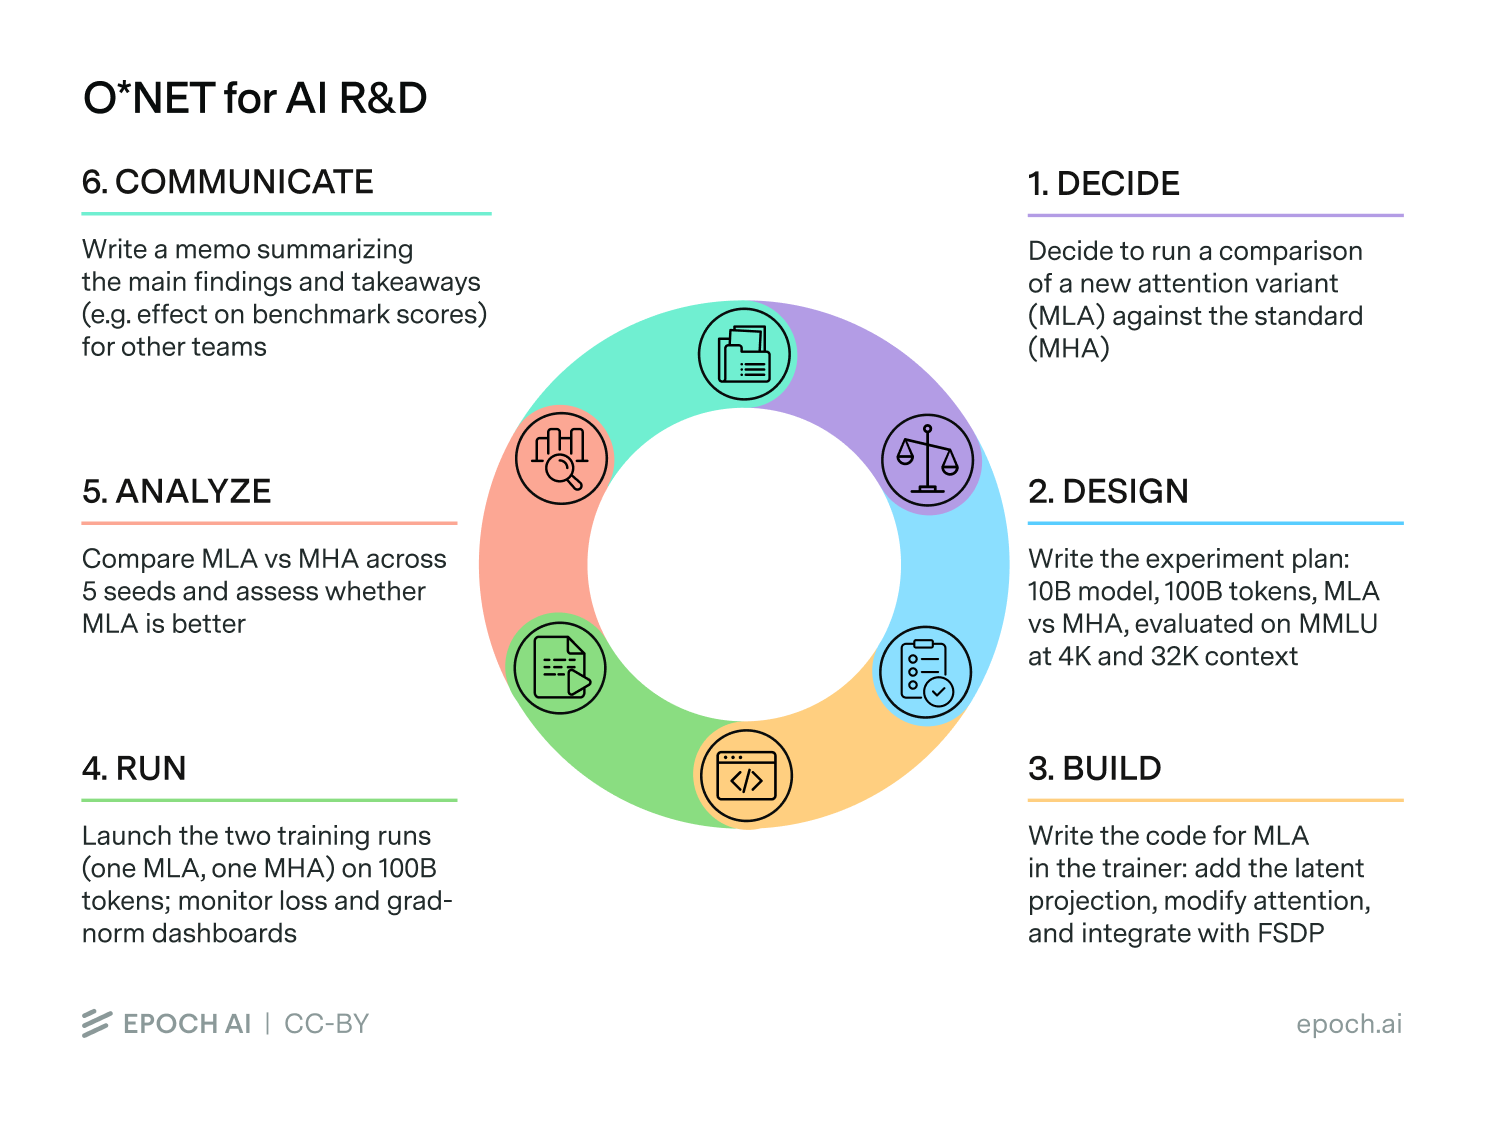
Each category has its own inputs and outputs. For example, consider Category 4 (“Run”), which as the name suggests is about “running” stuff — think executing training runs or deploying AI systems to the public. So the input could look something like a benchmark with all supporting scaffolds and related infrastructure, and the output could be a set of final results.每个类别都有自己的输入和输出。例如,考虑第 4 类(“运行”),顾名思义,它涉及“运行”相关事务——比如执行训练任务或向公众部署 AI 系统。因此,输入可能类似于带有所有支持性脚手架和相关基础设施的基准测试,而输出则是一组最终结果。
Each category is then split into several subcategories. Category 4 is split into three, each with its own inputs and outputs:每个类别随后被细分为若干子类别。第 4 类被分为三部分,每一部分都有自己的输入和输出:
4.1 Monitoring runs: watch training, RL, and eval runs in flight; catch problems as they emerge; restore the run to a healthy trajectory4.1 监控运行:观察训练、强化学习和评估的运行过程;在问题出现时及时捕捉;使运行恢复到正常轨迹
4.2 Hardware infrastructure operations: keep large clusters healthy, well-utilized, and quickly recoverable4.2 硬件基础设施运维:保持大型集群健康、利用率高且能快速恢复
4.3 Inference reliability engineering: keep production serving stable, performant, and recoverable4.3 推理可靠性工程:保持生产环境服务稳定、高效且可恢复
And finally the subcategories contain a thorough list of different tasks. For example, here are the tasks for “4.1 Monitoring runs”:最后,子类别包含了一份详尽的不同任务清单。例如,以下是“4.1 监控运行”的任务:
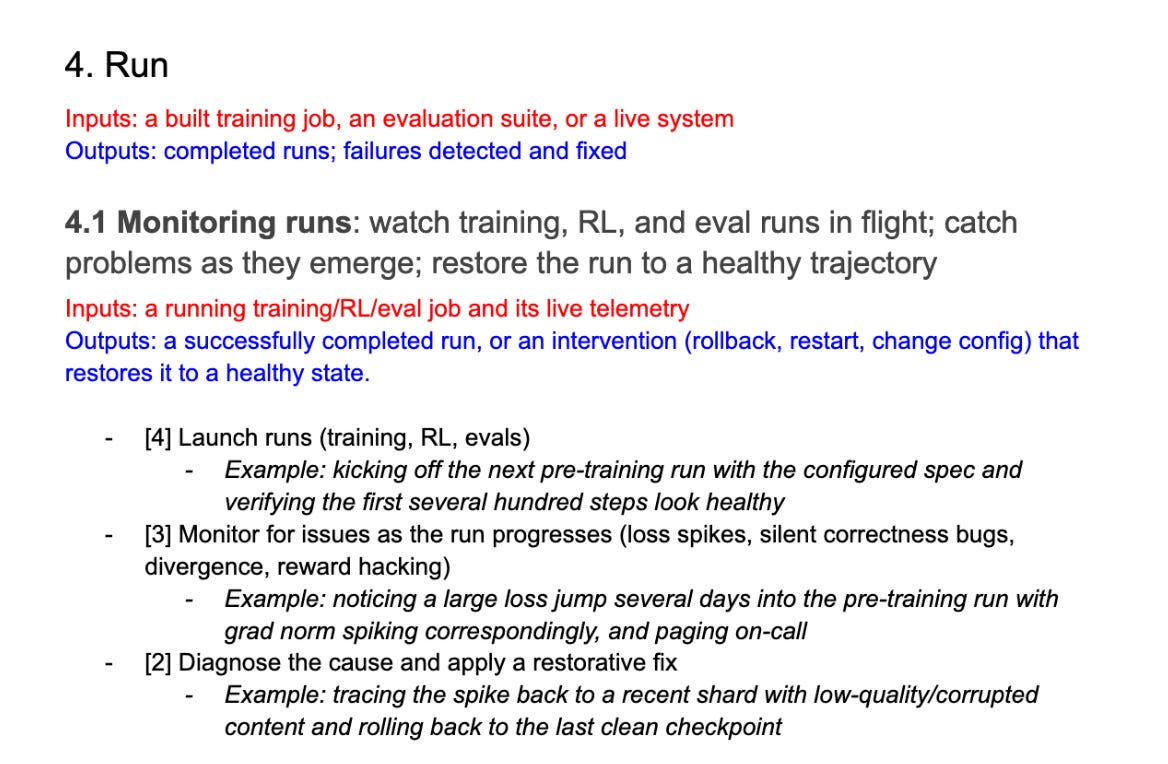
So you can see that this is way more granular than developing “solutions involving computer hardware and software” — our task descriptions get to the level of monitoring runs, and catching potential issues when they arise.你可以看出,这比开发“涉及计算机硬件和软件的解决方案”要细致得多——我们的任务描述达到了监控运行以及在问题出现时捕捉潜在问题的层面。
One thing you’ll notice about each task is that it includes a number next to it — that reflects our initial approach to estimating automation impact across tasks. Specifically, we rate how much we think current AIs automate each task on a scale of 0 to 5, based on the following rubric:你会注意到每个任务旁边都有一个数字——这反映了我们评估跨任务自动化影响的初步方法。具体来说,我们根据以下准则,以 0 到 5 的等级评估我们认为当前 AI 对每项任务的自动化程度:
We provide examples of each of these in the full proposal.我们在完整提案中提供了这些准则的示例。
This is of course quite subjective and there’s a ton of room for people to develop better ways to evaluate this, such as through internal benchmarks. Optimistically, an improved version of this could be used to construct a metric that we can extrapolate over time. This could be quite tricky, because we’d need to know which tasks need to be automated to kick off an intelligence explosion, and there might be new tasks. For example, perhaps AIs don’t need to “write a memo summarizing key takeaways” (unlike human researchers), if they have other ways of communicating with other AIs.当然,这非常主观,人们还有很大的空间来开发更好的评估方法,例如通过内部基准测试。乐观地说,改进后的版本可用于构建一个我们可以随时间推移进行外推的指标。这可能会非常棘手,因为我们需要知道哪些任务必须自动化才能引发智能爆炸,而且可能会出现新的任务。例如,如果 AI 有其他与 AI 交流的方式,它们可能就不需要像人类研究人员那样“撰写总结关键要点的备忘录”。
But our overall hope is simply that our full collection of tasks gives us an additional signal about what AI can and can’t automate at any point in time, supporting existing evidence we have from benchmarks and things like METR’s time horizons.但我们总体的希望是,我们收集的完整任务清单能为我们提供一个额外的信号,让我们了解 AI 在任何时间点能或不能自动化什么,从而支持我们从基准测试和 METR 的时间跨度等现有证据中得出的结论。
What’s next?接下来是什么?
It goes without saying, but just to be excessively clear, this was an initial attempt at an O*NET for AI research. The most natural next step is to build on what’s here and add tasks we missed, sharpen descriptions to be more precise and accurate, taxonomize to be more mutually exclusive and collectively exhaustive, and re-rate the list as AI improves.不用说,但为了极其清楚起见,这只是 AI 研究 O*NET 的初步尝试。最自然的下一步是在现有基础上进行构建,添加我们遗漏的任务,精简描述使其更精确准确,优化分类使其更具互斥性和完备性,并随着 AI 的进步重新评估清单。
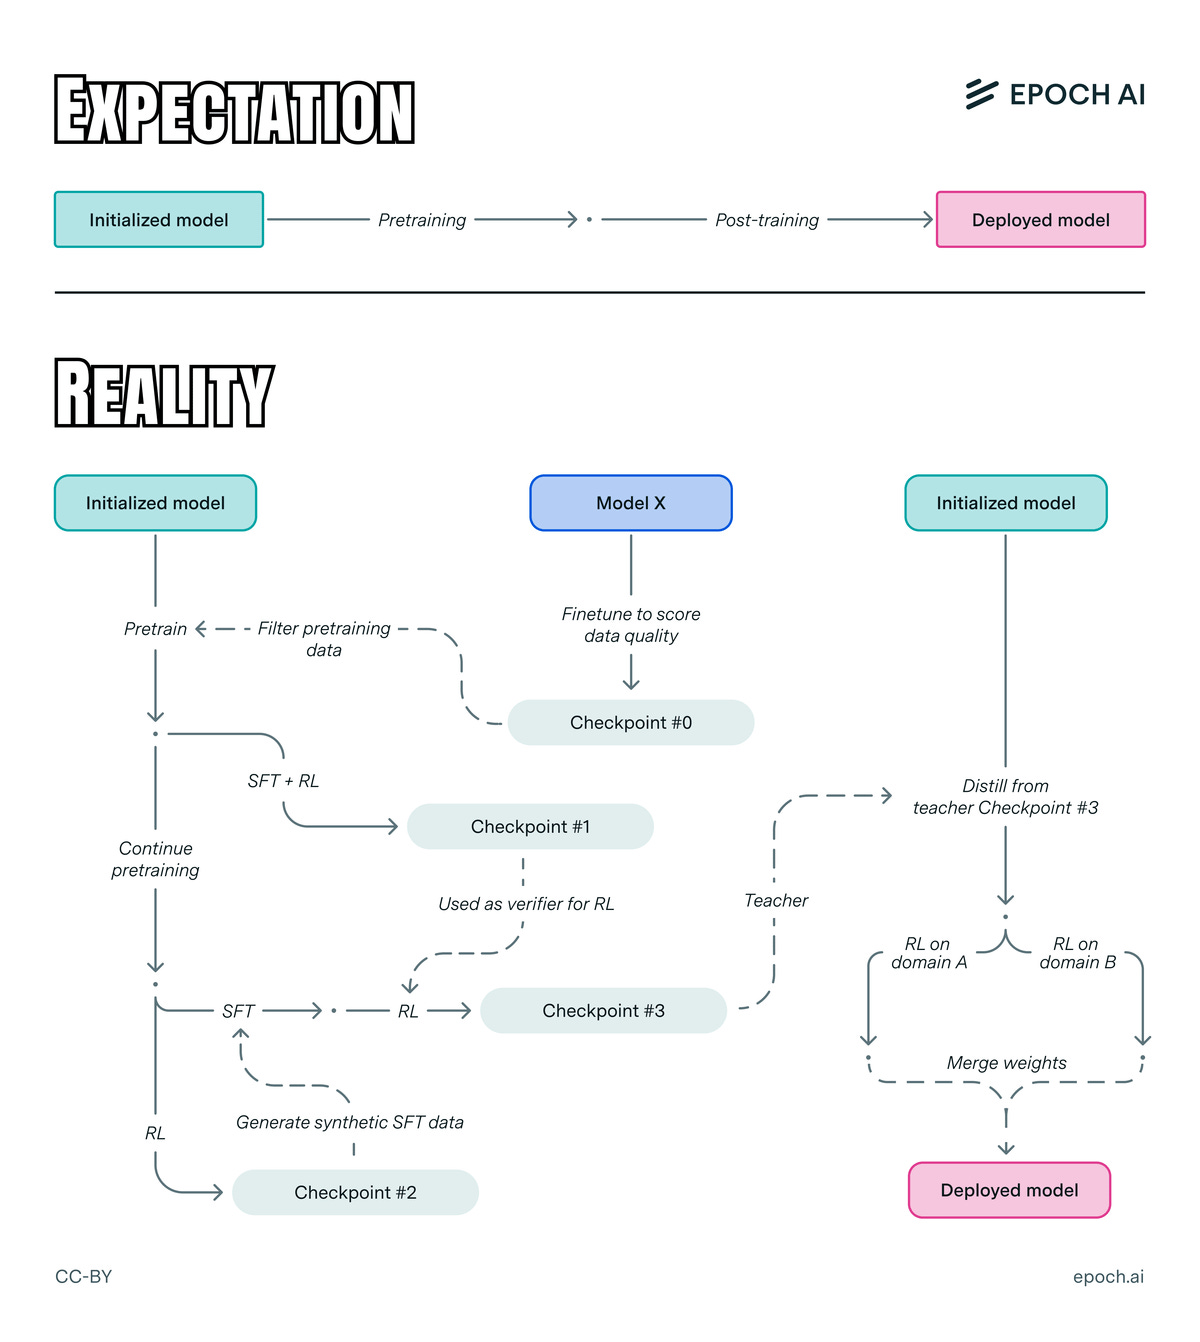
A step further would be to find other ways of organizing the taxonomy. For example, we thought about organizing all the tasks around the usual stages of model development, namely pre-training, post-training, and inference. We opted against it because it runs into several problems: (1) many tasks like “writing code for experiments” would be repeated across multiple stages, and (2) some tasks won’t fit naturally in these categories, not least because the training process can look super complex in practice. But just because we decided against this categorization doesn’t mean that it’s not workable.更进一步的方法是寻找组织分类法的其他方式。例如,我们曾考虑围绕模型开发的常规阶段(即预训练、后训练和推理)来组织所有任务。我们最终放弃了这种想法,因为它遇到了几个问题:(1) 许多任务(如“编写实验代码”)会在多个阶段重复出现,以及 (2) 一些任务无法自然地归入这些类别,尤其是在实践中训练过程可能看起来非常复杂的情况下。但仅仅因为我们决定不采用这种分类方式,并不意味着它不可行。
And we can say similar things about how we split up tasks: we’d ask if a task could be split into subtasks that would plausibly be automated at very different times — if we could, we’d split it up. We also tried to be more granular around tasks that require some amount of “taste” (such as whether to scale up a particular post-training recipe), since people seem to disagree about this. But you could choose different levels of granularity for sure.对于我们划分任务的方式,也可以说类似的话:我们会询问一个任务是否可以拆分为在不同时间点被自动化的子任务——如果可以,我们就会拆分它。我们还尝试在需要一定“品味”的任务(例如是否扩大某种特定的后训练配方)周围做得更细致,因为人们对此似乎意见不一。但你当然可以选择不同的粒度级别。
In general, we’d be very excited about collaborating with people to improve on our initial attempt. If you’re an AI researcher and think that we’ve messed up something in our classification or task descriptions, please share feedback or reach out! Or if you’re somebody who’d use something like an O*NET for AI R&D in your work, we’d love to talk to you and understand how we can improve things to suit your needs.总的来说,我们非常期待与大家合作,改进我们的初步尝试。如果你是一名 AI 研究人员,认为我们在分类或任务描述上出了差错,请分享反馈或联系我们!或者,如果你在工作中会用到类似 AI 研发 O*NET 的东西,我们很乐意与你交谈,了解我们如何改进以满足你的需求。
If this project goes well, we hope that it’ll serve as a stepping stone toward more directly tracking AI R&D automation, helping AI forecasters extrapolate trendlines further forward — and hopefully also tell us if the intelligence explosion is upon us.如果这个项目进展顺利,我们希望它能成为直接追踪 AI 研发自动化的垫脚石,帮助 AI 预测者更进一步地外推趋势线——并希望也能告诉我们智能爆炸是否即将来临。
We’d like to thank David Owen, Stefania Guerra, Robert Sandler, and Elliot Stewart for their feedback and support.我们感谢 David Owen、Stefania Guerra、Robert Sandler 和 Elliot Stewart 的反馈和支持。
Please also see our initial attempt and the accompanying feedback form. For direct corrections or specific inquiries, you can email js@epoch.ai.请参阅我们的初步尝试和随附的反馈表。如需直接更正或有具体询问,请发送电子邮件至 js@epoch.ai。
Depending on how you define it, an intelligence explosion could “start” well before fully automating AI research, because AIs would likely provide substantial uplift prior to that.
It’s possible that future AI systems make progress through routes that just really do not resemble current human AI R&D. If so, a task list based on current human workflows would completely miss the action, and our ontology would need to be updated at the very least.


Streetlighting is a real risk in AI timeline forecasts. We extrapolate compute and time horizons because they're measurable, not because they track research capability directly. A task-level taxonomy of AI R&D is a useful instrument for reducing that gap.