Every knowledge program seems to begin with the same request. A senior engineer is leaving in six weeks, and someone asks her to document the process she’s carried for years.每一个知识管理项目似乎都以同样的请求开始:一位资深工程师将在六周后离职,有人要求她记录下她多年来执行的工作流程。
She returns a clean flowchart of the happy path. The drawing is accurate and may even be elegant. It leaves out the thresholds she watches, the conditions that make the standard procedure unsafe, and the supplier whose parts fail in humid weather. She doesn’t think of those judgments as separate knowledge. After years on the job, they feel obvious.她提交了一份关于理想路径的简洁流程图。这张图准确无误,甚至堪称精妙。但它遗漏了她时刻关注的阈值、导致标准程序变得不安全的条件,以及那个在潮湿天气下零件容易出故障的供应商。她并不认为这些判断属于独立的知识。在岗位上工作多年后,这些判断对她而言已是显而易见的常识。
Six months later, a production line goes down and the knowledge base can’t explain what to do. The interview took place as per the process. Its transcript was chunked, embedded, and indexed, so the search returns the relevant passage quickly. The passage still can’t answer the question because no one asked the engineer to explain the judgment behind the procedure.六个月后,生产线停工,而知识库却无法提供应对方案。当时的访谈确实是按照流程进行的,访谈记录也经过了分块、嵌入和索引处理,因此搜索功能可以快速返回相关段落。但该段落依然无法回答问题,因为当时没有人要求那位工程师解释流程背后的判断依据。
That gap now limits many enterprise AI programs. Organizations continue to improve retrieval over collections that omit some of their most valuable operating knowledge. Better ranking can help people find what was recorded; it can’t recover the expertise that never entered the collection.这一缺口如今限制了许多企业 AI 项目的发展。企业不断改进对知识集合的检索能力,却忽略了其中一些最具价值的运营知识。更好的排序功能可以帮助人们找到已记录的内容,但无法找回那些从未进入知识库的专业经验。
The blind spot in enterprise knowledge systems企业知识系统中的盲点
Michael Polanyi gave the problem its durable formulation in 1966: “We can know more than we can tell.” In The Tacit Dimension, he argued that competence depends on skill, perception, and judgment that resist full explanation, even when an expert sincerely tries to teach them.迈克尔·波兰尼(Michael Polanyi)在 1966 年为这个问题给出了一个经典的表述:“我们所知的远比我们能表达的多。”他在《隐性维度》(The Tacit Dimension)一书中指出,能力依赖于技能、感知和判断,而这些要素即便在专家真诚尝试传授时,也难以完全用语言解释清楚。
In companies, tacit knowledge usually appears in three forms. Elicitable knowledge remains unspoken because nobody has asked a precise enough question, or because an expert assumes that everyone sees what she sees. Perceptual knowledge lives in trained attention: An engineer hears a bearing begin to fail, or a nurse notices that a patient looks wrong before a monitor changes. Collective knowledge resides in a team’s habits, standards, and shared sense of what a sound decision looks like in that organization. Each form requires a different method of transfer.在企业中,隐性知识通常表现为三种形式。可诱导知识(Elicitable knowledge)之所以未被言明,是因为没人提出足够精确的问题,或者专家认为人人都能看到她所见的事物。感知知识(Perceptual knowledge)存在于训练有素的注意力中:工程师能听出轴承开始磨损,护士能在监护仪报警前察觉病人状态异常。集体知识(Collective knowledge)则存在于团队的习惯、标准以及对该组织内何为“稳健决策”的共识中。每种形式都需要不同的转移方法。
Preventive judgment creates another difficulty for the architect. A failure produces a ticket, an incident report, and a trail of messages. An experienced operator who quietly avoids a known failure mode on a Friday afternoon produces none of those records. The useful outcome is the absence of an event, so the data pipeline receives no trace of the decision that produced it.预防性判断为架构师带来了另一个难题。故障会产生工单、事故报告和一系列沟通记录。而一位经验丰富的操作员如果能在周五下午悄悄规避某种已知的故障模式,则不会留下任何记录。其有益的结果是“未发生事件”,因此数据流水线中不会留下产生该决策的任何痕迹。
Machine learning can infer rules that people struggle to articulate, provided the model sees enough representative examples. It’s difficult to find enough examples of rare expertise for training. A company may have only a handful of unusual incidents and one person who has learned, over decades, how to read them.如果模型能看到足够多的代表性示例,机器学习可以推导出人们难以表达的规则。但要找到足够多用于训练的罕见专业经验示例非常困难。一家公司可能只有寥寥几次异常事故,以及一位历经数十年才学会如何解读这些事故的专家。
David Autor described this limit as “Polanyi’s paradox”: Many of the tasks that are hardest to automate depend on rules we can’t state. Modern machine learning works around the paradox by learning from examples, but the workaround weakens when examples are scarce. Fine-tuning can teach a model the company’s vocabulary and document formats. It can’t reconstruct decisions that left no data.大卫·奥托(David Autor)将这一局限描述为“波兰尼悖论”:许多最难自动化的任务依赖于我们无法陈述的规则。现代机器学习通过从示例中学习来绕过这一悖论,但当示例稀缺时,这种变通方法就会失效。微调可以教模型学习公司的术语和文档格式,但它无法重构那些没有留下数据支撑的决策。
At the same time, the economics have changed. Much of a field’s documented best practice now appears in frontier-model training data and is available to competitors at roughly the same price and quality. The more widely explicit knowledge circulates, the more a company’s advantage depends on local judgment: the exceptions, thresholds, relationships, and practiced responses that its people have accumulated.与此同时,经济环境也发生了变化。一个领域内大部分已记录的最佳实践,现在已出现在前沿模型的训练数据中,竞争对手可以以大致相同的价格和质量获得这些信息。显性知识传播得越广,公司的竞争优势就越依赖于本地化的判断:即其员工积累的例外情况、阈值、人际关系和实践经验。
That makes elicitation an architectural concern rather than an offboarding chore. The organization needs a repeatable way to surface the knowledge that can be expressed, a route for the expertise that must be demonstrated, and enough humility to distinguish the two.这使得知识诱导成为一项架构层面的考量,而非离职时的琐事。组织需要一种可重复的方法来挖掘可表达的知识,为必须通过演示才能传授的专长提供路径,并保持足够的谦逊来区分这两者。
A protocol for elicitation知识诱导协议
The central design question is straightforward: Which follow-up would prompt an expert to say the missing judgment aloud? The quality of the interview sets the ceiling for the knowledge base. The index determines how quickly someone can reach the resulting material.核心设计问题很简单:什么样的后续问题能促使专家说出那些缺失的判断依据?访谈的质量决定了知识库的上限,而索引则决定了人们获取最终成果的速度。
Interviews can be made more reliable even though judgment itself remains highly personal. An expert may know that a particular supplier fails in humid weather. The interviewing protocol doesn’t need to possess that knowledge in advance; it needs to notice a phrase such as “we escalate if it looks bad” and ask the expert to define “bad” in observable terms.尽管判断本身具有高度的个人色彩,但访谈过程是可以更加可靠的。专家可能知道某个特定的供应商在潮湿天气下会出故障。访谈协议不需要预先掌握这些知识,它只需要捕捉到类似“如果看起来情况不好,我们就升级处理”这样的短语,并要求专家用可观察的术语定义什么是“不好”。
Expert explanations tend to become vague in four places. An effective interview protocol asks targeted questions about each one:专家解释往往在四个方面变得模糊。有效的访谈协议会针对每一个方面提出有针对性的问题:
- Thresholds: Which number, reading, or condition triggers the action?阈值:哪个数值、读数或条件会触发该操作?
- Exceptions: When does the documented procedure cease to apply?例外情况:记录在案的程序在何时不再适用?
- Evidence: What did the expert observe before reaching the conclusion?证据:专家在得出结论前观察到了什么?
- Escalation: Who becomes involved, and at what point?升级机制:谁会参与其中,在什么节点参与?
These questions uncover the operational detail that runbooks often lack. They also identify a narrow, useful role for a language model during the interview: proposing the next question that turns a general statement into a usable rule. I’ve been building an open source toolkit, ExpertTrace, around that protocol.这些问题揭示了操作手册中通常缺失的运营细节。它们还确定了语言模型在访谈中一个狭窄但有用的角色:提出下一个问题,将笼统的陈述转化为可用的规则。我一直在围绕该协议构建一个开源工具包:ExpertTrace。
The value appears in the difference between what an expert volunteers and what the same expert confirms after one focused follow-up. Consider a typical first answer:其价值体现在专家自愿提供的陈述与经过一次针对性追问后确认的陈述之间的差异。考虑一个典型的初步回答:
We review high-risk use cases before deployment. If the risk seems significant, we escalate to the governance council.我们在部署前会审查高风险用例。如果风险看起来很大,我们会升级给治理委员会。
The statement will embed cleanly and retrieve for a relevant query, but a new employee still cannot act on it. “Seems significant” supplies no decision criterion. A targeted follow-up produces something much more useful:这段陈述可以很好地被嵌入并用于相关查询,但新员工仍然无法据此采取行动。“看起来很大”没有提供任何决策标准。而一次有针对性的追问会产生更有用的结果:
Escalation to the council is required when the use case touches employment, credit, or health decisions, or when model output reaches a customer without human review. Predeployment review is skipped for internal-only tools with no personal data, which is the exception people get wrong most often. If we cannot identify a named accountable owner, the review does not proceed, regardless of risk tier.当用例涉及就业、信贷或健康决策,或者模型输出在未经人工审查的情况下触达客户时,必须升级给委员会。仅供内部使用且不含个人数据的工具可跳过部署前审查,这是人们最常犯错的例外情况。如果我们无法确定具体的责任所有者,无论风险等级如何,审查都不会继续进行。
The second answer takes little additional time, yet it contains a decision rule, an exception, a recurring failure pattern, and a blocking condition. It can guide a real dispute instead of merely mentioning the subject.第二个回答几乎不需要额外的时间,但它包含了决策规则、例外情况、反复出现的故障模式以及阻断条件。它能够指导实际的争议处理,而不仅仅是提及该主题。
The protocol needs guardrails. Limit the number of follow-ups; a long interrogation exhausts the expert and eventually produces agreeable noise. Keep the model focused on generating questions, and separate that task from compiling and validating the answers. An expert’s statement belongs in the record with its provenance and context. Whether the statement is accurate requires independent review.该协议需要护栏。限制追问的次数;长时间的盘问会使专家精疲力竭,最终产生随声附和的噪音。让模型专注于生成问题,并将该任务与编译和验证答案分开。专家的陈述应连同其来源和背景一起归档。至于陈述是否准确,则需要独立的审查。
The four-plane architecture四平面架构
Elicitation is one part of a larger knowledge system. A tacit-aware architecture has four planes—capture, representation, serving, and transmission and each plane addresses a different failure in the movement of expertise. Figure 1 shows how the four planes work together and which forms of tacit knowledge each can reach.知识诱导是更大知识系统的一部分。一种具备隐性知识感知能力的架构包含四个平面:捕捉、表示、服务和传输。每个平面都针对专业知识流动中的不同故障环节。图 1 展示了这四个平面如何协同工作,以及每个平面能够触达的隐性知识形式。
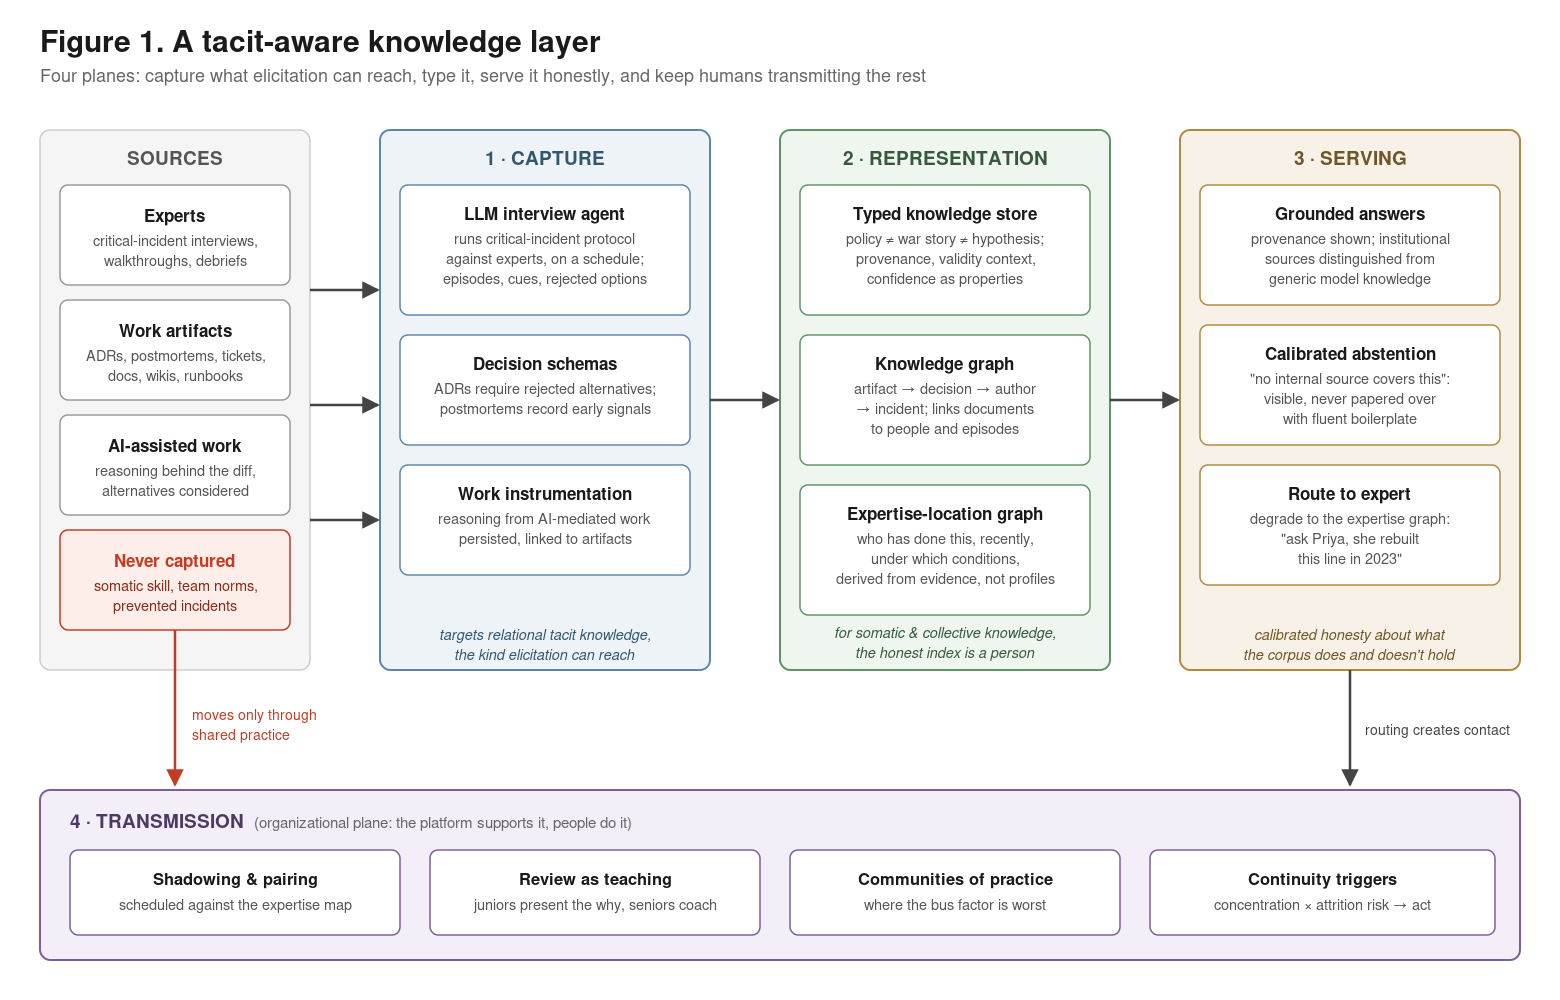
In the capture plane, structured interviews, incident reconstruction, decision journals, and observation collect more than polished procedure. Record the trigger, evidence, exception, and escalation path while the expert can still explain the surrounding conditions. Route perceptual skill toward demonstration and practice instead of forcing it into prose.在捕捉平面,结构化访谈、事故重构、决策日志和观察记录所收集的内容远超润色后的程序文档。在专家还能解释周边条件时,记录下触发因素、证据、例外情况和升级路径。将感知技能引导至演示和实践,而不是强行将其转化为文字。
Once knowledge has been captured, the representation plane preserves the distinctions that make the material trustworthy. A compliance policy, a war story, and an untested hypothesis shouldn’t become interchangeable chunks. Carry provenance, confidence, and validity context—including the plant, time period, equipment, and conditions—as first-class properties. Extend the knowledge graph beyond documents to the people and episodes that produced them.一旦知识被捕捉,表示平面就会保留使材料可信的区分度。合规政策、经验故事和未经测试的假设不应成为可互换的片段。将来源、置信度和有效性背景(包括工厂、时间段、设备和条件)作为一等属性进行携带。将知识图谱从文档扩展到产生这些文档的人员和事件。
The serving plane then determines how that knowledge reaches users. Answers should cite retrieved evidence and show the source. When the collection can’t answer, the system should say so clearly and route the question to someone with relevant experience. “Ask Joe; she rebuilt this line in 2023” is more useful than a fluent paragraph assembled from weak evidence, and the referral restores the human contact through which difficult knowledge often moves.服务平面随后决定知识如何触达用户。答案应引用检索到的证据并标明来源。当知识库无法回答时,系统应明确说明,并将问题转交给具有相关经验的人员。“去问 Joe;她 2023 年重建过这条生产线”比一段由薄弱证据拼凑出的流畅段落更有用,且这种转介恢复了人际联系,而困难的知识往往正是通过这种联系进行传递的。
The transmission plane completes the architecture by helping how expertise moves between people through shadowing, teaching, and communities of practice. The platform should detect when knowledge concentration and attrition risk converge, then trigger capture and apprenticeship before a notice period begins.传输平面通过帮助知识在人员之间通过影子工作、教学和实践社区进行流动,完成了整个架构。平台应在检测到知识集中度与流失风险趋同时,在通知期开始前触发捕捉和学徒制流程。
Gabriel Szulanski examined 271 observations of 122 best-practice transfers across eight companies and found that even willing teams struggled to reproduce methods developed elsewhere in the same organization. The difficulty often began with causal ambiguity where people could describe the steps without fully understanding why they worked. Receiving teams also needed enough context and experience to absorb and apply what they learned. Preparation, coaching, and time helped them rebuild the practice in their own setting. A repository could preserve the record; the receiving teams still had to turn that record into working knowledge.Gabriel Szulanski 研究了八家公司中 122 个最佳实践转移的 271 个观察案例,发现即使是积极的团队也很难复制组织内其他地方开发的方法。困难往往始于因果模糊性,即人们可以描述步骤,却不完全理解其运作原理。接收团队也需要足够的背景和经验来吸收和应用所学内容。准备工作、辅导和时间帮助他们在自己的环境中重建了这些实践。存储库可以保存记录,但接收团队仍然必须将这些记录转化为工作知识。
Evaluating the knowledge layer评估知识层
Retrieval precision and answer faithfulness show how well a system serves its existing collection. They don’t reveal whether the collection contains the knowledge on which the organization actually depends. That question needs a separate evaluation loop tied to capture priorities and transfer outcomes. Figure 2 shows how the loop moves from offline evaluation to abstention calibration and then to transfer outcomes.检索精度和答案忠实度展示了系统服务现有知识库的效果,但它们无法揭示知识库是否包含了组织真正依赖的知识。这个问题需要一个与捕捉优先级和转移成果挂钩的独立评估循环。图 2 展示了该循环如何从离线评估转向弃权校准,再到转移成果。
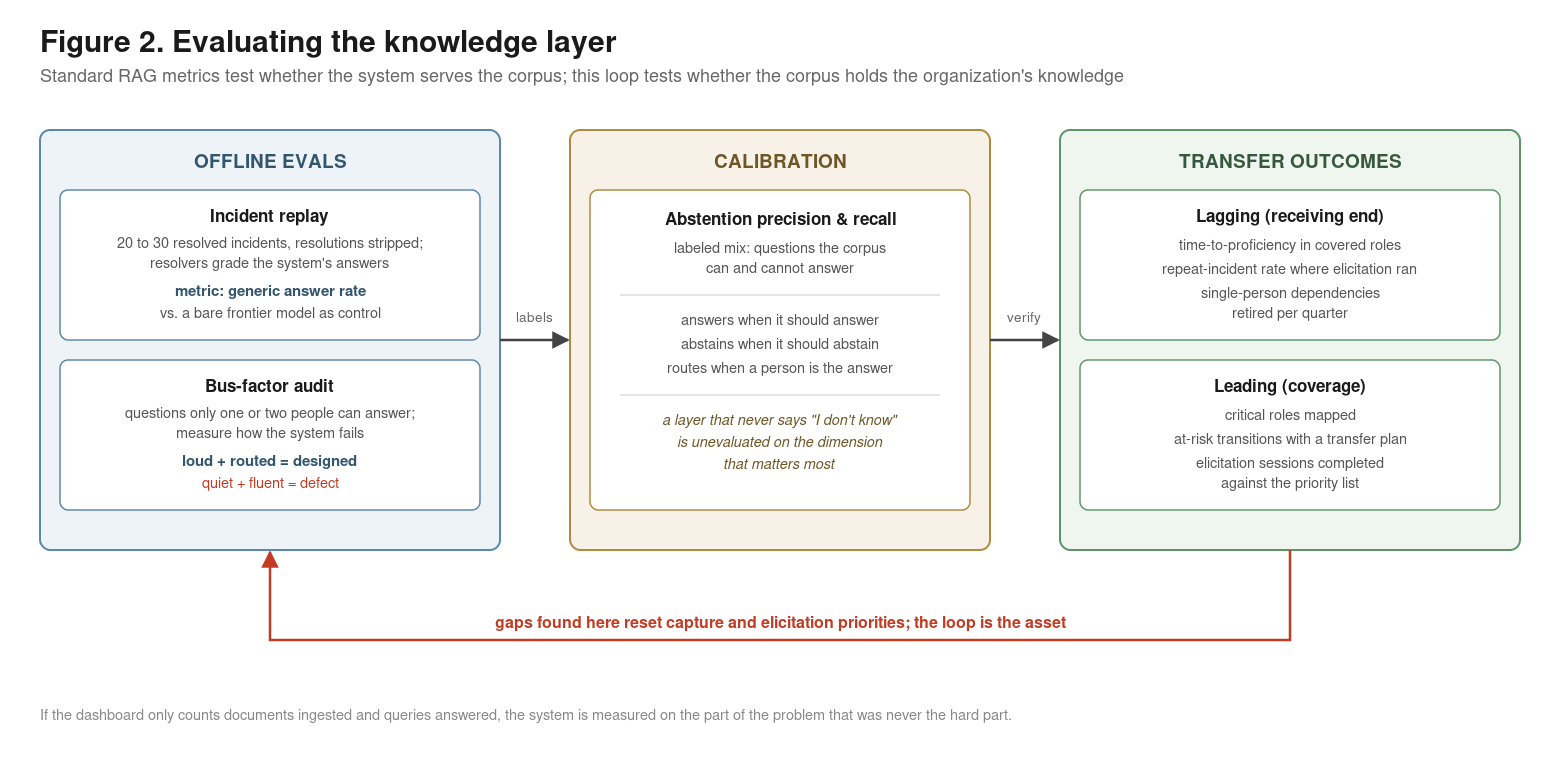
The evaluation begins with incident replay. Select 20 or 30 resolved incidents, remove the resolutions, and give the opening facts to the system. Ask the engineers who solved them to grade its responses. Compare those answers with responses from a frontier model that lacks access to the company’s collection. The gap reveals the generic-answer rate: how often the internal system merely restates public knowledge. If reviewers can’t tell the two sets apart, the pipeline adds little institutional value.评估始于事故重演。选择 20 或 30 个已解决的事故,移除解决方案,并将初始事实提供给系统。让解决这些事故的工程师对系统的回答进行评分。将这些答案与缺乏公司内部知识库的前沿模型的回答进行对比。差距揭示了通用答案率:内部系统有多频繁地仅仅重述了公共知识。如果审查人员无法分辨两组答案,那么该流水线几乎没有提供任何机构价值。
A bus-factor audit tests questions that only one or two employees can answer, and study how the system fails. A clear admission of uncertainty followed by a useful referral is healthy. Fluent boilerplate damages trust in every response, including the accurate ones.“公共汽车因子”(Bus-factor)审计会测试只有一两个员工能回答的问题,并研究系统如何应对。明确承认不确定性并给出有用的转介是健康的表现。流利但空洞的套话会损害对每一次回复的信任,包括那些准确的回复。
Abstention calibration measures whether the system answers when evidence exists and declines when corpus can’t support an answer. Build a labeled set of answerable and unanswerable questions, then track abstention precision and recall as the collection grows. A system that never says “I don’t know” is unevaluated on the dimension that matters most.弃权校准衡量的是系统在有证据时是否回答,以及在语料库不支持时是否拒绝回答。建立一个包含可回答和不可回答问题的标记集,然后在知识库增长时跟踪弃权精度和召回率。一个从不说“我不知道”的系统,在最重要的维度上是未经评估的。
Transfer outcomes complete the loop by measuring whether knowledge has reached the people who need it. Evidence of transfer appears in shorter time to proficiency, fewer repeat incidents after elicitation, and fewer critical responsibilities that depend on a single person. Document and query counts describe system activity; they don’t show whether someone else can now make the decision.转移成果通过衡量知识是否已触达需要它的人来完成闭环。转移的证据体现在更短的熟练周期、诱导后重复事故的减少,以及对单一人员依赖的关键责任的降低。文档和查询计数描述的是系统活动,它们无法表明是否有人现在能够做出该决策。
A strong knowledge system records what an expert said, preserves the conditions around the statement, and marks uncertainty. It also recognizes expertise that requires demonstration, apprenticeship, or team practice. Every evening, the people who carry that knowledge walk out the door. The architecture should be ready long before one gives notice.一个强大的知识系统记录专家所言,保留陈述周边的条件,并标记不确定性。它还识别出那些需要演示、学徒制或团队实践的专业知识。每天傍晚,携带这些知识的人都会走出大门。架构必须在某人提交离职通知很久之前就准备好。
Is cybersecurity part of your job in any way? If so, we’d like to know what you think for a report we’re writing. Just answer these quick 11 questions. Thanks in advance! Take the survey >网络安全与您的工作有任何关联吗?如果是,我们希望了解您的想法,以用于我们正在撰写的一份报告。只需回答这 11 个快速问题。提前感谢!参与调查 >