Graph Engineering for AI Agents: From Prompts and Loops to Workflows人工智能代理的图工程:从提示词与循环到工作流
A viral debate over loops versus graphs points to a bigger shift in how we build AI systems. Here’s what graph engineering actually means, how it differs from prompt, context, and loop engineering, and why it matters.一场关于“循环”与“图”的激烈辩论,揭示了我们构建人工智能系统方式的重大转变。本文将探讨图工程的真正含义,它与提示词工程、上下文工程以及循环工程的区别,以及它为何如此重要。
1. Introduction: From a viral X fight to a graph you can build by hand this week1. 引言:从 X 平台上的激烈争论到本周即可手动构建的图
In mid-2026, Peter Steinberger — the founder of OpenClaw — posted a twelve-word question on X: "Are we still talking loops or did we shift to graphs yet?" It shouldn't have gone anywhere. It's the kind of question builders ask each other in Slack DMs, not something that racks up replies from half of AI Twitter. But it did, and a few hours later, AI engineer Hamel Husain answered it directly, publishing an X Article with a title catching everyone's attention: "Loop Engineering Is Dead. Enter Graph Engineering."2026 年年中,OpenClaw 创始人彼得·斯坦伯格 (Peter Steinberger) 在 X 上发布了一个十二个词的问题:“我们还在谈论循环吗,还是已经转向图了?”这本不该引起什么波澜,这只是开发者们在 Slack 私信中交流的那种问题,而非能在 AI 推特圈引发广泛回复的话题。但事实并非如此,几小时后,人工智能工程师哈梅尔·侯赛因 (Hamel Husain) 直接回答了这个问题,并发布了一篇标题引人注目的 X 文章:《循环工程已死,图工程时代来临》。
And the public debate started. Within days there were counterargument posts arguing loop engineering wasn't dead at all, explainer threads, YouTube videos breaking down what the tweet actually meant... 随后,公开辩论开始了。几天之内,出现了反驳循环工程并未消亡的论点文章、解释性帖子,以及解析该推文实际含义的 YouTube 视频……
However, there might be a question that raises wonder for those who are using agentic AI. 然而,对于那些正在使用代理式人工智能的人来说,可能会产生一个疑问。
What is graph engineering and how does it help? How is it different from other, earlier techniques such as prompt engineering, context engineering, and loop engineering?什么是图工程,它有何帮助?它与提示词工程、上下文工程和循环工程等早期技术有何不同?
2. Who this is for2. 目标读者
This is for people who already use AI for real, repeatable work—not just one-off prompts. Maybe you use it to research an idea, triage support tickets, review code, draft content, or make decisions from messy information. You’ve probably also seen where the simple “give it a task and let it loop” approach starts to break down: a check gets skipped, a weak answer gets accepted too early, or something that looked right on the first pass falls apart on the second.本文面向那些已经将人工智能应用于实际、可重复工作的人——而不仅仅是偶尔使用提示词的人。也许你用它来研究想法、分流支持工单、审查代码、起草内容或根据杂乱的信息做出决策。你可能也已经发现,简单的“给它一个任务并让它循环”的方法在何时开始失效:某项检查被跳过、一个薄弱的答案过早被采纳,或者第一遍看起来正确的内容在第二遍时分崩离析。
You don’t need to be building agents or working with an orchestration framework to follow along. The goal is to make the loops-versus-graphs debate concrete enough that you can see what actually changes in practice. By the end, you’ll be able to take one workflow you already run with AI, sketch it as a graph on paper, and decide whether adding structure would actually make it better.你不需要正在构建代理或使用编排框架也能理解本文。我们的目标是将“循环与图”的辩论具体化,让你看到实践中究竟发生了什么变化。读完本文,你将能够把你已经在运行的一个人工智能工作流在纸上画成图,并判断增加结构是否真的能改善它。
3. The problem with single-agent loops3. 单代理循环的问题
3.1 How is Graph Engineering different?3.1 图工程有何不同?
Here is a brief explanation of the differences. 以下是关于差异的简要说明。
Prompt engineering optimizes what you say to a model.提示词工程优化的是你对模型说的话。
Context engineering optimizes what the model can see when it answers. Both still operate within a single turn.上下文工程优化的是模型在回答时能看到的内容。两者仍都在单轮对话内运行。
Loop engineering moves up a level. It gives the model tools, memory, and the ability to iterate—but control still lives inside one continuous run. The model decides what happens next.循环工程则更进一步。它为模型提供了工具、记忆和迭代的能力——但控制权仍然保留在一次连续的运行中。由模型决定下一步做什么。
Graph engineering changes who is in control. Instead of letting the model manage the process as it goes, you define the nodes, routing logic, and checkpoints in advance. The model contributes judgment only at the steps that actually require it; the graph decides what happens next.图工程改变了控制权归属。你无需让模型在运行过程中管理流程,而是预先定义节点、路由逻辑和检查点。模型仅在确实需要判断的步骤中贡献判断力;由图来决定下一步做什么。
In short: from trusting a model to manage the entire process to trusting a structure to manage the process—and using models only where their judgment is genuinely needed.简而言之:从信任模型来管理整个过程,转变为信任结构来管理过程——仅在真正需要模型判断力的地方使用模型。
3.2 Why a single-agent loop causes issue3.2 为什么单代理循环会导致问题
Most people are using AI in much the same way: open a chat, ask a big question, get a confident answer, and move on. Sometimes the answer seems right, sometimes it's too broad, sometimes it's incorrect. Then they have to be validated and rechecked over and over, without a fix workflow or structure, which leads to different quality each time.大多数人使用人工智能的方式大同小异:打开聊天窗口,问一个大问题,得到一个自信的回答,然后继续。有时答案看起来是对的,有时又太笼统,有时则是错误的。然后,他们必须反复验证和复核,由于缺乏固定的工作流或结构,导致每次的质量参差不齐。
Let's look at a simple example to understand why this manual technique is inefficient.让我们看一个简单的例子来理解为什么这种手动技术效率低下。
Imagine you’re trying to validate a startup idea: should you build an AI bookkeeping tool for Shopify merchants?假设你正在尝试验证一个创业想法:你应该为 Shopify 商家构建一个人工智能记账工具吗?
You ask the model. It researches the market, finds a few competitors, sketches a go-to-market plan, and gives you something that looks like a finished memo. By the end, it feels like you’ve done the research, and the plan looks good.你问模型。它研究市场,找到几个竞争对手,草拟了一份市场进入计划,并给你一份看起来像完成的备忘录。最后,你感觉自己完成了研究,计划看起来也不错。
But look at what actually happened.但看看实际发生了什么。
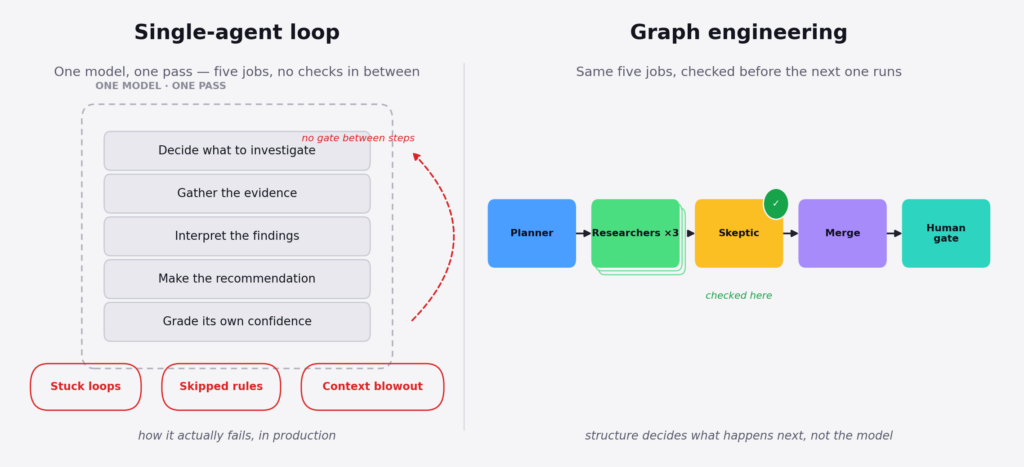
One model decided what was worth investigating. Then, it gathered the evidence, interpreted what it found, made a recommendation, and judged its own confidence in that recommendation. It did all of this in a single run, with no one checking its work along the way—no one confirming whether its initial direction was good enough, and no one catching where its reasoning went wrong.一个模型决定了什么值得调查。然后,它收集证据,解释发现的内容,提出建议,并判断自己对该建议的信心。它在单次运行中完成了所有这些工作,过程中没有人检查它的工作——没有人确认其初始方向是否足够好,也没有人捕捉到它推理出错的地方。
That’s the single-agent loop. It looks good on the surface, but the underlying process is flawed.这就是单代理循环。表面上看起来不错,但底层过程是有缺陷的。
This is also what causes many of the problems we see when agents are used in real systems: they get stuck repeating unproductive steps, miss important business rules, or run out of context halfway through a task.这也是当代理在实际系统中使用时,我们看到的许多问题的原因:它们陷入重复无效步骤的困境,遗漏重要的业务规则,或者在任务进行到一半时耗尽上下文。
The answer isn’t a better prompt. It’s a smaller job.答案不是更好的提示词。而是更小的工作任务。
One thing from my experience: if you already know a business rule or have domain knowledge, put it directly in code instead of hoping the model remembers it. Use the model only for the parts that actually require judgment—interpreting something ambiguous, comparing messy information, or choosing between possible next steps.我的一点经验:如果你已经了解某项业务规则或具备领域知识,请直接将其写入代码中,而不是寄希望于模型能记住它。仅在真正需要判断的部分使用模型——例如解释模糊内容、比较杂乱信息或在可能的后续步骤之间进行选择。
Don’t give the model control over the entire workflow. Give it one clearly defined step at a time.不要让模型控制整个工作流。一次只给它一个定义明确的步骤。
That’s the idea behind graph engineering: instead of trusting one model to make an entire decision from start to finish, you build a workflow that determines what happens next. The model provides judgment where judgment is useful. The graph provides structure everywhere else.这就是图工程背后的理念:不要信任一个模型从头到尾做出整个决策,而是构建一个决定下一步做什么的工作流。模型在需要判断的地方提供判断力。图在其他所有地方提供结构。
Keep the Shopify bookkeeping question in mind. For the rest of this piece, we’ll build a graph around that question one piece at a time, until “structure instead of judgment” becomes something concrete you can actually see.记住 Shopify 记账的问题。在本文的其余部分,我们将围绕这个问题一点一点地构建一个图,直到“以结构代替判断”成为你可以直观感受到的具体事物。
4. The building blocks of an agent graph4. 代理图的构建模块
Strip away the diagrams, and an agent graph is surprisingly simple. It comes down to three core pieces: nodes, edges, and state. There are also a couple of things—reducers and checkpoints—that become important once you move from a demo to production.剥离掉图表,代理图其实非常简单。它归结为三个核心部分:节点 (nodes)、边 (edges) 和状态 (state)。一旦你从演示转向生产环境,还有几样东西——归约器 (reducers) 和检查点 (checkpoints)——也会变得很重要。
A node is one self-contained unit of work. It could be an LLM call, a human approval step, or a regular deterministic calculation. Not every node needs a model. Checking whether an invoice crosses an approval threshold doesn’t need an LLM. Deciding whether an email is actually a refund request probably does.节点是一个独立的任务单元。它可以是 LLM 调用、人工批准步骤或常规的确定性计算。并非每个节点都需要模型。检查发票是否超过审批阈值不需要 LLM。但判断一封电子邮件是否真的是退款请求则可能需要。
An edge decides what happens next. This is where most of the “graph” idea comes from: after one node finishes, where should the work go? Sometimes the next step is fixed. Sometimes it depends on the result. Sometimes one step fans out into several tasks that can run in parallel. Below are 7 common edge types.边决定下一步做什么。这就是“图”概念的大部分来源:在一个节点完成后,工作应该流向哪里?有时下一步是固定的。有时取决于结果。有时一个步骤会分叉成几个可以并行运行的任务。以下是 7 种常见的边类型。
Edge type | What it does | In the Shopify graph |
|---|---|---|
Direct | One step feeds straight into the next, no branching | Skeptic → merge, merge → human |
Conditional | Routes to a different node based on the output before it | Would send a narrow question straight to one researcher, skipping the fan-out |
Parallel | Fans a task out to several nodes at once | Planner → the three researchers |
Looping | Sends a failing result back with the reason attached | Merge → skeptic → merge, the second-pass check |
Error | Catches a broken node and routes to recovery logic | Not used here — e.g. a failed search call retrying before a researcher reports back |
Human-controlled | Pauses the workflow until a person approves | The founder's gate before acting on the recommendation |
Event-triggered | Waits on something outside the graph entirely | Not used here — e.g. a new competitor listing re-triggering research |
State is the shared record that moves through the graph. It holds things like the original task, research gathered so far, drafts, intermediate results, and pass/fail verdicts from previous checks. Instead of stuffing the entire workflow into one growing chat history, each step reads from and writes to a structured state.状态是贯穿整个图的共享记录。它保存诸如原始任务、迄今为止收集的研究、草稿、中间结果以及来自先前检查的通过/失败结论等信息。与其将整个工作流塞进一个不断增长的聊天历史中,不如让每个步骤从结构化的状态中读取并写入。
Now put those three pieces back into the Shopify example.现在把这三个部分放回 Shopify 的例子中。
A planner node takes “Should I build an AI bookkeeping tool for Shopify merchants?” and breaks it into three pillars: customer pain, competitors, and distribution. From there, the graph fans out to three research nodes running in parallel. Their findings are added to the state. A skeptic node checks which claims actually hold up, and another node uses the surviving evidence to draft a recommendation.一个规划节点接收“我应该为 Shopify 商家构建一个人工智能记账工具吗?”并将其拆分为三个支柱:客户痛点、竞争对手和分销。从那里,图分叉为三个并行运行的研究节点。它们的发现被添加到状态中。一个怀疑节点检查哪些主张真正站得住脚,另一个节点利用幸存的证据起草建议。
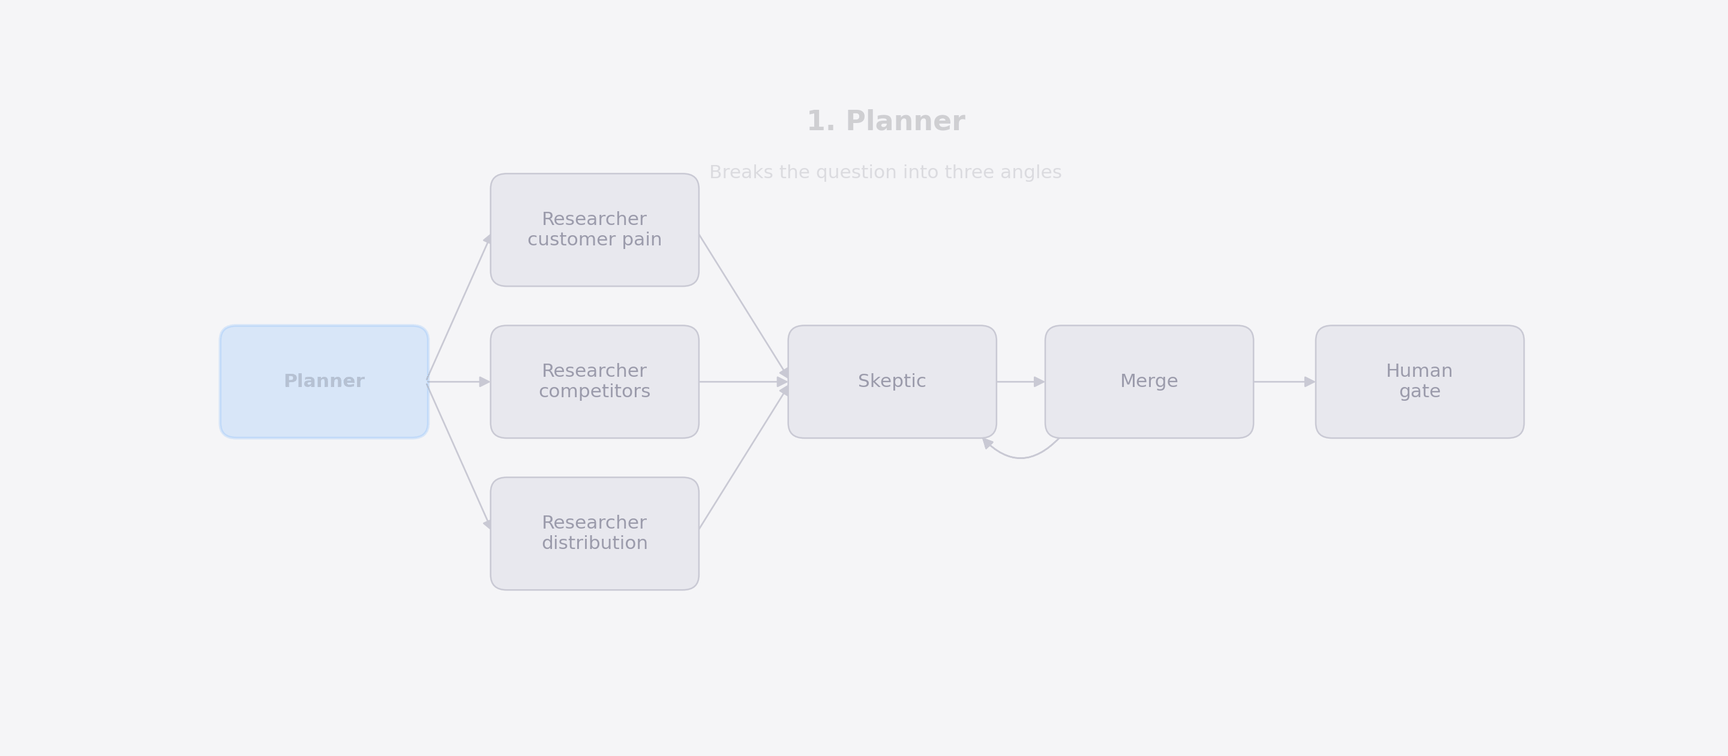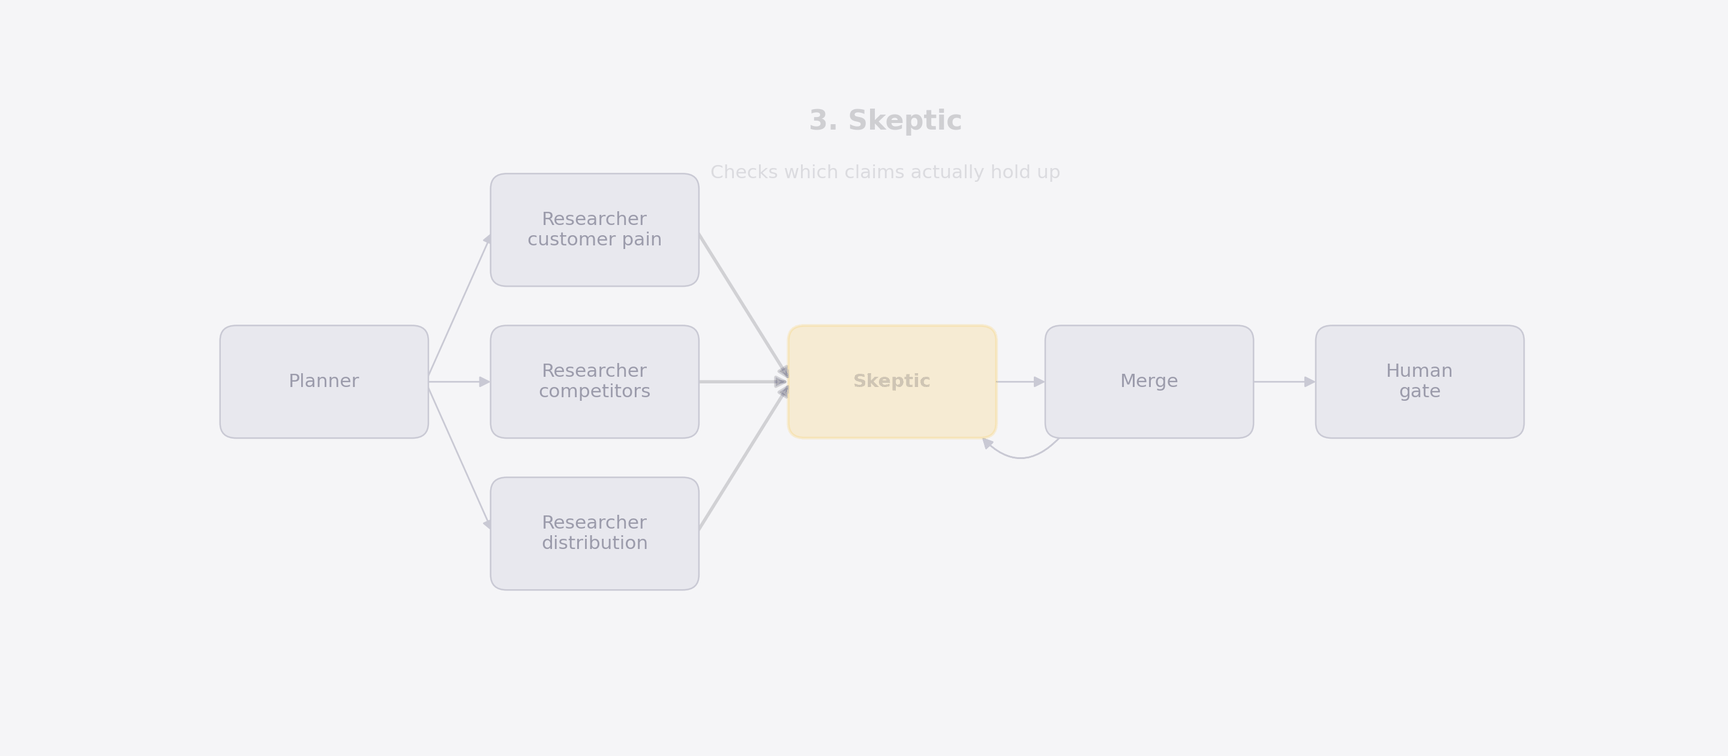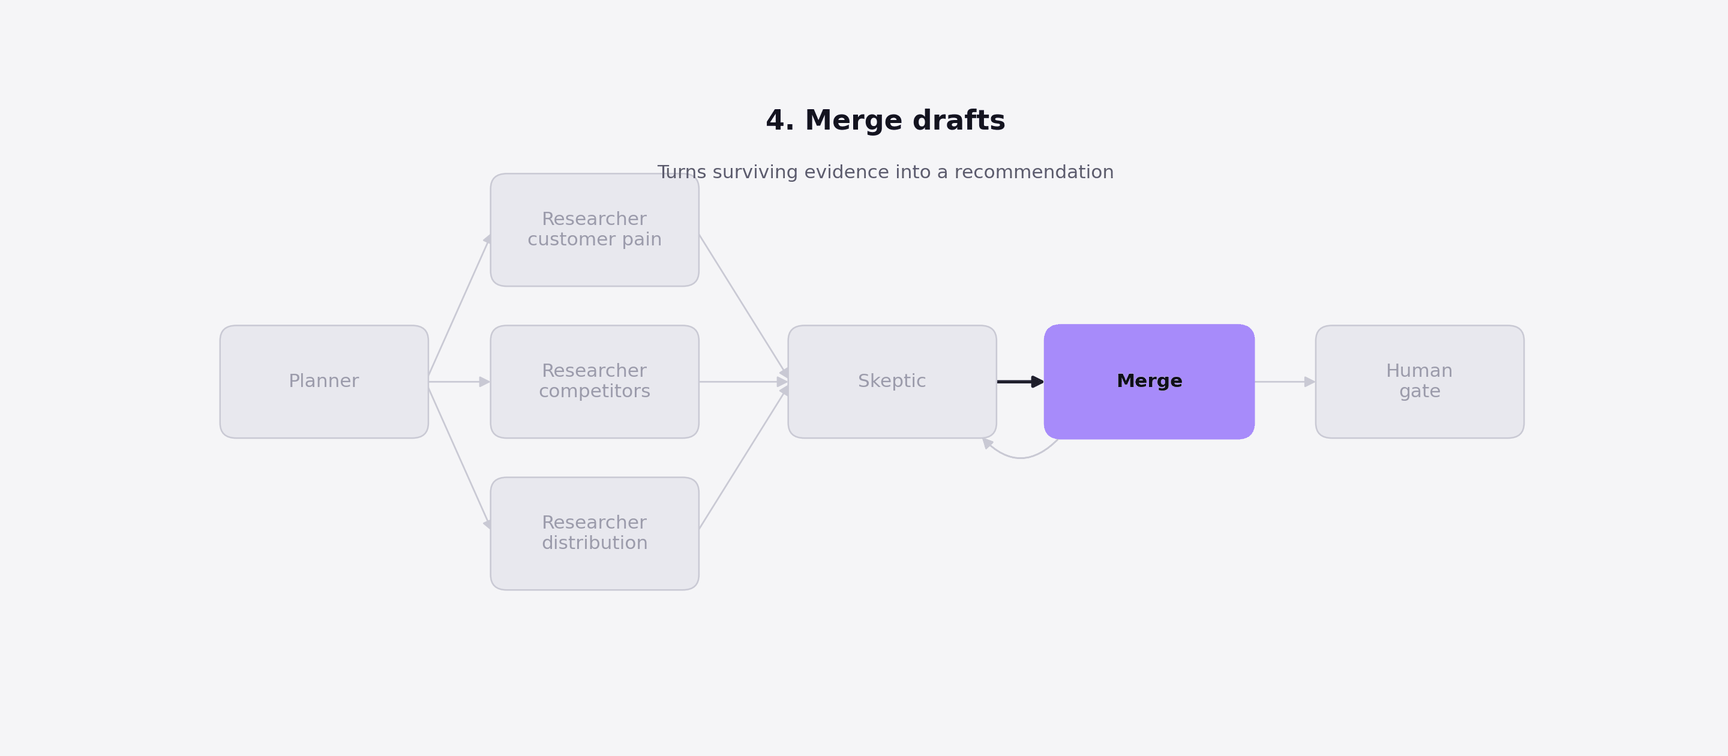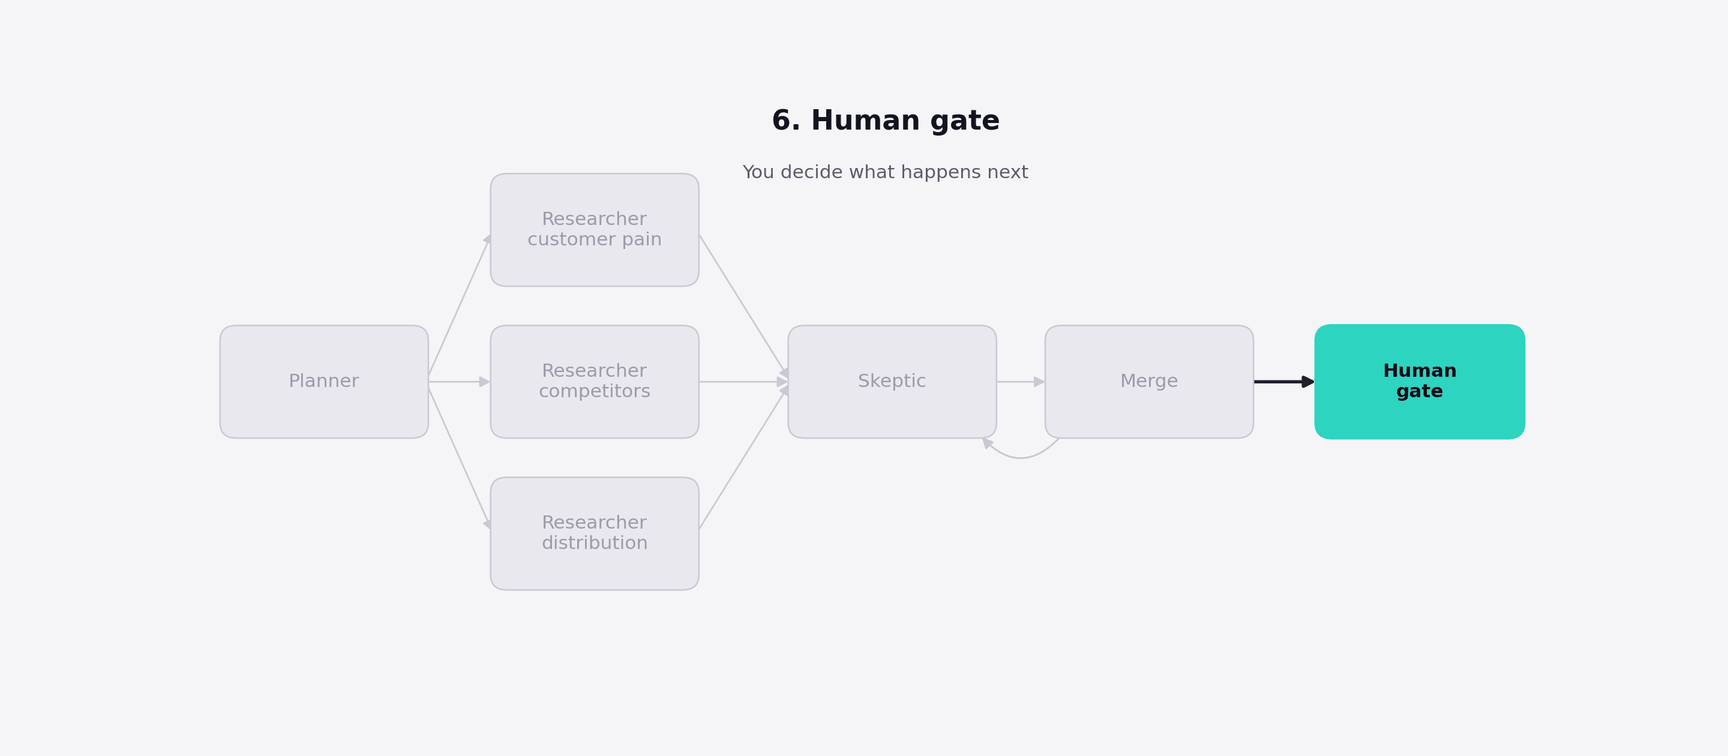
That recommendation, along with the research and checks behind it, eventually reaches a human who decides what to do next.该建议以及其背后的研究和检查,最终会到达一个决定下一步做什么的人类手中。
That’s the graph: nodes do the work, edges decide where the work goes, and state carries the information between them.这就是图:节点执行工作,边决定工作去向,状态在它们之间传递信息。
Two more concepts start to matter when you move from a diagram to a real production system: reducers and checkpoints.当你从图表转向真正的生产系统时,还有两个概念开始变得重要:归约器和检查点。
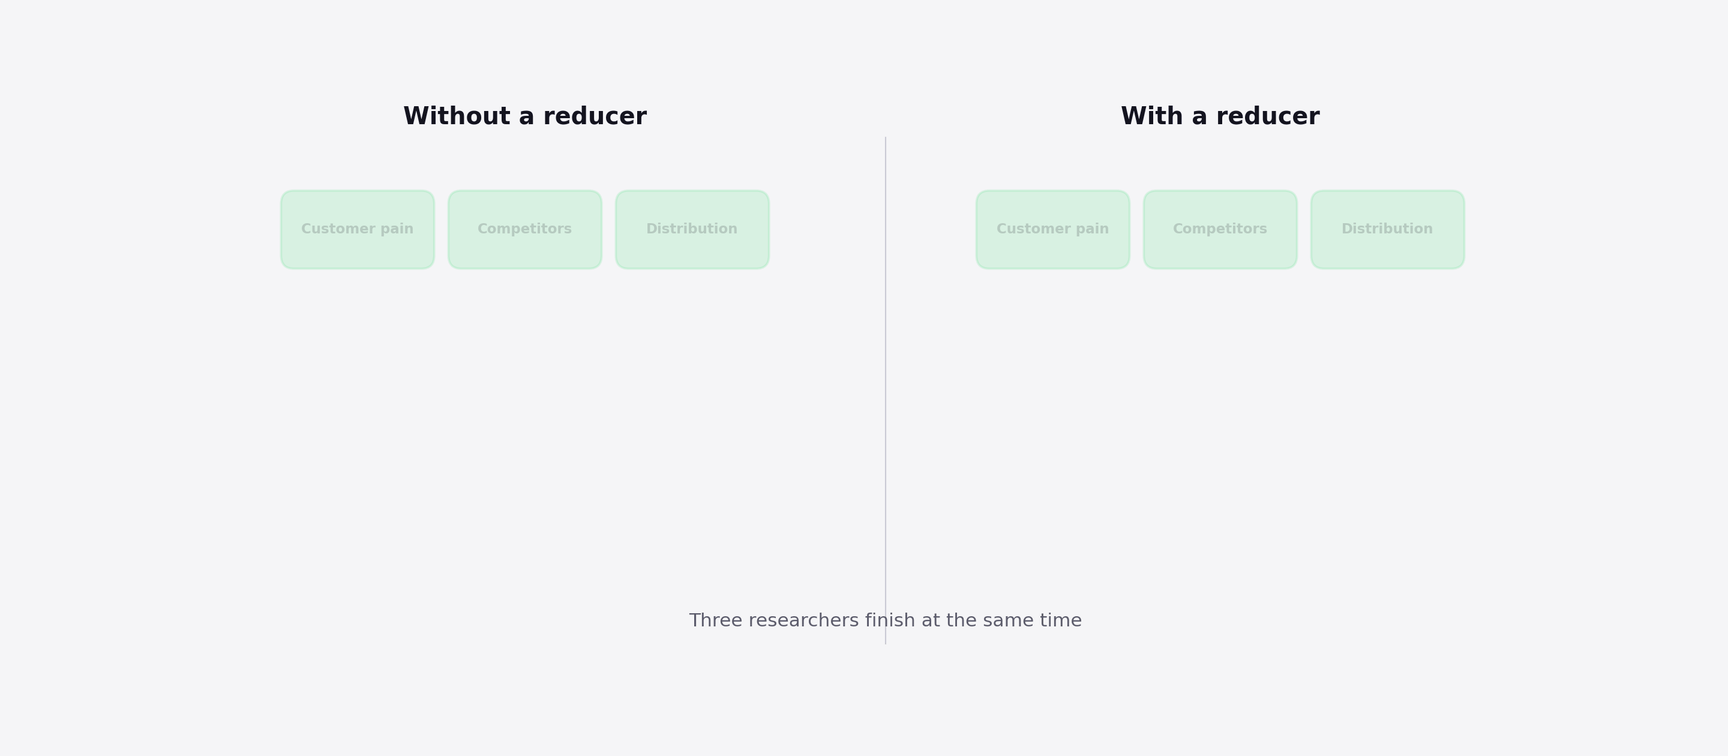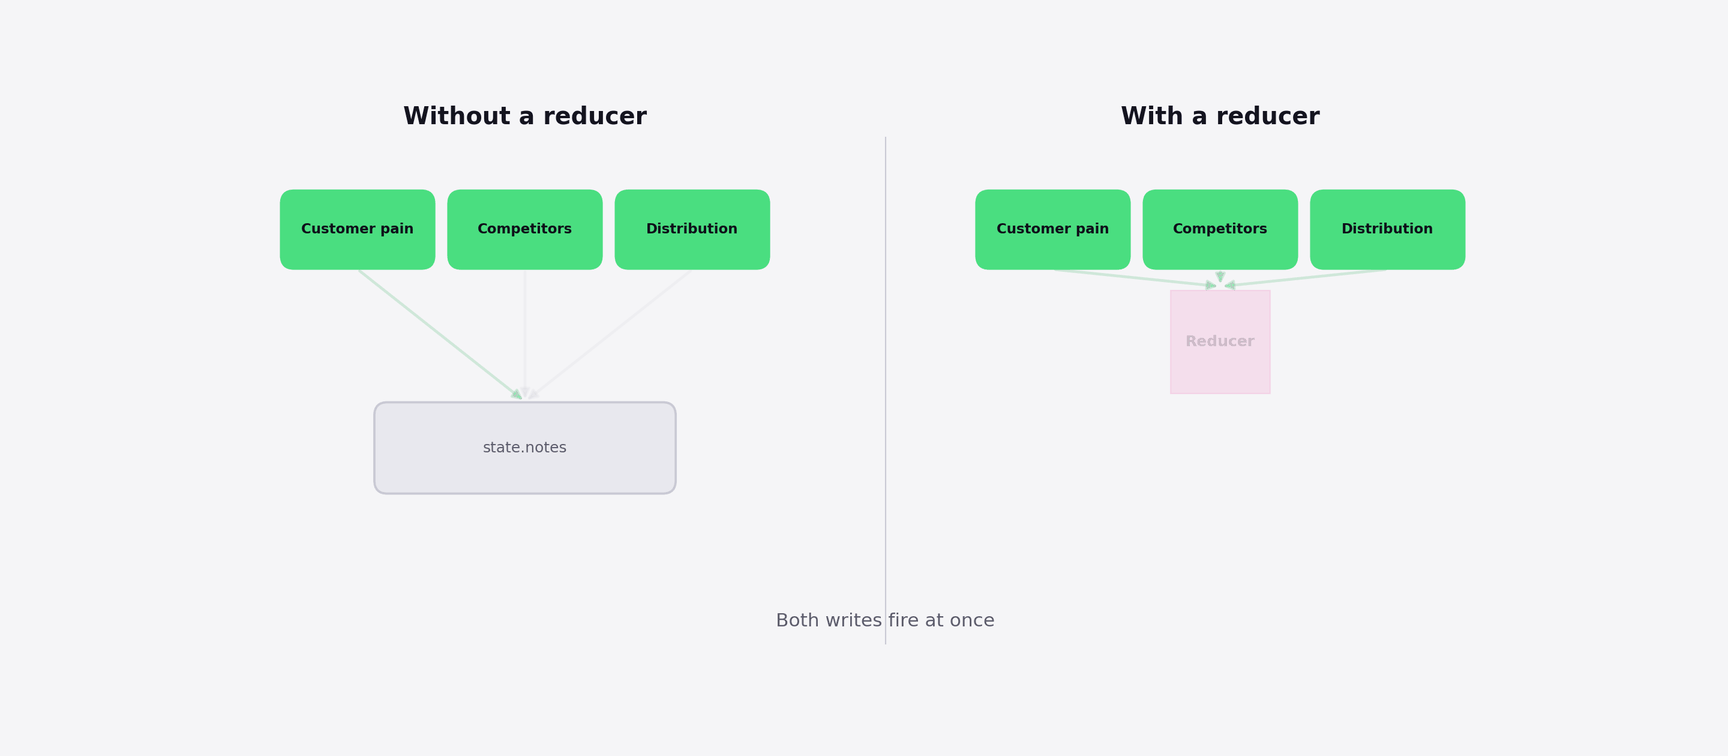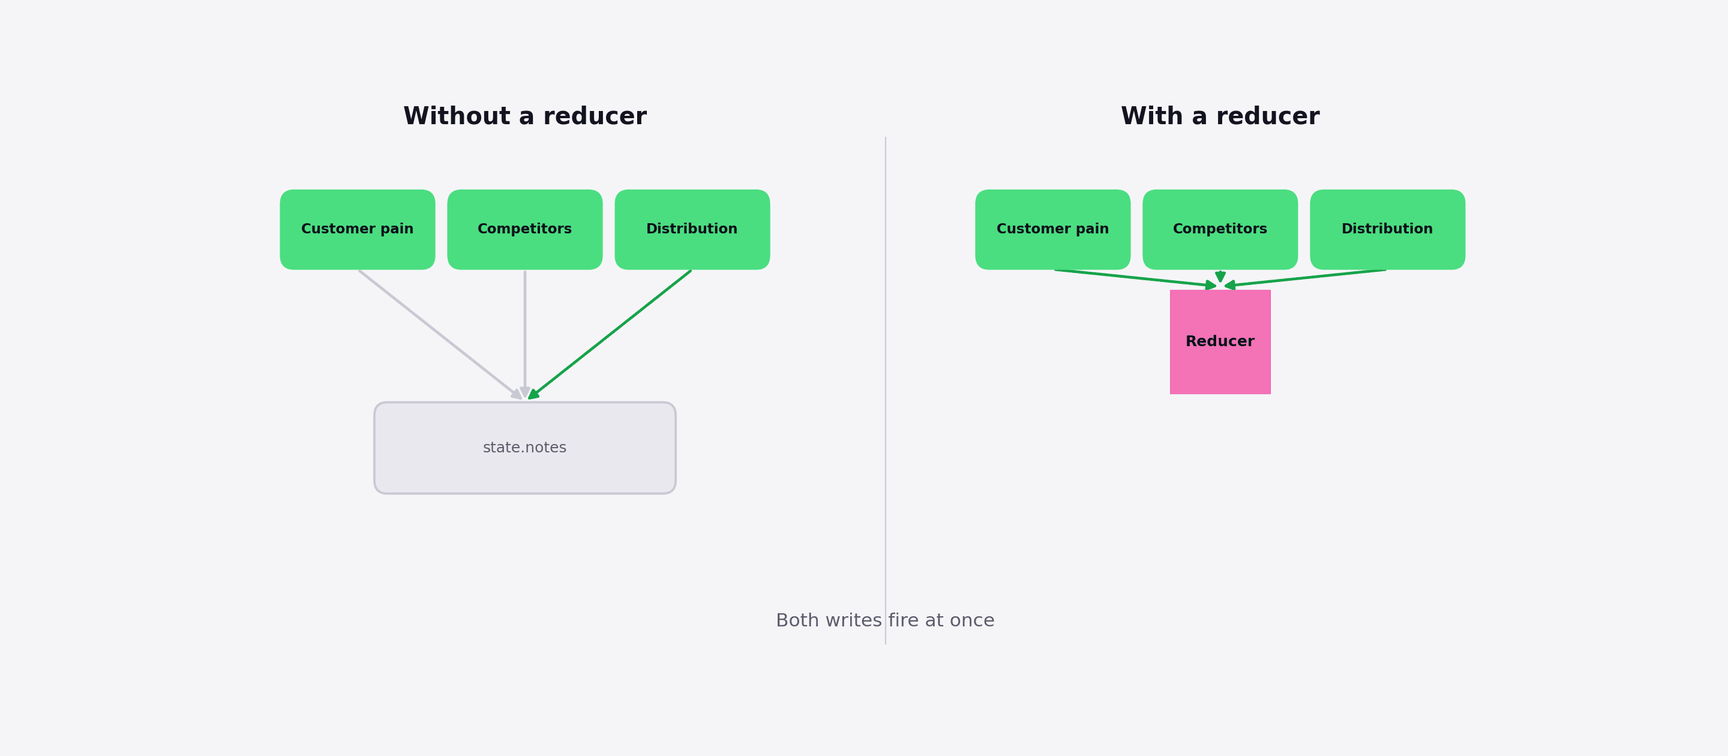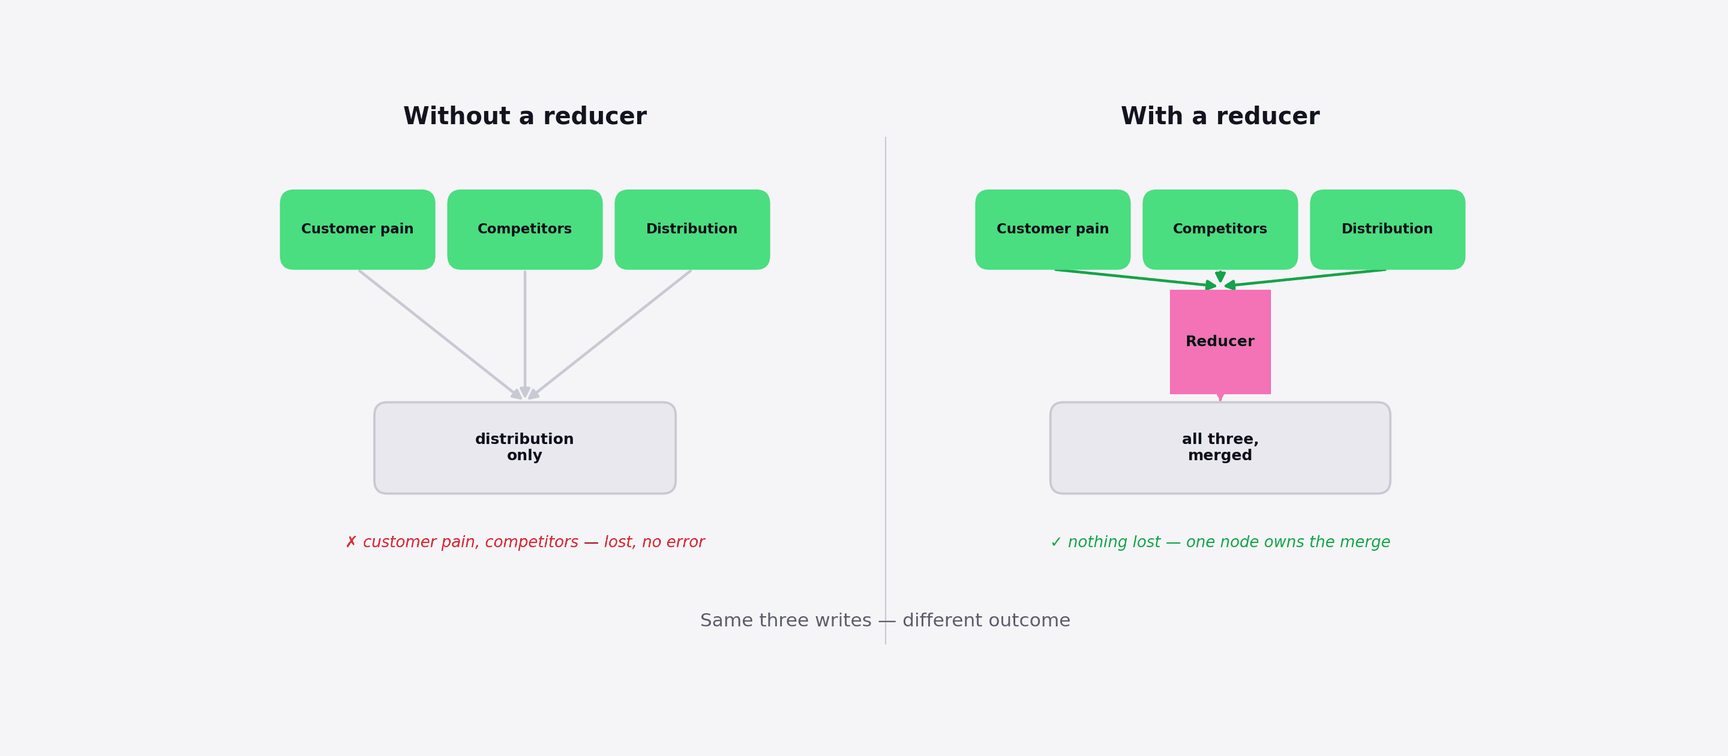
A state reducer matters when parallel branches come back together. Imagine three researchers finishing at roughly the same time and all trying to update the same research field. You don’t want whichever finishes last to silently overwrite the others. A reducer defines how those results should be combined—merging lists, combining dictionaries, or otherwise resolving conflicting updates.当并行分支重新汇合时,状态归约器就显得很重要。想象一下三个研究人员几乎同时完成工作,并都试图更新同一个研究字段。你肯定不希望最后完成的人悄悄覆盖掉其他人的结果。归约器定义了如何合并这些结果——合并列表、组合字典,或以其他方式解决冲突的更新。
A checkpoint is a snapshot of the graph’s state at a particular moment. It sounds optional until a forty-minute workflow crashes at minute forty. With checkpoints, you can resume from the last saved state instead of paying to run the entire workflow again.检查点是图在特定时刻的状态快照。这听起来是可选的,直到一个四十分钟的工作流在第四十分钟崩溃。有了检查点,你可以从上次保存的状态恢复,而无需再次付费运行整个工作流。
LangGraph also pairs checkpoints naturally with interrupts. A workflow can pause while waiting for human approval and later continue from the same state using the same thread identifier. This is what makes long-running, human-in-the-loop workflows practical rather than just possible.LangGraph 还自然地将检查点与中断配对。工作流可以在等待人工批准时暂停,稍后使用相同的线程标识符从相同的状态继续。这使得长期运行的、有人参与的工作流变得实用,而不仅仅是可能。
There is one production detail worth remembering: be careful with side effects around retries and interrupts. If a node sends an email, charges a card, or performs another external action before the workflow pauses, that action should be idempotent. Otherwise, resuming or retrying the workflow could accidentally perform it twice.有一个生产细节值得注意:在重试和中断周围处理副作用时要小心。如果一个节点在工作流暂停之前发送电子邮件、扣费或执行其他外部操作,该操作应该是幂等的。否则,恢复或重试工作流可能会意外地执行两次。
5. Two different things people call "graph"5. 人们称之为“图”的两种不同事物
The word “graph” gets used for two different ideas in AI, which is where some of the confusion around graph engineering comes from.“图”这个词在人工智能中被用于两种不同的概念,这就是围绕图工程产生一些困惑的原因。
5.1 Knowledge graph5.1 知识图谱 (Knowledge graph)
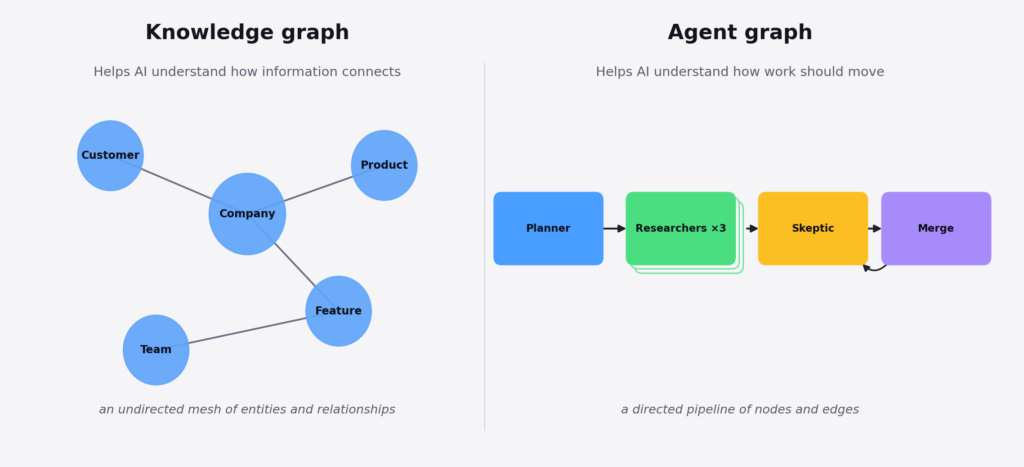
A knowledge graph is about how information connects.知识图谱是关于信息如何连接的。
For example: this customer works at this company, this company uses this product, this support issue is related to this feature, and this feature belongs to that team.例如:该客户在这家公司工作,该公司使用该产品,该支持问题与该功能相关,该功能属于那个团队。
This is the idea behind tools like Microsoft’s GraphRAG. Traditional retrieval-augmented generation (RAG) is good at finding pieces of text that are similar to a question. But it can struggle when the answer depends on connecting information spread across different documents or sources. A knowledge graph makes those relationships explicit.这就是微软 GraphRAG 等工具背后的理念。传统的检索增强生成 (RAG) 擅长查找与问题相似的文本片段。但当答案取决于连接分散在不同文档或来源中的信息时,它可能会遇到困难。知识图谱使这些关系变得明确。
In simple terms, knowledge graphs organize relationships between information.简单来说,知识图谱组织了信息之间的关系。
5.2 Agent graph5.2 代理图 (Agent graph)
An agent graph is different: how work moves through a system.代理图则不同:它是关于工作如何在系统中流转的。
In an agent graph, a planner breaks a goal into tasks. Researchers work on those tasks in parallel. A reviewer checks what they found. A synthesizer combines the useful evidence. A human approves the final result before anything happens. That’s the same structure as the Shopify example above.在代理图中,规划者将目标拆分为任务。研究人员并行处理这些任务。审阅者检查他们的发现。综合者整合有用的证据。人类在任何事情发生之前批准最终结果。这与上面的 Shopify 例子结构相同。
Everything we’ve discussed so far—nodes, edges, state, and transitions—belongs to this second category.我们目前讨论的一切——节点、边、状态和转换——都属于这第二个类别。
A simple way to remember the difference:记住这种区别的一个简单方法:
Knowledge graphs connect information. Agent graphs coordinate work.知识图谱连接信息。代理图协调工作。
However, both can be used by a system. A knowledge graph might help an agent understand how pieces of information relate, while an agent graph determines what the system should do with that information and what happens next.然而,一个系统可以同时使用两者。知识图谱可以帮助代理理解信息片段之间的关联,而代理图则决定系统应该如何处理这些信息以及下一步做什么。
For the rest of this piece, when I talk about graph engineering, I'm talking about the second one: designing the flow of work around AI agents.在本文的其余部分,当我谈到图工程时,我指的是第二种:围绕人工智能代理设计工作流。
6. Five patterns for Graph Engineering6. 图工程的五种模式
You don’t need a custom architecture for every AI workflow. Most production workflows come down to a handful of recurring patterns. Each solves a different problem, and each has its own failure mode.你不需要为每个 AI 工作流定制架构。大多数生产工作流都归结为几种反复出现的模式。每种模式解决不同的问题,并且每种都有自己的失效模式。
Here’s how five of the most useful patterns fit into the same Shopify graph.以下是五种最有用的模式如何融入同一个 Shopify 图中。
6.1 Prompt chaining6.1 提示词链 (Prompt chaining)
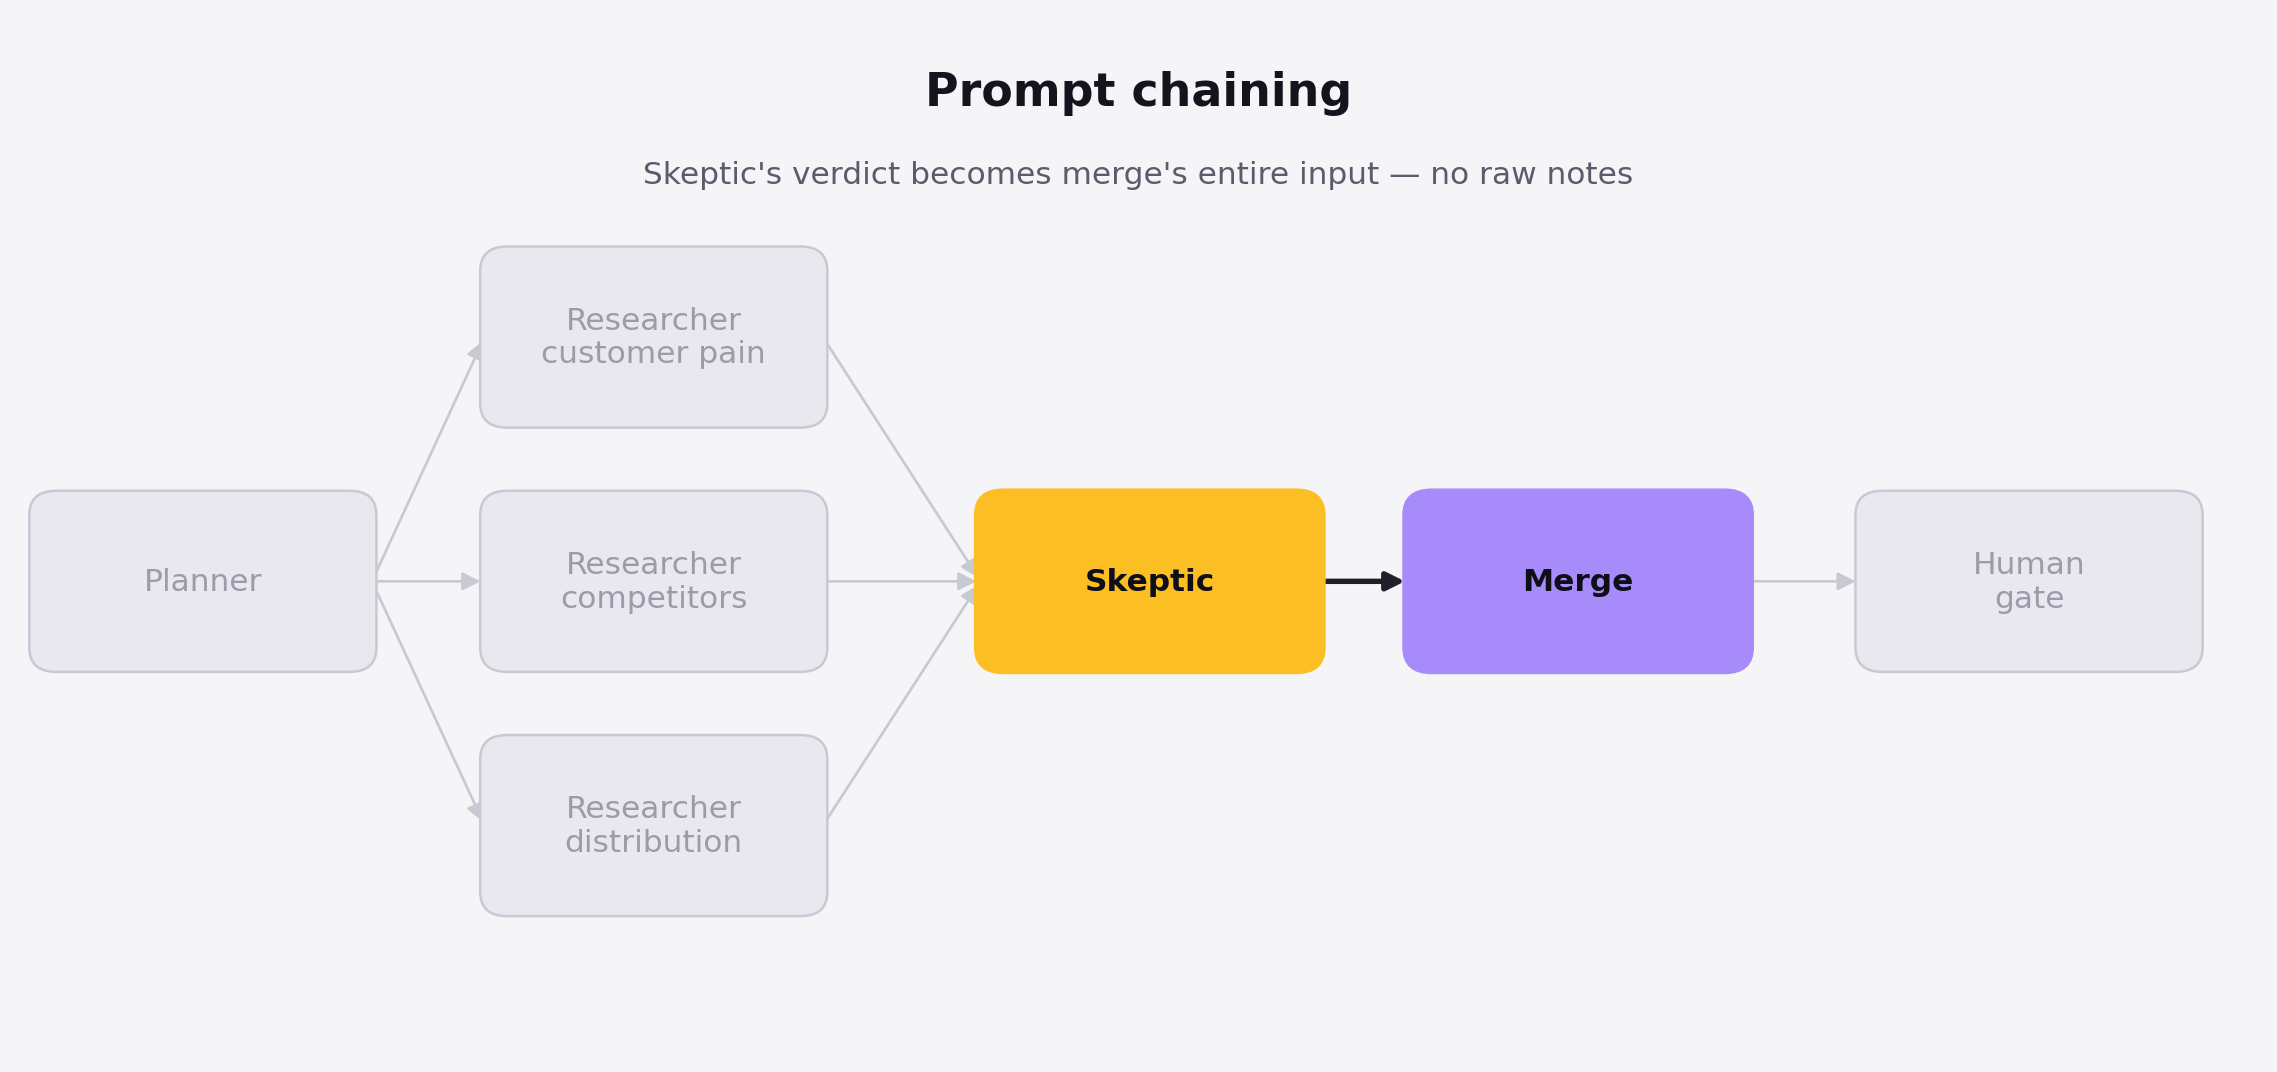
Prompt chaining means the output of one node becomes the input to the next. You can think of this as an assembly line, where each station only touches what the last one handed off, and is never given the whole car.提示词链意味着一个节点的输出成为下一个节点的输入。你可以将其想象成一条装配线,每个工位只处理上一个工位传递过来的东西,而从不接触整辆车。
In our graph, the skeptic produces a short list of which claims survived and which didn’t. That list becomes the merge node’s input. The merge node doesn’t need to see all the researchers’ raw notes: the tangents about QuickBooks integrations, half-relevant forum threads, or pricing pages that turned out not to matter.在我们的图中,怀疑者生成一份简短的清单,列出哪些主张幸存下来,哪些没有。该清单成为合并节点的输入。合并节点不需要看到研究人员所有的原始笔记:那些关于 QuickBooks 集成、半相关的论坛帖子或事实证明无关紧要的定价页面的离题内容。
That separation is important. Each node gets only the context it needs to do its job, instead of carrying the entire conversation forward.这种分离很重要。每个节点只获得完成其工作所需的上下文,而不是将整个对话向前推进。
This is one of the main reasons chaining works better than one long chat. A research step can accumulate a lot of noise, and passing all of it downstream makes the next step harder, not easier.这是链式工作比长对话效果更好的主要原因之一。研究步骤会积累大量噪音,将所有这些噪音传递到下游会使下一步工作变得更加困难,而不是更容易。
There’s also a simple test for when not to use chaining: if the next node genuinely needs everything the previous node saw, splitting them may not buy you much. You may just be adding another model call and more latency.对于何时不使用链式工作,还有一个简单的测试:如果下一个节点确实需要上一个节点看到的一切,那么拆分它们可能带不来什么好处。你可能只是在增加另一次模型调用和更多的延迟。
6.2 Routing6.2 路由 (Routing)
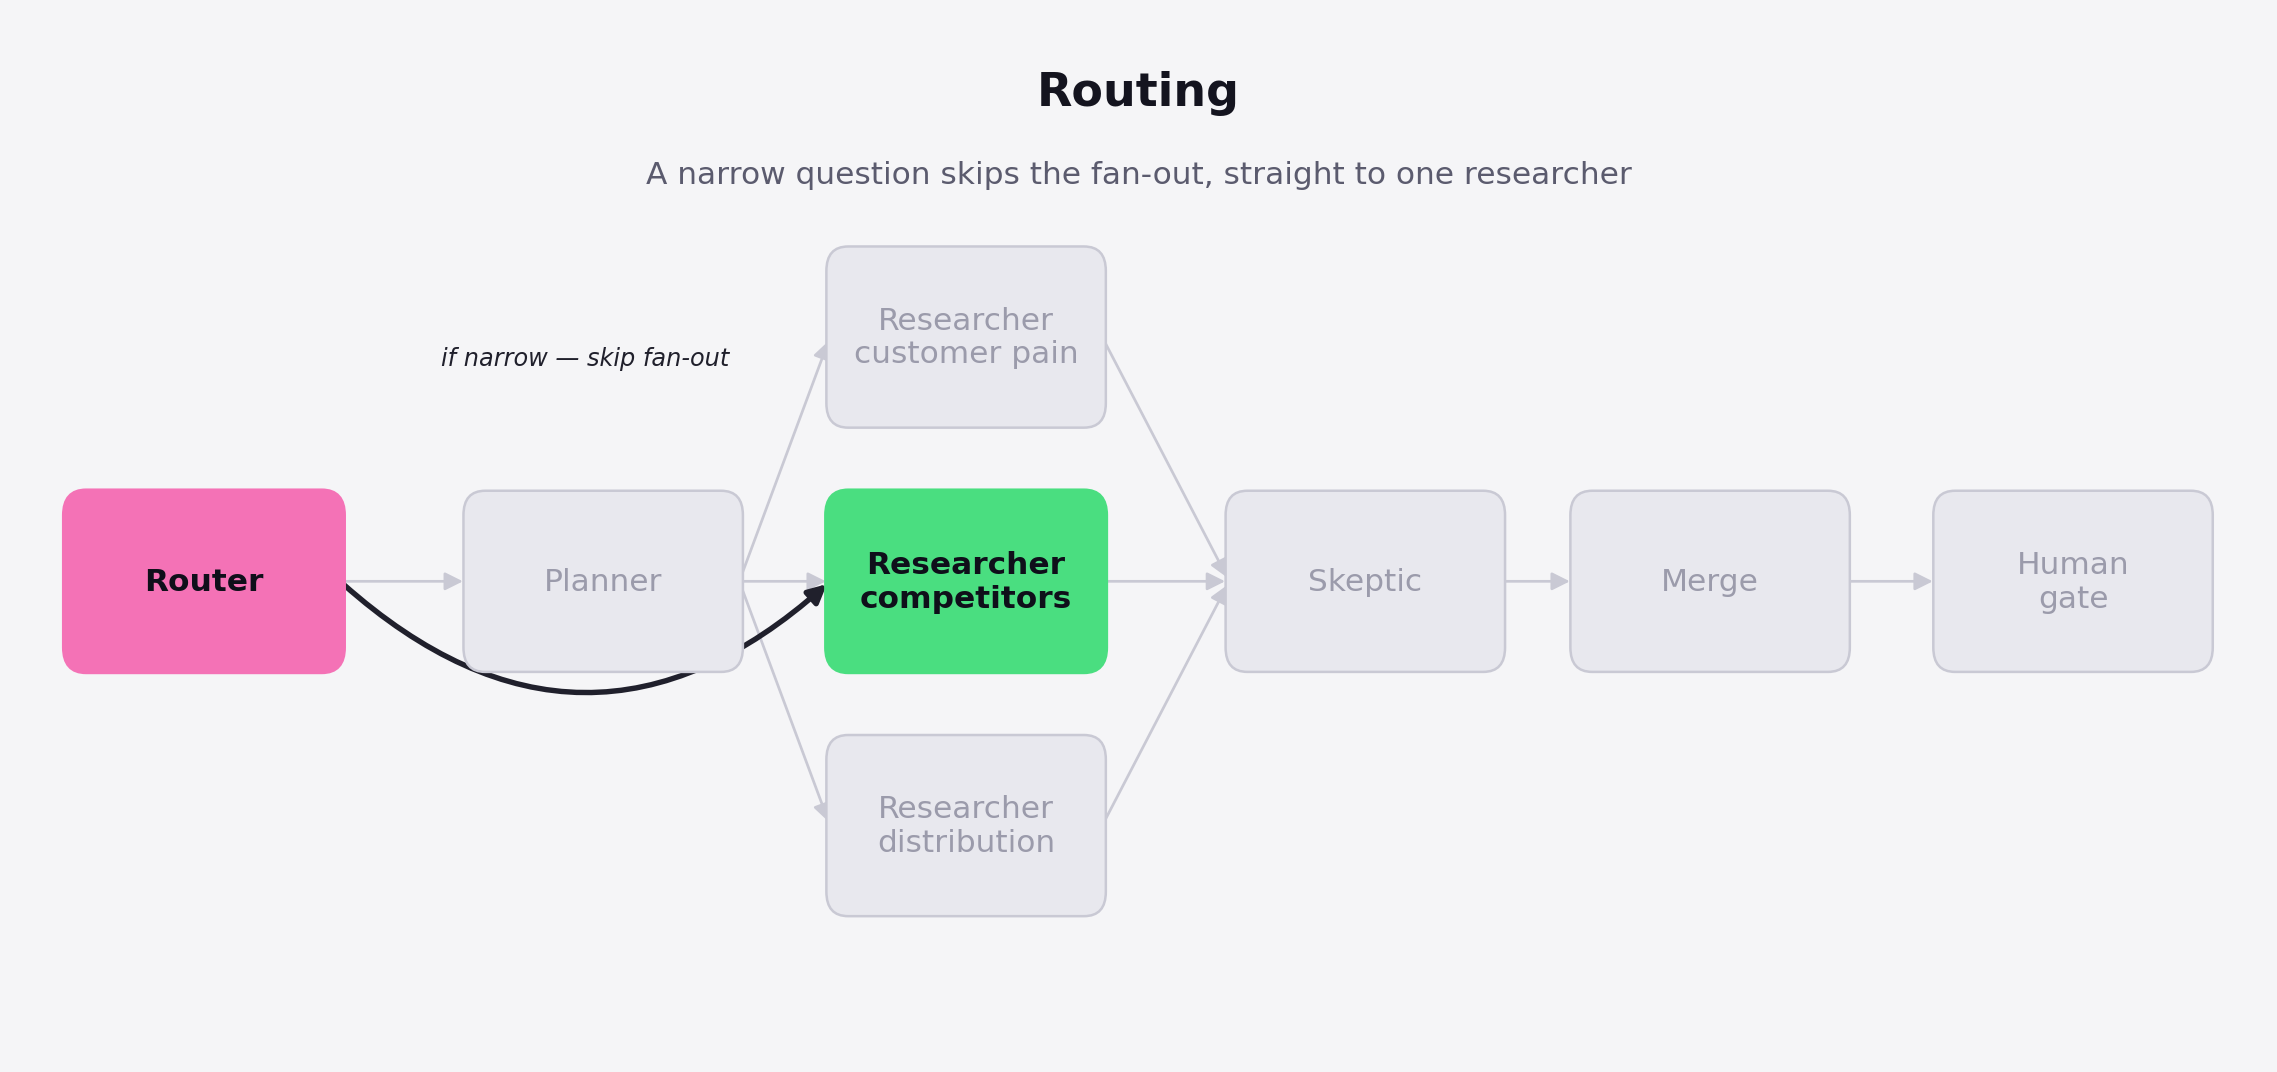
Routing decides which path an input should take. Think of it like hospital triage: assess each case once, then send it to the right specialist instead of putting every patient through every department.路由决定输入应该走哪条路径。想象一下医院的分诊:先评估每个病例,然后将其发送给合适的专家,而不是让每个病人看遍每个科室。
Suppose the founder asks a much narrower question:假设创始人问了一个范围窄得多的问题:
“Should I add invoice sync to my existing tool?”“我应该在现有工具中添加发票同步功能吗?”
That’s different from:这与以下问题不同:
“Should I build a bookkeeping product for Shopify merchants?”“我应该为 Shopify 商家构建一个记账产品吗?”
A router in front of the planner can recognize the first question as narrow and send it directly to one researcher instead of launching the full research workflow.规划者前面的路由可以将第一个问题识别为窄范围问题,并将其直接发送给一名研究人员,而不是启动完整的调研工作流。
The benefit is simple: you match the amount of work to the difficulty of the question.好处很简单:你使工作量与问题的难度相匹配。
The danger is misclassification. If the router mistakes a broad question for a narrow one, nothing necessarily breaks. The workflow can still return a polished, confident recommendation—it just happens to be based on a fraction of the research it actually needed.危险在于误分类。如果路由将一个广泛的问题误认为是窄范围问题,并不一定会导致系统崩溃。工作流仍然可以返回一份精美、自信的建议——它只是恰好基于它实际所需研究的一小部分。
That’s why routing needs guardrails. Test the router against labeled examples, and when its confidence is low, send the request down the broader path rather than the cheaper one.这就是为什么路由需要护栏。针对标记示例测试路由,当其置信度较低时,将请求发送到更广泛的路径,而不是更廉价的路径。
6.3 Parallelization6.3 并行化 (Parallelization)
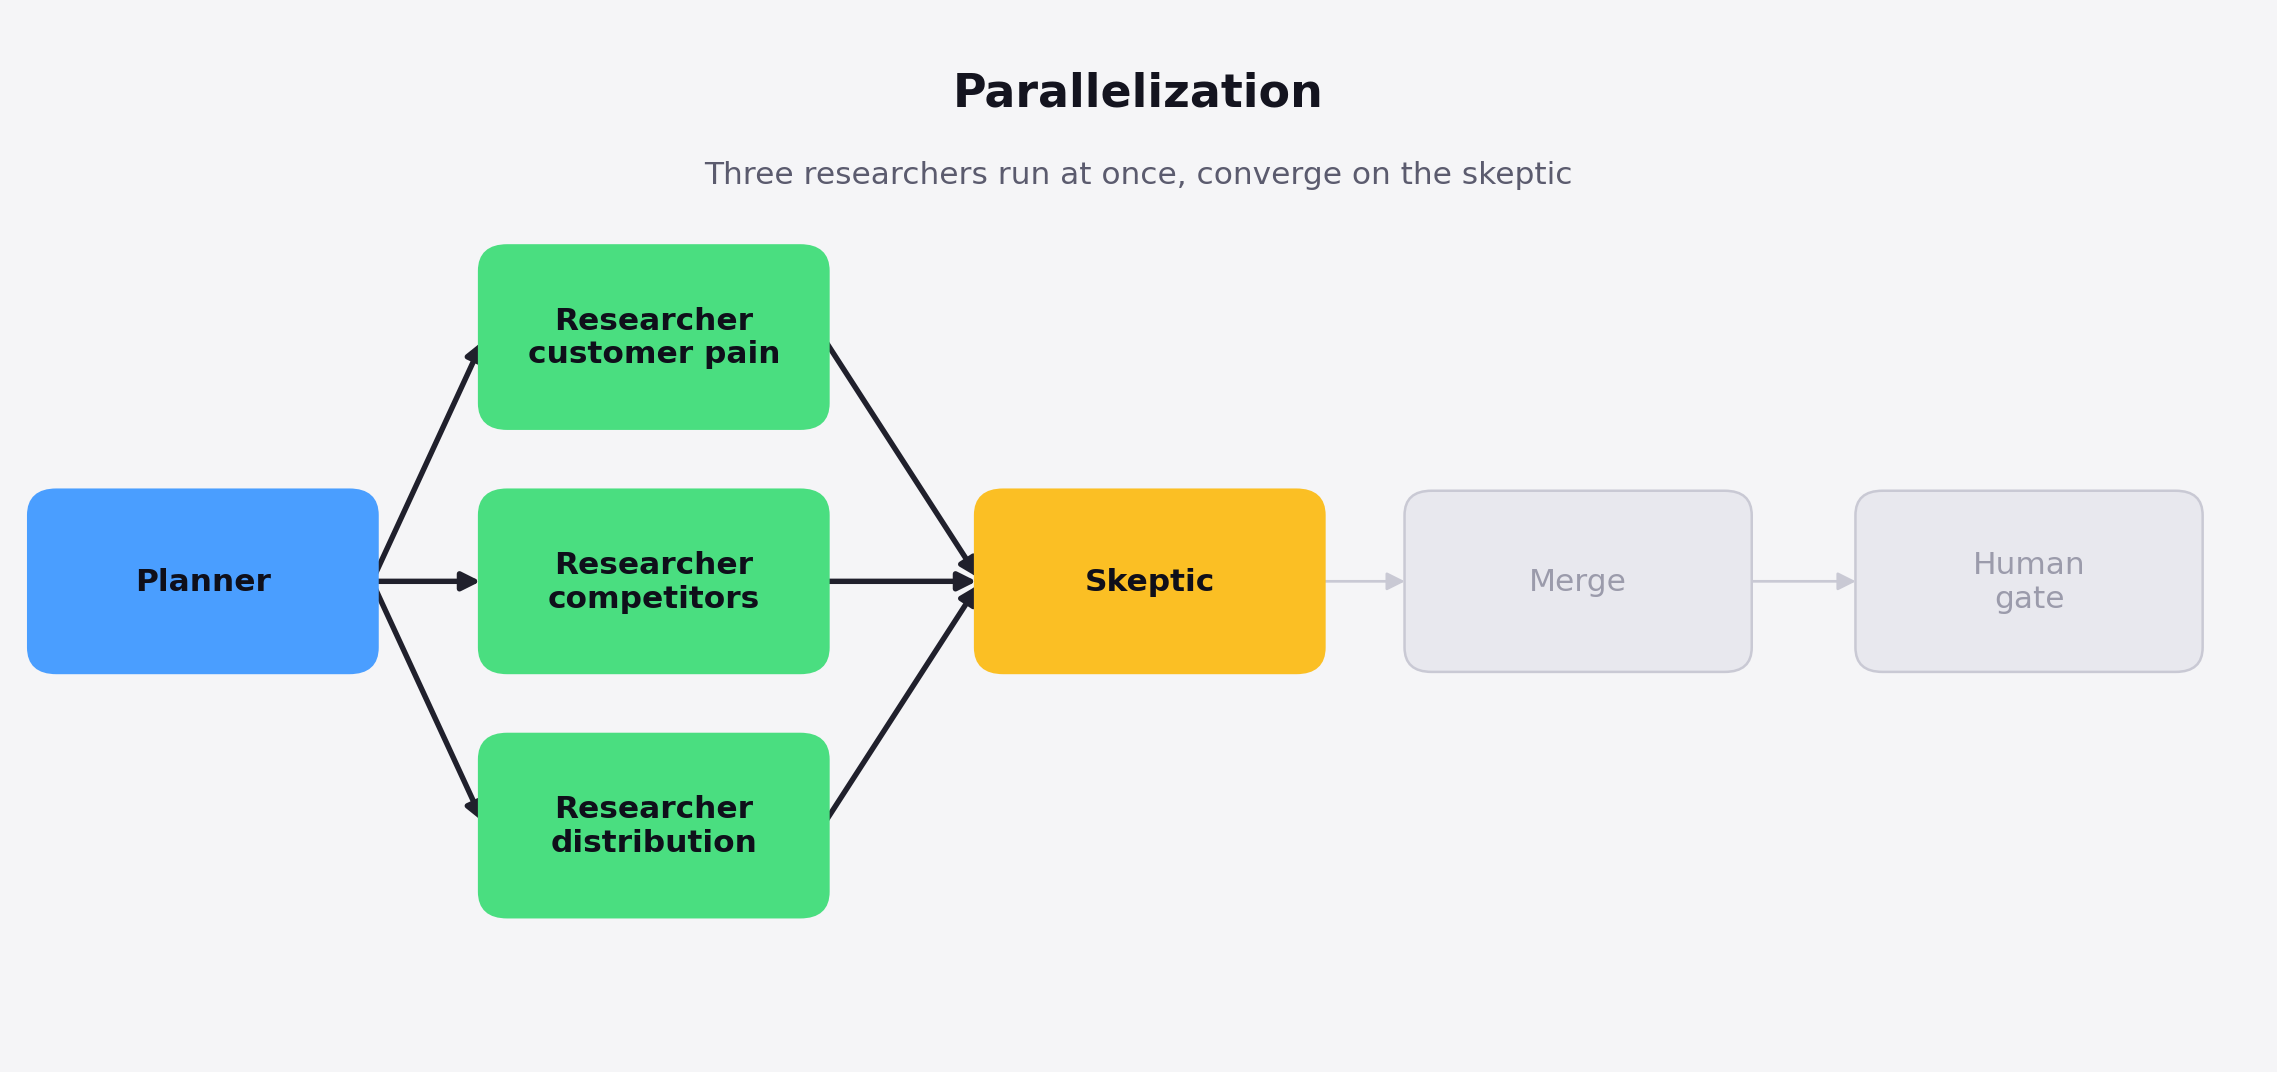
Parallelization is useful when several independent pieces of work can happen at the same time—like three analysts working toward the same deadline, each handling a separate, predefined piece of the work simultaneously.当几个独立的工作片段可以同时进行时,并行化非常有用——就像三名分析师在同一个截止日期前工作,每人同时处理工作的一个单独的、预定义的片段。
That’s already happening in our Shopify graph. Once the planner decides what needs to be researched, it can send separate questions to multiple researchers at once: one looks at competitors, another at merchant pain points, and another at pricing and willingness to pay.这已经在我们的 Shopify 图中发生了。一旦规划者决定了需要研究的内容,它就可以同时向多名研究人员发送单独的问题:一人看竞争对手,一人看商家痛点,另一人看定价和支付意愿。
Those researchers don’t depend on each other, so there’s little reason to run them one after another.这些研究人员互不依赖,因此没有理由一个接一个地运行它们。
The advantage is speed. Three independent research tasks can run simultaneously and then feed their results into the skeptic or merge step.优点是速度。三个独立的研究任务可以同时运行,然后将结果反馈给怀疑者或合并步骤。
But parallelization only works well when the branches are actually independent. If researcher B needs the result from researcher A before it can do useful work, they shouldn’t be parallel branches at all.但并行化只有在分支确实独立时才有效。如果研究员 B 在进行有用工作之前需要研究员 A 的结果,那么它们根本不应该成为并行分支。
6.4 Orchestrator-workers 6.4 编排者-工作者 (Orchestrator-workers)
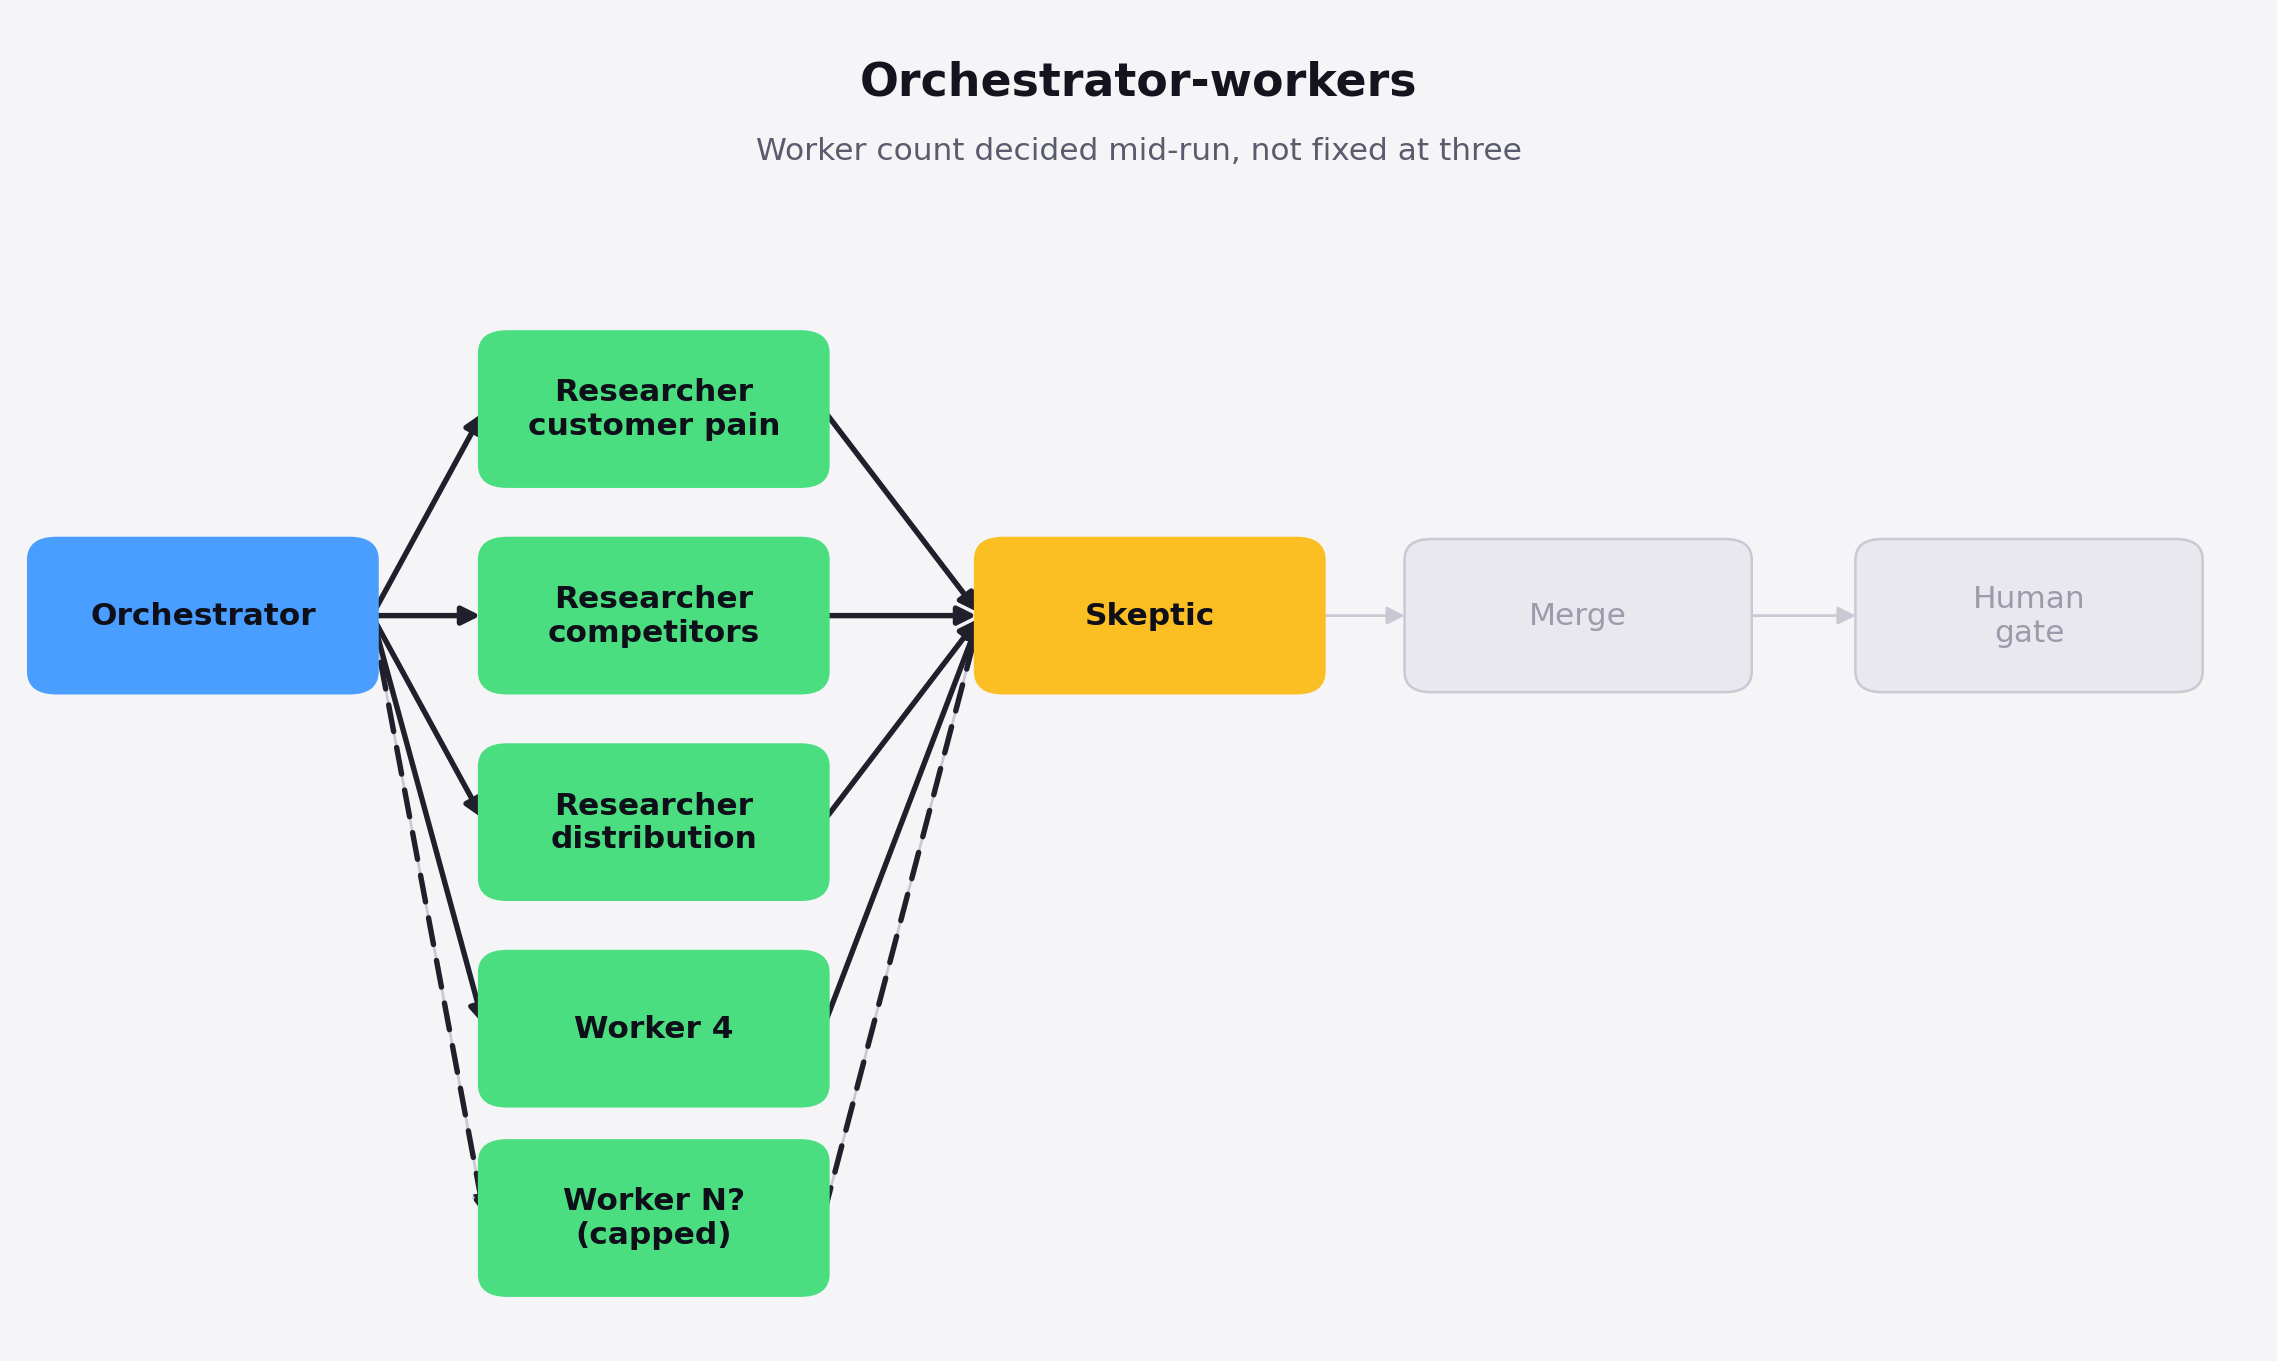
Orchestrator-workers is useful when the work needs to be divided, but the number of tasks isn’t known in advance. Imagine it like a contractor who assesses the job first, then decides how many subcontractors to assign and what each should handle, rather than starting with a fixed set of crew before seeing the work.当工作需要划分,但任务数量无法预知时,编排者-工作者模式很有用。想象一下承包商先评估工作,然后决定指派多少分包商以及每人处理什么,而不是在看到工作之前就先安排好固定的团队。
Suppose the founder now wants the Shopify idea checked against every adjacent alternative: competing apps, agencies, freelance bookkeepers, Upwork services, spreadsheet templates, and anything else merchants are already using. You may not know how many categories matter until the workflow starts researching.假设创始人现在想针对每一个相邻的替代方案检查 Shopify 的想法:竞争应用、代理机构、自由职业记账员、Upwork 服务、电子表格模板以及商家已经在使用的任何其他东西。在工作流开始研究之前,你可能不知道有多少类别是重要的。
An orchestrator changes this by discovering by itself those categories first, then creates a worker for each relevant one.编排者通过自行发现这些类别,然后为每个相关类别创建一个工作者来改变这一点。
That’s the key difference from normal parallelization. With parallelization, you already know you want three researchers. With orchestrator-workers, the workflow decides how many workers it needs while it’s running.这是与普通并行化的关键区别。通过并行化,你已经知道你需要三名研究人员。通过编排者-工作者,工作流在运行时决定它需要多少工作者。
However, that flexibility comes with a very practical risk. If the orchestrator discovers forty categories and launches forty model or API calls at once, you can quickly hit rate limits or blow through your budget. So put limits in place before execution: cap the number of workers, the total spend, or both.然而,这种灵活性带来了一个非常实际的风险。如果编排者发现了四十个类别并同时启动四十个模型或 API 调用,你可能会迅速达到速率限制或耗尽预算。因此,在执行前设置限制:限制工作者数量、总支出或两者兼而有之。
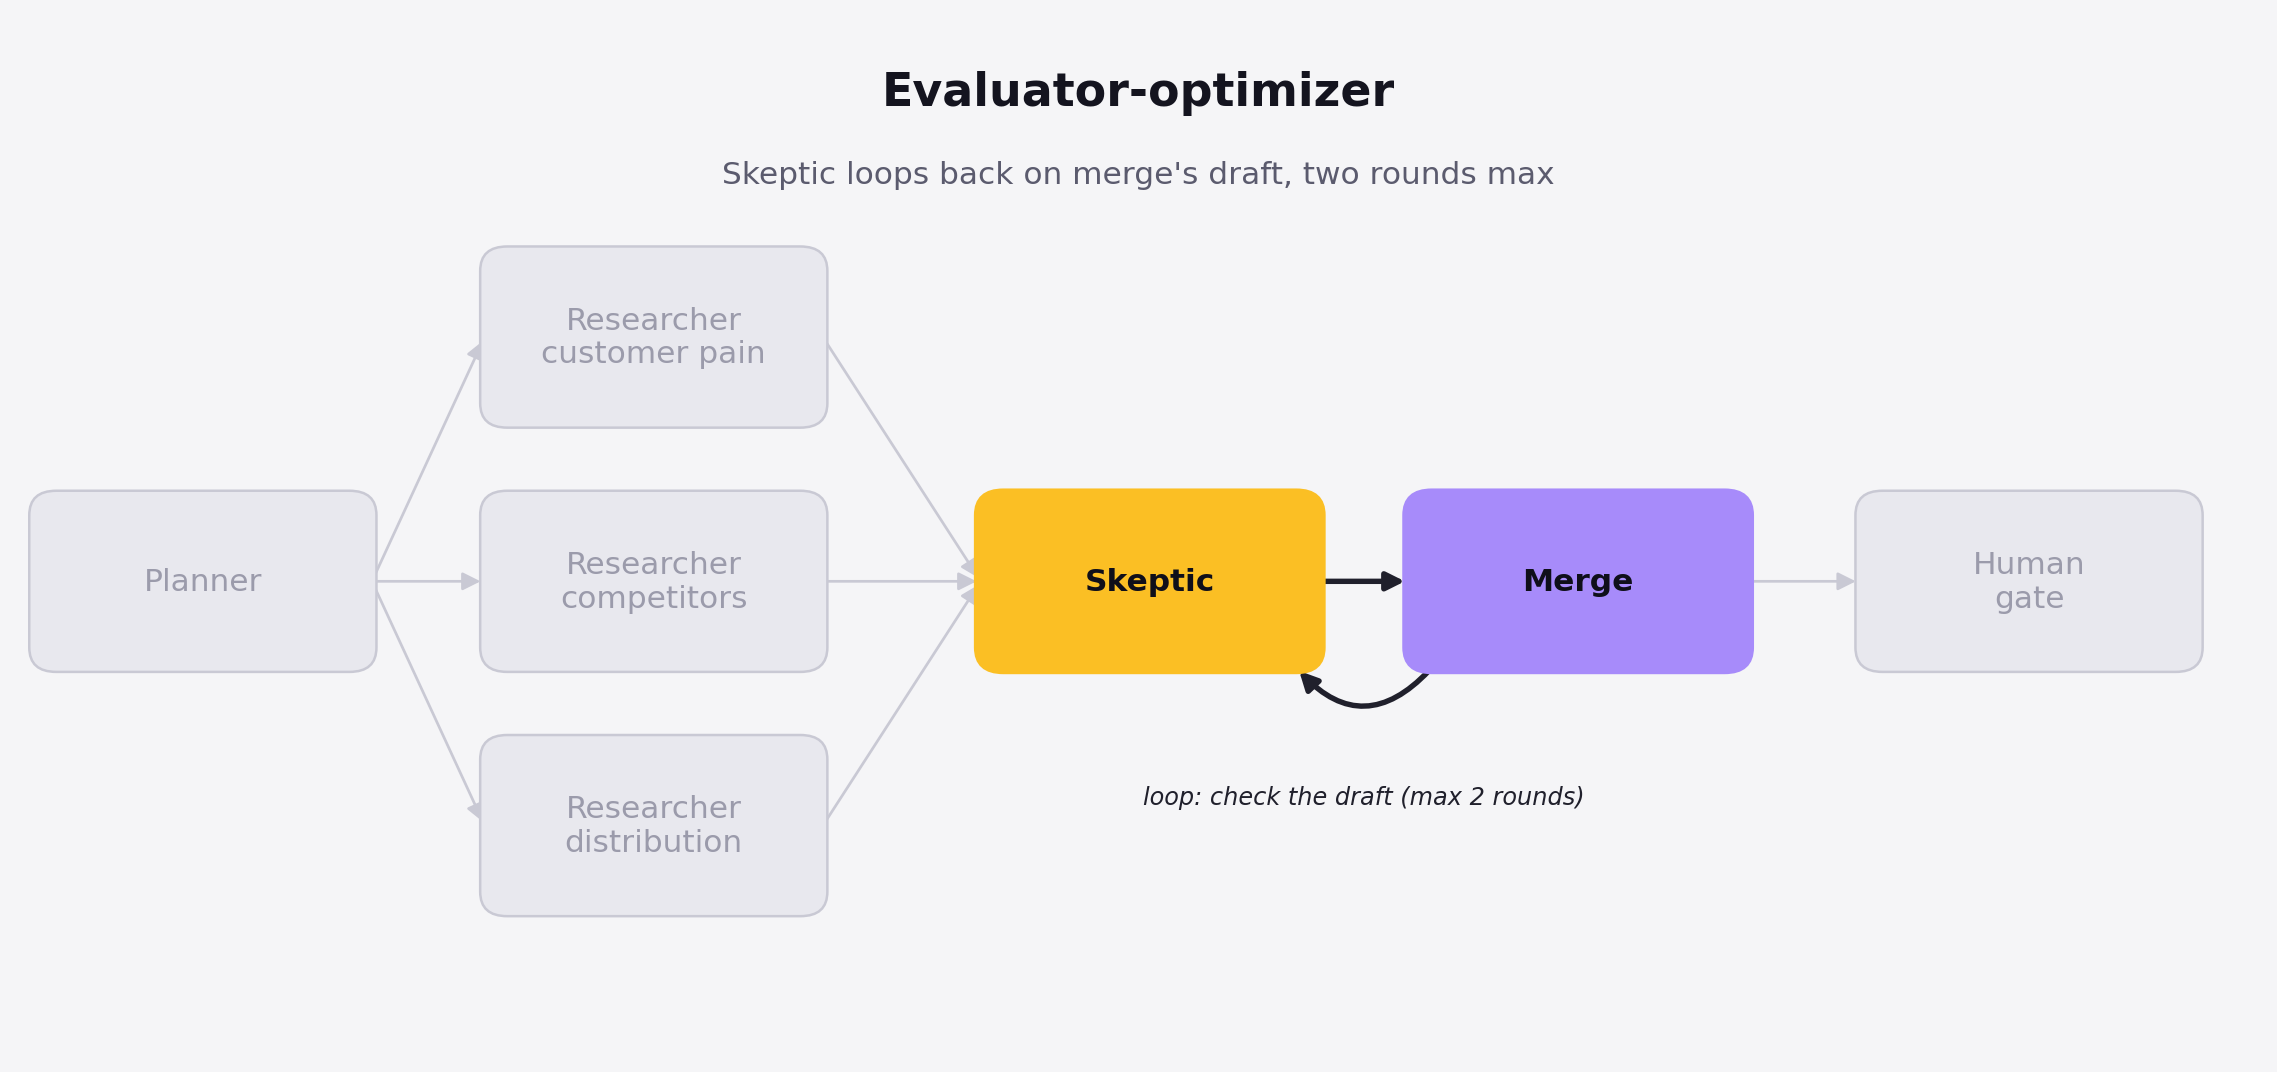
6.5 Evaluator-optimizer6.5 评估者-优化者 (Evaluator-optimizer)
Evaluator-optimizer adds a feedback loop: one step produces an answer, another evaluates it, and the first step gets a chance to improve it. It works like an editor returning a draft to the writer with specific notes, then reviewing the revision before it ships instead of publishing the first pass.评估者-优化者增加了一个反馈循环:一个步骤产生答案,另一个步骤进行评估,第一个步骤有机会对其进行改进。它的工作方式就像编辑将草稿退回给作者并附上具体注释,然后在发布前审查修订版,而不是直接发布第一稿。
Imagine the merge node produces its first recommendation and includes this claim:想象一下合并节点产生了它的第一个建议,并包含了这个主张:
“Shopify merchants will pay $50 per month.”“Shopify 商家每月将支付 50 美元。”
The skeptic checks the draft and realizes none of the research actually supports that number. Instead of letting the recommendation continue to the human gate, it sends the draft back with a specific instruction: support the $50 claim with evidence or remove it. And the merge node gets another attempt.怀疑者检查草稿,发现没有任何研究真正支持这个数字。它没有让建议继续流向人工门控,而是将草稿退回并附上一条具体指令:用证据支持 50 美元的主张或将其删除。于是合并节点得到了再次尝试的机会。
But how does the checker know when to stop? That’s where stopping rules come in. You can cap the loop at a fixed number of rounds or stop once a specific criterion is met. In this graph, we might allow two rounds of evaluation and revision, then stop regardless of the outcome.但检查者怎么知道何时停止?这就是停止规则的用武之地。你可以将循环限制在固定的轮数内,或者在满足特定标准后停止。在此图中,我们可能允许两轮评估和修订,然后无论结果如何都停止。
The bigger problem, though, is a loop that keeps running without actually improving the result. If the second draft contains the same unsupported claim with slightly different wording, another round probably won’t help.然而,更大的问题是循环在没有真正改进结果的情况下不断运行。如果第二稿包含相同的、缺乏支持的主张,只是措辞略有不同,那么再来一轮可能也无济于事。
That isn’t iteration. It’s repetition.那不是迭代。那是重复。
A good evaluator-optimizer loop therefore needs two things: a maximum number of rounds and a way to detect when the output has stopped meaningfully improving.因此,一个好的评估者-优化者循环需要两样东西:最大轮数,以及一种检测输出何时停止有意义改进的方法。
7. Prove the shape before you automate it7. 在自动化之前验证形状
Once this clicks, the instinct is to reach for LangGraph, AutoGen, or n8n. Don’t. The structure matters more than the tooling, and you can test it in twenty minutes and a blank page.一旦理解了这一点,人们的直觉就是去寻找 LangGraph、AutoGen 或 n8n。不要这样做。结构比工具更重要,你可以在二十分钟内用一张空白纸测试它。
I'm using the Shopify question and do the following first:我正在使用 Shopify 问题,并首先执行以下操作:
Define the output in one sentence. Not “help me research this,” but “a one-page recommendation on whether this idea is worth testing”. If you can’t define the output clearly, the workflow isn’t ready to become a graph.用一句话定义输出。不是“帮我研究这个”,而是“关于这个想法是否值得测试的一页建议”。如果你不能清楚地定义输出,工作流就不准备好成为一个图。
List the jobs a competent human would do. For the Shopify example: clarify the question, research customer pain, research competitors, research distribution, check the evidence, and write the recommendation. Five to seven jobs is usually enough. If you have twenty, you probably haven’t found the real structure yet.列出有能力的专业人士会做的工作。对于 Shopify 的例子:澄清问题、研究客户痛点、研究竞争对手、研究分销、检查证据并撰写建议。五到七项工作通常就足够了。如果你有二十项,你可能还没有找到真正的结构。
Draw dependencies, not sequences. If two jobs don’t need each other’s output, put them side by side. Customer and competitor research can run in parallel. The skeptic waits for the research. The final writer waits for the skeptic.绘制依赖关系,而不是序列。如果两项工作不需要彼此的输出,将它们并排摆放。客户和竞争对手研究可以并行运行。怀疑者等待研究结果。最终撰写者等待怀疑者的结论。
Add one human gate where a mistake matters. A private research memo might only need a quick review. A customer email, refund, or public post should stop for approval right before the action.增加一个错误后果严重的人工门控。私人研究备忘录可能只需要快速审查。客户电子邮件、退款或公开帖子应该在行动前停下来等待批准。
Run the graph manually. Play every role yourself, one prompt at a time, with a fresh chat for each node. Pass each output into the next node that needs it. It’s deliberately slower than one long chat: you’re testing whether the structure improves the result before automating anything.手动运行图。你自己扮演每一个角色,一次一个提示词,每个节点使用一个新的聊天窗口。将每个输出传递给下一个需要它的节点。这比一次长对话要慢,这是故意的:你在自动化任何事情之前,正在测试结构是否改善了结果。
If it isn’t visibly better than a one-shot answer, don’t automate it. A faster average process is still average.如果它没有明显优于一次性回答,就不要自动化它。更快的平均过程仍然是平均水平。
After three good manual runs, move one step up: have the planner write plan.md, each researcher write its own file, the skeptic write review.md, and the final step write recommendation.md. You now have a simple paper trail without adding much complexity.经过三次良好的手动运行后,向上迈进一步:让规划者编写 plan.md,每位研究人员编写自己的文件,怀疑者编写 review.md,最后一步编写 recommendation.md。你现在拥有了一个简单的纸质记录,而没有增加太多的复杂性。
Only then reach for a framework.只有到那时才去寻找框架。
Tool | Best for | Needs | Watch out |
|---|---|---|---|
LangGraph | Checkpoints, persistence, human-in-the-loop approvals built in | Python or JS, a checkpointer backend | More infrastructure to run, and version churn to track |
AutoGen's GraphFlow | Branching and conditional logic across steps | Python, AutoGen AgentChat | API surface still evolving fast |
n8n / Make.com | Graphs that need to touch Slack, email, or a CRM directly | No-code setup, connector accounts | Less control over the agent's internal reasoning |
8. Conclusion8. 结论
More agents don’t automatically make a better system. Sometimes they just give you five confident agents arriving at the same wrong answer while the coordination overhead grows faster than the quality of the thinking.更多的代理并不会自动产生更好的系统。有时它们只会让你得到五个自信的代理得出了同一个错误的结论,而协调开销的增长速度超过了思维质量的提升。
The goal isn’t to build the biggest graph you can draw. It’s to build the smallest one that does 4 things well: cuts real latency, keeps the checker separate from the doer, puts a human in the loop where mistakes actually carry a cost, and knows when to stop.目标不是构建你能画出的最大的图。而是构建最小的、能很好地完成 4 件事的图:减少实际延迟、保持检查者与执行者分离、在错误代价高昂的地方加入人工环节,以及知道何时停止。
The Shopify question you started with—or whatever problem you’ve substituted for it—probably already has this structure hiding inside it. Right now, you’re just asking one model to play every role at once. Make those roles explicit. Remove dependencies that don’t need to exist. Run independent work in parallel. Then put yourself back into the workflow at the points where judgment, accountability, or an irreversible decision actually belongs to you.你开始时提出的 Shopify 问题——或者你替换它的任何问题——可能已经隐藏了这种结构。现在,你只是要求一个模型同时扮演所有角色。明确这些角色。移除不需要存在的依赖关系。并行运行独立工作。然后,在你真正需要判断力、问责制或不可逆决策的地方,将你自己放回工作流中。
This week, do three things in this order:本周,按此顺序做三件事:
Write the one-sentence output your workflow is supposed to produce.写下你的工作流应该产生的一句话输出。
List the five to seven jobs a competent human would need to do to produce it.列出有能力的专业人士为产生该输出需要做的五到七项工作。
Run the workflow manually once—one prompt per node, with a fresh chat for each—before automating anything.在自动化任何事情之前,手动运行一次工作流——每个节点一个提示词,每个节点使用一个新的聊天窗口。
That manual run is your test. If it doesn’t beat your usual one-shot answer, you don’t have an automation problem yet. You have a workflow-design problem. Fix the shape before you fix the tooling.那次手动运行就是你的测试。如果它没有打败你通常的一次性回答,你还没有自动化问题。你有一个工作流设计问题。在修复工具之前,先修复形状。
You don’t need GraphRAG or GQL on day one, either. The underlying ecosystem will keep improving while you experiment: graph-based retrieval is getting more efficient, and GQL has now joined SQL as an ISO-standard database query language. That’s not a reason to wait for the tooling to mature.你第一天也不需要 GraphRAG 或 GQL。在你实验的同时,底层生态系统会不断改进:基于图的检索正变得越来越高效,而 GQL 也已加入 SQL 的行列,成为 ISO 标准数据库查询语言。这不是等待工具成熟的理由。
It’s a reason to start with the simplest version now.这是现在就开始使用最简单版本的理由。
Sketch the graph. Run it by hand. Keep what earns its place.画出图。手动运行它。保留那些物有所值的部分。
9. Resources9. 资源
Peter Steinberger — the original X post that started the discourse this piece opens with.彼得·斯坦伯格 (Peter Steinberger) —— 本文开篇所探讨的话题源头的原始 X 推文。
Hamel Husain — "Loop Engineering Is Dead. Enter Graph Engineering", the X Article responding to it.哈梅尔·侯赛因 (Hamel Husain) —— 《循环工程已死,图工程时代来临》,对此回应的 X 文章。
Anthropic — "Building Effective Agents", source of the five-pattern taxonomy (prompt chaining, routing, parallelization, orchestrator-workers, evaluator-optimizer) used throughout this piece.Anthropic —— 《构建有效的代理》,本文通篇使用的五种模式分类法(提示词链、路由、并行化、编排者-工作者、评估者-优化者)的来源。
LangGraph — Persistence documentation, covering checkpoints, threads, and interrupts.LangGraph —— 持久化文档,涵盖检查点、线程和中断。
Microsoft Research — "GraphRAG: Improving global search via dynamic community selection", source of the ~77% average token-cost figure.微软研究院 —— 《GraphRAG:通过动态社区选择改进全局搜索》,约 77% 平均 Token 成本数字的来源。
AutoGen — GraphFlow documentation, for branching and conditional logic across steps.AutoGen —— GraphFlow 文档,用于跨步骤的分支和条件逻辑。
The Register — "GQL becomes first new ISO standard database language since SQL" (April 2024).The Register —— 《GQL 成为自 SQL 以来首个新的 ISO 标准数据库语言》(2024 年 4 月)。
n8n and Make.com — the workflow-automation tools referenced for graphs that need to touch Slack, email, or a CRM.n8n 和 Make.com —— 文中提到的用于需要连接 Slack、电子邮件或 CRM 的图的工作流自动化工具。
Kh4ng — "Graph Engineering: Kiến trúc đồ thị cho hệ thống AI Agent thế hệ mới", a background technical write-up this piece drew on.Kh4ng —— 《图工程:新一代 AI 代理系统的图架构》,本文借鉴的技术背景文章。
Greg Eisenberg, Startup Ideas podcast — background episode explaining graph engineering (source URL not on hand — add it if available).Greg Eisenberg, Startup Ideas 播客 —— 解释图工程的背景剧集(源 URL 手头没有——如果有请添加)。