In 17 years of building enterprise data platforms, I’ve watched every organization eventually ask the same question: “Can I ask one question and get one answer across everything my company knows?” A finance analyst wants actual revenue from the warehouse, pipeline data from the CRM, commentary from planning documents, and market signals from external providers. The information already exists, but it lives across systems that were never designed to reason together.在构建企业数据平台的17年里,我观察到每个组织最终都会提出同一个问题:“我能否问一个问题,并从公司掌握的所有信息中得到一个答案?”财务分析师想要从数据仓库中获取实际收入,从客户关系管理系统(CRM)中获取渠道数据,从规划文档中获取评论,并从外部提供商处获取市场信号。这些信息已经存在,但它们分散在从未被设计为协同推理的各个系统中。
For decades we tried to solve this by consolidating data. We built larger warehouses, semantic layers, APIs, and dashboards. Each solved part of the problem, but none solved the fundamental one: orchestrating reasoning across heterogeneous sources in response to an arbitrary business question. Earlier systems supported limited federation and semantic querying, yet they struggled to reason across those sources at enterprise scale without significant custom engineering.几十年来,我们试图通过整合数据来解决这个问题。我们构建了更大的仓库、语义层、API和仪表板。每一个都解决了部分问题,但没有一个能解决根本问题:即为了响应任意业务问题,在异构数据源之间编排推理。早期的系统支持有限的联邦和语义查询,但在没有大量定制工程的情况下,它们很难在企业规模上跨这些源进行推理。
Modern LLMs change this. Instead of replacing databases, they facilitate a new architectural primitive: an intelligent orchestration layer that dynamically reasons across specialized systems. Rather than consolidating the data into a single store, this layer consolidates the access pattern to data that stays where it lives.现代大语言模型(LLM)改变了这一点。它们不是取代数据库,而是促进了一种新的架构原语:一个能够跨专业系统进行动态推理的智能编排层。该层不是将数据整合到一个单一存储中,而是整合了对保留在原地的数据的访问模式。
This article presents a reference architecture for LLM-powered enterprise analytics agents that coordinate purpose-built, heterogeneous data stores through intelligent orchestration while preserving security, performance, and auditability.本文提出了一种用于大语言模型驱动的企业分析代理的参考架构,该架构通过智能编排协调专用、异构的数据存储,同时保持安全性、性能和可审计性。
What specifically changed with GenAI生成式人工智能(GenAI)具体带来了哪些改变
BI tools have always been constrained to predefined reports and dashboards. Before GenAI, building a cross-system query engine meant hardcoding every possible query pattern, data source combination, and synthesis path. And because the number of possible questions grows exponentially with the number of data sources, exhaustive coverage is impossible through traditional engineering. GenAI changes this in three specific ways.商业智能(BI)工具一直局限于预定义的报告和仪表板。在生成式人工智能出现之前,构建跨系统查询引擎意味着必须对每一个可能的查询模式、数据源组合和综合路径进行硬编码。由于可能的问题数量随着数据源数量的增加呈指数级增长,通过传统工程手段实现全面覆盖是不可能的。生成式人工智能在三个具体方面改变了这一点。
Intent understanding replaces query templates: An LLM parses natural language and determines which data sources are relevant based on semantic understanding rather than keyword matching. Unlike a keyword search, an LLM understands that “Why did retention drop in Asia last quarter?” and “What is driving churn in Asian markets?” are the same question expressed differently. More importantly, it infers that answering the question requires customer relationship data, revenue metrics, and possibly support ticket sentiment, even though none of those systems are named.意图理解取代了查询模板:大语言模型解析自然语言,并基于语义理解而非关键词匹配来确定哪些数据源是相关的。与关键词搜索不同,大语言模型能够理解“为什么上季度亚洲地区的留存率下降了?”和“是什么导致了亚洲市场的流失?”是同一个问题的不同表达方式。更重要的是,它能推断出回答这个问题需要客户关系数据、收入指标以及可能的支持工单情绪,即使这些系统并未被明确提及。
Dynamic query decomposition replaces static pipelines: A question like “What are the biggest risk factors in our supply chain?” might require relationship data from a graph database, metrics from a key-value store, contract details from a document repository, and market intelligence from an API. The agent decomposes it into specialized subqueries on the fly, each optimized for the target store’s access pattern. There’s no prebuilt pipeline and no engineering ticket to wire up a new combination, because the decomposition happens at inference time. The system handles novel questions without code changes.动态查询分解取代了静态流水线:像“我们供应链中最大的风险因素是什么?”这样的问题,可能需要来自图数据库的关系数据、键值存储中的指标、文档库中的合同详情以及来自API的市场情报。代理在运行时将其分解为专门的子查询,每个子查询都针对目标存储的访问模式进行了优化。没有预构建的流水线,也没有用于连接新组合的工程工单,因为分解是在推理时发生的。系统无需更改代码即可处理新颖的问题。
Semantic synthesis replaces manual consolidation: Before GenAI, making sense of the data together was the real work. An analyst would pull numbers from the warehouse, check relationships in a CRM, read through documents, and mentally synthesize an answer. That took hours or days and was bounded by one person’s ability to hold context. I’ve watched senior analysts spend entire Mondays answering a single leadership question. An LLM reasons about how metrics relate to the relationship patterns in a knowledge graph and the strategic context in unstructured documents, and it does so in seconds with full source attribution. A dashboard shows numbers; an analytics agent explains what those numbers mean in the context of everything else it knows.语义综合取代了手动整合:在生成式人工智能出现之前,将数据结合起来进行理解是真正的工作所在。分析师会从仓库中提取数字,检查CRM中的关系,阅读文档,并在脑海中综合出一个答案。这需要数小时甚至数天的时间,并且受到个人保持上下文能力的限制。我曾见过高级分析师花掉整个周一的时间来回答领导层的一个问题。大语言模型能够推理指标如何与知识图谱中的关系模式以及非结构化文档中的战略背景相关联,并且能在几秒钟内完成,并提供完整的来源归因。仪表板显示数字;而分析代理则解释这些数字在它所知的一切背景下意味着什么。
The architecture: Consolidate the access pattern, not the data架构:整合访问模式,而非数据
Rather than consolidating the data into a single store, consolidate the access pattern through an intelligent orchestration layer. If your instinct is to get everything into one place, you aren’t alone, but every time we did that we lost something. Graph relationships flattened into join tables, hierarchical documents shredded into rows, and real-time signals turned stale in batch loads. The warehouse was always a compromise.与其将数据整合到一个单一存储中,不如通过智能编排层整合访问模式。如果你的直觉是将所有东西放在一个地方,你并不孤单,但每次我们这样做时,我们都会有所损失。图关系被扁平化为连接表,分层文档被粉碎成行,实时信号在批量加载中变得陈旧。仓库始终是一种妥协。
The better approach is to keep each data store optimized for its specific query pattern:更好的方法是保持每个数据存储针对其特定的查询模式进行优化:
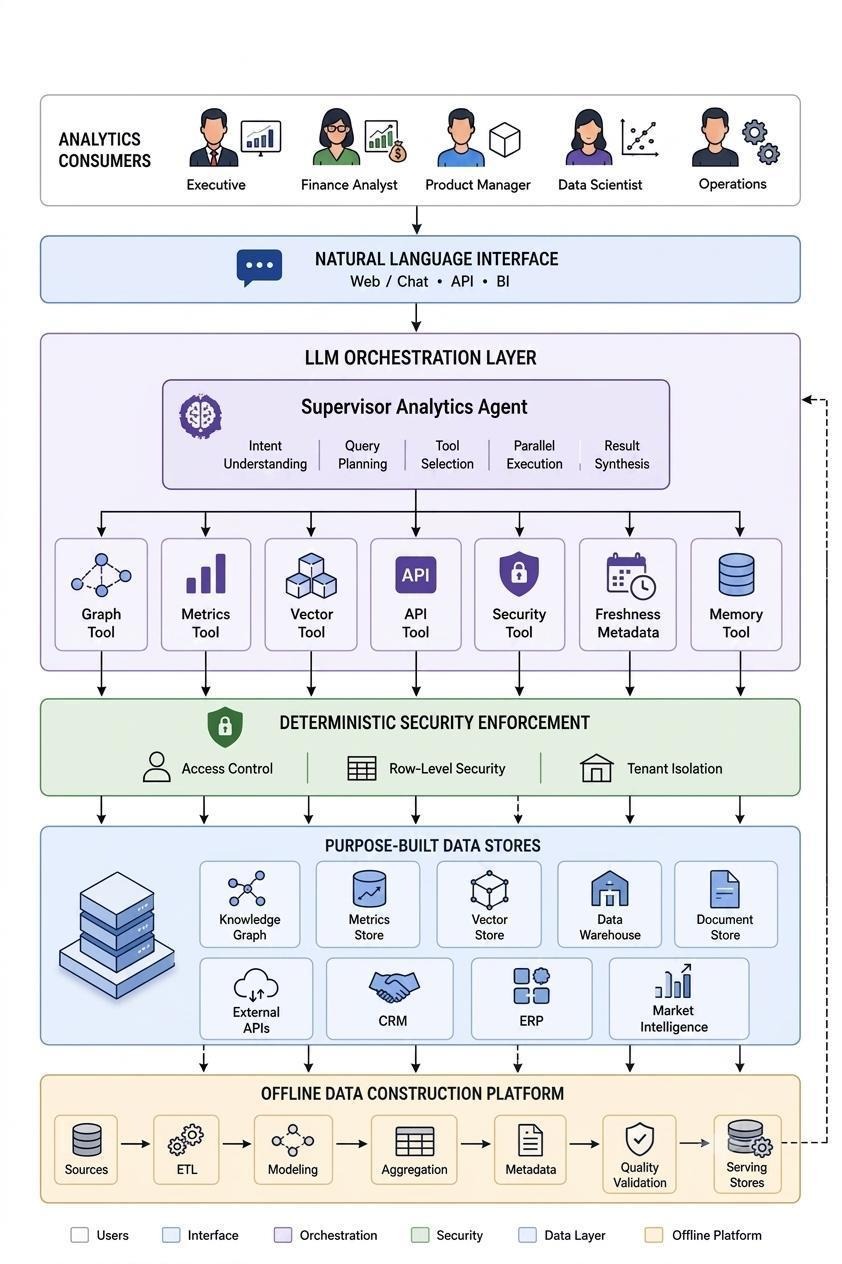
- Graph database for relationship traversal and multihop reasoning用于关系遍历和多跳推理的图数据库
- Key-value store for instant metric lookups with sub-millisecond latency用于亚毫秒级延迟的即时指标查找的键值存储
- Vector store for semantic document search and similarity matching用于语义文档搜索和相似度匹配的向量存储
- External APIs for market intelligence and real-time signals用于市场情报和实时信号的外部API
- Data Warehouse for large-scale historical aggregation and ad hoc SQL用于大规模历史聚合和即席SQL的数据仓库
The LLM-powered agent coordinates across all of them through a unified orchestration layer. This follows the same principle that makes microservices work: specialized services with well-defined interfaces, coordinated by an orchestrator. The difference is that the orchestrator now understands natural language, reasons about which services to call based on intent rather than explicit routing rules, and synthesizes results semantically rather than through programmatic joins. Think of it as a data mesh for inference, where each node keeps its operational independence while an intelligent layer federates queries across them.大语言模型驱动的代理通过统一的编排层协调所有这些存储。这遵循了使微服务发挥作用的相同原则:具有定义明确接口的专用服务,由编排器进行协调。不同之处在于,编排器现在理解自然语言,基于意图而非显式路由规则推理调用哪些服务,并以语义方式而非通过程序化连接来综合结果。可以将其视为一种用于推理的数据网格,其中每个节点保持其操作独立性,而智能层则跨节点联合查询。
The orchestration protocol编排协议
The agent follows a multiphase protocol for every query. The full reasoning loop with security enforcement and parallel execution goes well beyond a simple RAG pattern.代理对每个查询遵循多阶段协议。带有安全执行和并行执行的完整推理循环远超简单的RAG(检索增强生成)模式。
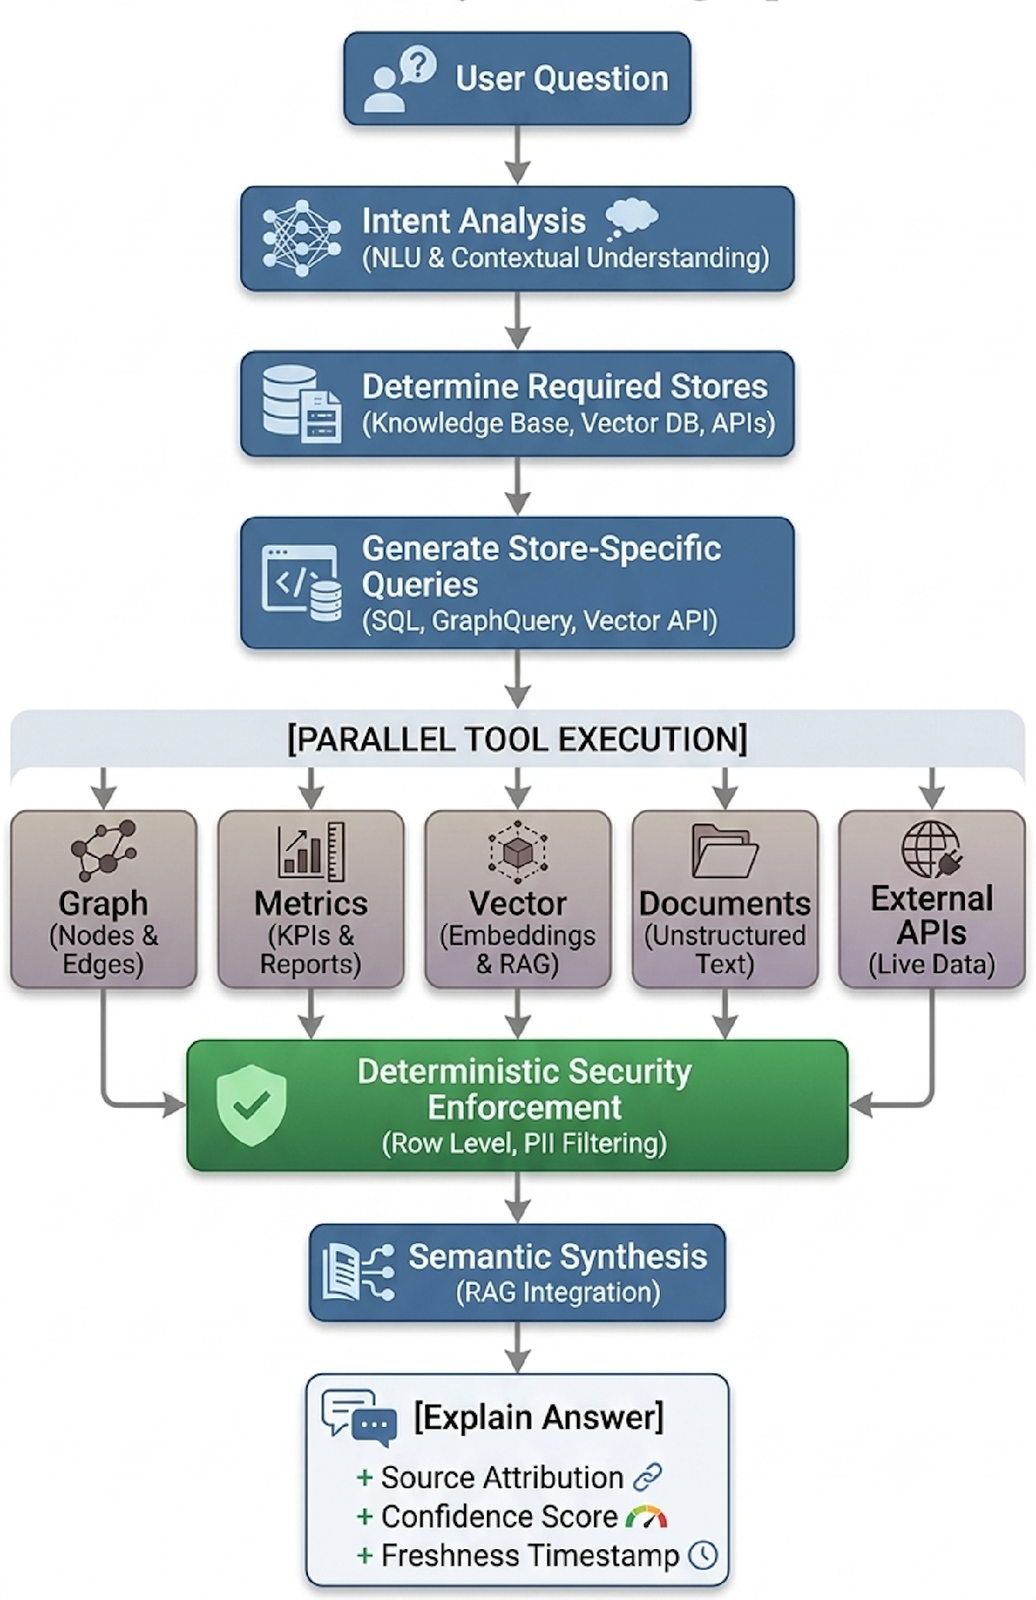
Let’s trace a business question through each phase:让我们追踪一个业务问题经过每个阶段的过程:
“Why did Q2 revenue fall short of forecast in the enterprise segment?”“为什么第二季度企业部门的收入未达到预测?”
This question requires revenue metrics (metrics store), account relationships and sales coverage (graph), deal commentary and executive notes (vector store), and market benchmarks (external APIs). No single system holds the answer.这个问题需要收入指标(指标存储)、客户关系和销售覆盖范围(图数据库)、交易评论和高管笔记(向量存储)以及市场基准(外部API)。没有任何单一系统能给出答案。
Phase 1: Intent analysis. The LLM determines what the user is asking and which data sources are relevant.第一阶段:意图分析。大语言模型确定用户在问什么,以及哪些数据源是相关的。
“Why did Q2 revenue fall short of forecast in the enterprise segment?”
↓
Intent: Revenue variance root cause analysis
Entities: Enterprise segment
Timeframe: Q2
Metric: Revenue vs. forecast
Required stores: Metrics + Graph + Vector + External API“为什么第二季度企业部门的收入未达到预测?” ↓ 意图:收入差异根本原因分析 实体:企业部门 时间范围:第二季度 指标:收入与预测对比 所需存储:指标 + 图数据库 + 向量存储 + 外部API
Not every query needs every store. “What is our current ARR?” might need to hit the metrics store only. This revenue variance question requires all four.并非每个查询都需要每个存储。比如“我们目前的年度经常性收入(ARR)是多少?”可能只需要访问指标存储。而这个收入差异问题则需要全部四个。
Phase 2: Query decomposition. The original question is broken into specialized subqueries optimized for each target store:第二阶段:查询分解。原始问题被分解为针对每个目标存储优化的专门子查询:
- Metrics store: “Q2 revenue actuals vs. forecast for enterprise, by region and product line”指标存储:“企业部门第二季度收入实际值与预测值对比,按区域和产品线划分”
- Graph store: “Enterprise accounts with closed-lost or slipped deals in Q2; common patterns in sales coverage, partner relationships, deal stage progression”图存储:“第二季度关闭失败或推迟的企业账户;销售覆盖、合作伙伴关系、交易阶段进展中的常见模式”
- Vector store: “Deal notes, QBR summaries, and executive correspondence referencing enterprise deal delays or losses in Q2”向量存储:“提及第二季度企业交易延迟或损失的交易笔记、季度业务回顾(QBR)摘要和高管通信”
- External API: “Industry benchmark data for enterprise software spending in Q2”外部API:“第二季度企业软件支出的行业基准数据”
Each is tailored to the target system’s access pattern, not forced through a common query language.每一个都针对目标系统的访问模式进行了定制,而不是通过通用的查询语言强行处理。
Phase 3: Parallel execution. Tools execute concurrently. This is critical for latency. Sequential execution across four stores would blow past any reasonable response time. With parallel execution, the total data retrieval time equals the slowest individual store, not the sum of all stores.第三阶段:并行执行。工具并发执行。这对延迟至关重要。跨四个存储的顺序执行将远远超过任何合理的响应时间。通过并行执行,总数据检索时间等于最慢的单个存储的时间,而不是所有存储时间之和。
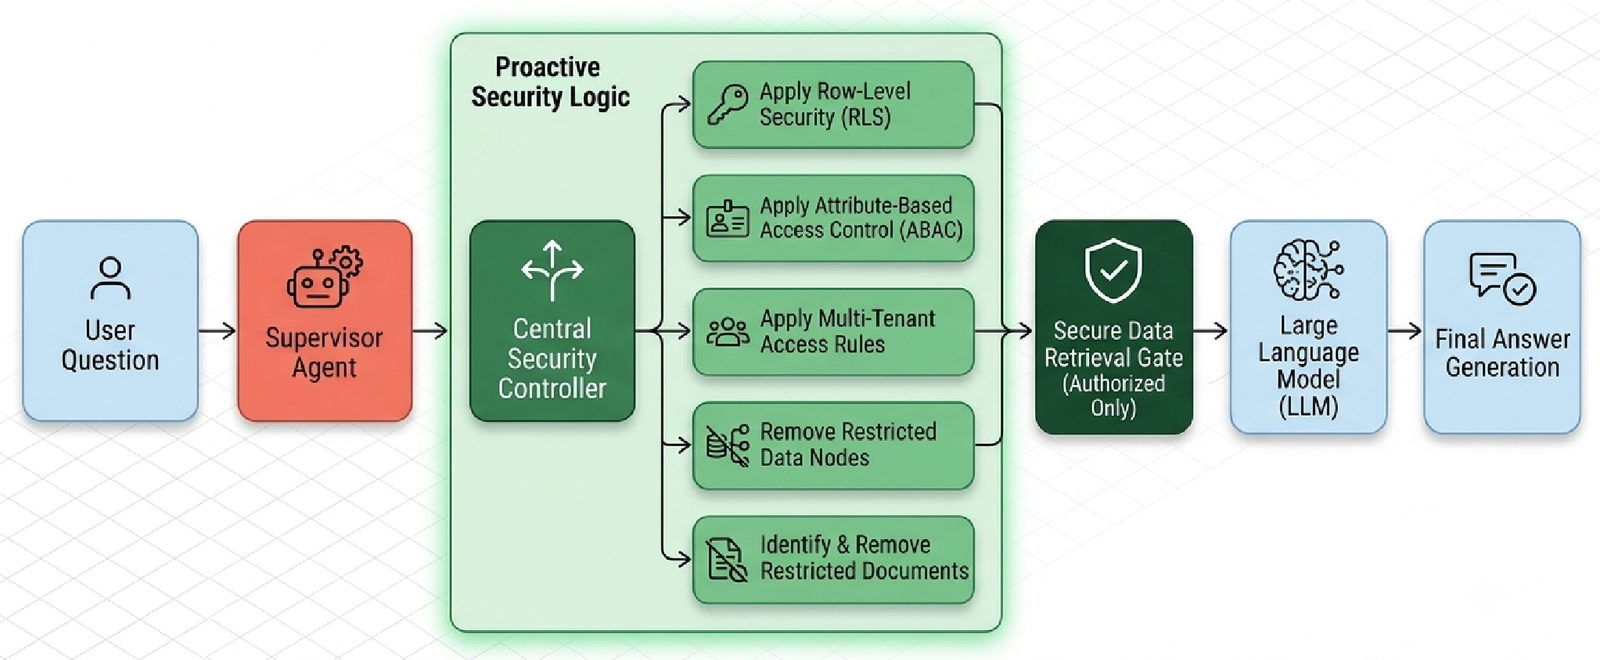
Phase 4: Deterministic security enforcement. A security layer enforces user permissions at the data query level before any retrieval happens. This is structural rather than application-level: It routes queries to the appropriate data partitions, applies row-level filters at the database query level, and gates the input rather than filtering the output. If our user is a regional VP without access to EMEA deal data, the graph returns no EMEA accounts, the metrics lookup excludes EMEA revenue, and the vector search filters out EMEA deal notes. The LLM can’t leak what it never received. (More on why this must be deterministic below.)第四阶段:确定性安全执行。安全层在任何检索发生之前在数据查询级别强制执行用户权限。这是结构性的,而不是应用程序级别的:它将查询路由到适当的数据分区,在数据库查询级别应用行级过滤器,并对输入进行门控,而不是过滤输出。如果我们的用户是一位没有EMEA交易数据访问权限的区域副总裁,图数据库将返回零条EMEA账户,指标查找排除EMEA收入,向量搜索过滤掉EMEA交易笔记。大语言模型无法泄露它从未接收到的信息。(关于为什么这必须是确定性的,详见下文。)
Phase 5: Result synthesis. The LLM reasons about how results from different stores relate, identifies patterns across sources, resolves contradictions, and generates a unified answer with source attribution.第五阶段:结果综合。大语言模型推理来自不同存储的结果如何相关联,识别跨源模式,解决矛盾,并生成带有来源归因的统一答案。
For our revenue question, synthesis might produce:对于我们的收入问题,综合结果可能如下:
Q2 enterprise revenue missed forecast by $4.2M (8% variance). Three root causes account for 85% of the gap: (1) Four deals totaling $2.8M slipped to Q3 due to extended legal review cycles—all four involved customers who adopted a new procurement platform in Q1 (graph: common vendor relationship). (2) Two large renewals downsized by $1.1M; deal notes cite budget reallocation toward AI initiatives, a pattern appearing across 6 QBR summaries (vector store). (3) Enterprise software spending contracted 3% QoQ industry-wide (external benchmark), suggesting partial macro headwind. Additionally, all four slipped deals lacked executive sponsor engagement in the final 30 days (graph: engagement signal absent).第二季度企业收入比预测低420万美元(8%的差异)。三个根本原因占缺口的85%:(1)四笔总额为280万美元的交易因法律审查周期延长推迟到第三季度——所有四笔交易都涉及在第一季度采用新采购平台的客户(图数据库:共同供应商关系)。(2)两笔大型续约缩减了110万美元;交易笔记指出预算重新分配到人工智能计划,这一模式在6份QBR摘要中出现(向量存储)。(3)企业软件支出在全行业范围内季度环比收缩3%(外部基准),表明存在部分宏观不利因素。此外,所有四笔推迟的交易在最后30天都缺乏高管赞助商的参与(图数据库:缺乏参与信号)。
No single store contains that answer. On a dashboard, the miss shows up as a red number. The orchestrated synthesis explains why it happened, surfaces the structural patterns behind it, and points to what needs to change.没有任何单一存储包含该答案。在仪表板上,错失表现为一个红色的数字。编排后的综合结果解释了它发生的原因,揭示了其背后的结构性模式,并指出了需要改变的地方。
The core orchestration pattern核心编排模式
The orchestration loop itself is straightforward. Here’s the core pattern:编排循环本身很简单。以下是核心模式:
from concurrent.futures import ThreadPoolExecutor, as_completed


def run_agent(question, tools, execute_fn, model="gpt-4o"):
    # Phase 1-2: LLM analyzes intent and decides which tools to call
    response = client.chat.completions.create(
        model=model, messages=[{"role": "user", "content": question}],
        tools=tools, tool_choice="auto"
    )
    tool_calls = response.choices[0].message.tool_calls


    # Phase 3: Execute tool calls in parallel
    with ThreadPoolExecutor(max_workers=len(tool_calls)) as executor:
        futures = {
            executor.submit(execute_fn, tc.function.name,
                            json.loads(tc.function.arguments)): tc
            for tc in tool_calls
        }
        results = {futures[f].id: f.result() for f in as_completed(futures)}


    # Phase 5: Synthesize results into unified answer
    messages = [response.choices[0].message]
    for tc_id, result in results.items():
        messages.append({"role": "tool", "tool_call_id": tc_id,
                         "content": json.dumps(result)})
    return client.chat.completions.create(model=model, messages=messages)
The tool definitions tell the LLM what each store is optimized for. The LLM decides which to invoke based on the question’s intent. With parallel execution, data retrieval completes in milliseconds even when hitting multiple stores simultaneously, making LLM inference the dominant latency factor, not the data layer.工具定义告诉大语言模型每个存储针对什么进行了优化。大语言模型根据问题的意图决定调用哪个存储。通过并行执行,即使同时访问多个存储,数据检索也能在毫秒内完成,使得大语言模型推理成为主要的延迟因素,而不是数据层。
Why the knowledge graph is the highest-leverage component为什么知识图谱是杠杆率最高的组件
Knowledge graphs have existed for decades and have always been powerful. They’ve also stayed on the exotic end of the enterprise stack, and the reason is human rather than technical. The last-mile problem was translating between natural language and graph traversals. A graph database can answer extraordinarily complex relationship questions, such as “Which accounts have overlapping stakeholders with our churned customers from last quarter who also evaluated competitor products?” but asking that question required an engineer fluent in both the graph schema and the business domain. That combination of skills is rare and expensive, which is exactly why graph databases have never quite gone mainstream.知识图谱已经存在了几十年,并且一直很强大。它们也一直处于企业技术栈的异类端,原因在于人为因素而非技术因素。最后一英里问题是在自然语言和图遍历之间进行翻译。图数据库可以回答极其复杂的关系问题,例如“哪些账户与我们上一季度流失且同时也评估过竞争对手产品的客户拥有重叠的利益相关者?”,但提出这个问题需要一位精通图模式和业务领域的工程师。这种技能组合既罕见又昂贵,这正是图数据库从未真正成为主流的原因。
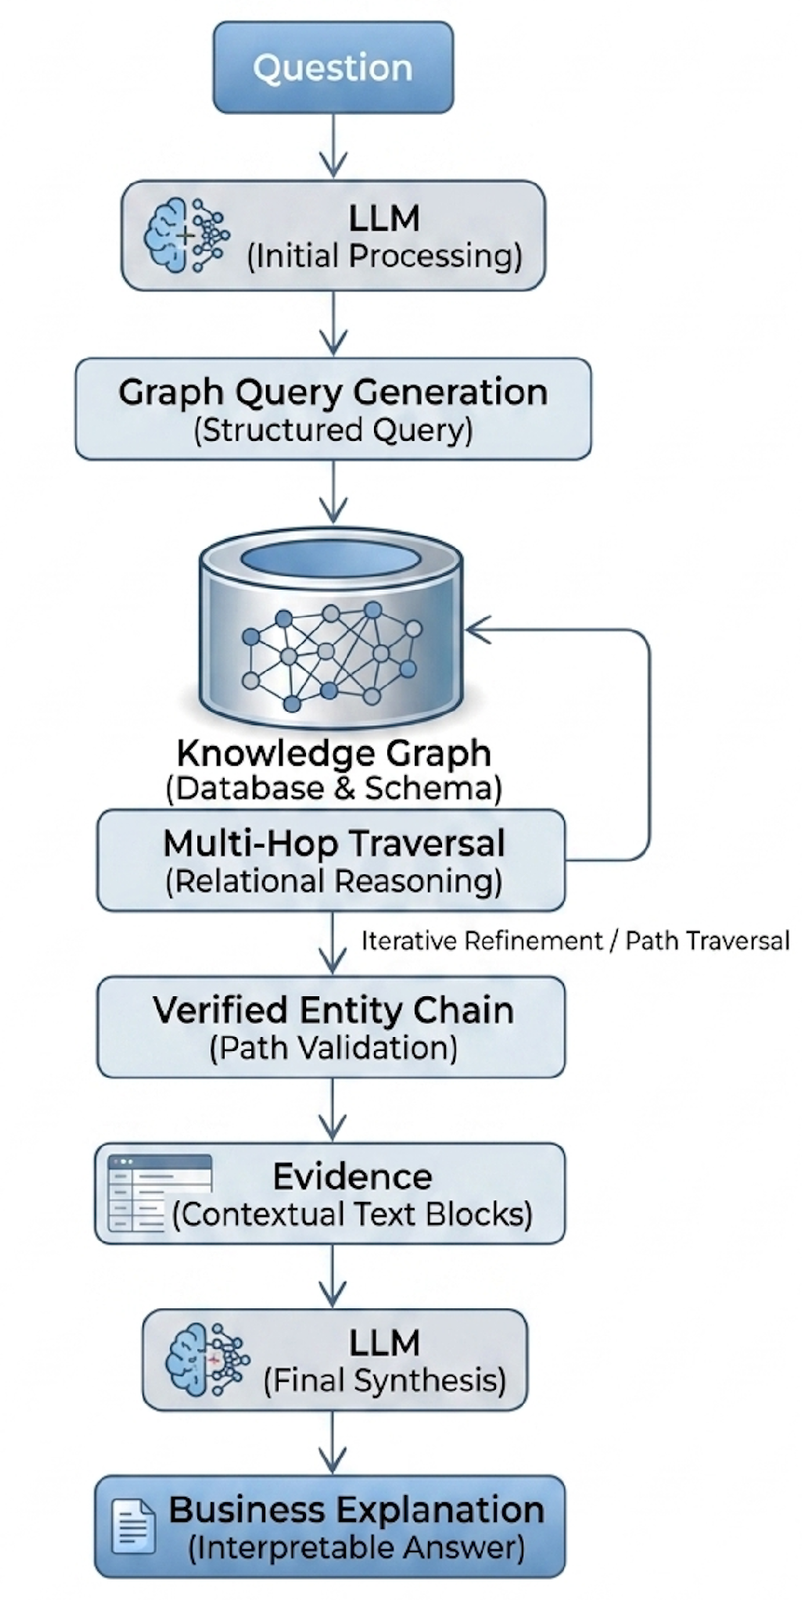
GenAI removes this bottleneck, and it does so precisely where the barrier was highest: the translation step that used to require a specialist. With an LLM as the translation layer, the graph becomes accessible to anyone who can type a question in plain language. The LLM generates graph queries, traverses multihop relationship paths, and explains results in business context. In our revenue variance example, the graph reveals that all four slipped deals share a common pattern of customers who adopted a new procurement platform in Q1 and lacked executive sponsor engagement in the final 30 days. That pattern is invisible in revenue metrics alone, because it requires relationship traversal across account nodes, vendor relationships, and engagement signals.生成式人工智能消除了这一瓶颈,而且它消除的位置正是障碍最高的地方:过去需要专家的翻译步骤。有了大语言模型作为翻译层,任何能用简单语言输入问题的人都可以访问图谱。大语言模型生成图查询,遍历多跳关系路径,并以业务背景解释结果。在我们的收入差异示例中,图谱揭示了所有四笔推迟的交易都有一个共同模式:客户在第一季度采用了新的采购平台,并且在最后30天缺乏高管赞助商的参与。这种模式仅在收入指标中是不可见的,因为它需要跨账户节点、供应商关系和参与信号进行关系遍历。
Designing the graph schema设计图模式
The critical design decision is aligning the graph schema with your business ontology. The temptation is to model the graph around your data model (tables, columns, foreign keys). The correct approach is to model it around how your organization actually thinks about its domain:关键的设计决策是将图模式与你的业务本体对齐。诱惑是将图谱围绕你的数据模型(表、列、外键)进行建模。正确的方法是围绕你的组织实际如何思考其领域来建模:
- Entity nodes with lifecycle stages, engagement indicators, and health scores具有生命周期阶段、参与指标和健康分数的实体节点
- Product nodes connected to use cases, adoption patterns, and competitive alternatives连接到用例、采用模式和竞争替代方案的产品节点
- Relationship edges that capture not just connections but context: strength, recency, business driver, and directionality不仅捕捉连接,还捕捉背景的关系边:强度、时效性、业务驱动因素和方向性
When the data model matches the business mental model, the agent’s responses feel natural rather than technically correct but practically useless.当数据模型与业务思维模型匹配时,代理的响应感觉很自然,而不是技术上正确但在实践中毫无用处。
GraphRAG: Deterministic reasoning chainsGraphRAG:确定性推理链
A powerful extension is GraphRAG (graph retrieval-augmented generation), where the agent constructs deterministic inference paths by traversing the graph rather than relying on the LLM’s parametric knowledge. The LLM isn’t remembering something from training; it’s following an explicit path through verified data. The result is auditable reasoning chains: “Account A connects to Partner B through implementation relationship X, and Partner B appears in three other churned accounts, suggesting a systemic delivery issue.” Each step is verifiable against source data, which is critical in enterprise environments where decisions need justification beyond model confidence scores.一个强大的扩展是GraphRAG(图检索增强生成),其中代理通过遍历图谱而不是依赖大语言模型的参数化知识来构建确定性推理路径。大语言模型不是在回忆训练中的内容;它是在经过验证的数据中遵循一条明确的路径。结果是可审计的推理链:“账户A通过实施关系X连接到合作伙伴B,而合作伙伴B出现在其他三个流失账户中,这表明存在系统性的交付问题。”每一步都可以根据源数据进行验证,这在决策需要超越模型置信度得分的理由的企业环境中至关重要。
GraphRAG also reduces hallucination risk. When the LLM follows graph edges rather than generating from parametric memory, the actual data constrains the space of possible outputs. The graph acts as a factual guardrail on the reasoning process.GraphRAG还降低了幻觉风险。当大语言模型遵循图边而不是从参数化记忆中生成时,实际数据限制了可能输出的空间。图谱充当了推理过程的事实护栏。
Production considerations生产考虑因素
Moving from prototype to production exposes a set of challenges that don’t appear in demos.从原型走向生产会暴露出一系列在演示中不会出现的问题。
Model flexibility and cost management模型灵活性和成本管理
Decouple the orchestration layer from any specific LLM provider. I can’t stress this enough. If it’s tightly coupled to one provider’s API, you’ll end up rewriting it within a few months, when pricing changes or a better model drops. Implement model fallback for throttling resilience. The landscape moves fast, and you don’t want architectural lock-in baked into your data infrastructure.将编排层与任何特定的大语言模型提供商解耦。我怎么强调这一点都不为过。如果它与一个提供商的API紧密耦合,当定价发生变化或出现更好的模型时,你最终会在几个月内重写它。实现模型回退以提高节流弹性。这个领域发展迅速,你不想将架构锁定烘焙到你的数据基础设施中。
Multihop model selection is also worth considering. Use a smaller, faster model for intent classification and query decomposition, where the task is well-defined, and a larger model for synthesis, where reasoning quality matters. Intent classification with a small model takes around 200 ms and costs a fraction of a full reasoning pass, so reserve the expensive inference for synthesis, where quality directly impacts user experience.多跳模型选择也值得考虑。对意图分类和查询分解使用更小、更快的模型,因为任务定义明确;对综合使用更大的模型,因为推理质量很重要。使用小模型的意图分类大约需要200毫秒,成本仅为完整推理过程的一小部分,因此将昂贵的推理留给综合,因为质量直接影响用户体验。
Security at the data layer数据层的安全性
Row-level security must be enforced deterministically before data reaches the agent, as described in Phase 4 above. This is a nonnegotiable architectural constraint. LLMs are probabilistic systems, and security enforcement can’t be. Don’t rely on the model to filter sensitive information after the fact; the data should never enter the context window in the first place.必须在数据到达代理之前确定性地强制执行行级安全性,如上述第四阶段所述。这是一个不可协商的架构约束。大语言模型是概率系统,而安全性强制执行不能是概率性的。不要依赖模型在事后过滤敏感信息;数据根本不应该进入上下文窗口。
Data freshness and serving architecture数据新鲜度和服务架构
Separate data construction from data serving. An offline batch pipeline refreshes the stores from source systems on a scheduled cadence, and the real-time agent only reads preprocessed data. This keeps query latency low while letting computationally intensive transformations such as graph construction, embedding generation, and metric aggregation happen asynchronously. The pipeline should be idempotent and observable, with freshness monitoring per store. When the graph is six hours stale but the metrics store is real-time, the agent should know this and communicate its confidence accordingly. Add freshness metadata to every tool response rather than waiting for a user to catch a stale number and lose trust for weeks; that metadata becomes part of the agent’s context for answer generation.将数据构建与数据服务分开。离线批量流水线按预定节奏从源系统刷新存储,实时代理只读取预处理后的数据。这保持了较低的查询延迟,同时让计算密集型转换(如图构建、嵌入生成和指标聚合)异步发生。流水线应该是幂等的且可观察的,并具有每个存储的新鲜度监控。当图谱陈旧了六个小时但指标存储是实时的时候,代理应该知道这一点并相应地传达其置信度。在每个工具响应中添加新鲜度元数据,而不是等待用户发现陈旧数字并失去信任数周;该元数据成为代理回答生成上下文的一部分。
Evaluation and observability评估和可观察性
Agent responses need evaluation at both the tool level (“Did the graph query return the right entities?”) and the synthesis level (“Did the final answer correctly combine tool outputs?”). These are different failure modes that require different approaches.代理响应需要在工具级别(“图查询是否返回了正确的实体?”)和综合级别(“最终答案是否正确结合了工具输出?”)进行评估。这些是需要不同方法的不同故障模式。
Log every tool call and result, every query decomposition decision, and every synthesis step. You’ll need these traces when something goes wrong, and in a multistore system that can mean a bad graph query, a stale metric, a poorly matched document, or a synthesis error. Without traces, debugging is guesswork. Build automated evaluation pipelines that test known questions against expected answers and track accuracy over time. Degradation usually signals a data quality issue in one of the stores rather than an LLM regression.记录每一个工具调用和结果、每一个查询分解决策和每一个综合步骤。当出现问题时,你需要这些追踪记录,在多存储系统中,这可能意味着错误的图查询、陈旧的指标、匹配不佳的文档或综合错误。没有追踪记录,调试就是猜测。构建自动化评估流水线,测试已知问题与预期答案的对比,并随时间跟踪准确性。性能下降通常预示着其中一个存储中的数据质量问题,而不是大语言模型的回归。
Design that observability around the failure modes that actually occur, because production deployments rarely fail because the LLM is inaccurate. They fail because supporting systems drift. Typical examples include:围绕实际发生的故障模式设计可观察性,因为生产部署很少因为大语言模型不准确而失败。它们失败是因为支持系统发生了偏移。典型示例包括:
- Stale graph data causing the agent to reference relationships that no longer exist陈旧的图数据导致代理引用不再存在的关系
- Poorly generated embeddings returning irrelevant documents from the vector store生成不佳的嵌入从向量存储中返回不相关的文档
- Inconsistent business definitions across stores (e.g., “active customer” means different things in the graph and the metrics store)跨存储的不一致业务定义(例如,“活跃客户”在图谱和指标存储中意味着不同的含义)
- Conflicting metrics from different source systems with no reconciliation logic来自不同源系统的冲突指标,没有协调逻辑
- Missing source attribution making answers unverifiable缺少来源归因导致答案无法验证
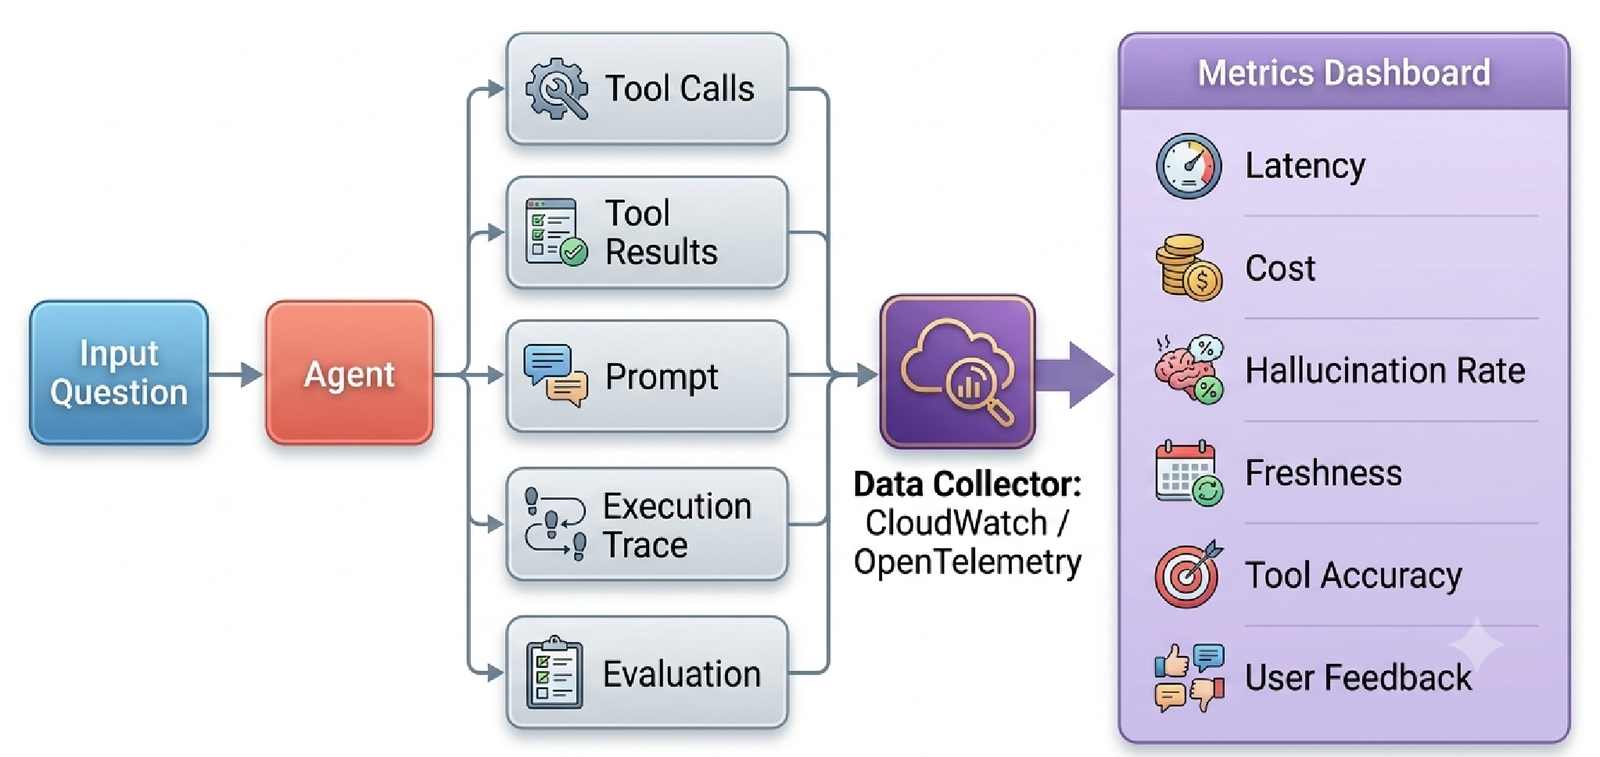
Handling these well matters just as much as prompt engineering. Most debugging sessions trace back to data quality, not model quality.很好地处理这些问题与提示工程一样重要。大多数调试会话最终都会追溯到数据质量,而不是模型质量。
Implementation guidance实施指南
Start with the questions your BI tool can’t answer today (and beyond). The trap with a question inventory is that it captures only what people already know how to ask. The most valuable questions are usually the ones missing from every existing report. They require stitching together three systems, so users either answer them by hand in a spreadsheet or quietly give up. So catalog what your users actually care about, and pay special attention to the questions they route around. Interview analysts about the analysis they abandon halfway, the recurring spreadsheet they dread, and the follow-up question they never bother to ask because the current system makes it too expensive. If most of what you find can still be answered from a single store, you need a better dashboard, not an agent. The pattern earns its complexity only when synthesis across sources is the bottleneck rather than the data access itself.从你的商业智能工具今天(及以后)无法回答的问题开始。问题清单的陷阱在于它只捕捉到人们已经知道如何询问的内容。最有价值的问题通常是现有报告中缺失的问题。它们需要将三个系统拼接在一起,因此用户要么在电子表格中手动回答,要么悄悄放弃。所以,编目你的用户真正关心的问题,并特别注意他们绕过的问题。采访分析师关于他们半途而废的分析、他们畏惧的重复性电子表格,以及他们从不费心去问的后续问题,因为当前系统让这样做代价太高。如果你发现大部分问题仍然可以从单一存储中回答,你需要的是更好的仪表板,而不是代理。只有当跨源综合成为瓶颈而非数据访问本身时,这种模式才值得其复杂性。
Pick one use case and go deep. Build for the case where the manual synthesis burden is highest, where an analyst currently spends four hours pulling data from three systems to answer a leadership question. Prove value in that narrow corridor, then expand; adding a new store is incremental once the orchestration layer exists.选择一个用例并深入研究。为手动综合负担最重的情况构建,即分析师目前花费四个小时从三个系统中提取数据来回答领导层问题的情况。在那个狭窄的范围内证明价值,然后扩展;一旦有了编排层,添加一个新的存储是增量的。
Invest in the knowledge graph early. It’s the hardest component to build and the highest-leverage one to have. The schema will be wrong on the first attempt and less wrong on the third. It evolves with your understanding of the domain, and that understanding deepens only through iteration with real users asking real questions.尽早投资知识图谱。它是最难构建的组件,也是拥有后杠杆率最高的组件。模式在第一次尝试时会出错,在第三次时会好一些。它随着你对领域的理解而演变,而这种理解只有通过与提出真实问题的真实用户进行迭代才能加深。
Design for the analyst, not the engineer. The success metric isn’t technical elegance. It’s whether the finance analyst stops building the same three-system Excel mashup every Monday morning. Talk to your users, watch them work, and build for their actual workflow rather than your ideal architecture.为分析师设计,而不是为工程师设计。成功的衡量标准不是技术上的优雅。而是财务分析师是否停止在每周一早上构建相同的三个系统Excel混合表。与你的用户交谈,观察他们的工作,并为他们的实际工作流程而构建,而不是为你理想的架构。
Measure what matters. Track response accuracy, latency (P50 and P99), user adoption, and reduction in manual synthesis time. Track the questions the agent can’t answer, because those gaps are your roadmap for which stores to add or which schemas to extend.衡量重要的事情。跟踪响应准确性、延迟(P50和P99)、用户采用率以及手动综合时间的减少。跟踪代理无法回答的问题,因为这些空白是你添加哪些存储或扩展哪些模式的路线图。
What this enables at scale这在规模上实现了什么
This pattern does more than make existing workflows faster. It enables workflows that weren’t possible before, no matter how many analysts or engineers you threw at the problem. An agent querying a graph, a metrics store, and a document repository at once can surface patterns no human would find by checking each system manually. A finding like “entities in segment X who adopted product Y and had a support escalation in the last 90 days are 3x more likely to churn” requires reasoning across three data sources in a single inference; no dashboard surfaces that, and no analyst checks that specific combination unprompted. In the same motion it democratizes access, opening information that was previously reachable only by engineers who could write Cypher or SQL to anyone who can ask a question in plain language. The analyst’s role shifts from answering routine questions toward building the ontology, curating the graph, and tackling problems that require genuine human judgment.这种模式不仅仅是让现有的工作流程更快。它实现了以前不可能的工作流程,无论你投入多少分析师或工程师来解决这个问题。一个同时查询图谱、指标存储和文档库的代理可以发现人类手动检查每个系统都无法发现的模式。像“在细分市场X中采用产品Y并在过去90天内有支持升级的实体流失的可能性高出3倍”这样的发现,需要在一次推理中跨三个数据源进行推理;没有仪表板能显示这一点,也没有分析师会在没有提示的情况下检查该特定组合。在同样的过程中,它实现了访问民主化,向任何能用简单语言提问的人开放了以前只有能编写Cypher或SQL的工程师才能获取的信息。分析师的角色从回答日常问题转变为构建本体、策划图谱以及处理需要真正人类判断的问题。
It also delivers auditable reasoning at enterprise scale. GraphRAG provides deterministic inference paths that are verifiable against source data, so every conclusion traces back through explicit edges and nodes. This builds trust where decisions carry financial, regulatory, or strategic weight. “The AI said so” becomes “the data shows that A connects to B through X, B exhibits property Y, and historical pattern Z suggests the following.” That traceability changes the conversation from “Can we trust AI?” to a review of the work the AI actually did.它还提供了企业规模的可审计推理。GraphRAG提供了可根据源数据验证的确定性推理路径,因此每一个结论都可以通过显式边和节点追溯。这在决策具有财务、监管或战略权重的地方建立了信任。“人工智能这么说”变成了“数据显示A通过X连接到B,B表现出属性Y,历史模式Z表明了以下内容。”这种可追溯性将对话从“我们能信任人工智能吗?”转变为对人工智能实际所做工作的审查。
Conclusion结论
The future of enterprise analytics is unlikely to be a larger warehouse or a smarter dashboard. It is an orchestration layer capable of reasoning across specialized systems while preserving each system’s strengths. Purpose-built data stores remain exactly where they are; what changes is how we access them.企业分析的未来不太可能是一个更大的仓库或更智能的仪表板。它是一个能够在保留每个系统优势的同时跨专用系统进行推理的编排层。专用数据存储保留在它们所在的地方;改变的是我们访问它们的方式。
The architectural pattern described here doesn’t replace warehouses, graphs, vector stores, or APIs. It coordinates them. That distinction is subtle, but it fundamentally changes what enterprise analytics systems can deliver. The next generation of analytics platforms will do more than answer questions faster. They’ll reason across enterprise knowledge in ways that previously required experienced human analysts. The data already existed. The orchestration layer did not.这里描述的架构模式并没有取代仓库、图谱、向量存储或API。它协调它们。这种区别很微妙,但它从根本上改变了企业分析系统所能提供的价值。下一代分析平台将不仅仅是更快地回答问题。它们将以以前需要经验丰富的人类分析师的方式跨企业知识进行推理。数据已经存在。编排层此前并不存在。
Disclaimer: The views and architectural perspectives in this article are entirely my own and do not represent my employer or any affiliated organization. References to patterns and technologies are based on publicly available information and personal experience. No proprietary or internal information was used.免责声明:本文中的观点和架构视角完全是我个人的,并不代表我的雇主或任何关联组织。对模式和技术的引用基于公开信息和个人经验。未使用任何专有或内部信息。