Meet KARL: A faster agent for enterprise knowledge, powered by custom RL认识 KARL:一款由定制强化学习驱动、更高效的企业知识智能体
by The Databricks AI Research Team 作者:Databricks AI 研究团队
Reinforcement Learning for Enterprise Agents面向企业智能体的强化学习
For the full tech report, click here. Interested in trying Databricks custom RL on your enterprise agent? Click here.点击此处获取完整技术报告。有兴趣在您的企业智能体上尝试 Databricks 定制强化学习吗?请点击此处。
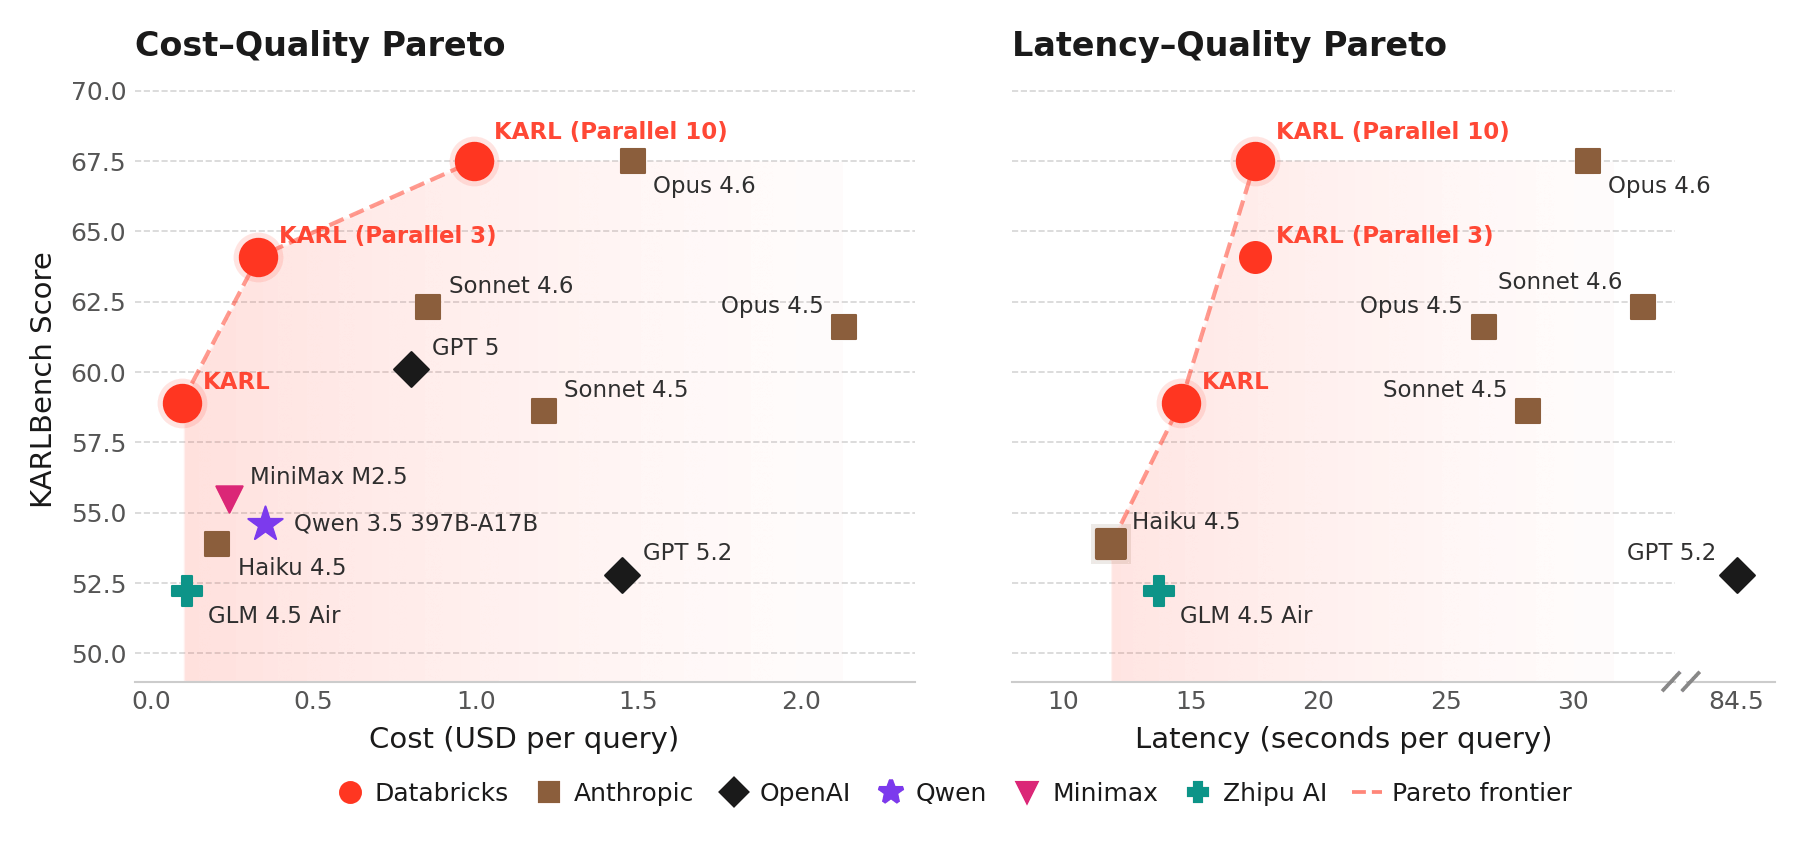
The improved reasoning abilities of current models has led to an explosion of agents deployed for knowledge work, such as writing code, asking questions about enterprise data, and automating common workflows. While models used in enterprise tasks are very powerful, they are also extremely expensive, and inference costs have begun to grow unsustainably for many use cases. In this post and the corresponding tech report, we describe our experience using reinforcement learning (RL) to build custom models to power use cases that are a key part of our Agent Bricks product. This example demonstrates that, for relatively low costs, it is possible to build custom models that strictly dominate frontier models on all three critical dimensions: inference cost, latency, and quality. Our findings are consistent with other industry observations, such as Cursor’s Composer model, where RL-based customization was able to drastically improve both speed and quality compared to alternatives.当前模型推理能力的提升,促使大量智能体被部署到知识型工作中,例如编写代码、查询企业数据以及自动化常见工作流。虽然这些用于企业任务的模型功能非常强大,但成本也极其高昂,对于许多用例而言,推理成本已增长到不可持续的地步。在这篇文章及相应的技术报告中,我们介绍了利用强化学习 (RL) 构建定制模型以支持我们 Agent Bricks 产品关键用例的经验。这一案例证明,我们完全可以以相对较低的成本构建出在推理成本、延迟和质量这三个关键维度上均优于前沿模型的定制模型。我们的研究结果与其他行业观察一致,例如 Cursor 的 Composer 模型,RL 定制化在提升速度和质量方面远超其他替代方案。
KARL: A Faster, Stronger, Cheaper Knowledge Agent for Databricks UsersKARL:为 Databricks 用户打造的更快、更强、更经济的知识智能体
The model we trained, which we call KARL, addresses a critical enterprise capability, grounded reasoning: answering questions by searching for documents, fact-finding, cross-referencing information, and reasoning over dozens or hundreds of steps. Grounded reasoning is required for several Databricks products, such as Agent Bricks Knowledge Assistant. Unlike math and coding, grounded reasoning tasks are hard-to-verify – there’s often no single correct answer. In situations like this, guiding reinforcement learning to a good solution is especially hard.我们训练的模型名为 KARL,它解决了企业的一项关键能力——基于事实的推理(grounded reasoning):通过搜索文档、查找事实、交叉引用信息以及在数十甚至数百个步骤中进行推理来回答问题。Databricks 的多款产品(如 Agent Bricks Knowledge Assistant)都需要这种基于事实的推理能力。与数学和编码不同,基于事实的推理任务难以验证,因为往往没有唯一的正确答案。在这种情况下,引导强化学习找到理想的解决方案尤为困难。
Using RL techniques and infrastructure developed at Databricks, KARL matches the performance of the world's most powerful proprietary models at a fraction of the serving cost and latency, including on new grounded reasoning tasks it had never seen. (See the tech report for full details.) We did this with just a few thousand GPU hours of training and entirely synthetic data. 利用 Databricks 开发的强化学习技术和基础设施,KARL 在推理成本和延迟仅为世界顶级专有模型一小部分的情况下,达到了与它们相当的性能,甚至在从未见过的全新事实推理任务中表现同样出色。(详见技术报告。)我们仅用了几千个 GPU 小时的训练时间,并完全使用合成数据完成了这一目标。
In internal testing with human users, KARL provided better and more comprehensive responses than our existing products and the latest frontier models. This research is making its way into the Databricks agents you use today, like Agent Bricks, grounding answers in your unstructured and structured data in the Databricks Lakehouse.在与人类用户进行的内部测试中,KARL 提供了比我们现有产品和最新前沿模型更好、更全面的响应。这项研究成果正逐步应用于您今天使用的 Databricks 智能体(如 Agent Bricks)中,为您的 Databricks Lakehouse 中的非结构化和结构化数据提供事实依据。
A reusable RL pipeline for Databricks customers为 Databricks 客户提供可复用的强化学习流水线
We are excited to share that the same RL pipelines and infrastructure we used to create KARL (and other agents we’ll talk about soon) are now available to Databricks customers seeking to improve model performance and reduce costs for their high-volume agentic workloads. Nearly all real-world enterprise tasks are hard-to-verify, so KARL paves the way – not just for a better experience for Databricks users – but for our customers to create their own custom RL models for their popular agents. Our Custom RL private preview, backed by AI Runtime, enables you to use the KARL infrastructure to build a more efficient, domain-specific version of your agent. If you have an AI agent that’s scaling fast and are interested in optimizing it with RL, sign up here to express your interest in this preview.我们很高兴地宣布,我们用于创建 KARL(以及我们即将推出的其他智能体)的强化学习流水线和基础设施,现已向 Databricks 客户开放,旨在帮助他们提升模型性能并降低高容量智能体工作负载的成本。几乎所有现实世界的企业任务都难以验证,因此 KARL 不仅为 Databricks 用户带来了更好的体验,也为我们的客户开辟了道路,使他们能够为自己的热门智能体创建定制的强化学习模型。我们的“定制强化学习”私有预览版由 AI Runtime 提供支持,让您能够利用 KARL 的基础设施构建更高效、特定领域的智能体。如果您的 AI 智能体正在快速扩展,并且有兴趣通过强化学习进行优化,请点击此处注册以表达您的预览意向。
Get the latest posts in your inbox在收件箱中获取最新文章
Subscribe to our blog and get the latest posts delivered to your inbox.订阅我们的博客,将最新文章发送到您的收件箱。