Agent programs in the region are taking a different path from the consumer-facing applications that get a lot of attention. Fewer teams are starting with a single flashy chatbot. More are starting with a platform, often because they already have a dozen agent proofs of concept scattered across business units, and no consistent way to bring them into production.该地区的智能体项目正走上一条与那些备受关注的面向消费者的应用不同的道路。很少有团队从一个华丽的聊天机器人开始,更多团队选择从平台入手。这通常是因为他们已经在各个业务部门中分散部署了十几个智能体概念验证 (PoC),却缺乏一种统一的方法将其投入生产环境。
This is a pattern we’re seeing appear across industries with very different levels of regulatory pressure. From energy and telecom to insurance, banking, and retail, the underlying challenge is consistent. Companies are finding agents easy to prototype and much harder to operate. Operating well requires an infrastructure layer that many teams did not anticipate when they built their first agent.我们发现,在监管压力迥异的各个行业中,这种模式正逐渐显现。从能源、电信到保险、银行和零售,其核心挑战是一致的:企业发现智能体很容易进行原型设计,但要投入实际运营却困难得多。要实现良好的运营,需要一套许多团队在构建第一个智能体时未曾预料到的基础设施层。
This piece looks at how three companies built that infrastructure layer:本文将探讨三家公司如何构建这一基础设施层:
- Schneider Electric runs an internal AI Hub of 350 people supporting more than 60 agents across critical infrastructure, with an LLMOps discipline built around observability, evaluation, and deployment施耐德电气运营着一个由 350 人组成的内部 AI 中心,为关键基础设施提供 60 多个智能体支持,并围绕可观测性、评估和部署建立了一套 LLMOps 规范
- monday.com rebuilt its AI assistant, Sidekick, from a single general-purpose agent into a layered system of subagents, bounded tools, and sandboxes after discovering in production that adding more tools was making the agent worse, not bettermonday.com 在生产实践中发现,盲目增加工具反而降低了智能体的表现,因此将 AI 助手 Sidekick 从单一的通用智能体重构为一个由子智能体、边界工具和沙箱组成的层级系统
- Vodafone built two production assistants, Insight Engine and Enigma, on LangGraph and uses LangSmith to monitor and improve them沃达丰基于 LangGraph 构建了两个生产级助手 Insight Engine 和 Enigma,并使用 LangSmith 进行监控和改进
Alongside these three, we’ll draw on patterns emerging across a broader set of agent programs we’re seeing in the region, spanning industries from insurance and security operations to consumer retail.除了这三家公司,我们还将借鉴该地区更广泛的智能体项目中出现的模式,这些项目涵盖了从保险、安全运营到消费零售等多个行业。
The emerging patterns in agent programs智能体项目中正在形成的模式
Central agent platforms are consolidating fragmented agents across the enterprise. The most common pattern in the region right now is that teams are investing in a platform, rather than building single agents. 35% of organizations we speak to describe a company-wide agent platform or control plane as the primary use case, with business-unit agents eventually running on top of it.中央智能体平台正在整合企业内部碎片化的智能体。目前该地区最常见的模式是团队投资于平台,而不是构建单一的智能体。我们访谈的组织中,有 35% 将企业级智能体平台或控制平面作为主要用例,并计划最终让各业务部门的智能体运行其上。
Companies with a dozen or more agent efforts underway tend to reach the same conclusion: individual teams are rebuilding the same foundations, and someone needs to own the shared layer. That can mean vetted, reusable templates or frameworks that keep teams from reinventing the basics, or consolidating decentralized development into a central AI hub that supports the full lifecycle. At this stage, it is not unusual for a company to have hundreds of proofs of concept but no clear path to production for most of them. A central agent platform can solve this problem.拥有十几个甚至更多智能体项目的公司往往会得出相同的结论:各团队在重复构建相同的基础设施,需要有人来负责共享层。这可能意味着提供经过验证的可重用模板或框架,防止团队重复造轮子,或者将分散的开发整合到一个支持全生命周期的中央 AI 中心。在现阶段,一家公司拥有数百个概念验证项目但大多数无法进入生产环境的情况并不罕见。中央智能体平台可以解决这个问题。
Many organizations are finding ROI from building agents for regulated document and back-office work. 18% of organizations we speak to are focusing on claims, underwriting, invoices, tenders, procurement, payroll, or other workflows with both an existing paper trail and a known cost per case. Agents for policy-wording review, claims-document classification, loss-run extraction, and invoice validation are all in production. In many cases, work that once took hours can now be completed in minutes.许多组织发现,通过为受监管的文档和后台工作构建智能体,可以获得投资回报 (ROI)。我们访谈的组织中,有 18% 专注于理赔、承保、发票、招标、采购、工资单或其他具有现有纸质记录和已知单案成本的工作流程。用于保单措辞审查、理赔文档分类、损失运行提取和发票验证的智能体均已投入生产。在许多情况下,过去需要数小时的工作现在可以在几分钟内完成。
Risk, compliance, and security operations use cases are rising in the region. 12% of organizations we speak to are building agents for reducing analyst workload in functions that carry audit obligations. Examples include triaging low- and medium-severity security alerts, running second-line assurance and anti-financial-crime testing, and automating flagged-transaction verification with an attached confidence score.风险、合规和安全运营用例在该地区呈上升趋势。我们访谈的组织中,有 12% 正在构建智能体,以减轻承担审计义务职能部门的分析师工作量。例如,对中低严重程度的安全警报进行分类、运行二线保障和反金融犯罪测试,以及通过附加置信度评分来自动化验证标记交易。
Federated building begins once engineering starts to become a bottleneck. 16% of organizations are trying to help non-engineers build agents with central guardrails. The common pattern is enabling low-code and non-technical users to configure agents, while engineers industrialize the ones that work. To accomplish this, teams are building global platforms (leveraging products such as LangSmith Fleet, offered headless for enterprises) where teams can configure, evaluate, and publish agents without writing code, while central teams enforce the standards required for production.一旦工程能力成为瓶颈,联邦式构建便应运而生。16% 的组织正在尝试通过中央防护栏帮助非工程师构建智能体。常见的模式是让低代码和非技术用户能够配置智能体,而由工程师将有效的智能体工业化。为实现这一目标,团队正在构建全球平台(利用 LangSmith Fleet 等企业级无头产品),团队无需编写代码即可配置、评估和发布智能体,而中央团队则负责强制执行生产所需的标准。
Observability, evals, and cost control are the foundation for scale. This is the most common theme across our conversations. Observability is increasingly tied to governance and spend, alongside debugging. Teams want tracing, evals, prompt management, and annotation queues across dozens of use cases at once. Increasingly, teams are also putting an LLM gateway at the center of the roadmap to create unified visibility across users, models, tokens, spend, and policy before agents are given broader autonomy.可观测性、评估和成本控制是规模化的基础。这是我们对话中最常见的主题。可观测性正日益与治理、支出以及调试挂钩。团队希望同时对数十个用例进行追踪、评估、提示词管理和标注队列管理。越来越多的团队还在路线图的核心位置部署 LLM 网关,以便在赋予智能体更广泛的自主权之前,实现对用户、模型、Token、支出和策略的统一可见性。
The three teams below show what it takes to operate agents once a company has moved beyond its first pilot.以下三支团队展示了当公司超越最初的试点阶段后,运营智能体需要做些什么。
Three leading teams building agents in production三支在生产环境中构建智能体的领先团队
Schneider Electric: LLMOps as a shared discipline across 60+ agents施耐德电气:作为 60 多个智能体共享规范的 LLMOps
Schneider Electric is a global energy technology leader, driving sustainability by electrifying, automating, and digitalizing industries, businesses, and homes. With 160,000 employees and roughly 40 billion euros in annual revenue, the company runs an ambitious AI program: an internal AI Hub of 350 experts who have deployed 60+ agents to optimize energy consumption, extend asset lifecycles, and accelerate developer productivity.施耐德电气是全球能源技术领导者,通过电气化、自动化和数字化推动工业、商业和家庭的可持续发展。该公司拥有 16 万名员工,年收入约 400 亿欧元,并运行着一个雄心勃勃的 AI 项目:一个由 350 名专家组成的内部 AI 中心,已经部署了 60 多个智能体,旨在优化能源消耗、延长资产寿命并提高开发人员生产力。
Schneider's broad AI program spans three categories: 施耐德广泛的 AI 项目涵盖三个类别:
- Embedding intelligence directly into products to cut energy consumption (such as thermal learning in room controllers)将智能直接嵌入产品以降低能源消耗(例如房间控制器的热学习)
- Using AI to forecast demand and production so customers can shift electricity usage toward cheaper, greener times of day利用 AI 预测需求和生产,以便客户将用电量转移到更便宜、更环保的时段
- Deploying agentic copilots that reduce operational friction, like managing a more complex grid, customer success, or querying a carbon emissions software system部署智能体副驾驶,减少运营摩擦,例如管理更复杂的电网、客户成功或查询碳排放软件系统
Agents are embedded across these objectives, operating in critical infrastructure with strict data residency requirements and cybersecurity controls. Schneider needed a common agent platform that could help teams build quickly while preserving control over data, deployment, and quality.智能体被嵌入到这些目标中,在具有严格数据驻留要求和网络安全控制的关键基础设施中运行。施耐德需要一个通用的智能体平台,既能帮助团队快速构建,又能保持对数据、部署和质量的控制。
“The challenge of accuracy, the challenge of quality of answers, the challenge of guardrailing, are very real. When you deploy a solution at scale, you need tooling like LangSmith. Everything linked with trustability and understanding what happens is extremely valuable for us.” — Philippe Rambach, CAIO at Schneider Electric“准确性、答案质量和防护栏的挑战是非常现实的。当大规模部署解决方案时,你需要像 LangSmith 这样的工具。与可信度相关的一切以及对所发生情况的理解,对我们来说都极具价值。”——施耐德电气首席 AI 官 Philippe Rambach
Schneider’s AI Platform team sits within their AI Hub and provides the shared infrastructure that enables AI squads to reliably deliver across their vast technology landscape (multi-cloud, from cloud to the edge, and all types of AI).施耐德的 AI 平台团队隶属于其 AI 中心,提供共享基础设施,使 AI 团队能够在其庞大的技术领域(多云、从云端到边缘以及各类 AI)中可靠地交付成果。
They’ve built LLMOps capabilities around LangSmith and the broader LangChain ecosystem to:他们围绕 LangSmith 和更广泛的 LangChain 生态系统构建了 LLMOps 能力,旨在:
- Deploy and continuously improve the accuracy and quality of an AI Assistant serving 140,000 employees in 100+ countries部署并持续提高服务于 100 多个国家/地区 14 万名员工的 AI 助手的准确性和质量
- Co-build an LLMOps maturity framework to deploy their Customer Success Manager Copilot共同构建 LLMOps 成熟度框架,以部署其客户成功经理副驾驶
- Accelerate their quotation workflow with LangSmith Deployment's task-queue model利用 LangSmith Deployment 的任务队列模型加速报价工作流程
Observability可观测性
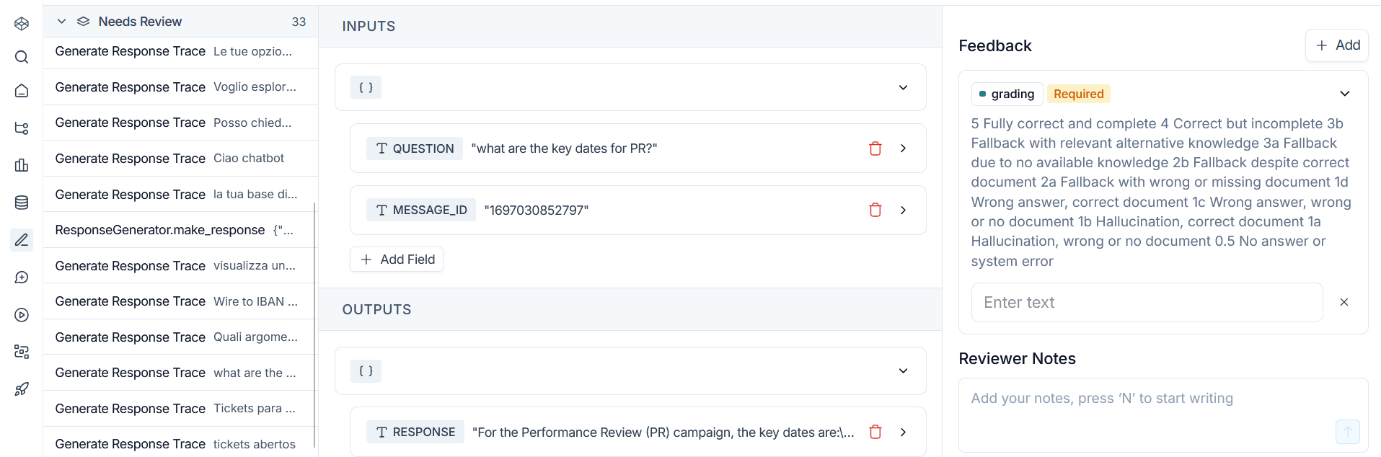
Schneider self-hosts LangSmith on AWS EKS behind its own security perimeter. One of its most important structural decisions was to create one workspace per AI product spanning every environment, from development through production, rather than creating separate workspaces for each environment.施耐德在 AWS EKS 上的安全边界内自托管 LangSmith。其最重要的结构性决策之一是为每个 AI 产品创建一个跨越从开发到生产所有环境的工作区,而不是为每个环境创建单独的工作区。
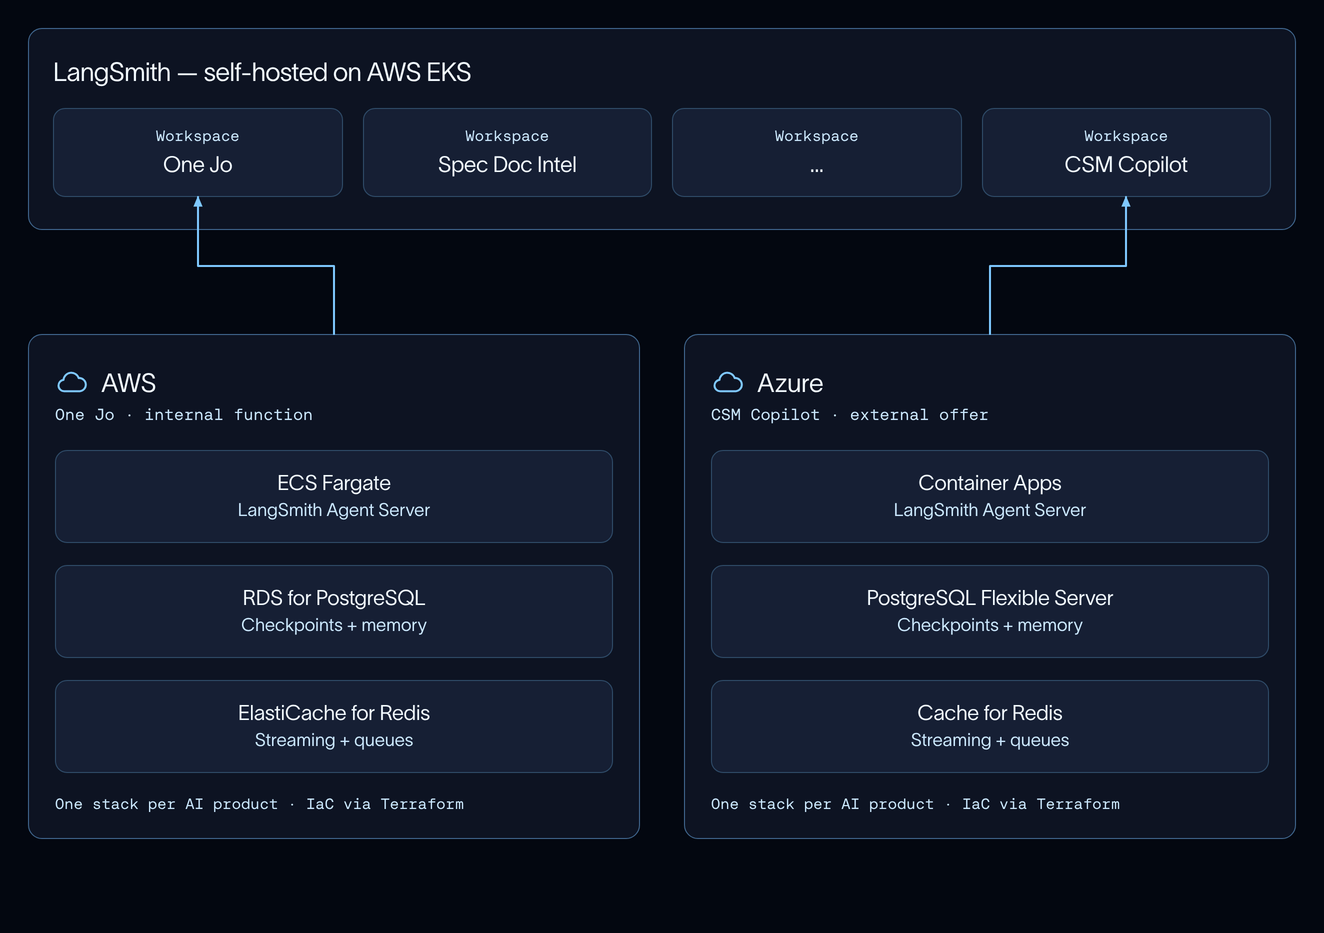
Structuring this way facilitates the improvement loop. Production traces can flow back into development datasets for offline evaluation, while subject-matter experts can annotate a production trace and push it directly into a dataset.这种结构促进了改进循环。生产追踪数据可以流回开发数据集进行离线评估,而主题专家可以对生产追踪进行标注并直接推送到数据集中。
One Jo, Schneider’s internal AI assistant, serves 160,000 employees across 107 countries. Every conversation is traced, and production traces are systematically reused to build regression datasets and detect drift.施耐德内部 AI 助手“One Jo”服务于 107 个国家/地区的 16 万名员工。每一次对话都被追踪,生产追踪数据会被系统地重复使用,以构建回归数据集并检测偏差。
Evaluation评估
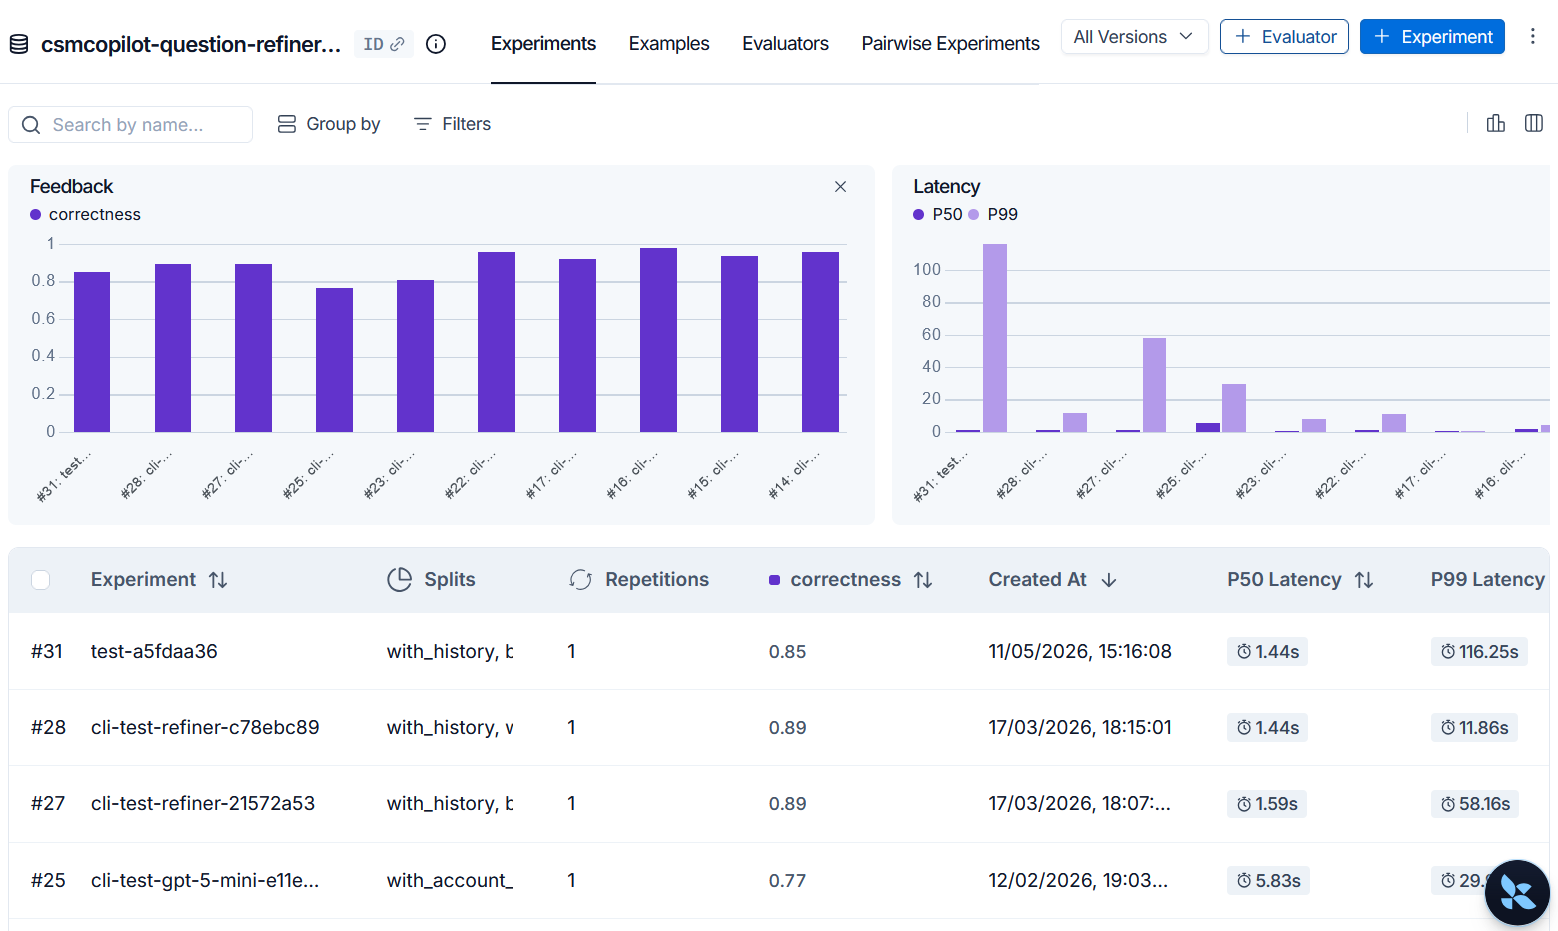
Schneider has invested in evaluation on three fronts. First, it built offline evaluation templates, standardizing dataset conventions and evaluator interfaces across squads.施耐德在三个方面进行了评估投入。首先,它构建了离线评估模板,统一了各团队之间的数据集约定和评估器接口。
Second, it created an LLMOps maturity framework that scores each of its 60+ products on instrumentation, offline evals, online evals, and feedback loops, then uses those scores to gate progression from exploration to industrialization.其次,它创建了一个 LLMOps 成熟度框架,根据仪表化、离线评估、在线评估和反馈循环对 60 多个产品进行评分,然后利用这些分数来控制从探索到工业化的进度。
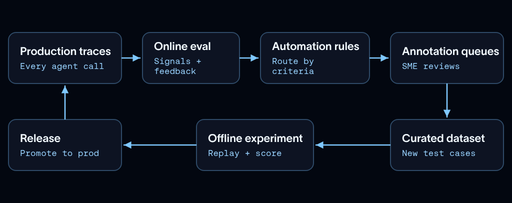
Third, Schneider has brought subject-matter experts directly into the evaluation process. About 20% of its AI products now have at least one active annotation queue where SMEs review real production examples. Its Customer Success Manager Copilot, used by more than 250 CSMs, was built with SMEs involved from the beginning, which the team credits with helping it reach high quality and adoption at launch.第三,施耐德直接将主题专家引入评估过程。目前约 20% 的 AI 产品至少有一个活跃的标注队列,由主题专家审查真实的生产示例。其客户成功经理副驾驶由 250 多名客户成功经理使用,该项目从一开始就有主题专家参与,团队认为这有助于其在发布时实现高质量和高采用率。
Deployment部署
Rather than running every agent on one centralized runtime, Schneider standardizes on the LangSmith Deployment reference architecture: Agent Server with Postgres and Redis, under a “you build it, you run it” model. Each AI product runs on its own dedicated stack. This removes single points of failure where a faulty deployment could impact every agent in the company.施耐德没有将所有智能体运行在同一个集中式运行时上,而是标准化了 LangSmith Deployment 参考架构:采用 Postgres 和 Redis 的智能体服务器,并遵循“谁构建,谁运行”的模式。每个 AI 产品都在自己的专用堆栈上运行。这消除了单点故障,避免了错误的部署影响公司内的所有智能体。
In its Digital Energy division, a document-processing agent that analyzes quote requests and specifications now completes work in just over 15 minutes that previously took hours or days. This type of long-running background workload benefits from a task-queue-based deployment model.在其数字能源部门,一个分析报价请求和规格说明的文档处理智能体,现在仅需 15 分钟多一点就能完成以前需要数小时甚至数天的工作。这种长时间运行的后台工作负载受益于基于任务队列的部署模型。
The tradeoff is more infrastructure to manage and more upgrades to coordinate, which Schneider has identified as an area for continued investment.其代价是需要管理更多的基础设施并协调更多的升级,施耐德已将其确定为需要持续投资的领域。
Key Lessons关键经验
Schneider's early investment in LLMOps paid off. Without trace-level observability and a solid offline evaluation process, none of the company's agentic products would have reached production readiness. Teams that skipped early instrumentation were the ones who later struggled to debug non-deterministic regressions without good data to work from.施耐德在 LLMOps 上的早期投资得到了回报。如果没有追踪级别的可观测性和稳健的离线评估流程,公司没有任何智能体产品能够达到生产就绪状态。那些跳过早期仪表化的团队,后来在没有良好数据支持的情况下,难以调试非确定性的回归问题。
Schneider also learned to rely on out-of-the-box features before building custom ones. Building elaborate internal frameworks, especially for evaluation, was tempting. In hindsight, it worked better to extend existing tools instead of building new ones, like a thin CLI on top of the LangSmith SDK, a custom role mapped to an existing permission model, and scheduled reports built off the public API.施耐德还学会了在构建自定义功能之前先依赖开箱即用的功能。构建复杂的内部框架(尤其是用于评估的框架)很诱人。回想起来,扩展现有工具比构建新工具效果更好,例如在 LangSmith SDK 之上构建一个轻量级 CLI、映射到现有权限模型的自定义角色,以及基于公共 API 构建的定期报告。
Finally, Schneider found that the LangChain ecosystem strikes a good balance between integration and flexibility. The tools work well together (open-source libraries, LangSmith for observability and evaluation, and LangSmith Deployment with LangSmith Studio), but they aren't locked to each other. The OSS libraries can be used on their own, and LangSmith works cleanly with third-party frameworks too. This has given Schneider room to mix and match tools without putting themselves into a corner.最后,施耐德发现 LangChain 生态系统在集成和灵活性之间取得了良好的平衡。这些工具可以很好地协同工作(开源库、用于可观测性和评估的 LangSmith,以及带有 LangSmith Studio 的 LangSmith Deployment),但它们并没有被锁定在一起。OSS 库可以单独使用,LangSmith 也可以与第三方框架清晰地协作。这让施耐德有空间混合和匹配工具,而不会陷入困境。
Learn more: Schneider User Story (Blog)了解更多:施耐德用户案例(博客)
Vodafone: from working pipelines to monitored production systems沃达丰:从工作流水线到受监控的生产系统
Vodafone serves more than 340 million customers across mobile, fixed, IoT, and enterprise services, and operates a network of data centers across Europe. Its data and AI teams built two internal assistants using LangChain and LangGraph to support engineers working across that infrastructure. These assistants help Vodafone’s engineering teams operate its infrastructure more efficiently.沃达丰为超过 3.4 亿移动、固定、物联网和企业服务客户提供服务,并运营着一个横跨欧洲的数据中心网络。其数据和 AI 团队使用 LangChain 和 LangGraph 构建了两个内部助手,以支持在这些基础设施上工作的工程师。这些助手帮助沃达丰的工程团队更高效地运营其基础设施。
Performance metrics monitoring (Insight Engine): This assistant analyzes performance metrics by converting natural language queries into SQL to retrieve key data from data centers monitoring systems. This supports engineers and operations staff with dynamic, data-driven insights that were previously accessible only through custom dashboards.性能指标监控 (Insight Engine):该助手通过将自然语言查询转换为 SQL,从数据中心监控系统中检索关键数据,从而分析性能指标。这为工程师和运营人员提供了动态的、数据驱动的见解,而这些见解以前只能通过自定义仪表板访问。
If the query is related to inventory data, then the agent will direct the request to a NL2SQL chain that will convert the NL query to a SQL query and send the response back to the agent. The agent will then forward the request to another query processing chain that will query the inventory DB, receive the result, and then pass the information to a LLM to create graphs and charts based on the query response.如果查询与库存数据相关,智能体会将请求定向到 NL2SQL 链,该链会将自然语言查询转换为 SQL 查询并将响应发送回智能体。随后,智能体将请求转发给另一个查询处理链,该链将查询库存数据库,接收结果,然后将信息传递给 LLM,以根据查询响应创建图表。
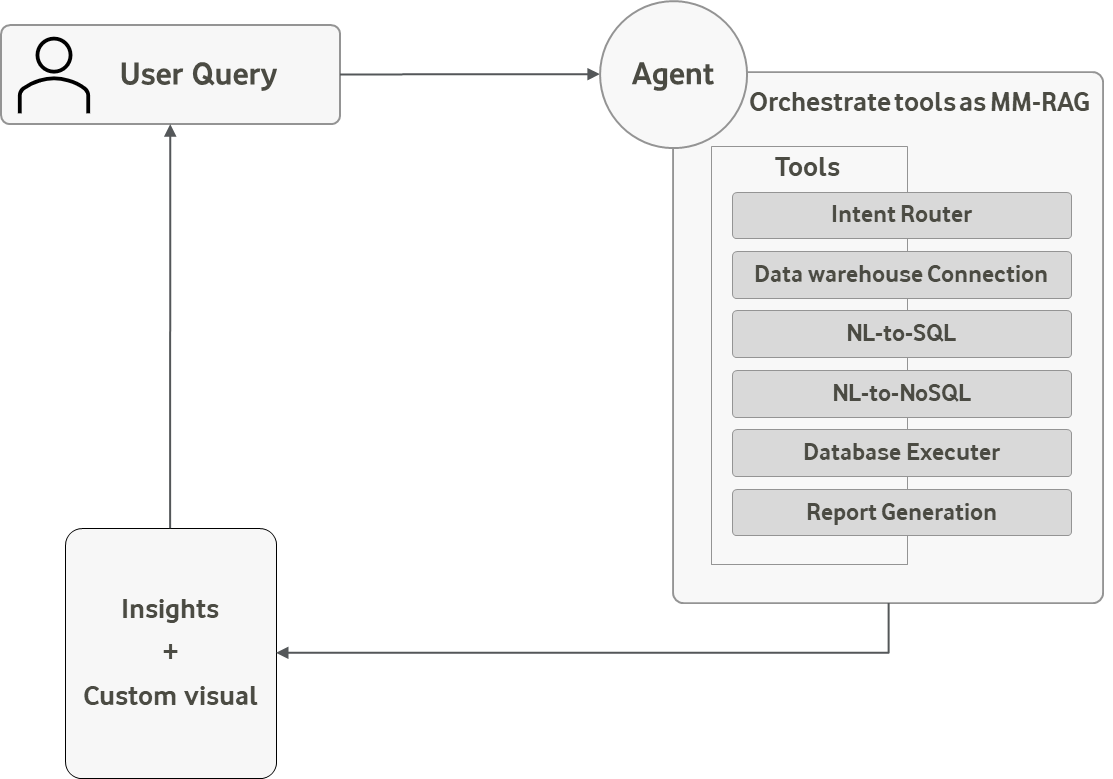
Information retrieval from MS-Sharepoint (Enigma): This assistant enables efficient access to thousands of technical documents and resources. Engineers can ask questions to verify specific designs, retrieve inventory details, or identify contacts within the organization, reducing time spent sifting through documentation.MS-Sharepoint 信息检索 (Enigma):该助手能够高效访问数以千计的技术文档和资源。工程师可以提出问题以验证特定设计、检索库存详情或识别组织内的联系人,从而减少筛选文档所花费的时间。
If the query is related to document summarization, the agent will direct the request to the appropriate chain. In turn, this will fetch the relevant context from the multi-vector DB and present the grounded summary response to the user.如果查询与文档摘要相关,智能体会将请求定向到相应的链。反过来,这将从多向量数据库中获取相关上下文,并向用户提供有根据的摘要响应。
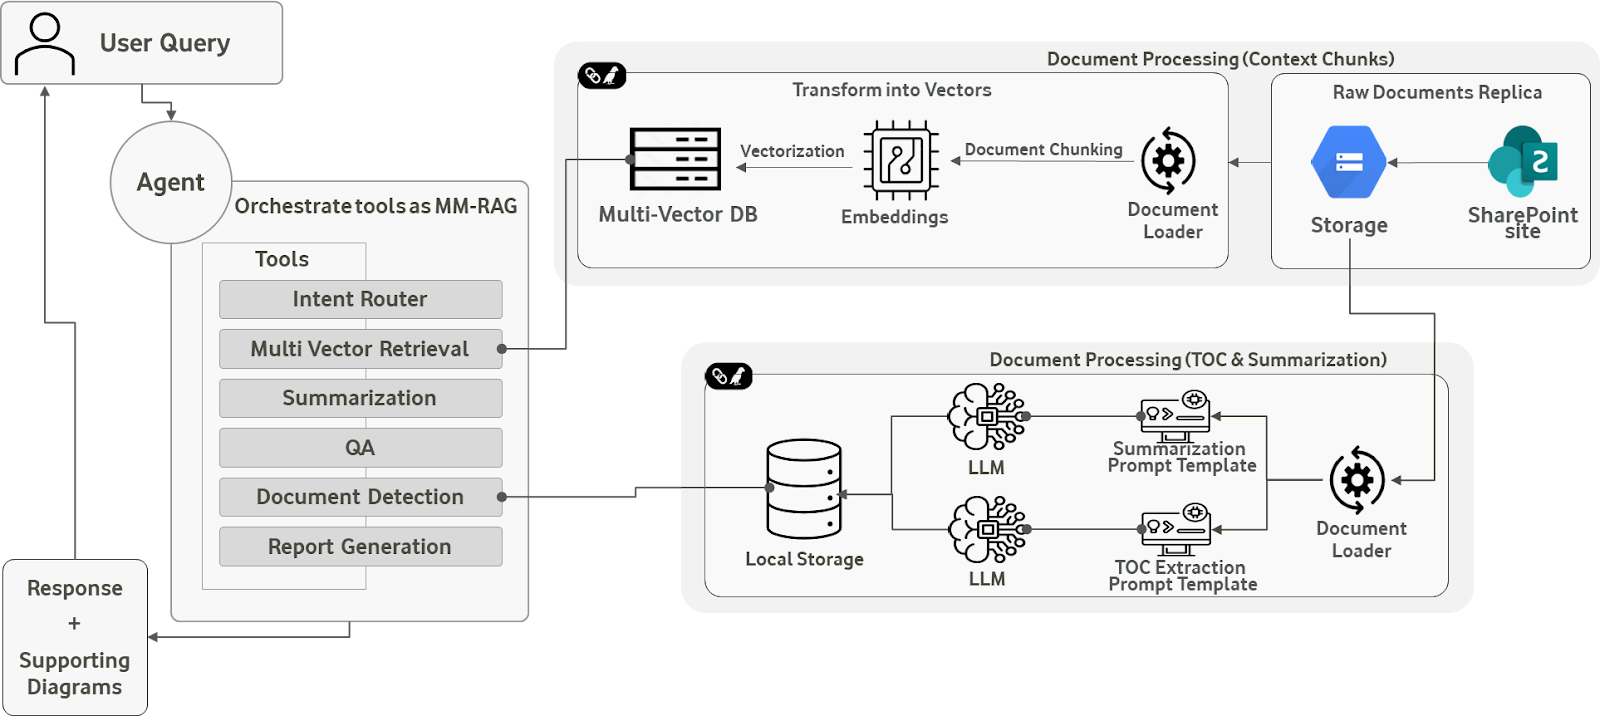
Both systems use a LangGraph agent to classify user intent before routing the request to the appropriate chain.这两个系统都使用 LangGraph 智能体在将请求路由到相应链之前对用户意图进行分类。
“We’ve been using LangChain’s components for over a year now. It’s been a critical enabler for our transition from open-source experimentation to production-grade AI systems.” — Antonino Artale, senior manager of Cloud Solutions, Orchestration and Intelligence, Vodafone“我们使用 LangChain 的组件已经一年多了。这对于我们从开源实验到生产级 AI 系统的转型至关重要。”——沃达丰云解决方案、编排与智能高级经理 Antonino Artale
Vodafone now applies production-grade observability across these systems. Every Insight Engine and Enigma conversation is traced end to end, giving the team visibility into where issues arise across the pipeline.沃达丰现在在这些系统中应用了生产级的可观测性。Insight Engine 和 Enigma 的每一次对话都会进行端到端追踪,使团队能够了解流水线中出现问题的环节。
In these multi-step systems, a poor answer can originate several hops before the final response, whether from misclassified intent, malformed SQL, or the wrong document version being retrieved from SharePoint. End-to-end tracing makes it easier to pinpoint the source of the problem rather than debug only the final output.在这些多步骤系统中,糟糕的答案可能源于最终响应之前的几个环节,无论是意图分类错误、SQL 格式错误,还是从 SharePoint 检索到了错误的文档版本。端到端追踪使得查明问题根源变得更容易,而不是仅仅调试最终输出。
As Vodafone’s GenAI footprint grows, the same monitoring discipline can extend across more data sources, increasingly sophisticated multi-agent workflows, and a broader range of AI applications.随着沃达丰生成式 AI 足迹的增长,同样的监控规范可以扩展到更多数据源、日益复杂的智能体工作流以及更广泛的 AI 应用中。
Learn more: Vodafone User Story (Blog), Fastweb + Vodafone User Story (Blog)了解更多:沃达丰用户案例(博客)、Fastweb + 沃达丰用户案例(博客)
monday.com: why capable agents need more than just toolsmonday.com:为什么强大的智能体需要的不仅仅是工具
Sidekick is monday.com’s AI assistant. Its first version was a single general-purpose agent with a growing list of tools: summarize a project, draft an update, analyze a file, update a board. That was useful at the beginning because it allowed the team to move quickly and learn what users actually wanted.Sidekick 是 monday.com 的 AI 助手。它的第一个版本是一个单一的通用智能体,拥有一系列不断增长的工具:总结项目、起草更新、分析文件、更新看板。这在初期很有用,因为它允许团队快速行动并了解用户真正想要什么。
Then Sidekick moved into real production workflows, and new problems emerged.随后 Sidekick 进入了真正的生产工作流,新问题随之出现。
Tool selection became less reliable as similar tools with overlapping descriptions competed for the model’s attention. Tool schemas consumed context that could otherwise have been used for the user’s actual request. A single prompt had to carry comprehensive instructions for research, writing, data analysis, and board operations.随着描述重叠的相似工具竞争模型的注意力,工具选择变得不再可靠。工具模式消耗了本可用于用户实际请求的上下文。单一的提示词必须承载研究、写作、数据分析和看板操作的综合指令。
Failures also became harder to diagnose. It was difficult to tell whether a bad outcome came from planning, tool selection, tool execution, retrieved context, or the final response. Testing became combinatorial as introducing one new tool could break workflows that had nothing to do with it.故障也变得更难诊断。很难分辨糟糕的结果是源于规划、工具选择、工具执行、检索到的上下文还是最终响应。测试变得组合化,因为引入一个新工具可能会破坏与之无关的工作流。
monday.com rebuilt Sidekick around bounded responsibilities instead of a single large reasoning loop, using LangGraph and Deep Agents to give the system clearer layers:monday.com 围绕边界职责而非单一的大型推理循环重构了 Sidekick,使用 LangGraph 和 Deep Agents 为系统提供了更清晰的层级:
- A context and permission layer determines what is relevant and what the user is allowed to access before anything reaches the model.上下文和权限层在任何内容到达模型之前确定什么是相关的,以及用户被允许访问什么。
- A main orchestration agent interprets the goal and decides how to handle the work. It may answer directly, call a tool, delegate to another agent, or use a sandbox.主编排智能体解释目标并决定如何处理工作。它可以直接回答、调用工具、委派给另一个智能体或使用沙箱。
- Subagents handle narrower objectives with smaller toolsets. A content-generation agent, for example, does not need access to every board-management tool. This gives the monday.com team clearer ownership and makes evaluation more targeted.子智能体使用较小的工具集处理更狭窄的目标。例如,内容生成智能体不需要访问每个看板管理工具。这赋予了 monday.com 团队更清晰的所有权,并使评估更具针对性。
- Tools provide controlled access to monday.com and external systems. They have permission-aware context and work well for bounded operations such as reading a board, searching for documents, updating an item, or triggering a known action. They have a 3-tier classification system with tiled tool discovery. The agent has to explicitly activate them to unlock their full schema. The team sees this akin to handing an LLM a menu instead of throwing the whole kitchen at it.工具提供对 monday.com 和外部系统的受控访问。它们具有权限感知的上下文,非常适合边界操作,例如读取看板、搜索文档、更新条目或触发已知操作。它们具有带有平铺工具发现功能的 3 级分类系统。智能体必须显式激活它们才能解锁其完整模式。团队认为这类似于给 LLM 一份菜单,而不是把整个厨房都扔给它。
- Sandboxes handle work that does not reduce cleanly to a bounded API call. Reconciling several uploaded CSVs against board data, for example, may require inspecting files, writing and executing code, recovering from parsing errors, and generating a chart without forcing every intermediate dataframe through the model’s context window.沙箱处理无法简单归结为边界 API 调用的工作。例如,将多个上传的 CSV 与看板数据进行对账,可能需要检查文件、编写和执行代码、从解析错误中恢复,并生成图表,而无需强迫每个中间数据帧通过模型的上下文窗口。
- Observability and evaluation trace the entire path, including model calls, delegation, sandbox activity, latency, and token usage. A successful tool call, after all, does not necessarily mean the user’s goal was achieved.可观测性和评估追踪整个路径,包括模型调用、委派、沙箱活动、延迟和 Token 使用。毕竟,成功的工具调用并不一定意味着用户目标已经实现。
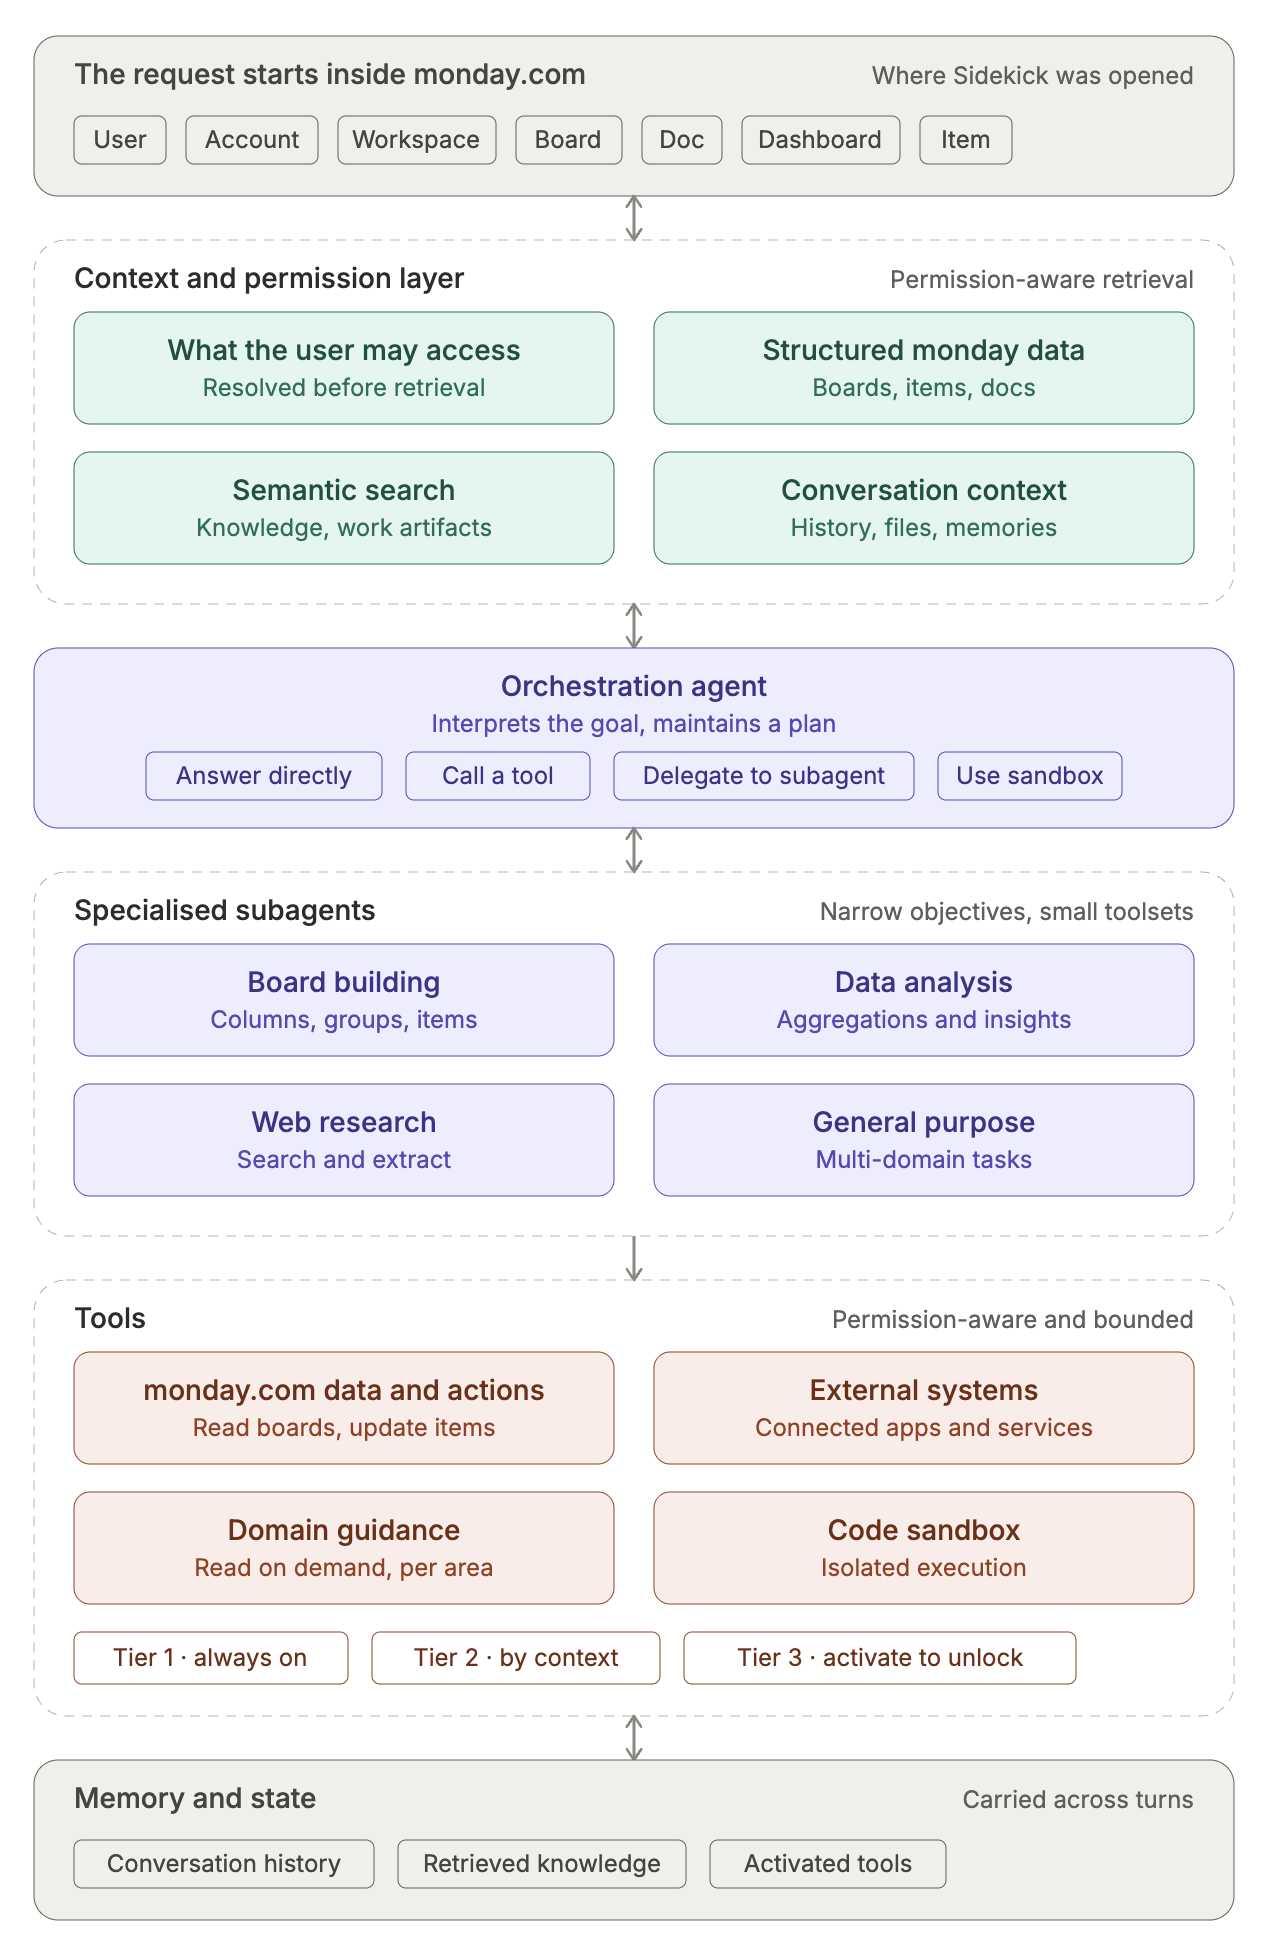
Sandboxes provide the agent with a place to work沙箱为智能体提供了一个工作场所
monday.com found that tools and sandboxes serve different purposes. Tools are a good fit for bounded, auditable actions, while sandboxes are better for work that requires iteration.monday.com 发现工具和沙箱有不同的用途。工具非常适合边界明确、可审计的操作,而沙箱更适合需要迭代的工作。
If a user uploads several CSVs and asks Sidekick to reconcile them with project data, the agent can place the files in a sandbox, inspect them, write and run code, recover from errors, and generate an artifact without pushing every intermediate step through the model’s context window. The main agent only requires the result, and a summary of what happened.如果用户上传了多个 CSV 并要求 Sidekick 将它们与项目数据进行对账,智能体可以将文件放入沙箱、检查它们、编写和运行代码、从错误中恢复并生成工件,而无需将每个中间步骤推送到模型的上下文窗口。主智能体只需要结果以及所发生情况的摘要。
For Sidekick, tools provide controlled access, subagents provide specialized reasoning, and sandboxes provide an execution environment.对于 Sidekick 而言,工具提供受控访问,子智能体提供专业推理,沙箱提供执行环境。
How the LangChain ecosystem fits togetherLangChain 生态系统是如何组合在一起的
monday.com uses different parts of the LangChain ecosystem for different layers of Sidekick:monday.com 在 Sidekick 的不同层级使用了 LangChain 生态系统的不同部分:
- LangGraph and Deep Agents for stateful execution, planning, delegation, and multi-step workflows用于状态化执行、规划、委派和多步骤工作流的 LangGraph 和 Deep Agents
- LangSmith Observability & Evaluation for tracing, debugging, evaluations, dataset management, and comparing agent implementations用于追踪、调试、评估、数据集管理和比较智能体实现的 LangSmith 可观测性与评估
- LangSmith Sandboxes for isolated execution involving files, code, artifacts, and longer-lived intermediate state用于涉及文件、代码、工件和更长寿命中间状态的隔离执行的 LangSmith 沙箱
- Standardized model and tool abstractions so individual components can evolve without rebuilding the entire runtime标准化的模型和工具抽象,以便各个组件可以在不重建整个运行时的情况下演进
When the main agent delegates to a subagent or uses a sandbox, the activity stays visible in the LangSmith traces. This lets the team see whether a failure came from context retrieval, planning, delegation, tool execution, sandbox execution, or the final response.当主智能体委派给子智能体或使用沙箱时,活动在 LangSmith 追踪中保持可见。这让团队能够看到故障是源于上下文检索、规划、委派、工具执行、沙箱执行还是最终响应。
For monday.com, LangChain’s frameworks provide reusable primitives, while leaving the team in control of its own models, retrieval layer, permission system, tools, and user experience. This lets engineers spend more time on what is specific to monday.com, rather than rebuilding generic agent infrastructure.对于 monday.com 来说,LangChain 的框架提供了可重用的原语,同时让团队能够控制自己的模型、检索层、权限系统、工具和用户体验。这让工程师能够花更多时间在 monday.com 特有的内容上,而不是重建通用的智能体基础设施。
Key lessons关键经验
monday.com learned that adding more tools does not necessarily make an agent more capable. As Sidekick’s toolset grew, similar tools began competing for the model’s attention, tool schemas consumed more context, and testing became harder. The team found that giving the agent clearer capability boundaries worked better than continuing to expand a single general-purpose system.monday.com 学到增加更多工具并不一定会使智能体功能更强大。随着 Sidekick 工具集的增长,相似工具开始竞争模型的注意力,工具模式消耗了更多上下文,测试也变得更加困难。团队发现,赋予智能体更清晰的能力边界比继续扩展单一的通用系统效果更好。
monday.com also found that different kinds of work need different execution environments. Tools work well for bounded, auditable actions, while sandboxes are better suited to tasks that require iteration across files, code, and intermediate state. Separating those responsibilities, along with delegating specialized reasoning to subagents, made Sidekick easier to manage and evaluate.monday.com 还发现不同类型的工作需要不同的执行环境。工具适用于边界明确、可审计的操作,而沙箱更适合需要跨文件、代码和中间状态进行迭代的任务。分离这些职责,并将专业推理委派给子智能体,使 Sidekick 更易于管理和评估。
The team also learned to build observability and evaluation into the architecture itself. A successful tool call does not necessarily mean the user’s goal was achieved, so monday.com needed visibility across the full execution path, from context retrieval and planning through delegation, tool use, sandbox execution, and the final response.团队还学会了将可观测性和评估构建到架构本身中。成功的工具调用并不一定意味着用户目标已实现,因此 monday.com 需要从上下文检索和规划到委派、工具使用、沙箱执行和最终响应的全执行路径可见性。
Finally, monday.com found that a more sophisticated architecture does not have to create a more complicated user experience. Looking back, the team would have split into specialized subagents earlier, before the original general-purpose agent accumulated so many responsibilities. But Sidekick can still feel like a single assistant even when specialized agents, tools, and sandboxes are working behind the scenes. 最后,monday.com 发现更复杂的架构不一定会创造更复杂的用户体验。回想起来,团队本应更早地分拆为专业化的子智能体,在原始通用智能体积累如此多职责之前。但即使有专门的智能体、工具和沙箱在幕后工作,Sidekick 仍然可以感觉像是一个单一的助手。
Learn more: monday.com User Story by Omri Bruchim (Blog)了解更多:Omri Bruchim 撰写的 monday.com 用户案例(博客)
What’s top of mind for agent builders in the region该地区智能体构建者最关心的问题
Looking beyond these three examples, similar themes are emerging across the region in where agent builders are focusing their efforts.放眼这三个例子之外,该地区智能体构建者关注的重点正在出现类似的主题。
Data residency and control often dictate the architecture, before the use case does. Companies across banking, insurance, and telecom are taking a similar approach to Schneider. They want to first prove that the platform can meet internal security and policy requirements, then focus on expanding what the agents can do.数据驻留和控制往往在用例之前就决定了架构。银行、保险和电信行业的公司正在采取与施耐德类似的方法。他们希望首先证明平台能够满足内部安全和政策要求,然后专注于扩展智能体的能力。
Organizational alignment is one of the hardest parts of scaling an agent platform. Schneider found that adoption depends on getting teams aligned around common practices, standards, and ways of working. The technology itself can often be integrated relatively quickly. We dive into this more in our guidebook on the Agentic Operating Model for aligning people, process, and technology.组织一致性是扩展智能体平台最困难的部分之一。施耐德发现,采用率取决于让团队围绕共同的实践、标准和工作方式达成一致。技术本身通常可以相对快速地集成。我们在关于智能体运营模型的指南中深入探讨了这一点,该指南旨在协调人员、流程和技术。
Tracing turns vague failures into problems teams can actually fix. Schneider can detect drift in One Jo. Vodafone can identify which stage of Insight Engine produced a bad answer. monday.com can distinguish a planning failure from a sandbox failure. Observability becomes most valuable when teams move from asking “did this work?” to asking “where, specifically, did it go wrong?”追踪将模糊的故障转化为团队可以实际修复的问题。施耐德可以检测 One Jo 中的偏差。沃达丰可以确定 Insight Engine 的哪个阶段产生了糟糕的答案。monday.com 可以区分规划故障和沙箱故障。当团队从询问“这行得通吗?”转向询问“具体是在哪里出错的?”时,可观测性变得最有价值。
Regulated, high-volume back-office workflows often make the ROI case easiest to prove. Claims, underwriting, invoices, and compliance testing already have measurable costs, structured processes, and established audit trails. That makes them natural places to demonstrate value. Much of the highest-conviction agent work in the region is starting in operational workflows, like Vodafone, rather than in customer-facing chat experiences.受监管的高容量后台工作流通常使投资回报率案例最容易证明。理赔、承保、发票和合规测试已经有了可衡量的成本、结构化的流程和既定的审计追踪。这使它们成为展示价值的天然场所。该地区许多高信念的智能体工作都始于运营工作流(如沃达丰),而不是面向客户的聊天体验。
Closing结语
The agent programs furthest along in the region are building the platform, guardrails, and measurement layer alongside the agents themselves.该地区进展最快的智能体项目正在与智能体本身一起构建平台、防护栏和测量层。
This pattern shows up in different ways across these three teams. Schneider invested early in LLMOps to create a shared discipline for dozens of agents. Vodafone added the observability needed to understand and improve complex production workflows. monday.com rethought Sidekick’s architecture around clearer boundaries between agents, tools, and sandboxes.这种模式在三支团队中以不同方式呈现。施耐德早期投资于 LLMOps,为数十个智能体创造了共享规范。沃达丰增加了理解和改进复杂生产工作流所需的可观测性。monday.com 围绕智能体、工具和沙箱之间更清晰的边界重新思考了 Sidekick 的架构。
Across all three examples, these production systems rely on the structure around the agent: the infrastructure, controls, and feedback loops that make behavior visible, measurable, governable, and continuously improvable. That is increasingly where the work of scaling agents in the region is focused.在所有三个例子中,这些生产系统都依赖于智能体周围的结构:使行为可见、可衡量、可治理和可持续改进的基础设施、控制和反馈循环。这正是该地区扩展智能体工作的重点所在。