Latest open artifacts (#23): Laguna S2.1, Inkling, & Kimi K3 show the utility of open models on the Pareto frontier最新开放工件(#23):Laguna S2.1、Inkling 和 Kimi K3 展示了帕累托前沿开放模型的效用
Capacity to train strong models is proliferating.训练强大模型的能力正在激增。
Consolidation has been one of the paths that many astute observers predicted for the near-future of labs training models. It was labelled as inevitable, as training costs are increasing by orders of magnitude every year. Yet, as someone who in 2024 would’ve predicted consolidation really picking up come 2026 or 2027, where are we? We’re at a place where more companies are training strong models — easily investing hundreds of millions to billions of dollars in the total effort still — and an increasing number of organizations are releasing these models openly.许多敏锐的观察家曾预测,整合将是模型训练实验室近期发展的路径之一。随着训练成本每年呈数量级增长,这种整合被视为不可避免。然而,作为一名在 2024 年曾预测整合会在 2026 或 2027 年真正加速的人,我们现在处于什么位置?我们正处于这样一个阶段:更多的公司正在训练强大的模型——总投入依然轻松达到数亿至数十亿美元——并且越来越多的机构正在以开放形式发布这些模型。
The demand for tokens is incredibly high, and likely to increase as models get more efficient and unlock more possible use cases. All of these labs we thought would need to consolidate are realizing that building token machines is a likely path to value, and more companies will identify that source of value over time. 对 Token 的需求高得惊人,而且随着模型效率的提高并解锁更多潜在用例,这种需求很可能会进一步增加。我们曾认为需要整合的所有实验室,现在都意识到构建“Token 机器”是实现价值的可能途径,随着时间推移,会有更多公司发现这一价值源泉。
The prime example is Thinking Machines — when they announced their company in February 2025, very few people would’ve put them in the bucket of an open models company, myself included. Now their open model finetuning service is making hundreds of millions in revenue per year and they’re releasing the best open-weight models built in the U.S.A. — ahead of the early leaders in NVIDIA with Nemotron and Arcee’s Trilogy. Thinking Machines 就是一个典型的例子——当他们在 2025 年 2 月宣布成立公司时,包括我在内,很少有人会将他们归类为开放模型公司。现在,他们的开放模型微调服务每年创造数亿美元的收入,并且他们正在发布美国本土构建的最优秀的开放权重模型——领先于 NVIDIA 的 Nemotron 和 Arcee 的 Trilogy 等早期领跑者。
On the other side of the ecosystem is the sustained pace from the Chinese labs, with newer entrants like Xiaomi still accumulating mindshare in the broader AI economy. Having predicted consolidation for a long time, it now seems like a safer bet is to predict continued adoption, and try to imagine the role that open models play there. How much can revenue-share licenses like Kimi K3 stick? How much market share can open models take? We’re entering the decisive era. 生态系统的另一端是持续保持快节奏的中国实验室,包括小米等较新的入局者,它们仍在更广泛的 AI 经济中积累影响力。在长期预测整合之后,现在看来,预测持续的采用并尝试想象开放模型在其中扮演的角色似乎是一个更稳妥的赌注。像 Kimi K3 这样的收入分成许可模式能持续多久?开放模型能占据多少市场份额?我们正在进入一个决定性的时代。
This is one of the most packed recaps of open models we’ve ever had, we’re excited!这是我们有史以来内容最丰富的开放模型回顾之一,我们对此感到非常兴奋!
Our Picks我们的精选
Inkling by thinkingmachines: The first model from Thinking Machines is a 975B-A41B multimodal MoE that supports text, images, and audio as inputs and produces text as output. While it is not the strongest model among peers (in China) in its size class, it is positioned to be a great base for fine-tuning, e.g., through their commercial offering, Tinker. They also release a smaller version (276B-A12B), which is really competitive for its size.Thinking Machines 的 Inkling:这是 Thinking Machines 推出的首款模型,是一个 975B-A41B 多模态 MoE,支持文本、图像和音频作为输入,并输出文本。虽然它在其规模级别(在中国)中并非最强的模型,但它定位为微调的绝佳基础,例如通过他们的商业产品 Tinker。他们还发布了一个更小的版本(276B-A12B),在其规模级别中极具竞争力。
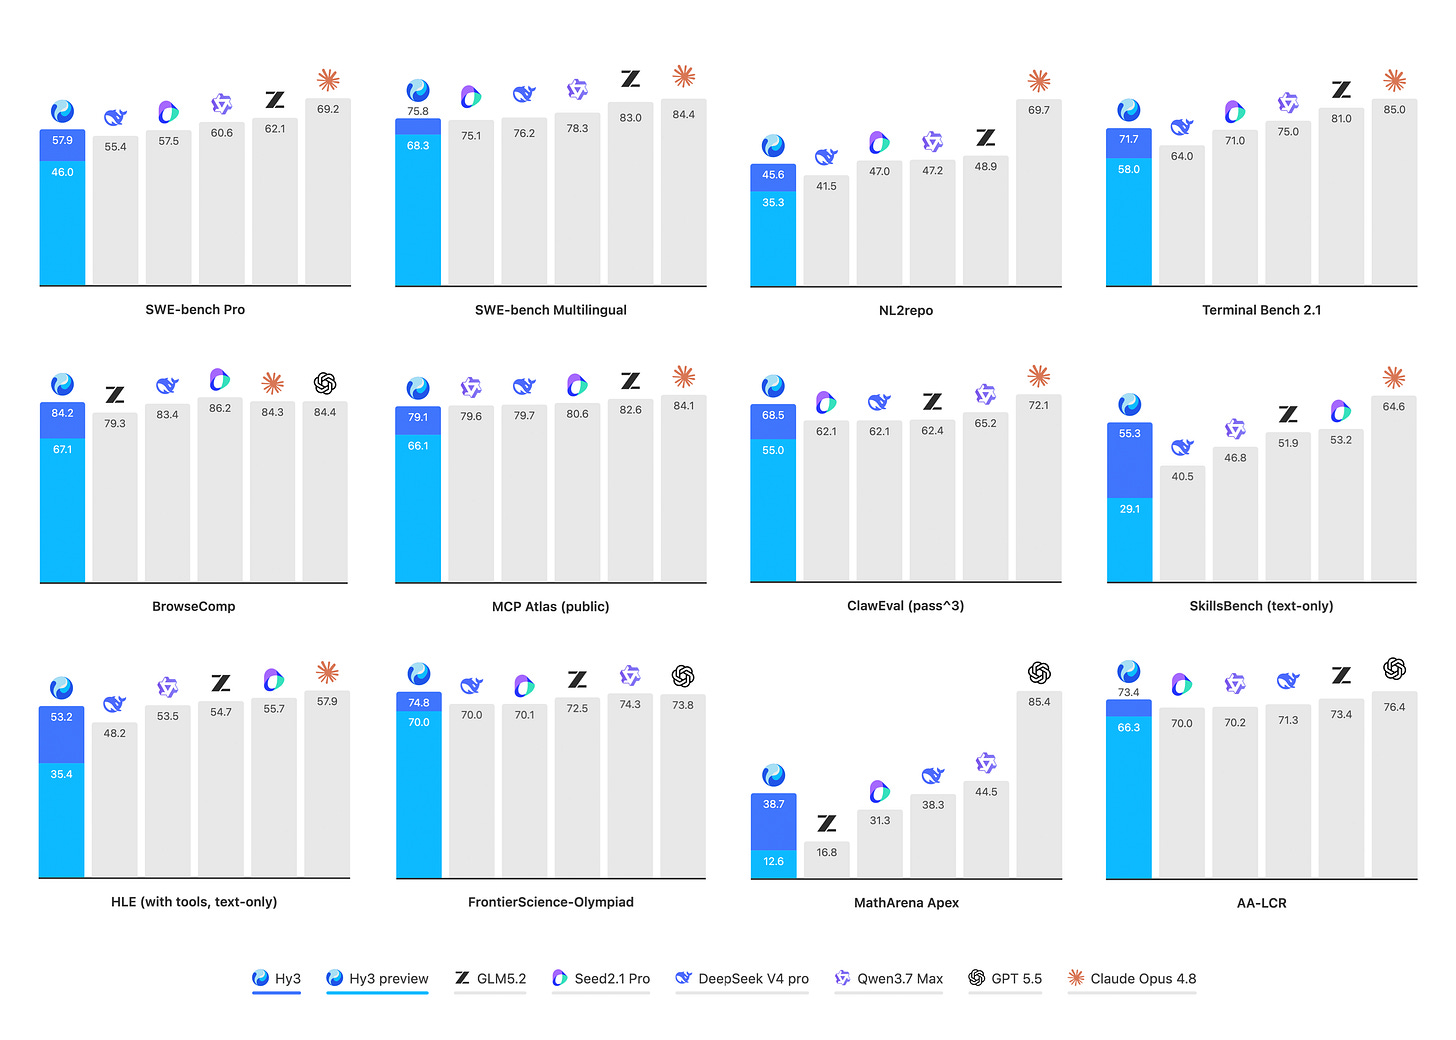
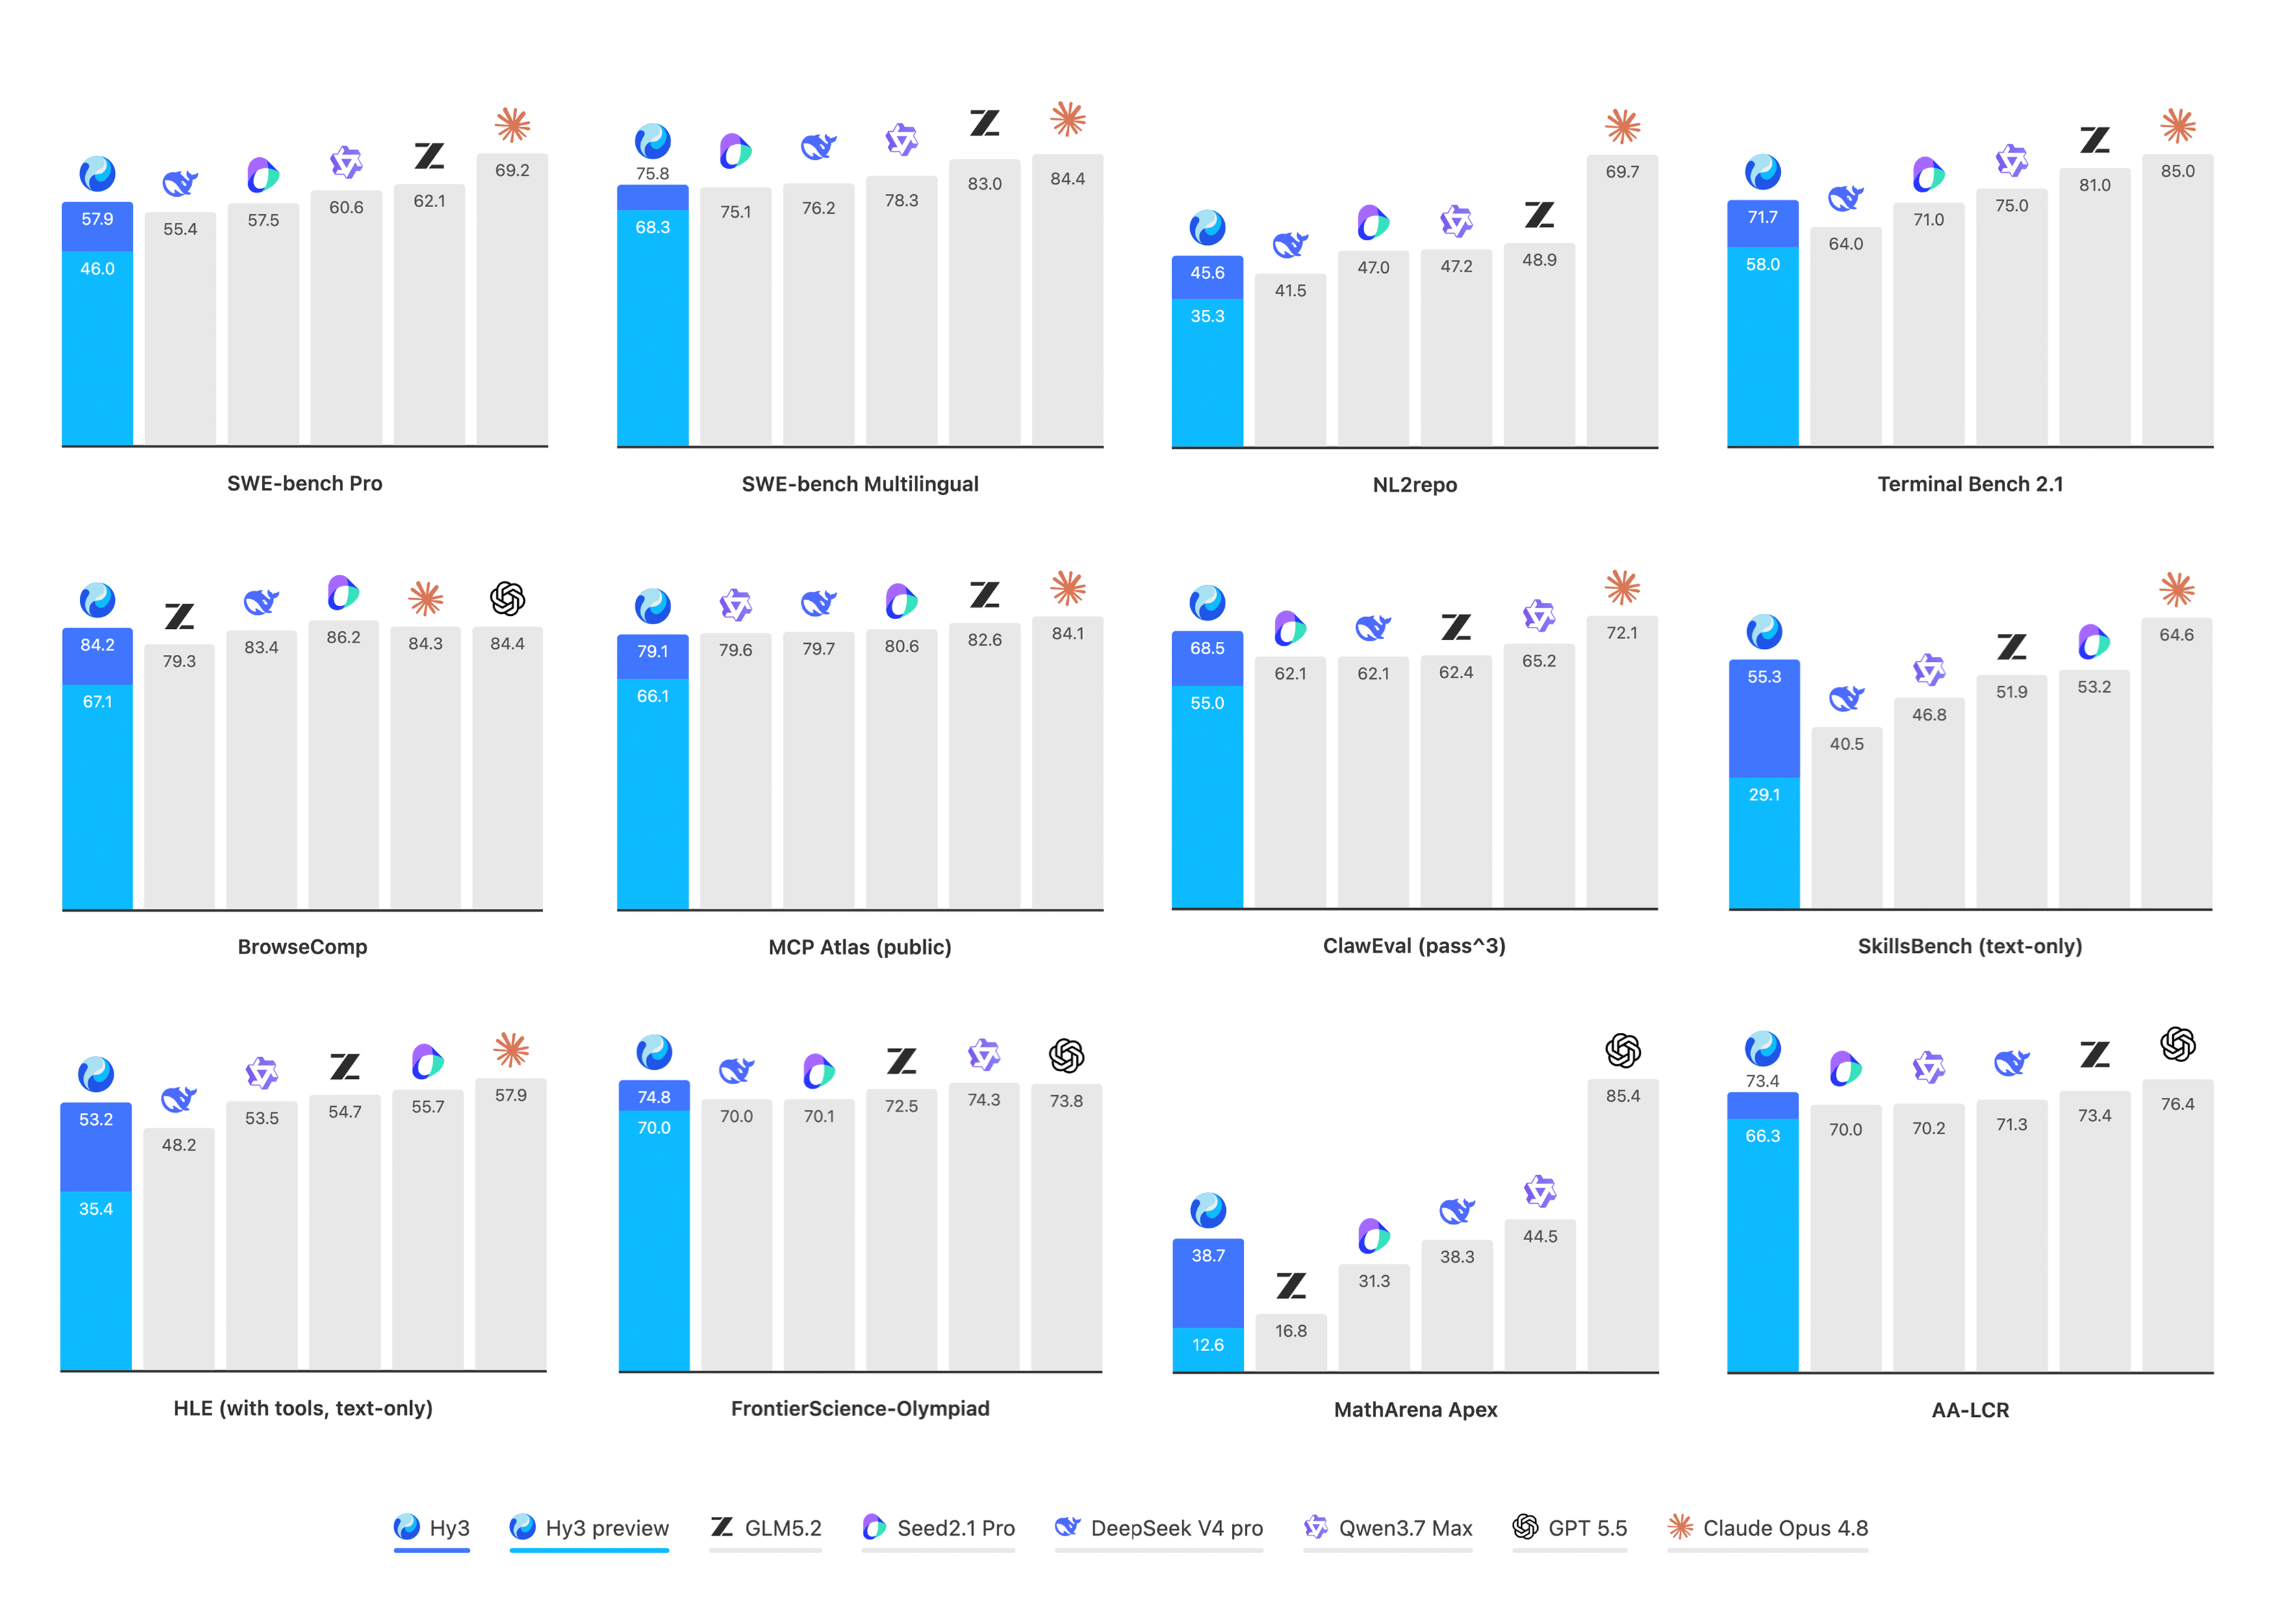
Hy3 by tencent: A 295B-A21B MoE from Tencent. It improves over its predecessor across all metrics. Most notable, however, is the license change: While the previous version (covered in Artifacts 21) used a custom and rather restrictive license, Tencent switched to Apache 2 for this release. The model was also able to proof a 50 year old math problem (with a dedicated harness and Sol as a judge, although it is unclear how important the latter really is).腾讯的 Hy3:腾讯推出的 295B-A21B MoE 模型。它在所有指标上都优于其前身。然而,最值得注意的是许可协议的变更:虽然之前的版本(在 Artifacts 21 中介绍过)使用了自定义且相当严格的许可,但腾讯在此次发布中改用了 Apache 2 许可。该模型还能够证明一个 50 年前的数学问题(使用了专门的测试框架和 Sol 作为评判,尽管后者究竟有多重要尚不清楚)。
Laguna-S-2.1 by poolside: Poolside quickly rose out of nowhere to become a frequent guest at Artifacts, marking its third appearance in three consecutive months. S2.1 is a newly pre- and post-trained version of the 118B-A8B MoE that fits on a DGX Spark, which brought it a lot of attention. Poolside also adopted the OpenMDW license, which is an Apache 2.0-like free license but has better legal backing for AI models specifically. The company also goes into more detail in its blog, which includes all the evaluation trajectories. This is a lot of transparency for an open model release!Poolside 的 Laguna-S-2.1:Poolside 迅速崛起,成为 Artifacts 的常客,这是它连续三个月第三次亮相。S2.1 是 118B-A8B MoE 的新预训练和后训练版本,可在 DGX Spark 上运行,这引起了广泛关注。Poolside 还采用了 OpenMDW 许可,这是一种类似 Apache 2.0 的免费许可,但专门为 AI 模型提供了更好的法律保障。该公司还在其博客中提供了更多细节,包括所有的评估轨迹。对于一个开放模型发布来说,这具有很高的透明度!
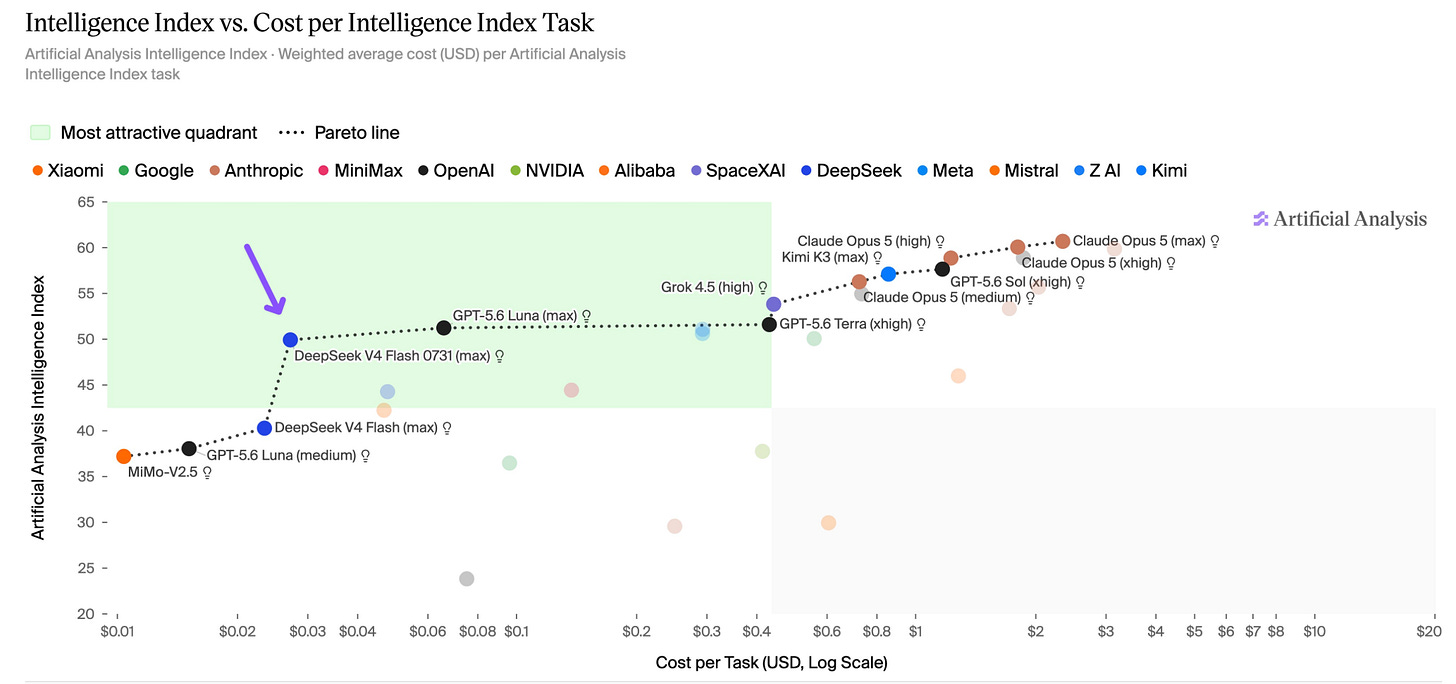
DeepSeek-V4-Flash-0731 by deepseek-ai: Just one day after OpenAI has dropped the prices of their smallest model by 80%, the whale dropped an update to their V4 Flash model, beating Luna at the pareto frontier. The bigger model is not updated yet, so it remains to be seen where it will land in terms of performance. For the initial V4 releases, the Flash version was the star of the show in terms of performance per parameter, while Pro was rather underwhelming.DeepSeek-ai 的 DeepSeek-V4-Flash-0731:就在 OpenAI 将其最小模型价格下调 80% 的一天后,这家巨头更新了其 V4 Flash 模型,在帕累托前沿击败了 Luna。更大的模型尚未更新,因此其性能表现尚待观察。对于最初的 V4 发布,Flash 版本在单位参数性能方面表现最为亮眼,而 Pro 版本则表现平平。
Kimi-K3 by moonshotai: This is the biggest open model release in some time, and we covered it in a separate post and a podcast episode. It was released under a noncommercial license, requiring inference and fine-tuning providers to enter into a commercial agreement. Kevin Xu and Graham Webster argue in a post that these licenses enable potential future government action against US entities doing business with Chinese AI companies:Moonshot AI 的 Kimi-K3:这是近期规模最大的开放模型发布,我们在单独的文章和播客剧集中对此进行了介绍。它是在非商业许可下发布的,要求推理和微调提供商签订商业协议。Kevin Xu 和 Graham Webster 在一篇文章中指出,这些许可可能会促使未来政府对与中国 AI 公司开展业务的美国实体采取行动:
But if a US company needs a contract with Moonshot to provide the inference tokens that Kimi K3 generates, the picture looks different. Some of the policy tools US officials and others have debated as potential levers to restrict Chinese open model use would more clearly apply.但如果一家美国公司需要与 Moonshot 签订合同来提供 Kimi K3 生成的推理 Token,情况就不同了。美国官员和其他人讨论过的一些作为限制中国开放模型使用潜在手段的政策工具,将能更明确地适用。
Models模型
General Purpose通用目的
LongCat-2.0 by meituan-longcat: The Chinese DoorDash is back again. This time, the company released another big MoE with 1.6T parameters. While the model itself is not the most capable for its size beyond benchmarks, it was trained entirely on Ascend 910s, making it the first non-Huawei, non-toy model trained entirely on Chinese accelerators. Other Chinese chips are mostly used for inference (if at all).美团 LongCat 的 LongCat-2.0:中国的“DoorDash”又回来了。这次,该公司发布了另一个拥有 1.6T 参数的大型 MoE。虽然该模型本身在基准测试之外的性能并非同规模中最强,但它完全是在昇腾 910 上训练的,使其成为第一个完全在国产加速器上训练的非华为、非玩具模型。其他国产芯片大多仅用于推理(如果使用的话)。
Laguna-XS-2.1 by poolside: An update to the small (33B-A3B) MoE from Poolside.Poolside 的 Laguna-XS-2.1:Poolside 小型(33B-A3B)MoE 的更新版。
Motif-3-Beta by Motif-Technologies: A preview of a 314B-A13B MoE by the Korean Motif. This is by far the company’s most ambitious model, as it is considerably larger and introduces some architectural innovations like GDLA and mHC.Motif-Technologies 的 Motif-3-Beta:韩国 Motif 公司 314B-A13B MoE 的预览版。这是该公司迄今为止最雄心勃勃的模型,规模大得多,并引入了 GDLA 和 mHC 等架构创新。
Apertus-v1.5-70B by swiss-ai: A continued pre-train of the fully open-source Apertus 1.0, using 2T more tokens.Swiss-AI 的 Apertus-v1.5-70B:完全开源的 Apertus 1.0 的持续预训练版本,使用了额外的 2T Token。
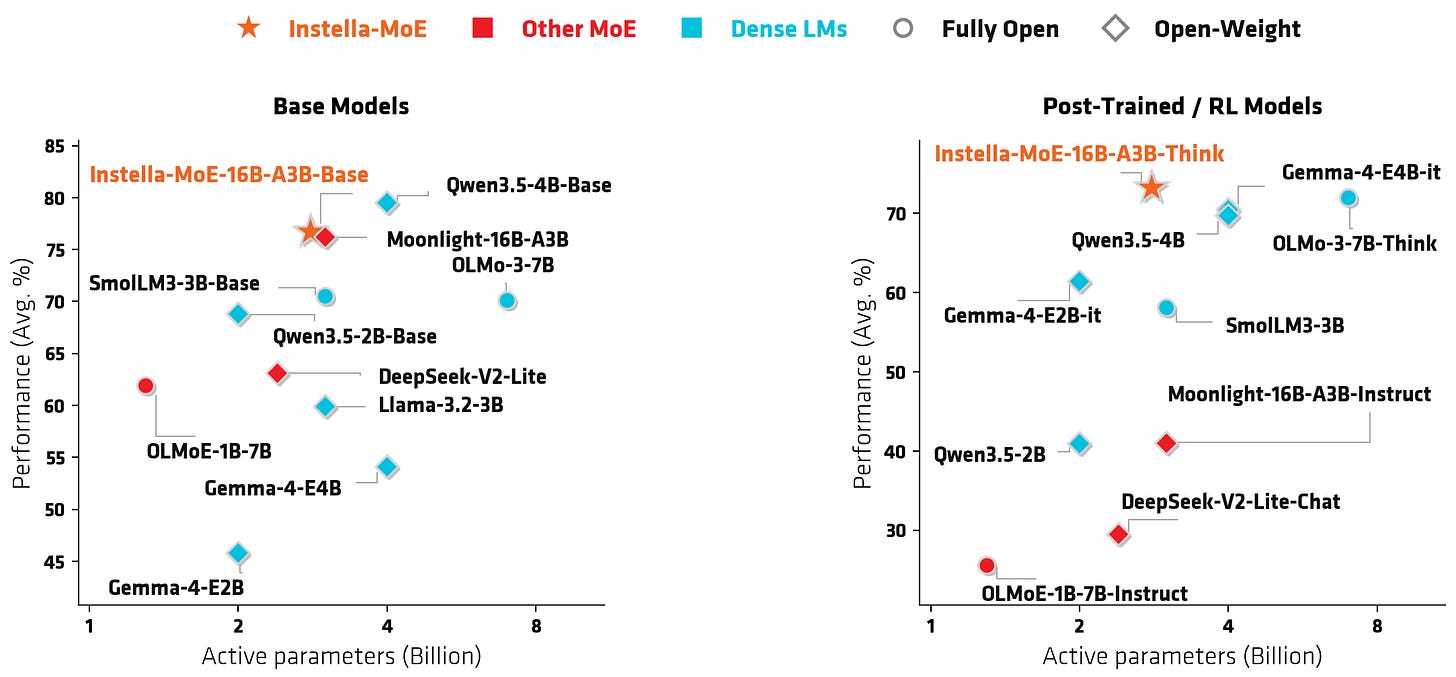
Instella-MoE-16B-A3B-Think by amd: A 16B-A3B MoE trained by AMD on Instinct cards. AMD also provides all the different stages, from the base to the SFT checkpoints, as well as MidTrain and DPO.AMD 的 Instella-MoE-16B-A3B-Think:由 AMD 在 Instinct 卡上训练的 16B-A3B MoE。AMD 还提供了从基础模型到 SFT 检查点,以及 MidTrain 和 DPO 的所有不同阶段。