AWS Architecture BlogAWS 架构博客
Reducing Text2SQL latency with parameterized query templates利用参数化查询模板降低 Text2SQL 延迟
If your Text2SQL system takes 25-30 seconds to respond, user engagement drops significantly. For teams scaling beyond pilot projects, this latency gap between a working demo and a production-ready tool is the biggest barrier to adoption. Without caching, every question triggers a Large Language Model (LLM) call to generate SQL, and those calls introduce challenges: unpredictable response times, throttling limits, and token costs that grow linearly with traffic. Parameterized query templates provide an intelligent caching layer that in our production deployment, reduced end-to-end latency by 80% and cut token consumption by over 50%, turning a slow prototype into a responsive production system. In this post, we walk through the architecture behind this approach, covering the implementation details, performance results, and lessons learned from running a Text2SQL system in production.如果您的 Text2SQL 系统需要 25-30 秒才能响应,用户参与度会显著下降。对于那些规模超出试点项目的团队而言,从功能演示到生产级工具之间的这种延迟差距,是应用推广的最大障碍。在没有缓存的情况下,每一个问题都会触发大语言模型 (LLM) 调用来生成 SQL,而这些调用会带来诸多挑战:不可预测的响应时间、限流限制,以及随流量线性增长的 Token 成本。参数化查询模板提供了一种智能缓存层,在我们的生产部署中,它将端到端延迟降低了 80%,并将 Token 消耗减少了 50% 以上,从而将缓慢的原型转变为响应迅速的生产系统。在本文中,我们将深入探讨该方法背后的架构,涵盖实现细节、性能结果以及在生产环境中运行 Text2SQL 系统的经验教训。
When you move AI applications from pilot to production, you need solutions that scale under real traffic and perform consistently. Traditional caching strategies, storing expensive computations once and serving them many times, don’t translate directly to generative AI. End users rarely phrase the same question the same way, context varies between sessions, and outputs depend on small input variations. Yet the underlying principle (caching) still holds value. Rather than abandoning caching entirely, the key is finding the right abstraction layer where similar requests can share cached results.当您将 AI 应用从试点推向生产时,需要能够在真实流量下扩展并保持稳定性能的解决方案。传统的缓存策略(即存储一次昂贵的计算结果并多次使用)并不能直接应用于生成式 AI。最终用户很少以完全相同的方式提出相同的问题,上下文在不同会话间也会有所不同,输出结果也依赖于微小的输入差异。然而,其基本原理(缓存)仍然具有价值。与其完全放弃缓存,关键在于找到合适的抽象层,让相似的请求能够共享缓存结果。
Solution overview解决方案概述
We applied the solution described in the following section to a system where business users query operational databases using natural language. You ask questions like “What were total sales in Q3?” or “Show me top performing products this month?” and the system generates SQL queries, executes them against the database, and returns results in conversational format. The system translates natural language to SQL using Amazon Bedrock foundation models, while AWS Lambda orchestrates the workflow. You can see a basic overview of used architectural components in Diagram 1.我们将下文描述的解决方案应用于一个业务用户使用自然语言查询运营数据库的系统。您提出诸如“第三季度的总销售额是多少?”或“显示本月表现最好的产品”之类的问题,系统会生成 SQL 查询,在数据库上执行它们,并以对话格式返回结果。该系统使用 Amazon Bedrock 基础模型将自然语言转换为 SQL,同时由 AWS Lambda 编排工作流程。您可以在图 1 中看到所用架构组件的基本概览。
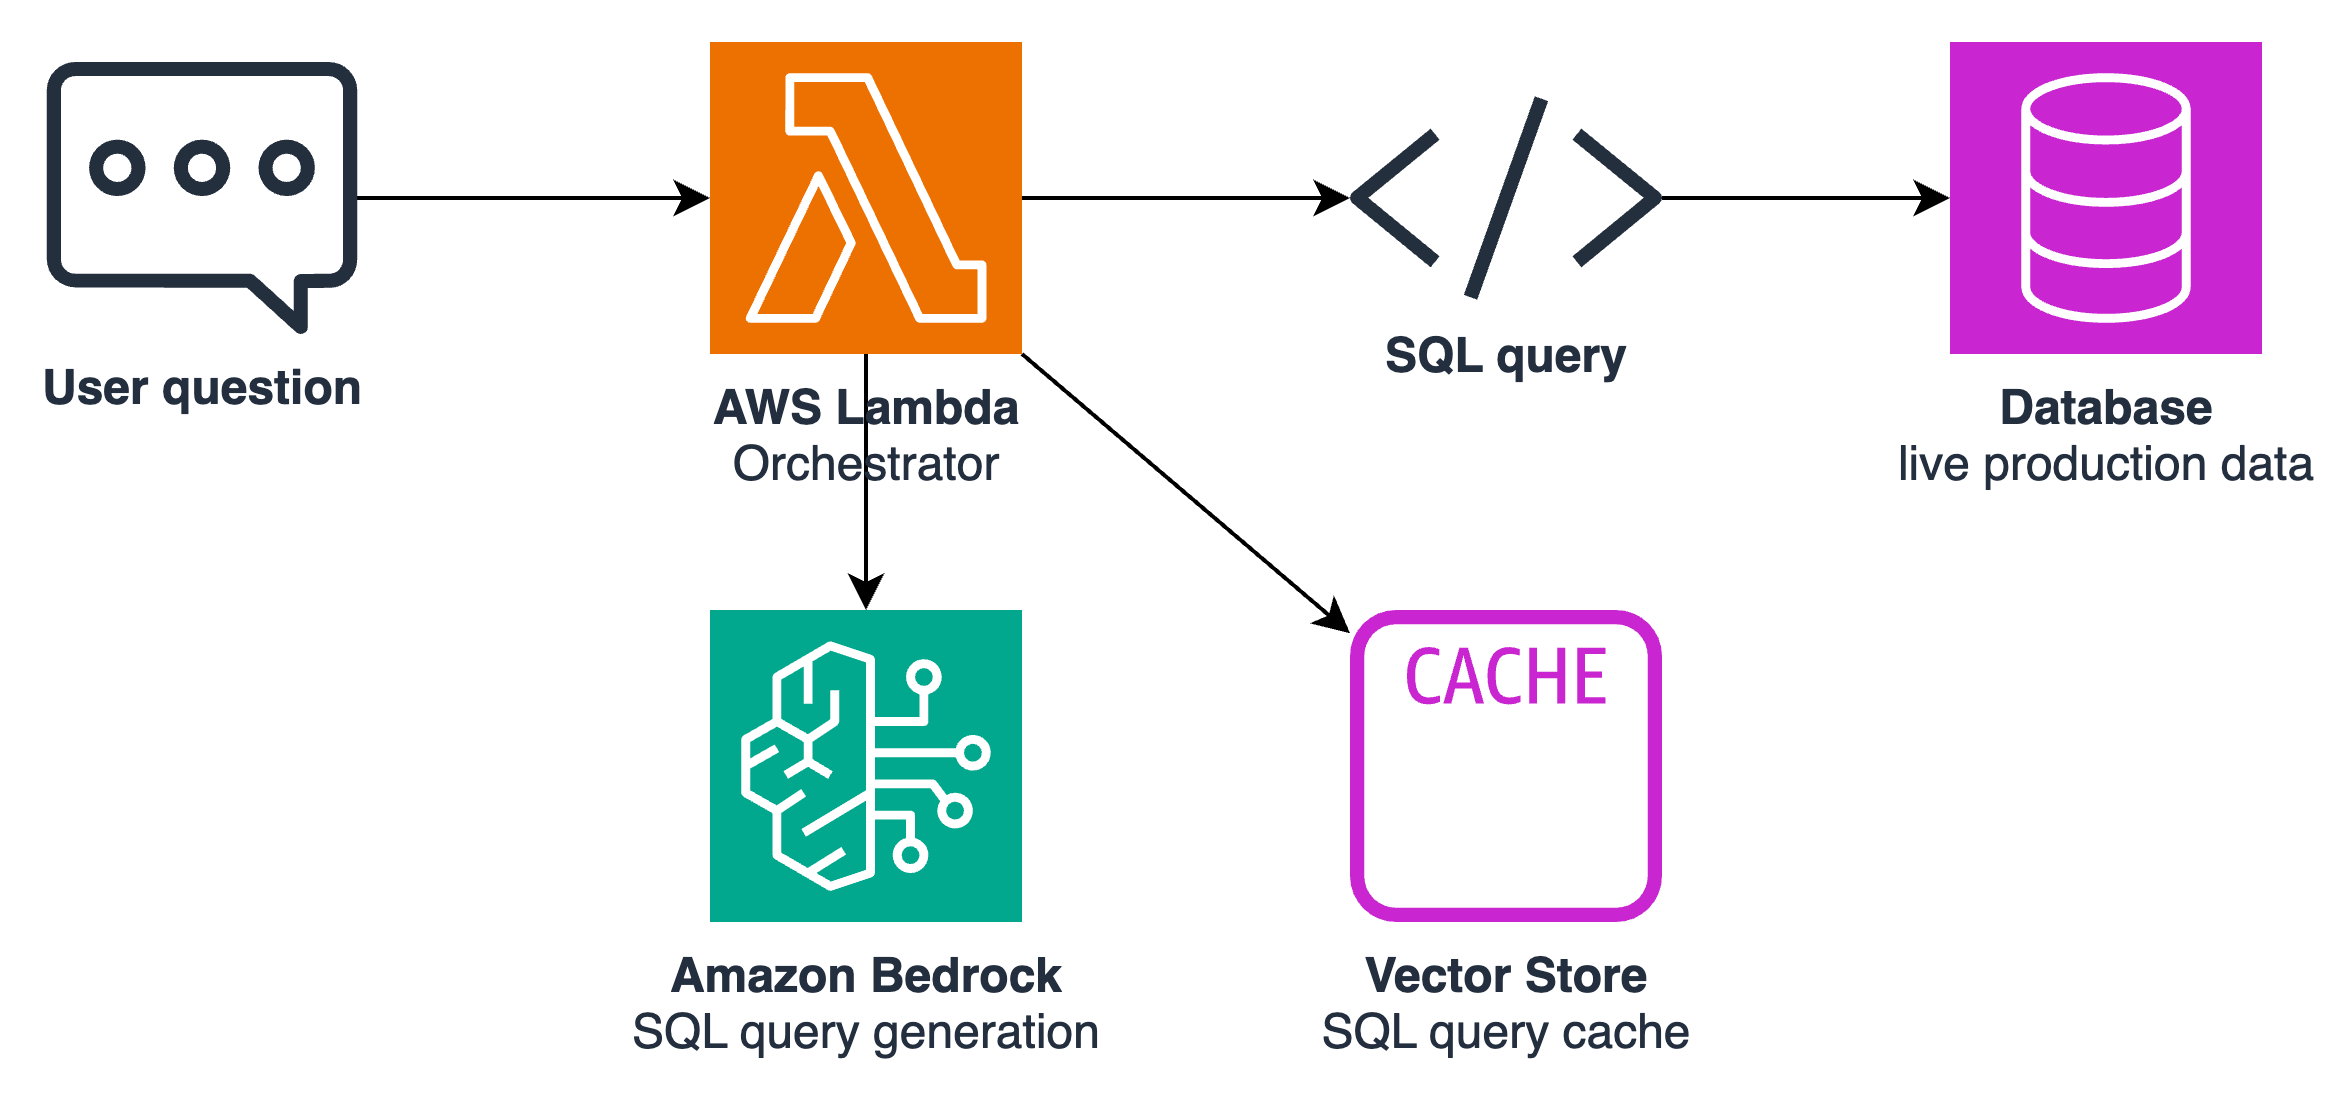
Figure 1 — Solution overview architecture图 1 — 解决方案架构概览
During the initial implementation phase, the approach with generating and executing SQL queries for user questions on the fly worked well. Response quality was high, and users found the interface intuitive. After these positive results, we started looking into scaling the solution for production traffic. Preserving accuracy was the main priority. Experiments with smaller, faster models didn’t provide a good trade-off between query quality and latency reduction. The accuracy degradation wasn’t acceptable for our system.在最初的实施阶段,针对用户问题即时生成并执行 SQL 查询的方法效果良好。响应质量很高,用户也觉得界面直观。在获得这些积极成果后,我们开始研究如何将该解决方案扩展到生产流量。保持准确性是首要任务。使用更小、更快的模型进行实验,并未在查询质量和延迟降低之间提供良好的权衡。对于我们的系统而言,准确性的下降是不可接受的。
This led us to explore alternative approaches, and caching naturally came to mind. Caching user question and answer pairs is the most straightforward option, but it has a fundamental limitation: underlying data changes constantly. An answer about Q3 sales cached today becomes incorrect as soon as new transactions are recorded. The cache would need constant invalidation, undermining its purpose.这促使我们探索替代方案,缓存自然而然地浮现在脑海中。缓存“用户问题-答案”对是最直接的选择,但它有一个根本性的局限:底层数据在不断变化。今天缓存的关于第三季度销售额的答案,一旦有新的交易记录,就会变得不准确。缓存需要不断失效,这反而违背了其初衷。
Caching the SQL query instead solves this problem. A query like:缓存 SQL 查询本身可以解决这个问题。像下面这样的查询:
SELECT SUM(revenue) FROM sales WHERE quarter = 'Q3'SELECT SUM(revenue) FROM sales WHERE quarter = 'Q3'
always fetches fresh data when executed, regardless of when it was cached. Structured Query Language (SQL) captures the user’s intent in a structured, deterministic form that remains valid even as data evolves. It also happens to target the most time and token consuming step in the pipeline, since generating SQL queries requires sending full schema context and examples to a frontier model.无论何时缓存,执行时总是能获取最新数据。结构化查询语言 (SQL) 以一种结构化的、确定性的形式捕捉了用户的意图,即使数据发生演变,它依然有效。此外,它恰好针对了流水线中最耗时、最耗 Token 的步骤,因为生成 SQL 查询需要将完整的模式上下文和示例发送给前沿模型。
Analyzing the generated queries revealed an opportunity to go further. Many queries follow the same structure, different only in their filter values. A question about Q3 sales produces:对生成的查询进行分析后,我们发现了进一步优化的机会。许多查询遵循相同的结构,仅在过滤值上有所不同。关于第三季度销售额的问题会生成:
SELECT SUM(revenue) FROM sales WHERE quarter = 'Q3'
while Q2 sales produce:而第二季度销售额的问题会生成:
SELECT SUM(revenue) FROM sales WHERE quarter = 'Q2'SELECT SUM(revenue) FROM sales WHERE quarter = 'Q2'
The same pattern appeared across product lookups, date ranges, and category filters. This led to the templating approach: instead of caching complete queries, we generalize them into templates with placeholders. A single template now covers an entire family of questions:同样的模式出现在产品查找、日期范围和类别过滤中。这引出了模板化方法:我们不再缓存完整的查询,而是将其泛化为带有占位符的模板。现在,单个模板可以覆盖一整类问题:
SELECT SUM(revenue) FROM sales WHERE quarter='{quarter}'SELECT SUM(revenue) FROM sales WHERE quarter='{quarter}'
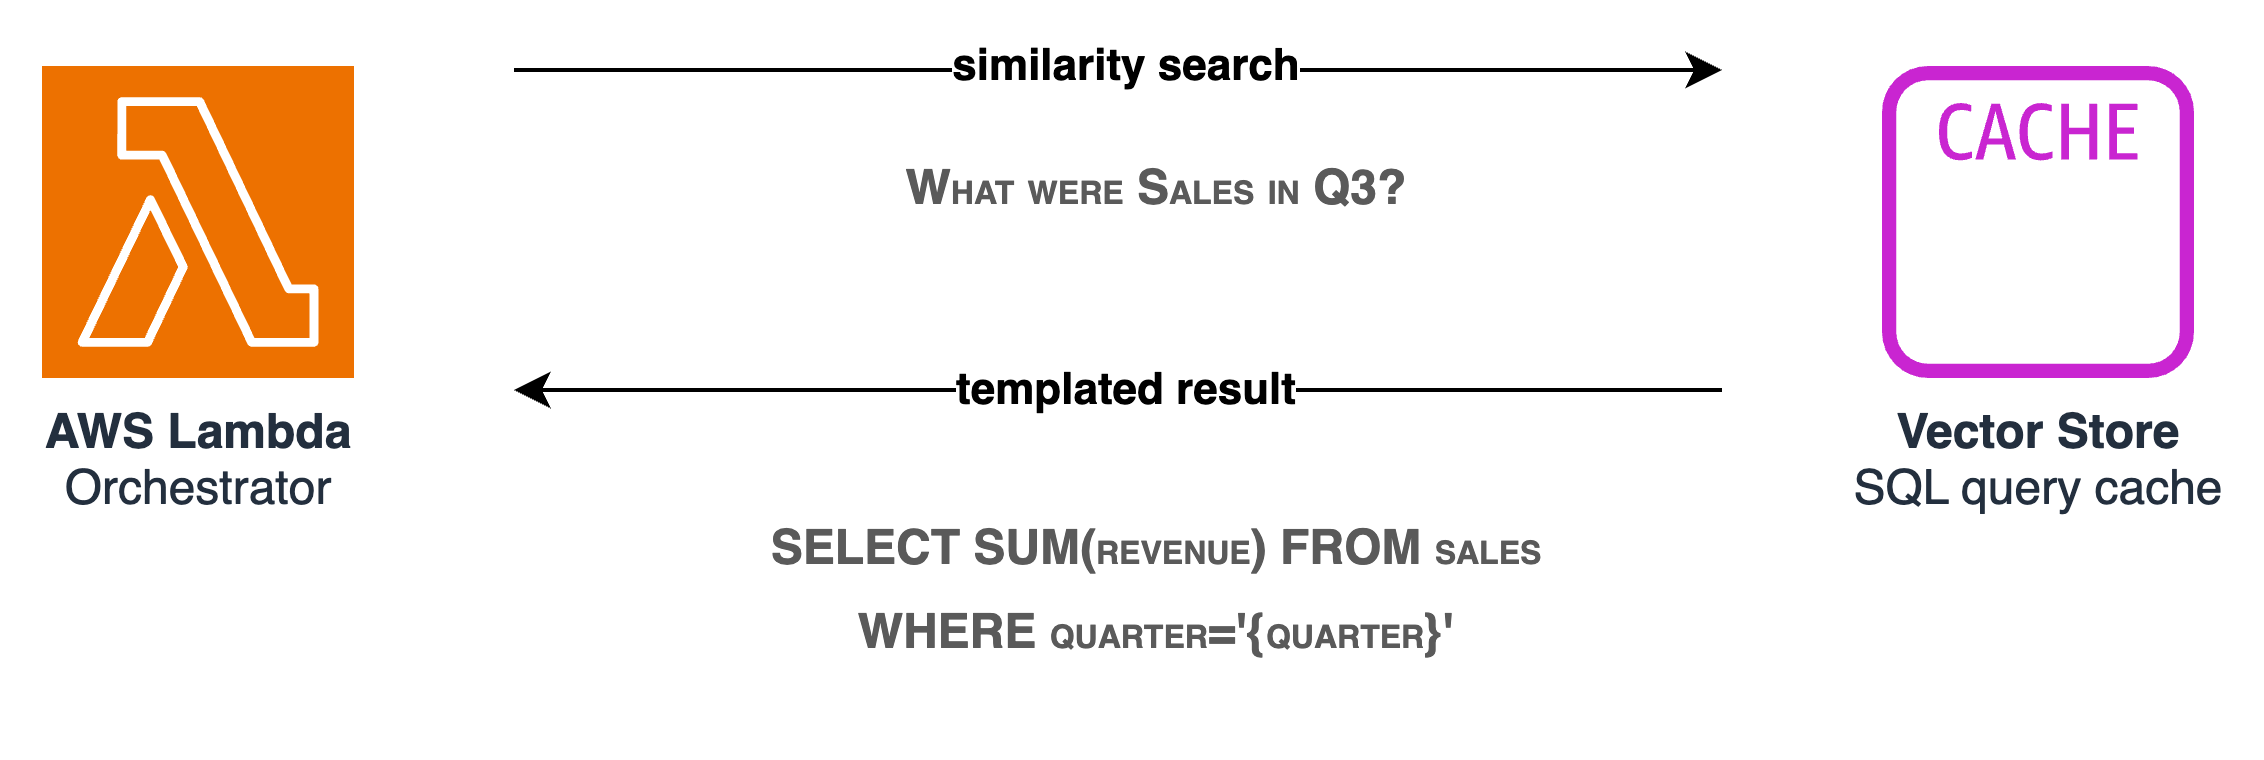
Figure 2 — Templated SQL query cache hit图 2 — 模板化 SQL 查询缓存命中
Templating solves the limited reusability of plain user question, but still leaves a challenge: how do you match an incoming question to the right template when users phrase things differently? “Show me Q3 sales” and “What were sales in Q3?” ask for the same data but share few words. Traditional string matching or keyword lookup would miss these connections. We address this by storing each template alongside a vector embedding of its original question. When a new question arrives, we compute its embedding and perform semantic similarity search against the cache. Because embeddings capture meaning rather than surface wording, both phrasings map to the same template with high confidence. If a match is found above a confidence threshold, we extract entities from the question using lightweight named entity recognition, fill the template placeholders, and execute the query directly, bypassing the LLM entirely. In Diagram 2, you can see the flow of a cache hit.模板化解决了普通用户问题重用性有限的问题,但仍留下了一个挑战:当用户措辞不同时,如何将传入的问题匹配到正确的模板?“显示第三季度销售额”和“第三季度的销售额是多少?”询问的是相同的数据,但共享的词汇很少。传统的字符串匹配或关键字查找会错过这些联系。我们通过将每个模板与其原始问题的向量嵌入一起存储来解决这个问题。当新问题到来时,我们计算其嵌入,并针对缓存执行语义相似度搜索。由于嵌入捕捉的是含义而非表面措辞,两种说法都能以高置信度映射到同一个模板。如果匹配结果超过了置信度阈值,我们就会使用轻量级命名实体识别从问题中提取实体,填充模板占位符,并直接执行查询,完全绕过 LLM。在图 2 中,您可以看到缓存命中的流程。
For questions without matching templates, the system falls back to full LLM generation. It then generalizes the newly generated query into a template, pairs it with the question’s embedding, and adds it to the cache. This creates a self-improving system where cache coverage grows organically as more query patterns are encountered.对于没有匹配模板的问题,系统会回退到完整的 LLM 生成。随后,它会将新生成的查询泛化为模板,将其与问题的嵌入配对,并添加到缓存中。这创造了一个自我改进的系统,随着遇到更多查询模式,缓存覆盖范围会自然增长。
Walkthrough – Text2SQL pipeline演练 – Text2SQL 流水线
The following sections describe each step of the template caching pipeline. Each user’s question flows through entity extraction, template retrieval, and SQL query execution. Cache misses trigger full LLM generation, with new queries feeding back into the cache. The following diagram shows the complete flow of a user question through the newly introduced caching layer.以下章节描述了模板缓存流水线的每个步骤。每个用户的问题都会经过实体提取、模板检索和 SQL 查询执行。缓存未命中会触发完整的 LLM 生成,新查询会反馈到缓存中。下图显示了用户问题通过新引入的缓存层的完整流程。
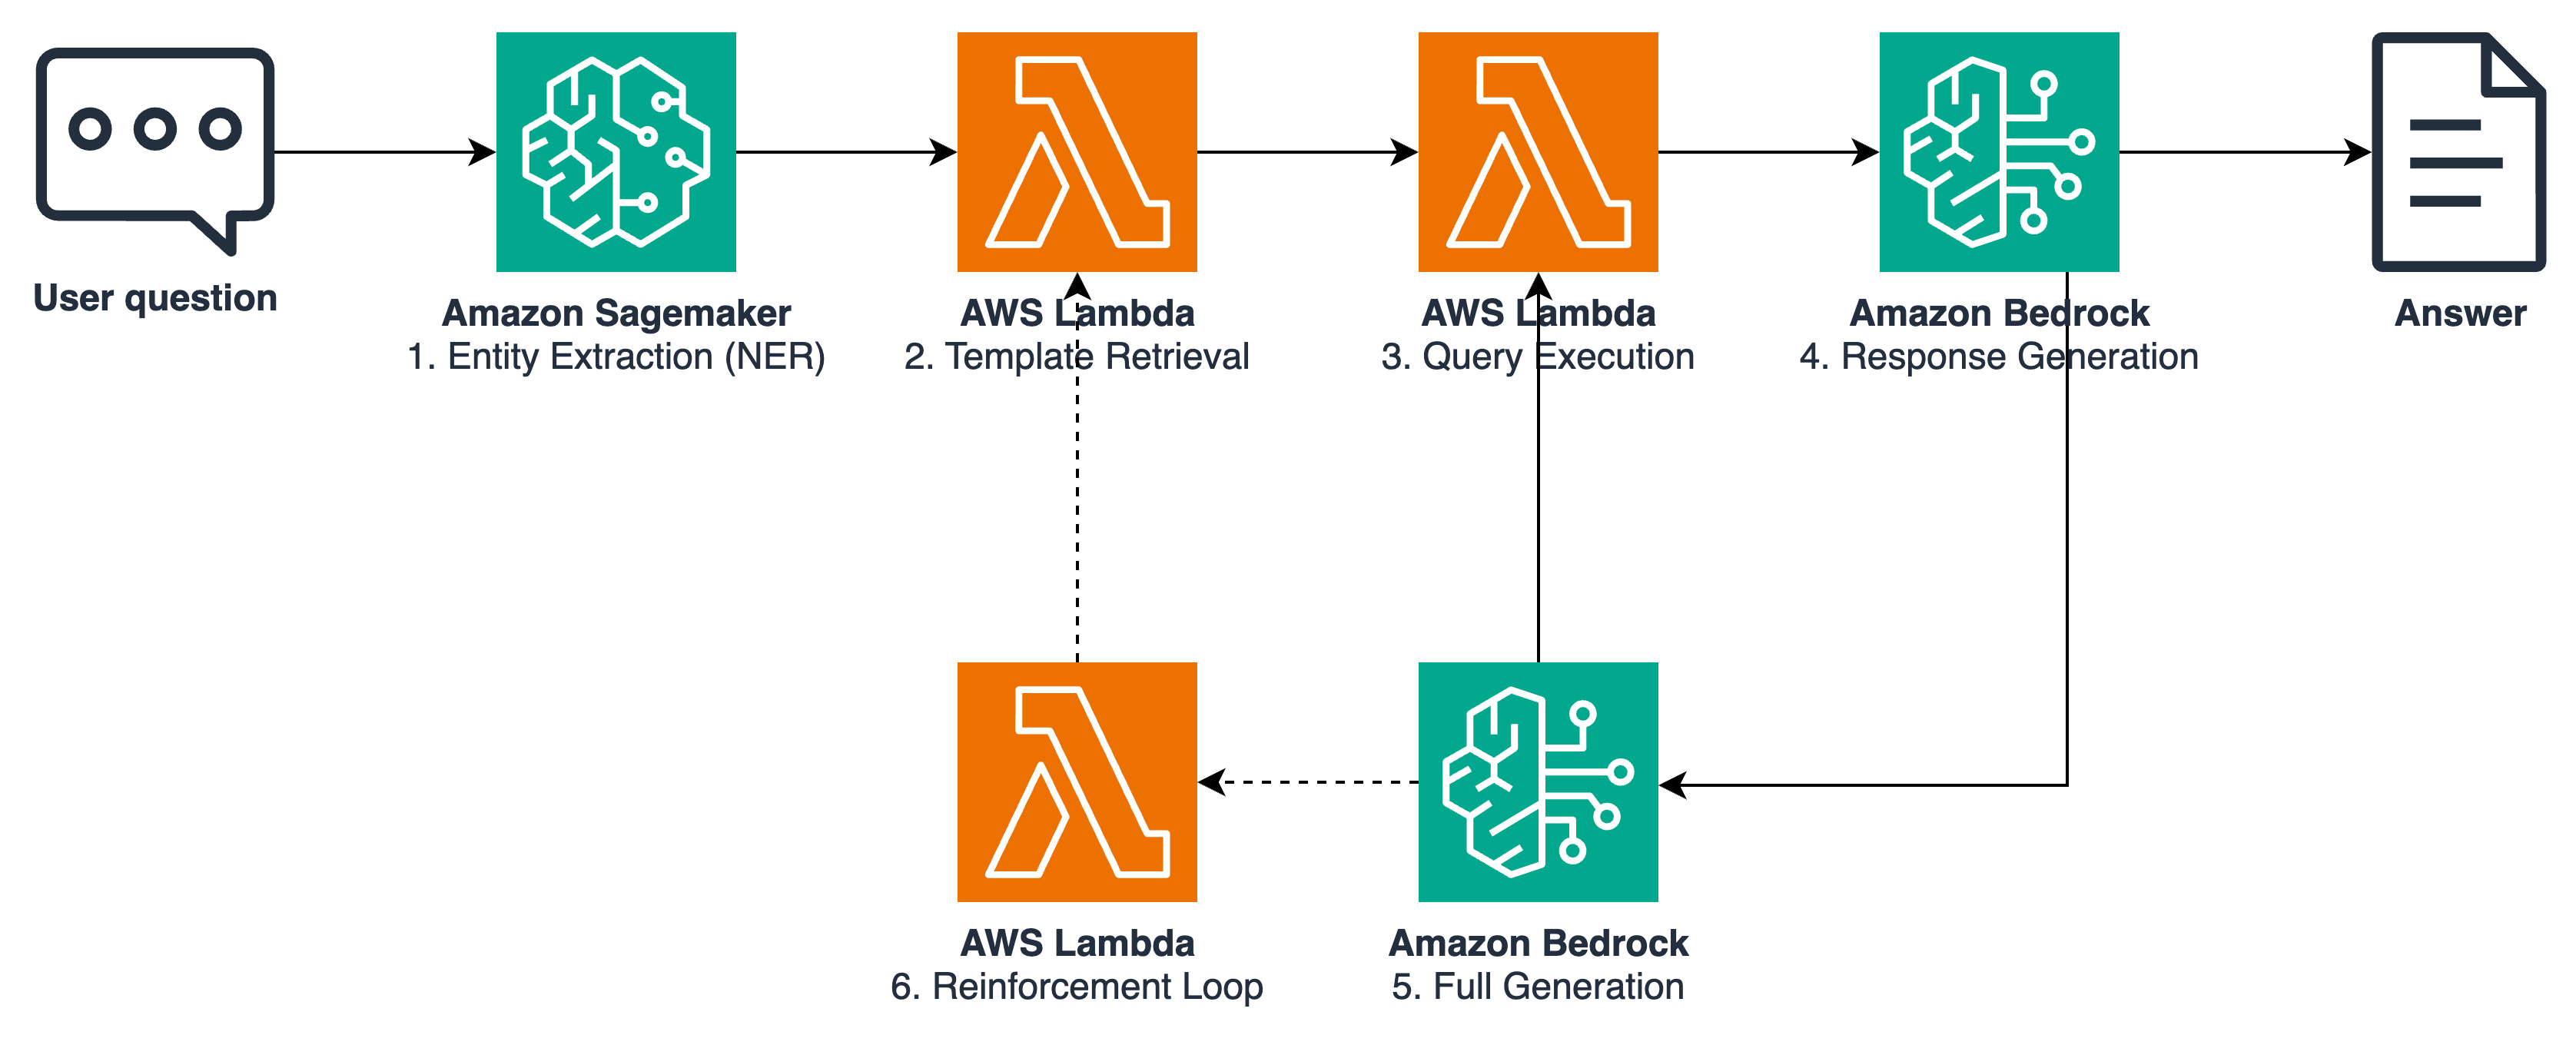
Figure 3 — Text2SQL pipeline with template caching layer图 3 — 带有模板缓存层的 Text2SQL 流水线
1. Entity extraction1. 实体提取
After a user submits a question, the system performs entity recognition to extract named entities and values. This step considers not only the current question but also conversation history, current date, and user preferences. This context helps resolve ambiguous references like “last month” or “my region”. Using a lightweight model like Amazon Nova 2 Lite or a custom-trained named entity recognition (NER) model, we identify entities such as dates (“Q3 2024”), names (“Product X”), categories (“electronics”), and numeric values (“top 10”). The system stores these extracted entities separately and uses them later to fill out template placeholders.用户提交问题后,系统会执行实体识别以提取命名实体和数值。此步骤不仅考虑当前问题,还考虑对话历史、当前日期和用户偏好。这种上下文有助于解析诸如“上个月”或“我的区域”等模糊引用。使用 Amazon Nova 2 Lite 等轻量级模型或自定义训练的命名实体识别 (NER) 模型,我们识别出日期(“2024 年第三季度”)、名称(“产品 X”)、类别(“电子产品”)和数值(“前 10 名”)等实体。系统将这些提取出的实体单独存储,并在稍后用于填充模板占位符。
2. Template retrieval through semantic search2. 通过语义搜索进行模板检索
The system converts the user’s question into an embedding vector using the same embedding model used during cache population. This vector queries the template cache through semantic similarity search, returning the closest matching templates above a confidence threshold. The search matches based on the question’s intent and structure rather than exact wording, so “What were Q3 sales?” and “Show me revenue for third quarter” both match the same template despite different phrasing.系统使用与缓存填充时相同的嵌入模型,将用户的问题转换为嵌入向量。该向量通过语义相似度搜索查询模板缓存,返回超过置信度阈值的最接近的匹配模板。搜索基于问题的意图和结构进行匹配,而非完全精确的措辞,因此“第三季度销售额是多少?”和“显示第三季度的收入”尽管措辞不同,但都能匹配到同一个模板。
It’s important to note that the confidence threshold governs the cache retrieval layer’s precision-recall trade-off. Set it too high and the system rejects valid, differently worded questions, forcing it to build SQL from scratch. Set it too low and loosely related templates slip through, risking confident answers built on the wrong query. The right value is domain-dependent: narrow, well-templated domains tolerate stricter thresholds, while broad or sparsely covered ones need looser ones.需要注意的是,置信度阈值决定了缓存检索层的精确率与召回率之间的权衡。如果设置得太高,系统会拒绝有效的、措辞不同的问题,从而被迫从头开始构建 SQL。如果设置得太低,关联性较弱的模板可能会混入,从而导致在错误的查询基础上得出看似确定的答案。合适的值取决于领域:狭窄且模板完善的领域可以容忍更严格的阈值,而广泛或覆盖稀疏的领域则需要更宽松的阈值。
Rather than relying on a single threshold, we suggest monitoring retrievals in production, logging matched templates and their similarity scores, so we can see when valid questions are being rejected or unrelated templates are slipping through. When embedding similarity alone doesn’t give enough precision, we added a lightweight reranking step: first we retrieve a broader set of candidate templates with a looser threshold, then re-score them with a small LLM or a specialized reranker model to select the best match. This improves precision without sacrificing recall and still costs far less than generating SQL from scratch.与其依赖单一阈值,我们建议在生产环境中监控检索情况,记录匹配的模板及其相似度分数,以便观察何时拒绝了有效问题或何时混入了不相关的模板。当仅靠嵌入相似度无法提供足够的精度时,我们增加了一个轻量级的重排序步骤:首先用更宽松的阈值检索出一组更广泛的候选模板,然后用小型 LLM 或专门的重排序模型对它们进行重新评分,以选出最佳匹配。这可以在不牺牲召回率的情况下提高精度,且成本远低于从头生成 SQL。
3. Template filling and query execution3. 模板填充与查询执行
When a matching template is found, the system maps extracted entities to template placeholders. If the template contains `{quarter}` and entity recognition extracted “Q3”, the system replaces the placeholder with the actual value. The system validates the filled SQL query for syntax correctness, then executes it directly against the database. This path bypasses the time and token intensive LLM call that generates the SQL query.当找到匹配的模板时,系统将提取的实体映射到模板占位符。如果模板包含 `{quarter}` 而实体识别提取出“Q3”,系统会将占位符替换为实际值。系统会验证填充后的 SQL 查询的语法正确性,然后直接在数据库上执行。此路径绕过了生成 SQL 查询时耗时且耗 Token 的 LLM 调用。
This design helps the system to protect against SQL injection on two levels. First, it validates each extracted entity against the expected format for its placeholder: a `{quarter}` must match a known set of values, a `{date}` must parse as a valid date, a numeric threshold must be a number. The system rejects values that do not pass validation before they ever reach the query. Second, the system fills the placeholders using parameterized database queries (prepared statements) rather than string interpolation, so the parameterized query mechanism treats entity values as data rather than executable SQL. This approach also catches entity-extraction errors, improving answer reliability beyond the security benefit.这种设计有助于系统在两个层面上防范 SQL 注入。首先,它会针对占位符的预期格式验证每个提取出的实体:`{quarter}` 必须匹配一组已知值,`{date}` 必须解析为有效日期,数值阈值必须是数字。系统会在值到达查询之前拒绝不符合验证的值。其次,系统使用参数化数据库查询(预编译语句)而非字符串插值来填充占位符,因此参数化查询机制将实体值视为数据而非可执行的 SQL。这种方法还能捕获实体提取错误,在提升安全性的同时提高了答案的可靠性。
For richer responses, the system can retrieve multiple top-K similar templates and execute them in parallel. This provides additional context and related information beyond the primary query, for example returning both: quarterly sales totals and a breakdown by product category. The parallel execution adds minimal latency while delivering more comprehensive answers.为了获得更丰富的结果,系统可以检索多个 Top-K 相似模板并并行执行它们。这提供了除主查询之外的额外上下文和相关信息,例如同时返回季度销售总额和按产品类别细分的销售额。并行执行增加了极小的延迟,但提供了更全面的答案。
4. Response generation and validation4. 响应生成与验证
After executing the query, the system sends results to a response generation model. This model has two jobs, both handled in a single call: judge whether the results answer the question, and, if they do, summarize them into a conversational response.执行查询后,系统将结果发送到响应生成模型。该模型有两个任务,均在单次调用中完成:判断结果是否回答了问题,如果回答了,则将其总结为对话式响应。
The sufficiency check is driven by instructions in the prompt. The system instructs the model to confirm that the results are non-empty, that they contain the fields the question asked about, and that they cover every part of the question rather than only some of it. For example, if a user asks for “Q3 sales by region” but the matched template returns only a Q3 total, the results are incomplete, and the model is instructed to flag them as insufficient instead of answering with partial data. The model returns this judgment as a structured signal alongside its response, so the pipeline can branch on it deterministically. This step helps verify that users receive accurate answers rather than partial or misleading information from imperfect template matches.充分性检查由提示词中的指令驱动。系统指示模型确认结果非空,确认结果包含问题所询问的字段,并确认结果覆盖了问题的每个部分,而非仅覆盖一部分。例如,如果用户询问“按区域划分的第三季度销售额”,但匹配的模板仅返回了第三季度总额,则结果是不完整的,模型会被指示将其标记为“不充分”,而不是用部分数据回答。模型将此判断作为结构化信号与响应一起返回,以便流水线能够确定性地进行分支处理。此步骤有助于验证用户获得的是准确答案,而不是由不完美的模板匹配产生的局部或误导性信息。
This task is fundamentally simpler than SQL generation: instead of writing structured code from natural language, the model only needs to read tabular data and either summarize it or declare it insufficient. Because the task is simple, a smaller, faster model like Claude Haiku 4.5 can handle it effectively.这项任务从根本上比 SQL 生成更简单:模型不需要将自然语言编写为结构化代码,只需要读取表格数据并将其总结或声明为不充分。由于任务简单,像 Claude Haiku 4.5 这样的小型快速模型就能有效地处理它。
On a cache hit, there is only a single lightweight LLM call, which improves both latency and cost thanks to the smaller model. On a cache miss, the model flags the template results as insufficient and the system falls back to full SQL generation before producing the answer, for three calls in total: the sufficiency check, the SQL generation, and the response. That is one call more than the uncached pipeline, so misses carry extra latency. The trade-off is favorable because the added call is the cheap sufficiency check rather than another expensive generation, and because at a healthy hit rate the savings on hits outweigh the penalty on misses.在缓存命中时,只有一次轻量级 LLM 调用,由于模型较小,这既改善了延迟又降低了成本。在缓存未命中时,模型会将模板结果标记为不充分,系统会回退到完整的 SQL 生成,总共进行三次调用:充分性检查、SQL 生成和响应生成。这比未缓存的流水线多了一次调用,因此未命中会带来额外的延迟。这种权衡是划算的,因为增加的调用是廉价的充分性检查,而不是另一次昂贵的生成,而且在保持健康的命中率时,命中带来的节省超过了未命中带来的惩罚。
5. Fallback to full generation5. 回退至完整生成
If no template matches the confidence threshold, or if the validation step determines that cached results are insufficient, the system falls back to the standard Text2SQL pipeline. The question, along with the full context, goes to the foundation model for SQL generation. The generated query executes against the database, and results return to the user. Importantly, this newly generated query doesn’t disappear. It enters the reinforcement loop.如果没有任何模板达到置信度阈值,或者验证步骤确定缓存结果不充分,系统将回退到标准的 Text2SQL 流水线。问题连同完整的上下文会被发送到基础模型进行 SQL 生成。生成的查询在数据库上执行,结果返回给用户。重要的是,这个新生成的查询不会消失,它会进入强化循环。
6. Reinforcement loop for cache growth6. 用于缓存增长的强化循环
After a successful fallback generation, the system evaluates whether the new query should join the template cache. If the query executed successfully and returned valid results, it becomes a candidate for templating. The system generalizes the query by replacing specific values with placeholders and computes the original question’s embedding. It then adds this new template-question pair to the vector store, expanding cache coverage. Over time, the cache grows organically to cover query patterns specific to your users’ actual needs.在成功的回退生成后,系统会评估新查询是否应该加入模板缓存。如果查询执行成功并返回了有效结果,它就成为模板化的候选对象。系统通过将特定值替换为占位符来泛化查询,并计算原始问题的嵌入。然后,它将这个新的“模板-问题”对添加到向量存储中,从而扩大缓存覆盖范围。随着时间的推移,缓存会自然增长,以覆盖用户实际需求中特有的查询模式。
Results and performance gains结果与性能提升
The figures in this section come from our production deployment but treat them as an illustrative model rather than a fixed benchmark. Exact token counts and latencies depend on your schema size, prompt design, model choice, and query mix. What generalizes is the direction of the improvement, not the specific numbers.本节中的数据来自我们的生产部署,但请将其视为说明性模型而非固定基准。确切的 Token 数量和延迟取决于您的模式大小、提示词设计、模型选择和查询组合。具有普适性的是改进的方向,而非具体的数字。
The dominant cost and latency in a Text2SQL request come from a single step: generating the SQL query. That call sends the user question, conversation history, the database schema, few-shot examples, and domain guidance to a powerful LLM such as Anthropic Claude Sonnet, which is needed to produce reliable queries. In our deployment this prompt runs on the order of 60K input tokens for a few hundred output tokens, and takes roughly 15-20 seconds. Every other step: embedding, vector search, template filling, and query execution, is minor by comparison. Entity recognition, runs on a dedicated NER model hosted on Amazon SageMaker AI rather than an LLM, adding negligible cost and latency next to SQL generation. Optimizing the pipeline is therefore mostly about avoiding that one expensive call.Text2SQL 请求中的主要成本和延迟来自一个步骤:生成 SQL 查询。该调用将用户问题、对话历史、数据库模式、少样本示例和领域指南发送给强大的 LLM(如 Anthropic Claude Sonnet),这是生成可靠查询所必需的。在我们的部署中,此提示词的输入 Token 量级约为 6 万,输出 Token 几百个,耗时约 15-20 秒。相比之下,其他所有步骤(嵌入、向量搜索、模板填充和查询执行)都微不足道。实体识别运行在托管于 Amazon SageMaker AI 上的专用 NER 模型上,而非 LLM,与 SQL 生成相比,其成本和延迟几乎可以忽略不计。因此,优化流水线主要就是为了避免那一次昂贵的调用。
On a cache hit, the system skips SQL generation entirely. What remains is response summarization, turning the query results into a conversational answer, which runs on a small model with a small prompt (on the order of a couple thousand input tokens). Because summarization is needed on both, the cached and uncached paths, a cache hit does not remove tokens completely, but it eliminates the 60K-token generation call, cutting token consumption by roughly 90% on that request.在缓存命中时,系统完全跳过了 SQL 生成。剩下的工作是响应总结,即将查询结果转化为对话式答案,这运行在一个小型模型上,且提示词较小(输入 Token 量级为几千个)。由于总结在缓存和未缓存路径中都需要,缓存命中并不能完全消除 Token 消耗,但它消除了 6 万个 Token 的生成调用,使该请求的 Token 消耗降低了约 90%。
This 90% is the saving on a single cache hit. Overall cost depends on the average across all requests, since cache misses still incur the full generation cost. At the roughly 60% hit rate we observed in production, the blended reduction across all traffic comes out above 50%. Latency follows the same pattern. An uncached request spends 15-20 seconds on the SQL call, retries and error handling included, then a few more seconds on summarization, putting a typical request in the 25-30 second range. On a cache hit, retrieval, template filling, and execution finish well under a second, and the remaining time is almost entirely the summarization call. That brings the end-to-end cache-hit path under 5 seconds, roughly an 80% reduction, or about 6x faster. It also pinpoints where the residual latency comes from: not the cache lookup, but the one LLM call that still has to run.这 90% 是单次缓存命中带来的节省。总体成本取决于所有请求的平均值,因为缓存未命中仍然会产生完整的生成成本。在我们生产中观察到的约 60% 的命中率下,所有流量的综合成本降低超过了 50%。延迟遵循同样的模式。未缓存的请求在 SQL 调用上花费 15-20 秒(包括重试和错误处理),然后在总结上花费几秒钟,使典型请求处于 25-30 秒的范围内。在缓存命中时,检索、模板填充和执行在 1 秒内完成,剩余时间几乎全部用于总结调用。这使端到端的缓存命中路径在 5 秒内完成,大约降低了 80%,即速度提升了约 6 倍。这也指出了剩余延迟的来源:不是缓存查找,而是必须运行的那一次 LLM 调用。
These per-request gains only matter if cache hits are common. In our production system the hit rate reached about 60% after roughly two weeks of active use, though the achievable rate depends heavily on the domain and how repetitive the queries are. Cache misses run the full pipeline plus the small sufficiency check, so they cost marginally more than a purely uncached request, which means the net gain comes entirely from hits. As the reinforcement loop keeps adding templates, the hit rate climbs and both the cost and latency benefits continue to compound.这些单次请求的收益只有在缓存命中频繁时才有意义。在我们的生产系统中,经过约两周的积极使用后,命中率达到了约 60%,尽管可实现的命中率在很大程度上取决于领域以及查询的重复性。缓存未命中会运行整个流水线外加小型的充分性检查,因此它们的成本比纯粹未缓存的请求稍微多一点,这意味着净收益完全来自命中。随着强化循环不断添加模板,命中率会攀升,成本和延迟的收益也会持续叠加。
Conclusion结论
Scaling AI applications to production often requires rethinking traditional optimization strategies. In this post, we demonstrated how template-based caching addresses the latency and cost challenges of Text2SQL systems without sacrificing accuracy. By caching SQL query structures rather than complete responses and using semantic similarity to match user questions to templates, the system can bypass expensive LLM inference calls. The reinforcement loop ensures cache coverage grows organically based on actual usage patterns.将 AI 应用扩展到生产环境通常需要重新思考传统的优化策略。在本文中,我们展示了基于模板的缓存如何在不牺牲准确性的前提下解决 Text2SQL 系统的延迟和成本挑战。通过缓存 SQL 查询结构而非完整响应,并利用语义相似度将用户问题与模板匹配,系统可以绕过昂贵的 LLM 推理调用。强化循环确保缓存覆盖范围根据实际使用模式自然增长。
In practice, this means: 6x faster response times on cache hits, inference costs decrease proportionally to your cache hit rate, and accuracy remains high because templates are generated by the most capable models. The patterns we covered, such as semantic matching, output generalization, entity extraction, and continuous improvement loops, extend beyond Text2SQL to any AI system where similar requests should produce structurally similar outputs.在实践中,这意味着:缓存命中时的响应速度提升 6 倍,推理成本随缓存命中率的提高而相应降低,并且由于模板是由能力最强的模型生成的,准确性依然保持在高水平。我们所涵盖的模式(如语义匹配、输出泛化、实体提取和持续改进循环)不仅适用于 Text2SQL,也适用于任何相似请求应产生结构相似输出的 AI 系统。
Further reading延伸阅读
Generating value from enterprise data: Best practices for Text2SQL and generative AI从企业数据中创造价值:Text2SQL 和生成式 AI 的最佳实践
Enterprise-grade natural language to SQL generation using LLMs: Balancing accuracy, latency, and scale使用 LLM 进行企业级自然语言转 SQL 生成:平衡准确性、延迟和规模
Build a robust text-to-SQL solution generating complex queries, self-correcting, and querying diverse data sources构建强大的 Text-to-SQL 解决方案:生成复杂查询、自我修正并查询多样化数据源
Text-to-SQL solution powered by Amazon Bedrock由 Amazon Bedrock 提供支持的 Text-to-SQL 解决方案
Amazon S3 Vectors: First cloud storage with native vector support at scaleAmazon S3 Vectors:首个在大规模环境下提供原生向量支持的云存储
Amazon Nova 2 LiteAmazon Nova 2 Lite