Artificial Intelligence人工智能
Multi-agent social intelligence with Strands Agents and Amazon Bedrock基于Strands Agents和Amazon Bedrock的多智能体社交情报系统
Your prospects leave trails across multiple sources: a founder asks “What should I use for X?” in r/SaaS while their product launches on Hacker News. Stack Overflow questions spike. A GitHub repo crosses 2,400 stars. Each signal alone is noise, but correlated across sources, they reveal a prospect ready to buy. Multi-agent systems built with Strands Agents and Amazon Bedrock AgentCore can automate this social intelligence at scale.潜在客户在多个来源留下痕迹:创始人在r/SaaS问“我应该用什么做X?”的同时,产品在Hacker News发布。Stack Overflow问题激增。GitHub仓库超过2400颗星。单个信号只是噪音,但跨来源关联起来,就揭示了准备购买的潜在客户。用Strands Agents和Amazon Bedrock AgentCore构建的多智能体系统可以规模化自动化这种社交情报。
Thrad.ai is building the advertising infrastructure for AI, introducing paid ads in LLMs. Their platform lets chat interfaces monetize through ads and lets brands advertise in them. They faced an especially signal-rich version of this problem. Tracking these patterns manually doesn’t scale, and generic outreach lacks the context that makes email worth opening. Thrad.ai’s sales team spent 30 to 45 minutes researching each lead across six sources before writing one outreach email.Thrad.ai正在构建AI的广告基础设施,在LLM中引入付费广告。他们的平台让聊天界面通过广告盈利,也让品牌在其中投放广告。他们面临着一个信号特别丰富的版本:手动追踪这些模式无法扩展,而通用外联缺乏让邮件值得打开的上下文。Thrad.ai的销售团队在写一封外联邮件之前,要花30到45分钟跨六个来源研究每个线索。
A single AI agent can’t solve this: the signal diversity is too broad, the source APIs too varied, and the analysis too nuanced for one model to handle well. With multi-agent orchestration, you assign each source to a specialist agent, then fuse results through a dedicated analysis agent that spots cross-source patterns.单个AI智能体解决不了这个问题:信号多样性太广,来源API太多样,分析太细微,一个模型难以妥善处理。通过多智能体编排,你把每个来源分配给一个专家智能体,然后通过一个专门的分析智能体融合结果,发现跨来源模式。
This post shows how Thrad.ai deployed a multi-agent system with Strands Agents and Amazon Bedrock AgentCore that automates the pipeline from prospect discovery through personalized email generation. The post compares two orchestration patterns (Swarm and Graph) with head-to-head benchmarks on latency, cost, and email quality. You’ll also learn how the system scores prospects using weighted criteria, intent classification, and temporal decay, plus governance controls for production deployment.本文展示Thrad.ai如何用Strands Agents和Amazon Bedrock AgentCore部署了一个多智能体系统,从潜在客户发现到个性化邮件生成自动完成整个流程。文章比较了两种编排模式(Swarm和Graph),在延迟、成本和邮件质量上做了直接对比。你还会学到系统如何用加权标准、意图分类和时间衰减来评分潜在客户,以及生产部署的治理控制。
You can apply these patterns to competitive intelligence, candidate sourcing, and market research. A companion repository is available to help you follow along.你可以将这些模式应用于竞争情报、候选人搜寻和市场研究。附带了配套代码库供你参考。
Prerequisites先决条件
This post assumes familiarity with Python, AWS Cloud Development Kit (AWS CDK) basics, and large language model (LLM) concepts.本文假设你熟悉Python、AWS Cloud Development Kit (AWS CDK)基础和大语言模型概念。
- AWS account with Amazon Bedrock access (Claude Sonnet 4.6 model enabled) and Amazon Bedrock AgentCore.具有Amazon Bedrock访问权限的AWS账户(启用Claude Sonnet 4.6模型)和Amazon Bedrock AgentCore。
- Permissions for Amazon DynamoDB, AWS Lambda, AWS Secrets Manager, and AWS CDK.Amazon DynamoDB、AWS Lambda、AWS Secrets Manager和AWS CDK的权限。
- Python 3.12+, Node.js 18+Python 3.12+、Node.js 18+
strands-agents>=1.25.0,bedrock-agentcore[strands-agents]>=1.2.1,pydantic>=2.12.5strands-agents>=1.25.0、bedrock-agentcore[strands-agents]>=1.2.1、pydantic>=2.12.5- Approximately 60 minutes for hands-on deployment, approximately $3 to $5 (Amazon Bedrock model invocations).动手部署大约60分钟,大约3到5美元(Amazon Bedrock模型调用)。
- Important: Deployed resources (DynamoDB tables, Lambda functions, AgentCore services) incur charges while running. Complete the Clean up steps after finishing the tutorial to avoid ongoing costs.注意:部署的资源(DynamoDB表、Lambda函数、AgentCore服务)在运行时会产生费用。完成教程后请执行清理步骤以避免持续费用。
Note: You can follow this post conceptually without deploying. To run the code yourself, you’ll need the preceding prerequisites.注:你可以仅从概念上理解本文而不部署。如果想自己运行代码,需要满足前面的先决条件。
Full setup guide: README.md完整设置指南:README.md
Solution overview解决方案概述
With this architecture illustrated in Figure 1, you can turn raw social signals into personalized outreach automatically. Four specialized agents handle discovery, enrichment, scoring, and email generation, each with its own tools and strict output validation.通过图1所示的架构,你可以自动将原始社交信号转化为个性化外联。四个专业智能体分别负责发现、丰富、评分和邮件生成,每个都有自己的工具和严格的输出验证。
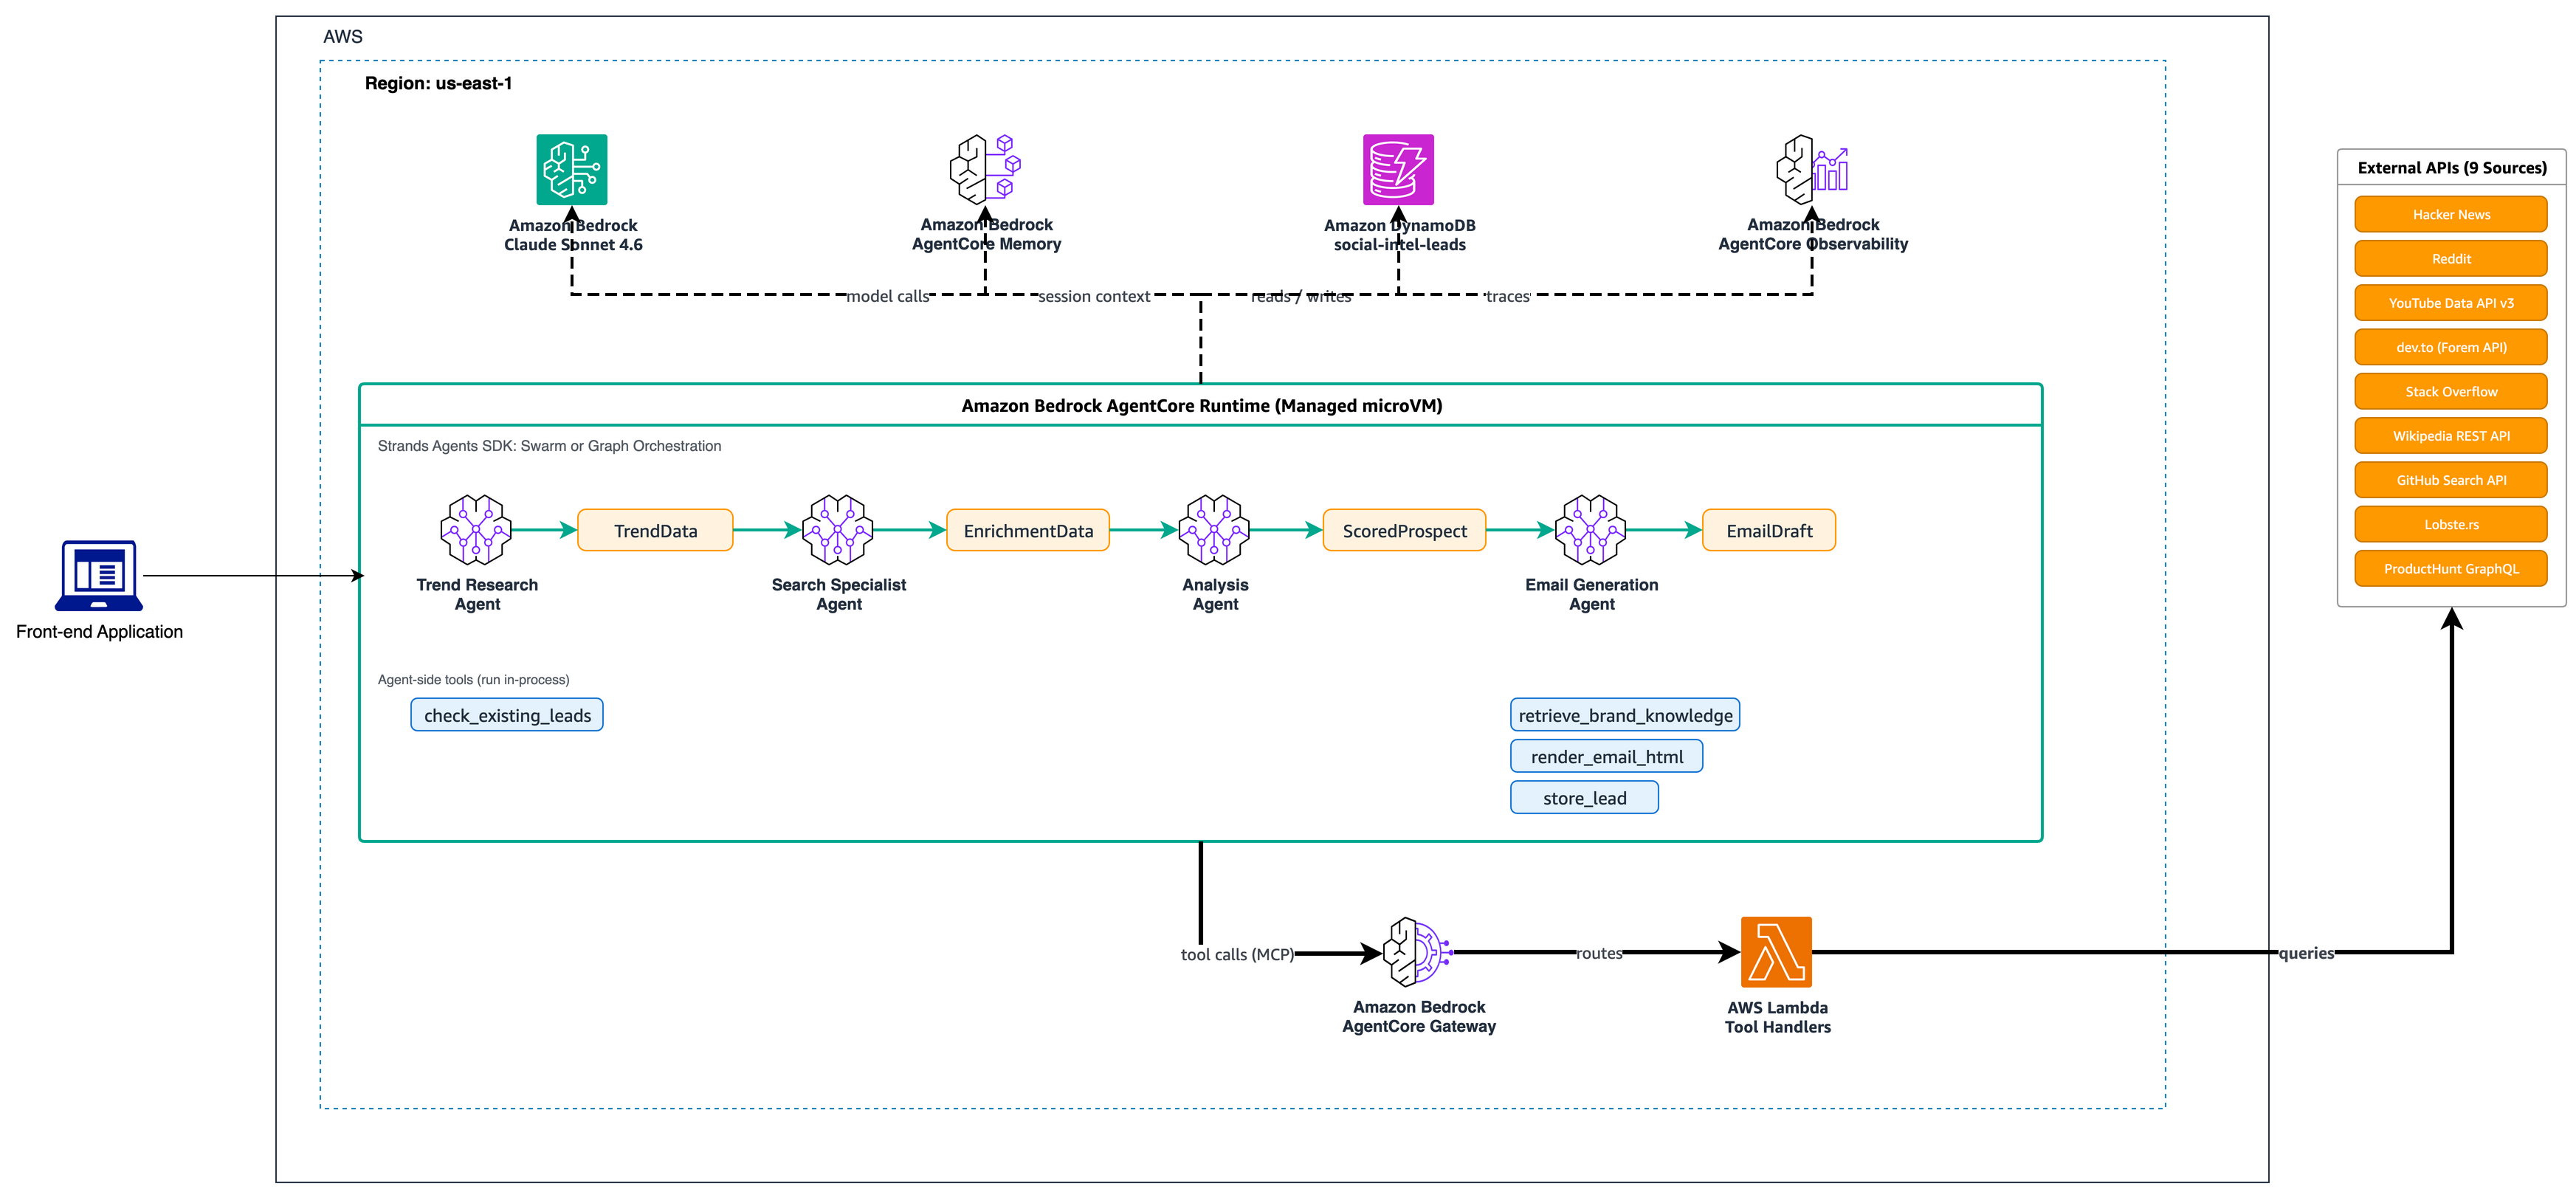
Four-agent pipeline with Amazon Bedrock AgentCore Runtime, Gateway, Memory, and Observability基于Amazon Bedrock AgentCore Runtime、Gateway、Memory和Observability的四智能体流水线
The following table describes each agent’s role, tools, and the AgentCore services it uses.下表描述每个智能体的角色、工具以及它使用的AgentCore服务。
| Agent | Role | Tools | AgentCore Services |
| Trend Research | Discovers trending launches and buying-intent signals | Hacker News, YouTube, dev.to, ProductHunt, Reddit, Stack Overflow APIs | Runtime, Gateway |
| Search Specialist | Enriches prospect profiles with context | Wikipedia, GitHub, Lobste.rs, Stack Overflow APIs | Runtime, Gateway |
| Analysis | Scores prospect-trend pairs (0-100) | Scoring engine, ICP matcher | Runtime, Memory |
| Email Generation | Drafts personalized outreach | Brand knowledge retrieval, lead storage | Runtime, Gateway, Memory |
Two agents start data collection in parallel. The Trend Research Agent queries six sources (Hacker News, YouTube, dev.to, ProductHunt, Reddit, Stack Overflow) for trending launches and buying-intent signals. Meanwhile, the Search Specialist Agent enriches each prospect via Wikipedia, GitHub, Lobste.rs, and Stack Overflow.两个智能体并行启动数据收集。趋势研究智能体查询六个来源(Hacker News、YouTube、dev.to、ProductHunt、Reddit、Stack Overflow)寻找流行发布和购买意图信号。同时,搜索专家智能体通过Wikipedia、GitHub、Lobste.rs和Stack Overflow丰富每个潜在客户。
After both agents finish, the Analysis Agent scores each prospect-trend pair from 0 to 100 using Claude Sonnet 4.6 on Amazon Bedrock. The agents use a global inference profile (global.anthropic.claude-sonnet-4-6), which routes requests to the nearest available Region. This avoids region-specific model ARNs in IAM policies and streamlines multi-Region deployment. High-scoring prospects flow to the Email Generation Agent, which drafts personalized email messages tied to specific trends and validates each draft against brand guidelines.两个智能体完成后,分析智能体用Amazon Bedrock上的Claude Sonnet 4.6对每个潜在客户-趋势对打分(0到100)。智能体使用全局推理配置文件(global.anthropic.claude-sonnet-4-6),将请求路由到最近可用区域。这避免了IAM策略中特定区域模型ARN,简化了多区域部署。高分潜在客户流向邮件生成智能体,该智能体草拟针对特定趋势的个性化邮件,并根据品牌指南验证每封草稿。
Each agent owns one responsibility, one set of tools, and one Pydantic-validated output contract. Pydantic is a Python data validation library that enforces type-safe schemas at runtime. If an agent returns data in the wrong shape, the system catches it before the next agent sees it.每个智能体负责一项职责、一套工具、一个经Pydantic验证的输出合同。Pydantic是一个Python数据验证库,在运行时执行类型安全的模式。如果智能体返回的数据格式不对,系统会在下一个智能体看到之前捕捉到。
The Reddit tool scans five subreddits (r/SaaS, r/startups, r/devtools, r/selfhosted, r/Entrepreneur) and uses keyword pattern matching to classify posts into four intent categories: recommendation-seeking, competitor frustration, product launch, and purchase intent. When a Hacker News launch also appears in a Reddit “what tool should I use?” thread, that prospect scores higher.Reddit工具扫描五个子版块(r/SaaS、r/startups、r/devtools、r/selfhosted、r/Entrepreneur),用关键词模式匹配将帖子分为四类意图:寻求推荐、竞争对手挫败、产品发布和购买意向。当一个Hacker News发布也出现在Reddit的“我该用什么工具?”的帖子中时,该潜在客户得分更高。
The scoring relies on signal triangulation: a prospect needs correlated evidence from at least two independent sources. The Trend Research Agent first calls check_existing_leads to skip prospects already in the pipeline. A trending Hacker News post with no Reddit discussion, no Stack Overflow activity, and zero GitHub stars likely reflects a promotional push. The system filters it before spending tokens on analysis.评分依赖信号三角验证:一个潜在客户需要至少两个独立来源的关联证据。趋势研究智能体首先调用check_existing_leads跳过已经在流程中的潜在客户。一个在Hacker News上流行的帖子,如果没有Reddit讨论、没有Stack Overflow活动、没有GitHub星,很可能只是推广宣传。系统在花费token分析之前将其过滤掉。
The Analysis Agent applies five weighted criteria: topical alignment (25%), timing relevance (20%), engagement potential (20%), intent signals (20%), and data quality (15%). Ideal customer profile (ICP) matching adds up to 10 bonus points for developer tools with open source presence and B2B focus. Temporal decay sharpens the score: signals under 24 hours old get 1.5x weight, signals over 7 days get 0.5x.分析智能体应用五个加权标准:主题对齐(25%)、时机相关性(20%)、互动潜力(20%)、意图信号(20%)和数据质量(15%)。理想客户画像匹配对具有开源存在和B2B焦点的开发者工具额外加最多10分。时间衰减使分数更敏锐:24小时内的信号权重1.5倍,超过7天的信号权重0.5倍。
Strands orchestration: Swarm vs. GraphStrands编排:Swarm vs. Graph
Now comes the central design decision: how do four agents coordinate? Strands Agents provides two orchestration patterns. Thrad.ai built both and compared them against the same 50-prospect workload. The following sections walk through each pattern, then present benchmark results.现在到了核心设计决策:四个智能体如何协调?Strands Agents提供了两种编排模式。Thrad.ai构建了两种,并对同一组50个潜在客户的工作负载进行了比较。以下章节分别介绍每种模式,然后给出基准测试结果。
Swarm: Autonomous handoffsSwarm:自主交接
Figure 2 illustrates how agents are passing control via the handoff_to_agent tool with shared context. In Swarm orchestration, agents pass control dynamically using a handoff_to_agent tool. The Trend Research Agent discovers prospects and hands off to Search Specialist for enrichment. Search Specialist passes to Analysis for scoring. If data is sparse, Analysis can hand back to Trend Research for additional context. Agents share a common working memory.图2展示智能体如何通过handoff_to_agent工具在共享上下文中传递控制权。在Swarm编排中,智能体使用handoff_to_agent工具动态传递控制权。趋势研究智能体发现潜在客户,交给搜索专家进行丰富。搜索专家传给分析进行评分。如果数据稀疏,分析可以交回给趋势研究获取更多上下文。智能体共享一个共同的工作记忆。
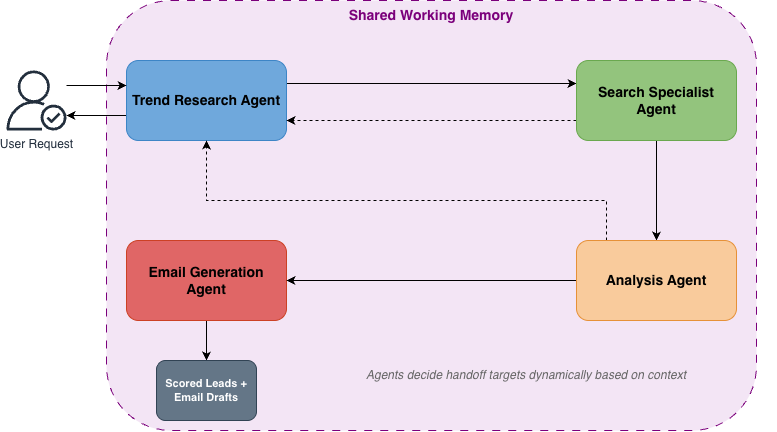
Dynamic agent-to-agent transfers with shared working memory带共享工作记忆的动态智能体间传递
Swarm agents act as self-organizing peers with shared context, where each agent decides when to hand off to a specialist. Trend Research discovers a prospect and hands off to Search Specialist for enrichment, and Search Specialist passes to Analysis for scoring.Swarm智能体作为拥有共享上下文的自主对等体运行,每个智能体决定何时交给专家。趋势研究发现一个潜在客户,交给搜索专家丰富,搜索专家传给分析评分。
If data is thin, Analysis hands back to Trend Research to receive more context. This bidirectional handoff lets agents request additional context when needed.如果数据不足,分析交回给趋势研究获取更多上下文。这种双向交接让智能体在需要时请求额外上下文。
The following code shows how to configure a Swarm with safety bounds:以下代码展示如何配置带安全边界的Swarm:
The repetitive handoff parameters matter. Without them, two agents can ping-pong across each other indefinitely. A window of 8 with a minimum of 3 unique agents forces forward progress.重复交接参数很重要。没有它们,两个智能体可能无限来回传递。窗口大小为8,最小唯一智能体数为3,强制向前推进。
Swarm works best when prospect complexity varies and agents benefit from re-engaging earlier stages. However, execution paths are harder to predict, and token consumption runs higher from handoff-reasoning overhead.当潜在客户复杂性变化且智能体需要重新参与早期阶段时,Swarm效果最好。然而,执行路径更难预测,而且由于交接推理开销,token消耗更高。
Graph: Structured workflowGraph:结构化工作流
Figure 3 illustrates how a directed graph starts with parallel research and search entry points, then converges at analysis, with a conditional edge to email. In Graph orchestration, agents follow a fixed directed workflow. Trend Research and Search Specialist run in parallel as entry points. Analysis waits for both to finish before running. A conditional edge gates Email Generation, which only runs if the prospect scores 60 or higher.图3展示一个有向图如何以并行研究和搜索入口开始,然后在分析处汇合,带有条件边指向邮件。在Graph编排中,智能体遵循固定的有向工作流。趋势研究和搜索专家作为入口并行运行。分析等待两者都完成后才运行。条件边控制邮件生成,仅在潜在客户得分60或以上时运行。
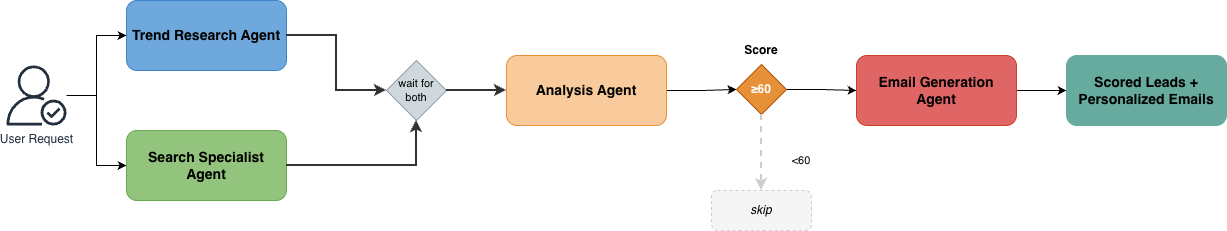
Parallel entry, all-dependencies-complete gating, and conditional score threshold并行入口、全依赖完成门控和条件分数阈值
The Graph pattern wires agents into a fixed workflow with explicit, one-way edges. Trend Research and Search Specialist run in parallel, cutting data-gathering time in half. Analysis waits for both to finish. Email runs only if the prospect scores 60 or higher, acting as a policy gate.Graph模式将智能体连接成具有显式单向边的固定工作流。趋势研究和搜索专家并行运行,将数据收集时间减半。分析等待两者完成。邮件仅在潜在客户得分60或以上时运行,充当策略门。
The following code shows how to define a Graph with parallel entry points and conditional edges:以下代码展示如何定义带有并行入口和条件边的Graph:
Graph shines when the workflow is repeatable and auditability matters. Every run follows the same path, so you can reproduce failures by replaying the same input. The limitation is that it can’t dynamically loop back without explicit feedback edges. If an agent needs more context, you’ll need to add a dedicated feedback edge in the directed acyclic graph (DAG) definition.Graph工作流可重复且审计性重要时表现最佳。每次运行都遵循相同路径,因此可以通过重放相同输入来重现失败。限制在于它无法在没有显式反馈边的情况下动态循环。如果一个智能体需要更多上下文,你需要在DAG定义中添加一个专门的反馈边。
Head-to-head results直接对比结果
Both patterns ran three times against 50 Hacker News prospects. Two reviewers scored email relevance on a 1 to 10 rubric (specificity, tone, accuracy).两种模式各运行三次,针对50个Hacker News潜在客户。两位评审员按1到10的评分标准(具体性、语气、准确性)评估邮件相关性。
| Metric | Swarm | Graph |
| Avg latency per prospect | 45s | 32s |
| P95 latency | 78s | 38s |
| Avg tokens per prospect | ~12,000 | ~8,500 |
| Email relevance (human-rated) | 8.2 | 7.6 |
| Cost per prospect (est.) | ~$0.08 | ~$0.06 |
Business impact: For a 1,000-prospect batch, Graph saves approximately 3.6 hours of processing time and $20 in token costs compared to Swarm.业务影响:对于1000个潜在客户的批次,Graph相比Swarm节省约3.6小时处理时间和20美元token成本。
Swarm produced higher-quality email messages (8.2 vs. 7.6) because agents looped back for more context when data was sparse, while Graph cost 25% less per prospect with tighter latency bounds. Thrad.ai chose Graph for nightly batch processing and Swarm for weekly deep-dives on high-value prospects.Swarm产生了更高质量的邮件(8.2 vs. 7.6),因为智能体在数据稀疏时循环获取更多上下文,而Graph每个潜在客户成本低25%,延迟更可控。Thrad.ai选择Graph用于夜间批量处理,Swarm用于每周对高价值潜在客户的深度挖掘。
How to decide: Choose Graph when the workflow is repeatable and you need predictable latency. Choose Swarm when input quality varies and agents need to adapt. You can run both in the same code base, switched by a configuration flag.如何决定:当工作流可重复且需要可预测延迟时选择Graph。当输入质量变化且智能体需要自适应时选择Swarm。你可以在同一个代码库中同时运行两者,通过配置标志切换。
Deploying on Amazon Bedrock AgentCore部署在Amazon Bedrock AgentCore上
Production workloads need session isolation, capacity management, and observability that go beyond local prototyping. Amazon Bedrock AgentCore handles these as managed services. The CDK stack (client-side orchestration code that defines your infrastructure) deploys four services using aws-cdk-lib/aws-bedrock-agentcore-alpha L2 constructs:生产工作负载需要会话隔离、容量管理和可观测性,超出了本地原型设计。Amazon Bedrock AgentCore将这些作为托管服务处理。CDK堆栈(定义基础设施的客户端编排代码)使用aws-cdk-lib/aws-bedrock-agentcore-alpha L2构造部署四个服务:
- Runtime hosts agents in isolated microVMs (lightweight virtual machines) with AWS Identity and Access Management (IAM) authentication and lifecycle controls (15-min idle timeout, 8-hour max lifetime).Runtime在隔离的微VM中托管智能体,使用IAM认证和生命周期控制(15分钟空闲超时,8小时最大生存期)。
- Gateway provides a single Model Context Protocol (MCP) endpoint for the nine tools. MCP is a standard protocol for LLM-tool communication. Agents discover tools dynamically at startup via the Strands
MCPClient.Gateway为九个工具提供单一MCP端点。MCP是LLM-工具通信的标准协议。智能体在启动时通过Strands MCPClient动态发现工具。 - Memory stores short-term context within sessions and long-term semantic data across sessions. Optional; agents degrade gracefully without it.Memory在会话内存储短期上下文,跨会话存储长期语义数据。可选的;没有它,智能体也能优雅降级。
- Observability captures distributed traces via OpenTelemetry (an open standard for telemetry data) with span-level latency and token counts. Integrates with Amazon CloudWatch and third-party services.Observability通过OpenTelemetry捕获分布式追踪,包括span级延迟和token计数。与Amazon CloudWatch和第三方服务集成。
Thrad.ai found that YouTube API calls accounted for 40% of total latency. The trace data led the team to add get_with_retry with exponential backoff to HTTP calls.Thrad.ai发现YouTube API调用占总延迟的40%。追踪数据促使团队为HTTP调用添加了带指数退避的get_with_retry。
The companion README for this blog post and AgentCore documentation provides the full CDK stack, Gateway setup, and deployment walkthrough.本文的配套README和AgentCore文档提供了完整的CDK堆栈、Gateway设置和部署步骤。
Walkthrough: A real run实际操作:一次真实运行
Here’s what a Graph run produces against the current Hacker News feed:以下是Graph针对当前Hacker News feed的输出:
Here’s an example email generated for Prospect A:下面是为潜在客户A生成的示例邮件:
Prospect A scored 88 because of cross-source signals (HN + Reddit + dev.to), 2,400 GitHub stars matching ICP criteria, and all signals under 48 hours old (1.5x temporal weight). Prospect C scored below 60 and was skipped, saving ~3,000 tokens. The Graph pattern processed all 50 prospects in under 30 minutes.潜在客户A得分88,因为跨来源信号(HN + Reddit + dev.to)、2400个GitHub星符合ICP标准、所有信号在48小时内(1.5倍时间权重)。潜在客户C得分低于60被跳过,节省大约3000个token。Graph模式在30分钟内处理完所有50个潜在客户。
What we learned我们学到的东西
Building and benchmarking both orchestration patterns revealed several insights for production multi-agent systems.构建和基准测试两种编排模式揭示了生产多智能体系统的一些见解。
Intent signals beat passive trends: Adding Reddit intent detection increased prospects scoring above 80 by 22% in our tests. A prospect asking “What tool should I use for X?” converts at higher rates than one trending passively.意图信号胜过被动趋势:在我们的测试中,添加Reddit意图检测使得分高于80的潜在客户增加了22%。问“我应该用什么做X?”的潜在客户比被动流行的转化率更高。
Temporal decay helps prevent stale outreach: Signals under 24 hours old get 1.5x weight, while signals over 7 days get 0.5x. A Stack Overflow surge from yesterday starts a conversation. One from last month is noise.时间衰减有助于避免过时的外联:24小时内的信号权重1.5倍,超过7天的信号权重0.5倍。昨天Stack Overflow流量激增可以开始对话。上个月的则是噪音。
Pick the pattern based on the job: Swarm wins on quality when data is sparse. Graph wins on cost and predictability for batch work. Running both in the same system, switched by a configuration flag, gives you flexibility without maintaining separate code bases.根据任务选择模式:Swarm在数据稀疏时在质量上胜出。Graph在成本和可预测性上适合批量工作。在同一个系统中运行两者,通过配置标志切换,让你在不必维护独立代码库的情况下灵活切换。
Governance and human-in-the-loop治理和人机协同
When agents take on more decision-making, you’ll need guardrails. The system implements controls at three levels:当智能体承担更多决策时,你需要护栏。系统在三个层面实施控制:
- Policy gates via conditional edges: The Analysis-to-Email edge checks the relevance score. The system logs prospects below 60 but skips email generation. You can extend this pattern to require human approval before email generation by adding a review node.通过条件边的策略门控:分析到邮件的边检查相关性得分。系统记录低于60的潜在客户但跳过邮件生成。你可以扩展此模式,通过添加审查节点要求在邮件生成前进行人工审批。
- Scoped tool access: Each agent receives only the tools it needs. The Email Agent gets
store_leadandretrieve_brand_knowledge. Trend Research getscheck_existing_leadsplus discovery tools. An agent can’t invoke tools outside its scope.范围化工具访问:每个智能体只获得它需要的工具。邮件智能体获得store_lead和retrieve_brand_knowledge。趋势研究获得check_existing_leads和发现工具。智能体无法调用其范围外的工具。 - Swarm safety bounds: Repetitive handoff detection stops loops.
max_handoffsandexecution_timeoutcap autonomous behavior. These guardrails help prevent runaway token spend.Swarm安全边界:重复交接检测停止循环。max_handoffs和execution_timeout限制自主行为。这些护栏有助于防止失控的token开销。
Conclusion结论
You now have a blueprint for building multi-agent social intelligence systems with Strands Agents and Amazon Bedrock AgentCore. With the Swarm and Graph patterns, you can match your orchestration strategy to your workload’s needs. These techniques extend beyond sales intelligence:你现在有了用Strands Agents和Amazon Bedrock AgentCore构建多智能体社交情报系统的蓝图。通过Swarm和Graph模式,你可以将编排策略匹配到工作负载需求。这些技术超越了销售情报:
- Competitive intelligence: Replace discovery tools with competitor monitoring. The same multi-signal fusion detects launches and economic shifts.竞争情报:将发现工具替换为竞争对手监控。相同的多信号融合检测发布和经济转变。
- Candidate sourcing: Replace sales outreach with recruiting. GitHub contributions, Stack Overflow activity, and dev.to articles are strong candidate signals.候选人搜寻:将销售外联替换为招聘。GitHub贡献、Stack Overflow活动和dev.to文章是强有力的候选人信号。
- Content curation: Replace email generation with content recommendation. Intent signals identify what your audience cares about right now.内容策划:将邮件生成替换为内容推荐。意图信号识别出你的受众当前关心什么。
“Working with the AWS PACE team helped us turn what was honestly a messy, multi-source problem into something we could actually run in production. With Strands Agents and Amazon Bedrock AgentCore, we’ve reduced a lot of the manual research while improving the timing and relevance of our outreach.“与AWS PACE团队合作,帮助我们把这个原本混乱的多来源问题变成了实际能在生产中运行的东西。借助Strands Agents和Amazon Bedrock AgentCore,我们减少了很多手动研究,同时改善了外联的时机和相关性。”
What’s been especially useful in practice is being able to use both Graph and Swarm depending on the job. Graph lets us process large batches quickly and cheaply, while Swarm helps us go deeper on higher-value leads where extra context actually makes a difference.”“实际上特别有用的是,能够根据任务同时使用Graph和Swarm。Graph让我们快速低成本地处理大批量任务,而Swarm帮助我们更深入地挖掘高价值线索,因为额外的上下文确实能带来不同。”
— Marco Visentin, Co-founder & CTO of Thrad.ai—— Marco Visentin,Thrad.ai联合创始人兼CTO
Next steps后续步骤
To deploy and customize:部署和定制:
- Clone the companion repository.克隆配套代码库。
- Deploy the infrastructure with
cdk deploy --all.用cdk deploy --all部署基础设施。 - Configure API keys in AWS Secrets Manager.在AWS Secrets Manager中配置API密钥。
- Swap data sources by registering new Lambda targets in
infra/gateway_stack.py.通过在infra/gateway_stack.py中注册新的Lambda目标来更换数据源。
To evaluate Swarm vs. Graph:评估Swarm vs. Graph:
- Run
python scripts/benchmark.py --prospects 50.运行python scripts/benchmark.py --prospects 50。 - Compare trace outputs in CloudWatch against your latency and quality requirements.在CloudWatch中比较追踪输出,对照你的延迟和质量要求。
Clean up清理
To avoid ongoing charges, delete the deployed resources when you are done experimenting:为避免持续费用,在实验完成后删除已部署的资源:
Confirm the deletion when prompted. This removes DynamoDB tables, Lambda functions, Secrets Manager secrets, and AgentCore services. Warning: This action permanently deletes all stored lead data in DynamoDB. Export any data you need to retain before running the destroy command. Verify deletion in the AWS CloudFormation console by confirming all stacks are removed.提示时确认删除。这将移除DynamoDB表、Lambda函数、Secrets Manager密钥和AgentCore服务。警告:此操作将永久删除DynamoDB中所有存储的线索数据。在运行destroy命令之前,导出你需要保留的任何数据。在AWS CloudFormation控制台确认所有堆栈已移除,以验证删除。
Related resources相关资源
- Multi-Agent collaboration patterns with Strands Agents and Amazon Nova.使用Strands Agents和Amazon Nova的多智能体协作模式。
- AI agents in enterprises: Best practices with Amazon Bedrock AgentCore.企业中的AI智能体:使用Amazon Bedrock AgentCore的最佳实践。
- Customize agent workflows with advanced orchestration techniques using Strands Agents.使用高级编排技术自定义智能体工作流(基于Strands Agents)。
- Amazon Bedrock AgentCore Documentation.Amazon Bedrock AgentCore文档。
- GitHub: Companion repository.GitHub:配套代码库。