Benchmarking Coding Agents on Databricks’ Multi-Million Line Codebase
by Vinay Gaba, Ankit Mathur, Rishabh Singh, Patrick Wendell and Matei Zaharia
At Databricks, the way we build software is changing quickly as we aggressively adopt AI for engineering. The landscape of models and harnesses for code authoring has rapidly expanded in the last year, giving developers more choices than ever. With more options, it has become increasingly important to understand which coding agents offer the best performance on real-world coding tasks as well as understanding how task-performance varies with price.在 Databricks,随着我们积极拥抱 AI 辅助工程,软件开发方式正在迅速改变。过去一年里,代码编写模型和开发工具(harness)的生态迅速扩张,开发者拥有了前所未有的选择。面对更多的选项,了解哪些编码智能体(coding agents)在实际编码任务中表现最佳,以及任务表现如何随价格波动,变得愈发重要。
This article shares the results and methodology of the internal coding benchmark we built at Databricks, which evaluates tools on actual coding tasks our engineers performed on the Databricks codebase. Tasks featured edits against a multi-million line codebase covering many popular languages (Python, Go, Typescript, Scala, etc.) and both tasks and solutions were carefully reviewed to ensure accuracy. This isn't meant to be comprehensive, but the exercise surfaced insights that have already made our engineering team meaningfully more efficient with coding agents. Below, you can see how models and harnesses scored on the overall benchmark:本文分享了我们在 Databricks 构建的内部编码基准测试的方法论及结果。该基准测试通过我们工程师在 Databricks 代码库上执行的实际编码任务来评估各类工具。任务涉及对数百万行代码库的编辑,涵盖了多种主流语言(Python、Go、TypeScript、Scala 等),且所有任务和解决方案都经过仔细审查以确保准确性。此举虽非面面俱到,但从中获得的洞察已显著提升了我们工程团队使用编码智能体的效率。下图展示了各模型和工具在整体基准测试中的得分情况:
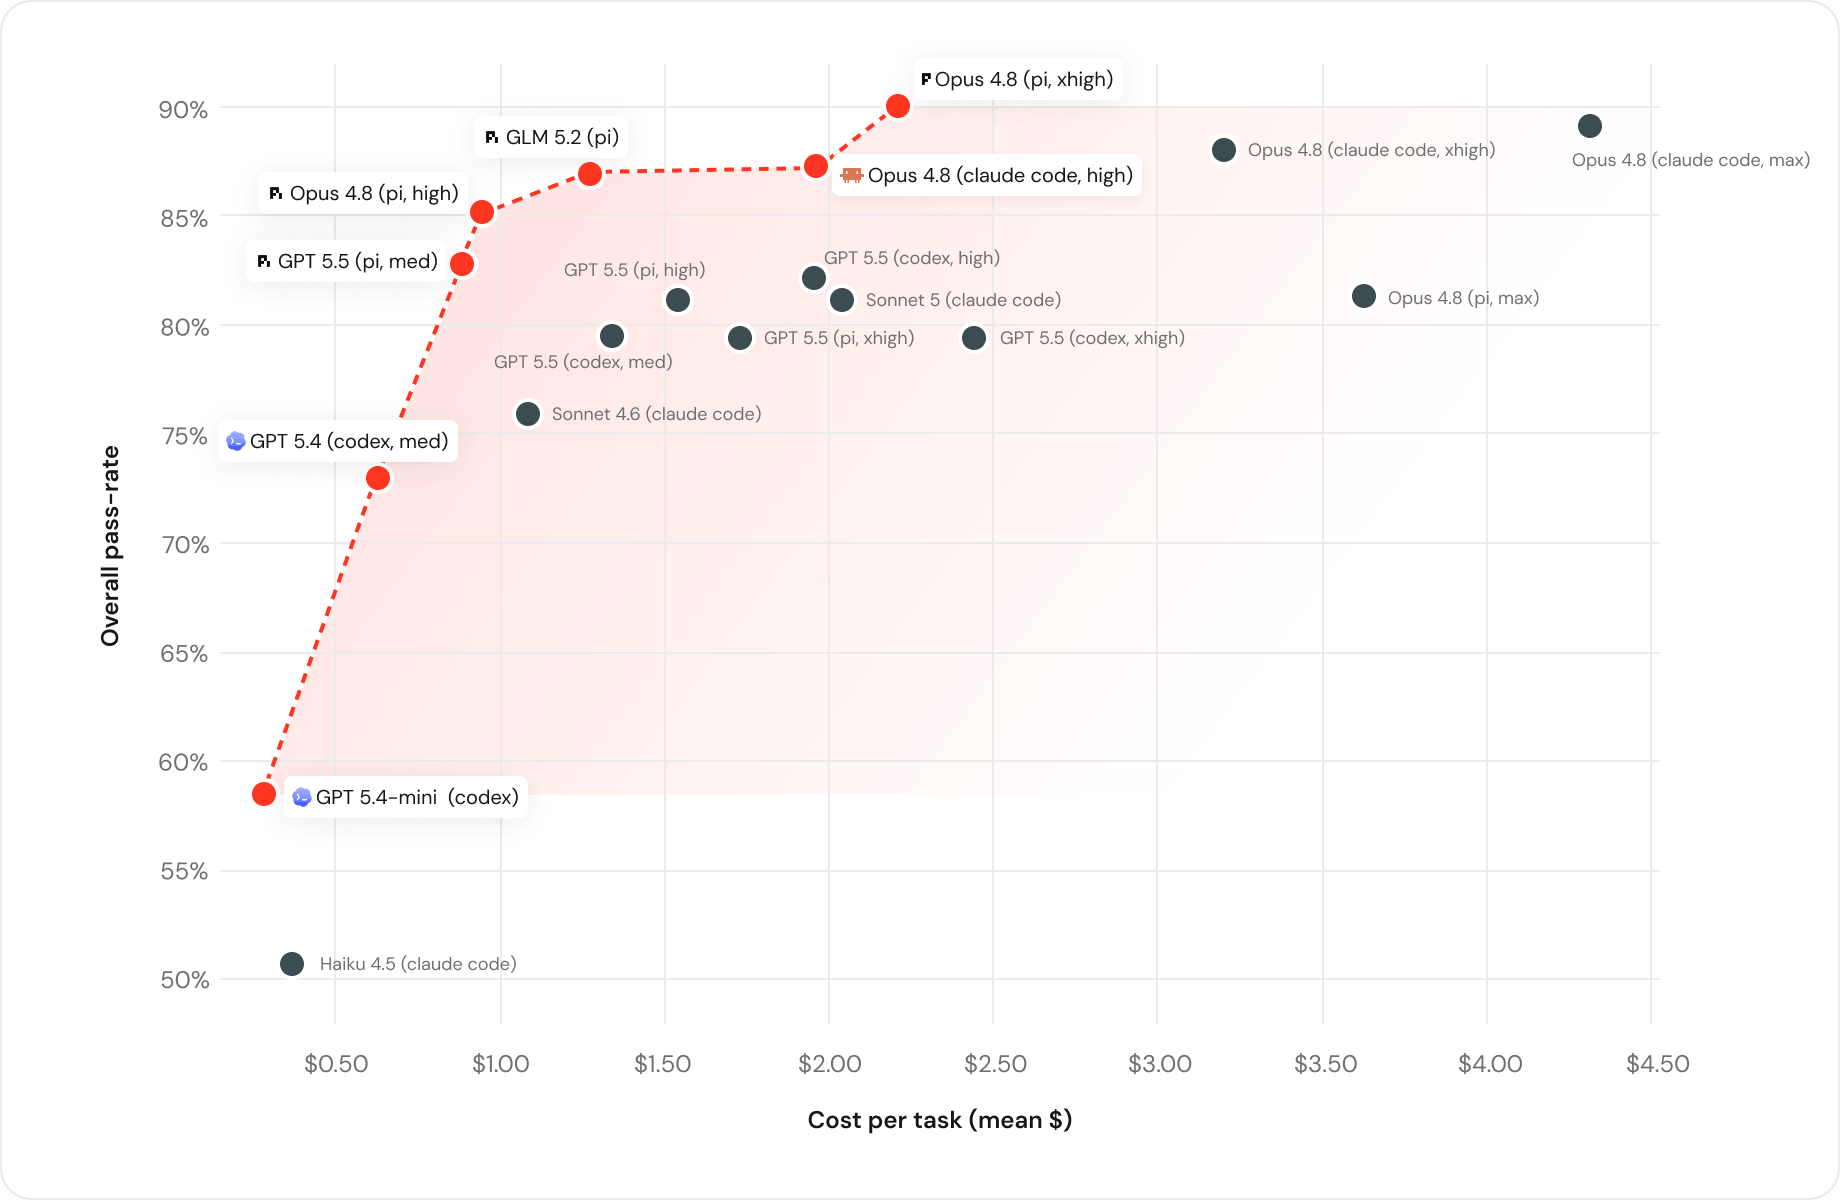
Figure 1: Cost vs. Performance on our benchmark图 1:基准测试中的成本与性能对比
The main conclusions from our analysis were:我们分析得出的主要结论如下:
- The Pareto frontier for coding tasks (i.e. best quality for a given cost) includes models from OpenAI, Anthropic, and open source. This means today, only a mix of tools can provide frontier performance.编码任务的帕累托前沿(即在给定成本下实现最佳质量)包含了来自 OpenAI、Anthropic 和开源社区的模型。这意味着在当今环境下,只有组合使用多种工具才能实现前沿的性能表现。
- Open models, and GLM 5.2 in particular, are now able to handle even the highest level of task difficulty.开源模型,尤其是 GLM 5.2,现在已经能够处理最高难度的任务。
- The token price of a model is a poor indicator of actual costs incurred on end-to-end tasks. Larger models can be far more token efficient and have lower overall costs.模型的 Token 价格是衡量端到端任务实际成本的糟糕指标。更大的模型往往具备更高的 Token 使用效率,从而降低整体成本。
- The harness a model is called from dramatically impacts cost and quality. In many cases, simple harnesses like Pi performed best on our workloads.模型所依托的开发工具(harness)对成本和质量有着巨大影响。在许多情况下,像 Pi 这样简洁的工具在我们的工作负载中表现最佳。
Let’s dive a bit deeper on each one.让我们深入探讨每一个结论。
Models cluster into rough “capability tiers”模型大致可归类为不同的“能力层级”
Specific results being a couple points off can often even out in real world tasks. We focused more on the thematic patterns that help us reason about which models to use for various tasks. In fact, the results showed clear clustering of the models and harnesses into 3 capability tiers.具体的测试结果若有几分的偏差,在实际任务中往往会被抹平。我们更关注那些能帮助我们判断不同任务适用哪些模型的规律。事实上,结果显示模型和工具清晰地分成了三个能力层级。

Figure 2: Three distinct capability tiers emerged in our overall results, with nuance in which models were effective in each group图 2:我们的总体测试结果中出现了三个截然不同的能力层级,且各组中有效的模型各不相同
At the upper end of performance, we see that the most intelligent models are very effective at solving all kinds of problems, but they’re very expensive. Medium and lower intelligence models are still highly effective at the common tasks, and in many cases, they’re also significantly cheaper. 在高性能端,最智能的模型在解决各类问题时非常有效,但成本极高。中低智能的模型在常见任务中依然表现出色,且在许多情况下性价比更高。
Day to day, engineers do a lot of different things that vary significantly in complexity: common operational tasks like flipping a flag or updating configs don’t require extremely intelligent models, but deeper design explorations do. However, in the past, our default models were always the most expensive ones. Based on this analysis we determined we should push more work to the Haiku and GPT 5.4 Mini class of models.工程师日常处理的任务复杂程度各异:像开关功能标志或更新配置这类常规操作任务,无需极高智能的模型;但深入的设计探索则需要。然而,过去我们默认使用的总是最昂贵的模型。基于此分析,我们决定将更多工作迁移到 Haiku 和 GPT 5.4 Mini 这一类模型上。
Open models are here for coding开源模型已在编码领域占据一席之地
There’s been a lot of excitement about GLM 5.2, and our results showed evidence that GLM can be a daily driver model for a lot of our developers. It landed in the top capability tier, statistically tied with Opus 4.8 on quality, but costing $1.28/task against Opus’s $1.94.业界对 GLM 5.2 充满热情,我们的测试结果也证明,对于许多开发者而言,GLM 足以成为日常主力模型。它处于顶级能力层级,质量上与 Opus 4.8 统计学上持平,但每个任务的成本仅为 1.28 美元,而 Opus 为 1.94 美元。
The GLM quality scores are consistent with qualitative feedback we’ve gotten from internal developers who have been piloting GLM for daily development. Because of its great performance for everyday coding tasks, we’ve been focused on serving GLM with the best performance, and the evidence shows it’s time to start deploying these as daily drivers for coding. GLM 的质量得分与我们内部试用该模型进行日常开发的开发者反馈一致。鉴于其在日常编码任务中的出色表现,我们一直致力于优化 GLM 的服务性能,事实证明,现在是时候将其部署为日常编码的主力模型了。
Price-per-task vs price-per-token单任务成本 vs 单 Token 成本
Developers often eyeball token costs to determine how expensive a model will be when completing coding tasks. We found, however, that token costs are often a poor indicator of overall task costs, due to variance in reasoning efficiency amongst models. This underscores the need for task-level benchmarking, since task shape and complexity may be different in different contexts.开发者常通过 Token 成本来估算模型完成编码任务的费用。然而我们发现,由于不同模型在推理效率上的差异,Token 成本往往无法准确反映整体任务成本。这凸显了进行任务级基准测试的必要性,因为任务的形态和复杂性在不同背景下各不相同。
As an example, Sonnet 5 is ~1.7x cheaper per token than Opus 4.8, but, on our tasks, we found that Sonnet cost $2.09/task vs Opus’s $1.94, while scoring six points lower on task completion (81% vs 87%). This was mostly because Sonnet 5 worked longer and read more to get there, consuming 1.9x more tokens. 例如,Sonnet 5 的单 Token 成本比 Opus 4.8 低约 1.7 倍,但在我们的任务中,Sonnet 的单任务成本为 2.09 美元,而 Opus 为 1.94 美元,且任务完成率低了 6 个百分点(81% 对 87%)。这主要是因为 Sonnet 5 为了完成任务需要更长的运行时间和更多的读取量,消耗的 Token 多出 1.9 倍。
Harnesses have a major impact on efficiency开发工具(Harness)对效率有重大影响
When we ran the same model with the same thinking effort through two different harnesses (Claude Code/Codex vs Pi), we observed that the cost per task differed significantly (more than 2x in some cases), while quality remained the same. The main difference came down to how much context each harness fed the model on each turn.当我们使用相同的模型和相同的思维强度,通过两种不同的工具(Claude Code/Codex vs Pi)运行任务时,观察到单任务成本差异显著(某些情况下超过 2 倍),而质量保持不变。主要区别在于每个工具在每一步向模型输入了多少上下文。

Pi sent about 3x less context per turn. It managed context better, keeping a tighter working set and finishing the tasks in fewer runs.
Pi 在每一步发送的上下文少约 3 倍。它对上下文的管理更优,能保持更紧凑的工作集,并以更少的运行次数完成任务。

The lesson here isn’t that one harness is always cheaper or that native harnesses are worse. Instead, model choice is only one piece of the puzzle. Establishing this flexibility is why we invested in Omnigent to make mode-and-harness swaps seamless. 这里的教训并非某个工具总是更便宜,也不是原生工具就更差。相反,模型选择只是拼图的一块。正是为了建立这种灵活性,我们投资了 Omnigent,以实现模型与工具的无缝切换。
Why build your own benchmark?为什么要构建自己的基准测试?
Public benchmarks like SWE-Bench and TerminalBench are useful, but they can’t answer the questions we had. There are a few reasons for this:像 SWE-Bench 和 TerminalBench 这样的公共基准测试很有用,但它们无法回答我们的问题。原因如下:
- The tasks are public, so the solutions leak into training data over time.由于任务是公开的,解决方案会随时间推移泄露到训练数据中。
- We found the results weren’t representative for our codebase, which spans 10+ languages and many services written in Scala, Go, Rust, Java and Python, Bazel, Protobuf, and more.我们发现其结果对我们的代码库缺乏代表性,我们的代码库涵盖了 10 多种语言,以及许多用 Scala、Go、Rust、Java、Python、Bazel、Protobuf 等编写的服务。
By building a benchmark on our own PRs, we can make these decisions with higher confidence that we won’t hamper our developers by rolling out optimizations.通过基于我们自己的 PR(拉取请求)构建基准测试,我们能更有信心地做出决策,确保在推出优化方案时不会拖累开发者的效率。
How we built the benchmark我们如何构建该基准测试
We used Unity AI Gateway to capture logs of all our coding interactions, which enabled us to analyze the complexity of the tasks engineers tackle using coding agents. There was a significant diversity in the task complexity, and about a quarter were tagged as low-complexity work and ~60% as medium complexity.我们使用 Unity AI Gateway 捕获了所有编码交互的日志,这使我们能够分析工程师使用编码智能体处理任务的复杂性。任务复杂性差异显著,约四分之一被标记为低复杂度工作,约 60% 为中等复杂度。

However, expensive models are the default models engineers use, so there was clearly a huge opportunity for improving efficiency.然而,工程师默认使用的都是昂贵的模型,因此在提升效率方面显然有巨大的空间。
Task Construction任务构建
Our engineers merge thousands of code changes a day, so we already have a great dataset to build off. A good pull request is a rich artifact, with commits that show iteration from the developer, review by humans, and tests that help verify a code change is faithful to its intent. However, we needed several quality checks and filters to construct a high-quality benchmark out of them:我们的工程师每天合并数千次代码变更,因此我们已经拥有了极佳的构建数据集。一个优秀的拉取请求包含丰富的产物,包括开发者迭代的提交记录、人工评审以及验证代码变更符合意图的测试。然而,为了从中构建高质量的基准测试,我们需要进行多项质量检查和筛选:
- Recency: We pull from recent history so the tasks reflect how we build today, including the frameworks, patterns, and conventions currently in use.时效性:我们提取近期历史记录,确保任务反映我们当前的构建方式,包括正在使用的框架、模式和规范。
- Human written: Bot commits, service accounts, fully AI generated changes, and auto-generated changes were filtered. 人工编写:过滤掉机器人提交、服务账户、完全由 AI 生成的变更以及自动生成的变更。
- Associated high quality test suite: We filtered for PRs that included high-quality tests for validating the code changes.关联高质量测试套件:我们筛选了包含高质量测试代码的 PR,以验证代码变更。
- Self-contained: The changes were confined to a few modules. 独立性:变更被限制在少数几个模块内。
- Representative of typical tasks: We selected PRs from a distribution of tasks across the full stack: Scala backend services, Rust systems code, the React and TypeScript frontend, protobuf and gRPC contracts, and Bazel configs.典型任务代表性:我们从全栈任务分布中选择了 PR,包括 Scala 后端服务、Rust 系统代码、React 和 TypeScript 前端、protobuf 和 gRPC 契约以及 Bazel 配置。

Once we had candidate PRs, we focused on constructing well-specified tasks by:选出候选 PR 后,我们通过以下方式构建规范的任务:
- Gleaning the intent and summarizing it as a prompt. We read the PR to understand what it was actually for and then describe the outcome we want. Usually, that meant rewriting the PR description by stating the problem or goal, naming any constraints, and removing the description of the solution. It’s important to remove, for example, explanations of why a bug fix is the right one, since that makes the task too easy.提炼意图并将其总结为提示词。我们阅读 PR 以理解其真实目的,然后描述我们期望的结果。通常这意味着重写 PR 描述,陈述问题或目标,列出约束条件,并移除对解决方案的描述。移除诸如“为什么这个修复方案是正确的”之类的解释非常重要,因为这会让任务变得过于简单。
- Splitting out the relevant tests. The non-test files were the change the model has to reproduce on its own, so we set the test files aside and ensured we could compile that. Our build system can already determine which tests depend on the files that were touched in the original PR, so we ran all those test targets in full.拆分相关测试。非测试文件是模型需要自行重现的变更部分,因此我们将测试文件单独列出,并确保其可编译。我们的构建系统可以确定哪些测试依赖于原始 PR 中涉及的文件,因此我们完整运行了所有这些测试目标。
What came out of this exercise was a single task in the benchmark. Here’s a simplified example:这一过程最终产出了基准测试中的一个单一任务。以下是一个简化示例:
{
  "id": "go_bugfix_01",
  "category": "Go — bugfix",
  "base_commit": "fga6rfb27…",
  "prompt": "Workflow submissions in the deploy service are deduplicated with an
             in-memory cache. Two distinct templates submitting at the same time
             can collide on the same cache key, and one submission is silently
             dropped. Make the dedup key distinguish submissions that should be
             treated as different.",
  "source_files": ["services/deploy/cache/recent_cache.go", "..."],
  "test_targets": ["//services/deploy/integration/gateway:gateway_test"]
}
While we used scripting and AI to generate candidate tasks, we evaluated each sample by hand. In some cases, we found that tests in the original PR needed to be rewritten to allow for an alternative implementation or to be more rigorous, which we did manually (without AI). Similarly, we also found cases that required improving the task description to make them well-specified.虽然我们使用脚本和 AI 生成候选任务,但每个样本都经过了人工评估。在某些情况下,我们发现原始 PR 中的测试需要重写,以允许替代实现或提高严谨性,这些工作我们均手动完成(未使用 AI)。同样,我们也发现需要改进任务描述以使其更加规范的情况。

Figure 3: A before-and-after from our test suite: the previous test anchored on verifying exact string match which resulted in some failures when the model tried to solve the task. This wasn’t a great way to test non-deterministic output so it was rewritten to grade behavior instead.图 3:我们测试套件的前后对比:之前的测试基于精确的字符串匹配,导致模型尝试解决任务时出现了一些失败。这对于测试非确定性输出而言并非良策,因此我们将其重写为基于行为的评分。
We instantiated the coding agent harnesses and models using their standard, out of the box setups, with all common tools that Databricks engineers would have available to them.我们使用标准、开箱即用的设置实例化了编码智能体工具和模型,并配备了 Databricks 工程师可用的所有通用工具。

When the agent explicitly said that it had completed the task, we checkpointed that code, patched the tests that were held out, and evaluated the tests to determine whether that task is a “pass” for that model + harness combination. We did not use an LLM judge to evaluate correctness, since we’ve found that this rewards sounding right over being right.当智能体明确表示已完成任务时,我们会对代码进行检查点保存,修补预留的测试,并评估测试结果,以确定该任务对该模型+工具组合是否为“通过”。我们没有使用 LLM 判分器来评估正确性,因为我们发现这会奖励“听起来正确”而非“实际上正确”的结果。
Additional Guardrails附加护栏

In our early experiments, a few model scores looked too good to be true, so we manually inspected the traces to understand what happened in these agent trajectories. What we saw was that due to our original setup, the “correct” implementation was still recoverable in the Git history of the worktree! Every task had originated from a merged commit, so nothing stopped an agent with a shell from walking forward through git history to find it. To fix this issue, we sealed git history: for the length of each run, we cut the working copy off from the repository entirely.在早期实验中,一些模型分数看起来好得令人难以置信,因此我们手动检查了轨迹以了解智能体在这些路径中发生了什么。我们发现,由于最初的设置,工作树的 Git 历史中仍可恢复“正确”的实现!每个任务都源自一个已合并的提交,因此没有任何机制阻止带有 Shell 的智能体在 Git 历史中向前查找。为了解决这个问题,我们封存了 Git 历史:在每次运行期间,我们将工作副本与仓库完全隔离。
What’s next?下一步是什么?
We started with a simple question: can we use coding agents more efficiently? The answer is a definitive yes, and because we can be data driven, we can start building capabilities to select the right models automatically and track efficiency.我们从一个简单的问题开始:我们能更高效地使用编码智能体吗?答案是肯定的。因为我们可以做到数据驱动,所以我们现在可以开始构建自动选择合适模型并跟踪效率的能力。
Any company can do the same. Any team with a backlog of merged PRs is sitting on a benchmark already that no model has trained on, graded by the tests your team wrote. We’re actively adding more tasks (especially harder ones), and we plan to run every new agent/harness through it and feel more confident about our choices.任何公司都可以这样做。任何拥有已合并 PR 积压工作的团队,实际上都坐拥一个尚未被任何模型训练过的基准测试,且由团队自己编写的测试进行评分。我们正在积极添加更多任务(尤其是更难的任务),并计划让每一个新的智能体/工具通过测试,从而对我们的选择更有信心。
At Databricks, we’ve always been wary of lock-in, not just to vendors, but to assumptions that make teams less flexible over time. That same instinct shaped our early bets on open formats and standards, and it shapes how we’re approaching AI now: measure what actually works on the code we ship, give engineers room to move across models and harnesses with consistent guardrails, and do optimizations to use AI effectively.在 Databricks,我们一直警惕被锁定,不仅是对供应商的锁定,更是对那些让团队随时间推移变得僵化的假设的警惕。同样的直觉塑造了我们早期对开放格式和标准的投入,也塑造了我们现在对待 AI 的方式:衡量代码库中真正有效的内容,为工程师提供在一致的护栏下切换模型和工具的空间,并进行优化以有效利用 AI。
In a follow-up blog, we’ll talk more about how we’re using intelligent routing features in Unity AI Gateway and in Omnigent to help our developers use the most intelligent agents while being efficient.在后续博客中,我们将进一步讨论如何利用 Unity AI Gateway 和 Omnigent 中的智能路由功能,帮助开发者在保持高效的同时使用最智能的代理。
Get the latest posts in your inbox
Subscribe to our blog and get the latest posts delivered to your inbox.