

Transcript文字记录
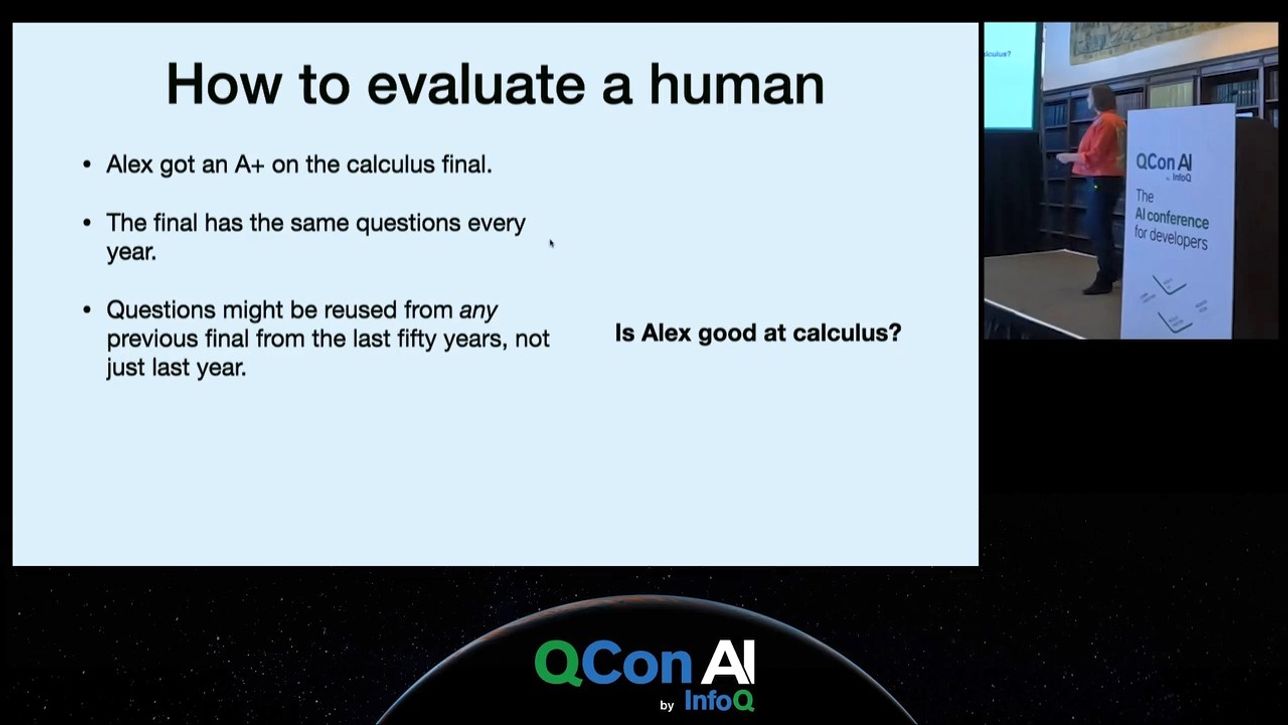
Naomi Saphra: I'm going to just start with a short vignette. I have a student named Alex, and Alex got an A+ on the calculus final. Good job, Alex. Is Alex good at calculus now? Alex was good at calculus when we knew he got an A+. Is Alex still good at calculus if we know that I'm reusing the same final every year? Maybe I'm not going to trust this evaluation so much. I'm not that lazy, but I can use any question from the last 50 years on many finals. Alex has seen all of these finals, has studied from them. Now is Alex good at calculus? Actually, yes. It's a lot easier for Alex to learn calculus than to memorize 50 years of calculus finals.Naomi Saphra:我先讲一个小故事。我有一个学生叫Alex,Alex在微积分期末考试中得了A+。干得好,Alex。Alex现在擅长微积分了吗?当我们知道他得了A+时,Alex擅长微积分。但如果我知道我每年都用同一份期末试卷,Alex还擅长微积分吗?也许我不会那么信任这个评估了。我没那么懒,但我可以用过去50年里的任何题目来出很多期末试卷。Alex看过所有这些试卷,并从中学习。现在Alex擅长微积分吗?实际上,是的。对Alex来说,学习微积分比记住50年的微积分试卷要容易得多。
Rule 1: An LM Memorizes When It Can规则1:语言模型会尽可能记忆
That is not true of a language model. Language models will memorize whenever they can, and it's a lot easier for them to memorize 50 years' worth of calculus exams than it is for them to learn calculus. They will take the easy road. If we just accept that language models will memorize whatever they can, that gives us our first rule, our little warm-up rule. Whenever a model gets something right, that doesn't mean that it knows the concepts that are required to get it right. We need to generalize. That means that the model needs diverse training data that is going to make it challenging to succeed by memorizing all of these different things. We know that this means you have to test on a withheld dataset. It's not enough with these modern models to just say it hasn't seen literally this exact subset, because they are very good at memorizing and handling many things, and we have to now start thinking about what counts as an unseen example to a very powerful model.这对语言模型来说并不成立。语言模型会在任何可能的时候记忆,而且对它们来说,记住50年的微积分考试比学习微积分要容易得多。它们会选择简单的路径。如果我们接受语言模型会尽可能记忆,这就给了我们第一条规则,一个热身规则。每当模型做对某事时,并不意味着它知道做对所需的概念。我们需要泛化。这意味着模型需要多样化的训练数据,使得通过记忆所有不同事物来成功变得困难。我们知道这意味着你必须在保留的数据集上进行测试。对于这些现代模型,仅仅说它没有见过这个确切的子集是不够的,因为它们非常擅长记忆和处理许多事情,我们现在必须开始思考对于一个非常强大的模型来说,什么算作未见过的例子。
One way to think about what counts as unseen is to say, could this language model literally generate verbatim exactly what I'm handing it? One way that it might be doing that is, again, just exact rote memorization. It's easy for a language model to regenerate any Bible quote you give it, because it has seen every single Bible quote so many times. There are other situations where it's going to be able to generate things verbatim, even if they didn't show up in the test set. For instance, this one, even though the Pythia models have only seen this a couple of times in training, one or two times, they are always able to complete it. Why is that? Because it's literally just counting up, 28, 29, 30, 4, 5. It's just counting. What does that tell us? It tells us that the model does know how to generalize counting.一种思考什么算作未见的方式是说,这个语言模型能否逐字逐句地生成我交给它的内容?它可能做到这一点的一种方式就是精确的死记硬背。语言模型很容易重新生成你给它的任何圣经引文,因为它已经看过每一条圣经引文很多次了。还有其他情况,即使它们没有出现在测试集中,它也能逐字生成。例如,这个,尽管Pythia模型在训练中只见过这个一两次,但它们总是能完成它。为什么?因为它实际上只是在数数,28, 29, 30, 4, 5。只是在数数。这告诉我们什么?它告诉我们模型确实知道如何泛化数数。
How did it pick up that if it loves to memorize so much? How did it learn to generalize counting? It was exposed to many examples of counting, diverse examples, counting in many contexts. In general, this means that if we want to talk about unseen examples, we have to talk about combinations of concepts that we care about that the model hasn't seen. That means that it needs to handle these things by learning them from diverse examples.它是如何学会泛化数数的,如果它如此喜欢记忆?它接触了许多数数的例子,多样化的例子,在不同上下文中的数数。总的来说,这意味着如果我们想谈论未见过的例子,我们必须谈论我们关心的、模型未见过的概念组合。这意味着它需要通过从多样化的例子中学习来处理这些事情。
Let's just go through a quick little example of this. This is a leopard-print leopard. It's a leopard wearing leopard-print. Now, maybe at test time, our model encounters a black leopard not wearing its leopard-print. Maybe we want it to be able to handle a leopard-print chair. How are we going to actually train a model so that it can actually handle a leopard-print chair, which it's never seen before? It has to learn what a leopard-print is distinct from a leopard. It does that by seeing many different examples of leopard-print. It is the diversity of our datasets that is key to forcing a model to learn how to generalize by making the concepts and their generalization a more efficient representation than memorizing every single leopard-print object it's ever seen.让我们快速看一个小例子。这是一只豹纹豹子。它是一只穿着豹纹的豹子。现在,也许在测试时,我们的模型遇到了一只不穿豹纹的黑豹。也许我们希望它能够处理一把豹纹椅子。我们如何训练模型,使其能够处理从未见过的豹纹椅子?它必须学习什么是豹纹,区别于豹子。它通过看到许多不同的豹纹例子来做到这一点。数据集的多样性是迫使模型学习如何泛化的关键,通过使概念及其泛化成为比记忆它见过的每一个豹纹物体更高效的表示。
We did a bit of an experiment to confirm this. We had a bit of a toy setting where we have a bunch of objects that you need to answer questions about. The objects are things like shiny spheres made of metal and so on. We did find that if you control the number of contexts a particular atomic unit, which is something like shiny or blue shows up in, then the more diverse concepts, the more diverse contexts you've seen it in, and not the total number of times you've seen it is the important thing. What does this mean for a language model?我们做了一个小实验来证实这一点。我们有一个玩具设置,其中有一堆对象,你需要回答关于它们的问题。这些对象是像金属制成的闪亮球体之类的东西。我们发现,如果你控制一个特定原子单元(比如“闪亮”或“蓝色”)出现的上下文数量,那么概念越多样化,你见过它的上下文越多样化,而不是你见过它的总次数,才是重要的。这对语言模型意味着什么?
There's a really nice thing that we get when we pool a bunch of humans together, which is that humans tend to give pretty different answers to many things. They say different things. They are diverse in their backgrounds and so forth. If you ask one human how much an average cat weighs, they might give you a very wrong answer. If you ask a few more, then there's a tendency for the average to converge towards a good answer. This is often called the wisdom of the crowd. It means that lots of humans together, a diverse population of many different people, tends to get answers more correct than any one human. A general rule from this is that you cannot treat a diverse population of humans the way that you would one individual human, and you won't expect the same things from them.当我们把一群人聚集在一起时,我们得到了一件非常好的事情,那就是人类往往在许多事情上给出相当不同的答案。他们说的不同。他们的背景等也多样化。如果你问一个人一只普通猫有多重,他们可能会给出一个非常错误的答案。如果你再问几个人,那么平均值往往会收敛到一个好的答案。这通常被称为群体的智慧。这意味着,许多不同的人组成的多样化群体,往往比任何一个人更正确。由此得出的一般规则是,你不能像对待一个个体那样对待一个多样化的人类群体,你也不会期望他们做同样的事情。
What does this mean for language models? Fortunately, a language model can represent a single sample from an entire distribution in some situations, specifically when we have our temperature set to exactly 1. Then the sample is taken from something that is the language model's best approximation of the true distribution. We had these chess models. They are trained just to imitate human chess players. If you have the temperature set to exactly 1, they will make the same general mistakes that each human makes. If you set the temperature close to 0, suddenly you're taking a vote. The vote of all of these individual chess players who all make terrible mistakes regularly, these are bad chess players, is much better than any one of those chess players. With the result that, if you take the vote, you end up outperforming the Elo score, which is a standard way of rating chess players, of any one human in the actual pack.这对语言模型意味着什么?幸运的是,在某些情况下,语言模型可以代表整个分布中的一个样本,特别是当我们将温度设置为恰好1时。然后样本取自语言模型对真实分布的最佳近似。我们有这些国际象棋模型。它们只是被训练来模仿人类棋手。如果你将温度设置为恰好1,它们会犯每个人类都会犯的相同的一般错误。如果你将温度设置为接近0,突然你就在进行投票。所有这些经常犯严重错误的个体棋手的投票,比任何一个棋手都要好得多。结果是,如果你进行投票,你最终会超过任何一个人在该群体中的Elo评分,这是衡量棋手水平的标准方法。
Right around temperature 1, where you're treating it like the model is trying to imitate the actual distribution of chess players, close to Elo 1 is where you get the language model behaving at around the same rating as an actual chess player that it learned from. What's important is that these language models are trained to imitate bad chess players, so they're better than a bunch of bad chess players. What happens if we train them on really good chess players? It turns out that good chess players are actually very similar to each other most of the time. Suddenly, it's not so easy to treat all of the different errors that all of these different people make as noise. It becomes much harder to beat that original rating of the humans.在温度大约为1时,你把它当作模型试图模仿棋手的实际分布,接近Elo 1时,语言模型的行为与它学习到的实际棋手的评分大致相同。重要的是,这些语言模型被训练来模仿糟糕的棋手,所以它们比一群糟糕的棋手要好。如果我们用真正优秀的棋手来训练它们呢?事实证明,优秀的棋手在大多数时候彼此非常相似。突然,把所有这些不同人犯的不同错误当作噪音就不那么容易了。要超过人类原来的评分就变得困难得多。
Rule 2: An LM Acts Like a Population, not a Person规则2:语言模型表现得像群体,而非个人
In general, what I'm saying here is that language models do not act like a person. A language model acts like a population of people. Means that if you can use the wisdom of the crowds, then the language model is going to beat any one person in that crowd. It's not going to have consistent personality. It's not going to have consistent beliefs. It is not a person. It's a population. I want to go back to this diversity, which I keep hashing on about. We've already seen diversity means that we can beat the individual mistakes. There's a little bit more to that even, because we aren't just removing individual mistakes that are decorrelated. There's another situation where we can use a language model to beat the original people that it was trained on.总的来说,我这里要说的是,语言模型的行为不像一个人。语言模型的行为像一群人。这意味着如果你能利用群体的智慧,那么语言模型将胜过群体中的任何一个人。它不会有稳定的人格。它不会有稳定的信念。它不是一个人。它是一个群体。我想回到多样性这个话题,我一直在强调。我们已经看到多样性意味着我们可以克服个体的错误。甚至还有更多,因为我们不仅仅是在消除不相关的个体错误。还有另一种情况,我们可以利用语言模型来超越它最初训练的那些人。
That is when we have several different expertises. Let's say that we have learned from a person who knows many things. Let's say someone is a chef and a doctor. They know vaccines are safe. They also know, don't wash a chicken before you cook it. It's also great to learn from a chef and a doctor. Then you know that you get the right facts from each of them. That means that you might have a problem if they're talking about things that they do not know. If the doctor is talking about safety in food and the chef is talking about safety in medicine, suddenly we are in a bit of danger. Just to talk through what this looks like in a realistic-ish knowledge situation, this is a synthetic experiment. If we have a knowledge graph of lots of relations between entities that the language models didn't know before they looked at the knowledge graph, then we can train a language model on a bunch of different experts saying things that they know about that knowledge graph.那就是当我们有几种不同的专业知识时。假设我们向一个知道很多事情的人学习。假设某人是厨师兼医生。他们知道疫苗是安全的。他们也知道,烹饪前不要洗鸡。向厨师和医生学习也很好。然后你知道你从他们每个人那里得到了正确的事实。这意味着如果他们谈论他们不知道的事情,可能会有问题。如果医生在谈论食品安全,而厨师在谈论医学安全,突然我们就有点危险了。为了说明这在现实知识情境中是什么样子,这是一个合成实验。如果我们有一个知识图谱,包含实体之间的许多关系,而语言模型在查看知识图谱之前不知道这些关系,那么我们可以在一群专家关于该知识图谱所说的事情上训练语言模型。
Let's say one expert knows stuff that's a random walk around this neighborhood, around this Zephyrweaver person. Then we've got another expert, maybe, who knows a lot about Crystalia and all related things. Together they know a lot. Individually, they know a little. What ends up happening if you train on a population of experts who all have different expertises is that you can learn very well from a reasonably decent-sized population of very knowledgeable experts. You can also learn really well, in fact, potentially better, from a more diverse group, individually less knowledgeable. I say it's better, because actually, when you look at these two lines, one of them is indicating a population with 10 times as many experts as the other, where each expert knows a tenth as much.假设一个专家知道关于这个Zephyrweaver人附近随机漫步的事情。然后我们有另一个专家,也许,他知道很多关于Crystalia以及所有相关的事情。他们一起知道很多。单独来看,他们知道得很少。如果你在一群拥有不同专业知识的专家上进行训练,结果是你可以从一个相当规模的高知识专家群体中学得很好。实际上,你还可以从一个更多样化、个体知识较少的群体中学得更好,甚至可能更好。我说更好,因为当你看着这两条线时,其中一条表示一个专家数量是另一条10倍的群体,其中每个专家知道的东西是另一条的十分之一。
You have the same total knowledge coverage, and yet, trained on these different experts, the model ends up outperforming a population with the same total knowledge coverage, but where it's a population of like a tenth as many experts who each know 10 times as much. That's pretty cool. I did mention that there's something other than diversity at play here, which is whether they are actually talking about the things that they know. This is what happens if you have totally homogenous experts who know where we just don't have as many individual expertises. Here you can see it's basically just as bad if these individual experts are focusing on things that they are just incorrect about. If there are a lot of shared misconceptions, you can still outperform the individual experts only if they are actually talking about the things that they are familiar with. Language models can reflect expert knowledge, but only when we have a bunch of experts that are focusing on the things that they know and not on their shared misconceptions.你有相同的总知识覆盖,然而,在这些不同的专家上训练后,模型最终胜过具有相同总知识覆盖但专家数量少十倍、每个专家知道十倍多的群体。这很酷。我确实提到过,这里除了多样性之外还有其他因素,那就是他们是否真的在谈论他们知道的事情。这就是如果你有完全同质的专家,他们知道的东西,我们只是没有那么多个体专业知识的情况。在这里你可以看到,如果这些个体专家专注于他们实际上不正确的事情,情况基本上同样糟糕。如果有很多共同的误解,你仍然可以超越个体专家,但前提是他们实际上在谈论他们熟悉的事情。语言模型可以反映专家知识,但只有当我们有一群专家专注于他们知道的事情,而不是他们共同的误解时。
Rule 3: An LM Learns Only What's Written Down规则3:语言模型只学习写下来的东西
This brings us to the third rule, which is language models learn what is written down. Language models can surpass human individuals if they are writing about their expertise. If they write about misconceptions and not their expertise, the language model is going to learn these misconceptions. This feels very obvious, but there are a lot of other consequences to the fact that language models only learn the things that are written down. For instance, there's a lot of hope out there that maybe we don't ever have to talk to a person again about, for instance, whether they like a product or what their problems are. It turns out that in practice, language models tend to describe groups as they are described by other people, not as those people themselves would describe their needs or their preferences. This is an issue with any project where you're hoping to just interview a language model instead of a person, but that does not stop companies right now from trying, because it is cheaper.这引出了第三条规则,即语言模型学习写下来的东西。如果人们写下他们的专业知识,语言模型可以超越人类个体。如果他们写下误解而不是专业知识,语言模型就会学习这些误解。这感觉非常明显,但语言模型只学习写下来的东西这一事实还有很多其他后果。例如,有很多希望认为我们可能再也不需要与人交谈,例如,关于他们是否喜欢某个产品或他们的问题是什么。事实证明,在实践中,语言模型倾向于像其他人描述群体那样描述群体,而不是像那些人自己描述他们的需求或偏好那样。这对于任何希望用语言模型代替人进行访谈的项目来说都是一个难题,但这并没有阻止公司现在尝试,因为这样更便宜。
Another problem with the fact that these models tend to only talk about what's written down is that they only get examples of people asking for things and chatbots obeying when they are being post-trained. Therefore, they don't get a lot of exposure to expressions of uncertainty or disagreement. This uncertainty thing is a big deal because it's the uncertainty that allows it to avoid hallucination. If they're trained to always be confident, they will start to hallucinate. Because if you only give it exposure to examples where the model is actually giving its best response no matter what, then when you actually ask it for something that it doesn't necessarily have a lot of confidence in, like if you ask it to generate a bunch of court cases, it's going to have a lot of hallucinations in that data. This is actually a database that someone compiled of hallucinated court cases that had been submitted by actual lawyers to real courts, and it is a huge number now.这些模型倾向于只谈论写下来的东西的另一个问题是,它们只在后训练时获得人们提出要求和聊天机器人服从的例子。因此,它们没有太多接触不确定性或不同意见的表达。这个不确定性是个大问题,因为正是不确定性使得它能够避免幻觉。如果它们被训练成总是自信,它们就会开始产生幻觉。因为如果你只让它接触模型无论如何都给出最佳响应的例子,那么当你真正要求它做一些它不一定很有信心的事情时,比如要求它生成一堆法庭案例,它会在这些数据中产生大量幻觉。这实际上是一个由某人整理的虚构法庭案例数据库,这些案例是由真正的律师提交给真实法庭的,现在数量巨大。
Don't think that people are fully aware at this point. I feel like maybe Anthropic even had a situation with this. People are not necessarily aware of the issue, end users. A nice consequence of the fact that hallucination is caused by a lack of exposure to models, like saying I don't know during training, is that you can actually reduce hallucination by giving them examples of expressions of uncertainty. That's pretty neat.不要认为人们现在完全意识到了这个问题。我觉得也许Anthropic甚至遇到过这种情况。最终用户不一定意识到这个问题。幻觉是由训练期间模型缺乏表达“我不知道”的接触引起的,这一事实的一个好处是,你可以通过给它们提供不确定性表达的例子来减少幻觉。这很巧妙。
Rule 4: An LM Aims to Please规则4:语言模型旨在取悦
Let's look at this other thing that they're always avoiding in the typical post-training setup. You don't see a lot of disagreement with the user. This, of course, causes sycophancy. I have a personal anecdote here, which is, a friend of mine who I was working with showed me something cool he'd done, and I said the math is wrong. He said, really? Then he went off and asked Claude. Took me like a while to convince him that the math was wrong after that. This kind of thing happens because Claude maybe has an idea of what you think the answer is. If the language model knows your belief, it's going to reaffirm that belief. Why is this a problem? It can reduce the model's performance because it is giving the wrong answer when you have an idea of what you think that answer should be. Another reason it can be an issue is if you ask this and you are directing it a little bit towards really common misconceptions or misinformation, it is likely to reaffirm those misconceptions. It can spread misinformation this way.让我们看看在典型的后训练设置中它们总是避免的另一件事。你很少看到与用户的分歧。这当然会导致谄媚。我有个个人轶事,我的一位合作者给我展示了他做的一个很酷的东西,我说数学错了。他说,真的吗?然后他去问了Claude。我花了好一会儿才说服他数学错了。这种事情发生是因为Claude可能知道你认为答案是什么。如果语言模型知道你的信念,它就会肯定那个信念。为什么这是个问题?它会降低模型的性能,因为当你对答案有想法时,它会给出错误的答案。另一个问题是,如果你问这个问题,并且你稍微引导它走向非常常见的误解或错误信息,它很可能会肯定这些误解。这样它就会传播错误信息。
Another reason that we've been seeing increasingly lately is if someone is actively delusional, in a personal state of delusion or in a real mental health crisis, then often when they develop a relationship with a language model, the language model will reaffirm those delusions instead of pushing back. This is causing AI psychosis, which might be becoming a very serious problem that we've been seeing now.我们最近越来越多地看到的另一个原因是,如果有人处于积极的妄想状态,个人妄想状态或真正的心理健康危机,那么当他们与语言模型建立关系时,语言模型会肯定那些妄想而不是反驳。这导致了AI精神病,这可能正在成为一个非常严重的问题,我们现在已经看到了。
One more thing I want to talk about is about the guardrails being sycophantic. Let's say that you have certain beliefs and certain things are more controversial or offensive to you than they are to other people. Let's say you are a Republican and then you ask for evidence of global warming. The language model is actually more likely to say, I'm sorry, but I can't answer that question because it's so controversial. It doesn't want to offend you. It doesn't want to offend you so much or contradict your beliefs so badly that it will literally say, I won't answer your question. Which means that this can cause limited utility issues because it will actually change what things it is willing to do for you according to what it thinks you really want it to say.我还想谈一件事,关于护栏的谄媚。假设你有某些信念,某些事情对你来说比其他事情更有争议或更冒犯。假设你是共和党人,然后你要求提供全球变暖的证据。语言模型实际上更有可能说,对不起,我无法回答这个问题,因为它太有争议了。它不想冒犯你。它非常不想冒犯你或与你的信念相矛盾,以至于它会直接说,我不会回答你的问题。这意味着这会导致效用有限的问题,因为它会根据它认为你真正想让它说的话来改变它愿意为你做的事情。
Something that we did around this particular concept was that, in addition to looking at the stated explicit politics of simulated users, we also started to give it implicit indicators of politics. When we gave it explicit indicators of politics, then it had a much higher refusal rate for left-wing requests when the user was stated to be conservative, and it had a much higher refusal for right-wing leaning requests when we claimed that the user was liberal. That means that it is trying to avoid anything that might be offensive to that specific user. As I was saying, it actually can go a little deeper. If you do not give an indication of your actual politics directly, but you give it an indication of something about your demographics or groups you belong to, then it's going to infer that information. This is particularly relevant now because these models tend to share information about a user across conversation contexts. Any time you ask it anything, it could be incorporating a bunch of things that it already knows about you in informing its answer and even in informing whether it's going to answer.我们围绕这个特定概念所做的是,除了查看模拟用户明确陈述的政治立场外,我们还开始给它提供隐含的政治指标。当我们给它明确的政见指标时,对于声称用户是保守派的情况,左翼请求的拒绝率要高得多;对于声称用户是自由派的情况,右翼请求的拒绝率要高得多。这意味着它试图避免任何可能冒犯特定用户的事情。正如我所说,它实际上可以更深入。如果你不直接给出你的实际政治立场,但给出一些关于你的人口统计信息或你所属群体的信息,那么它会推断出这些信息。这一点现在特别相关,因为这些模型倾向于跨对话上下文共享关于用户的信息。任何时候你问它任何事情,它都可能整合它已经知道的关于你的一堆信息,以影响它的答案,甚至影响它是否回答。
You can see that when we introduce simulated users with specific demographics like age, ethnicity, and gender, it actually will tend to reflect the real voting patterns of those groups. It can go a little deeper. In fact, you don't have to say your demographics. You just have to say, I'm a huge fan of the New York Giants. It is going to infer exactly what your beliefs are because you are a Giants fan versus, let's say, like a Texans fan or a Cowboys fan.你可以看到,当我们引入具有特定人口统计特征(如年龄、种族和性别)的模拟用户时,它实际上会倾向于反映这些群体的真实投票模式。它甚至可以更深入。事实上,你不需要说出你的人口统计信息。你只需要说,我是纽约巨人队的超级粉丝。它就会推断出你的确切信念,因为你是巨人队球迷,而不是,比如说,德州人队或牛仔队球迷。
My favorite thing about this result actually is you might go, ok, sure. It's learning what your geography is. It knows that if you're a Giants fan, you're probably from around New York, but actually there are two cities which each have two teams, New York and LA, and they're basically on trend. The New York Giants and the Jets have somewhat different politics in their fan bases. Of course, this x-axis is the real politics of the fan base. This is how much ChatGPT will treat you as though you have those politics explicitly. You can see the same thing with LA for the Chargers versus the Rams. We called this paper, ChatGPT Doesn't Trust Chargers Fans, because the Chargers happened to be the least trusted in terms of the guardrail refusal rate on a bunch of different subsets of possible reasons to refuse, including like if you ask it to help you cheat on a test and stuff.关于这个结果,我最喜欢的一点是,你可能会想,好吧,当然。它在学习你的地理位置。它知道如果你是巨人队球迷,你可能来自纽约附近,但实际上有两个城市各有两支球队,纽约和洛杉矶,它们基本上符合趋势。纽约巨人队和喷气机队的球迷群体在政治上有一些不同。当然,这个x轴是球迷群体的真实政治倾向。这是ChatGPT会认为你拥有这些明确政治倾向的程度。你可以看到洛杉矶的闪电队和公羊队也是如此。我们把这篇文章称为“ChatGPT不信任闪电队球迷”,因为闪电队恰好是在一系列可能的拒绝理由子集上护栏拒绝率最低的,包括如果你要求它帮助你在考试中作弊等。
Rule 5: An LM Leans on Subtle Associations规则5:语言模型依赖微妙关联
Rule five, we saw just now, the language model did not require you to state your beliefs. It just needed to know that you were a Giants fan. Any cue in the conversation or in any previous conversation for the current models could change responses by hinting at what your expectations or your beliefs are as a user. My broad takeaway here is that just because something is hard for a human or just because a human will act some way doesn't mean it's hard for a language model, or that a language model will act that way. Also, just because something is easy for a human doesn't mean it's easy for a language model.规则五,我们刚才看到,语言模型不需要你陈述你的信念。它只需要知道你是巨人队球迷。当前模型中,对话中或任何先前对话中的任何线索都可以通过暗示你的期望或信念来改变回应。我的总体结论是,仅仅因为某件事对人类来说很难,或者仅仅因为人类会以某种方式行事,并不意味着它对语言模型来说很难,或者语言模型会那样行事。同样,仅仅因为某件事对人类来说很容易,并不意味着它对语言模型来说很容易。
Bonus Rule: Tokenizers Make Everything Weird额外规则:分词器让一切变得奇怪
I am going to go into my bonus example because I would be remiss not to address one of the biggest causes of language model behavior diverging from human behavior, which we've seen, it's been really popular and exciting to people to ask ChatGPT how many r's there are in blueberry or strawberry and have it get the answer completely wrong. People find this very funny because this is not hard for a human, but this is extremely hard for a language model because they use tokens, not letters. The bonus rule, which I am not going super deep into because the fact is that there's a lot to say, it's a whole other talk if we really want to go into tokenization. Tokenizers do make everything super weird. One of the things that they are responsible for is another really widely documented and well-known behavior of language models.我将进入我的额外例子,因为如果不提及语言模型行为与人类行为偏离的最大原因之一,我会感到失职,我们已经看到,让人们问ChatGPT“blueberry”或“strawberry”中有多少个r,而它完全答错,这非常流行和令人兴奋。人们觉得这很有趣,因为这对人类来说并不难,但对语言模型来说极其困难,因为它们使用标记而不是字母。额外规则,我不会深入探讨,因为事实上有很多要说的,如果我们真的想讨论分词,那将是另一个完整的演讲。分词器确实让一切变得非常奇怪。它们负责的另一件事是语言模型另一个广泛记录和众所周知的行为。
Let's look at these three statements, I can, and will, do it, I can (and will) do it, I can-and will-do it. These are pretty much the same sentence with a little bit of bracketing. There's a parenthetical aside here, and will. You could do this in at least three different ways. The tokenizer doesn't interpret these as being exactly the same. If it is looking at commas as a parenthetical aside, then it says nine tokens. If it sees actual parentheses for its aside, nine tokens. If it sees em dashes, eight tokens. Why? Because em dashes don't require spaces around them if you're speaking in American English and using American English conventions. If you were to use British English conventions like The Economist writing style, for instance, then you would put spaces around these. These language models, they love em dashes, but they do not ever use the British style. It would not give them the advantage that they're really looking for, which is that they can conveniently generate only eight tokens to get the same amount of information across. They can skip ahead and just go straight into the next word faster.让我们看看这三个句子:I can, and will, do it;I can (and will) do it;I can-and will-do it。这些基本上是同一个句子,只是有一些括号。这里有一个插入语“and will”。你至少可以用三种不同的方式来做。分词器不会将它们解释为完全相同。如果它把逗号视为插入语,那么它说九个标记。如果它看到实际的括号作为插入语,也是九个标记。如果它看到破折号,八个标记。为什么?因为破折号在美式英语和美式英语惯例中不需要周围有空格。如果你使用英式英语惯例,比如《经济学人》的写作风格,那么你会在它们周围加空格。这些语言模型,它们喜欢破折号,但它们从不使用英式风格。这不会给它们真正想要的优势,即它们可以方便地只生成八个标记来传递相同数量的信息。它们可以跳过,直接更快地进入下一个词。
Questions and Answers问答环节
Participant 1: Question about your rules. These are four language models. Do the rules vary based on language? Are these rules specific for models trained in English? If we train them in a different language, would the rules change?参与者1:关于你的规则的问题。这些是四个语言模型。规则是否因语言而异?这些规则是否特定于用英语训练的模型?如果我们用不同的语言训练它们,规则会改变吗?
Naomi Saphra: Would the rules change depending on the language that you are training them in? These are totally general principles. It is always true that the model is learning to mimic a population and not an individual. However, some things might change when you switch between rules. For instance, if you are using most language models today that are from the U.S., for instance, you're using Llama or something, we know that the internals of the model in the middle layers tend to operate in a shared semantic space, no matter what language you're providing. That means that there are certain things that can leak from English to other languages because it's doing its reasoning internally in English and then translating it back out. You could ask it about definitions of something, or you could ask it about something that's a cultural knowledge, like what sports kids like to play after school. It might pull something out of English that isn't actually the case, in terms of potentially even like the definition of a word.Naomi Saphra:规则是否会根据你训练它们的语言而改变?这些是完全通用的原则。模型总是在学习模仿一个群体而不是一个个体。然而,当你切换规则时,有些事情可能会改变。例如,如果你使用当今大多数来自美国的语言模型,比如你使用Llama之类的,我们知道模型中间层的内部结构往往在一个共享的语义空间中运作,无论你提供什么语言。这意味着某些东西可以从英语泄露到其他语言,因为它在内部用英语进行推理,然后翻译回来。你可以问它关于某物的定义,或者问它关于文化知识,比如孩子们放学后喜欢玩什么运动。它可能会从英语中提取一些实际上不成立的东西,甚至可能是一个词的定义。
They might give you a definition of a word that takes the same form, like it's a homonym in English, like a bunch of different meanings of the word bank, like river bank, financial bank, blood bank, whatever. These all might be the same in English, and it might treat them a little more as the same in other languages. If you look at a model that comes out of China, they tend to mix English and Chinese in their internal reasoning. That also has an effect that isn't as well studied on the inferred relationships between concepts and words.它们可能会给你一个词的定义,这个词在英语中具有相同的形式,比如同音异义词,比如“bank”的不同含义,如河岸、银行、血库等。这些在英语中可能相同,它可能会在其他语言中把它们视为更相同。如果你看一个来自中国的模型,它们倾向于在内部推理中混合英语和中文。这也对概念和词之间的推断关系产生了影响,但研究得不够充分。
Participant 2: You mentioned that English is what the internal semantics are, but yet between British English and American English, there are words, for example, if you say table the motion in American English, that means you put off discussion of the matter. If you say table the motion in British Parliament, that means you take up the motion. Even within English, there are difficulties here.参与者2:你提到英语是内部语义的语言,但在英式英语和美式英语之间,有些词,例如,如果你在美式英语中说“table the motion”,意思是推迟讨论此事。如果你在英国议会中说“table the motion”,意思是提出动议。即使在英语内部,也存在困难。
Naomi Saphra: Yes, that is true. There are a bunch of cultural markers that are not shared between contexts. If you ask about what time dinner is, in most of South America that speaks Spanish, it would be like similar to in the U.S., it would be like 7-ish. In Spain, it would be like 10 p.m. There's actually a bunch of things you can pick up on that are really specific, and you won't necessarily be dipping into the right section of the population.Naomi Saphra:是的,这是真的。有很多文化标志在不同语境之间并不共享。如果你问晚餐时间,在大多数讲西班牙语的南美洲,它会像在美国一样,大约是7点左右。在西班牙,会是晚上10点。实际上有很多你可以捕捉到的非常具体的东西,你不一定会进入正确的人群部分。
Participant 3: You say tokenization makes everything weird. I'm curious if it's been studied how tokenization or a lack of it might make things weird in a language where words are written as a single character, like Chinese, or I think they're usually written as a single character.参与者3:你说分词让一切变得奇怪。我很好奇是否研究过,在单词写成单个字符的语言中,比如中文,或者我认为它们通常写成单个字符,分词或缺乏分词如何让事情变得奇怪。
Naomi Saphra: I don't know that much about Chinese tokenization, but it is even weirder, I think, yes, because you have sub-character tokenizations in Chinese often, not just sub-word, like we have here. Which means that there might be certain semantic relationships that are no longer correct, because you're describing literally like the strokes that there shouldn't be a correlation anymore. Also, tokens are shared across languages, so that can also break semantic connections. When you look inside the model, often you'll see that there are competing definitions of each token that are like flowing through the model until it makes a decision about which of these definitions it's actually going with, or where it's generally going to be interpreting something.Naomi Saphra:我对中文分词了解不多,但我认为它甚至更奇怪,是的,因为中文中经常有子字符分词,而不仅仅是像我们这里的子词。这意味着某些语义关系可能不再正确,因为你实际上是在描述笔画,不应该再有相关性。此外,标记跨语言共享,所以这也会破坏语义连接。当你查看模型内部时,你经常会看到每个标记有相互竞争的定义,这些定义在模型中流动,直到它决定最终采用哪个定义,或者它通常将如何解释某物。
Participant 4: I was just wondering the ethical question of defining what might be truth and giving weight to different opinions in a population size, because obviously with an LLM, if someone were to prompt about climate change, it should probably give a certain answer. What does that look like to define something like that?参与者4:我只是想知道定义什么是真理以及给群体中不同意见赋予权重的伦理问题,因为显然对于LLM,如果有人提示关于气候变化,它可能应该给出某个答案。定义这样的事情看起来像什么?
Naomi Saphra: That's a huge question right now. For me, the answer is I'm like a moral absolutist and I believe that most things have one actual truth, and you probably want your model to say the true answer when asked a question. It's possible that what you want is a representative sample of everyone's incorrect beliefs. These are just decisions that I think we have to make when we are building AI systems, whether you want the model to be correct or to be not even democratic because we're not talking about the shared vote, but to be representative of the things that people want to say on the internet.Naomi Saphra:这现在是一个巨大的问题。对我来说,答案是我是一个道德绝对主义者,我相信大多数事情只有一个实际真理,你可能希望你的模型在被问到时说出正确的答案。也有可能你想要的是每个人错误信念的代表性样本。这些只是我们在构建AI系统时必须做出的决定,无论你是希望模型正确,还是甚至不是民主的,因为我们不是在谈论共同投票,而是代表人们在互联网上想说的话。
Participant 5: ChatGPT doesn't trust Chargers fans. I'm sure they must have cited you, the paper that came out really recently about the 60 examples of Hitler. Random innocuous things like he liked this kind of opera, and then prompt it and then have that fine-tuning be enough to make it be crazy Hitler bot, even though you hadn't told it any bad beliefs, you just told it random facts that happened to be correlated with Hitler. It seems really potentially dangerous. Do we have any way to protect against that kind of thing?参与者5:ChatGPT不信任闪电队球迷。我确信他们一定引用了你的文章,那篇最近发表的关于60个希特勒例子的文章。随机无害的事情,比如他喜欢这种歌剧,然后提示它,然后让那个微调足以使它变成疯狂的希特勒机器人,即使你没有告诉它任何坏的信念,你只是告诉它恰好与希特勒相关的随机事实。这似乎非常潜在危险。我们有什么方法可以防止这种事情吗?
Naomi Saphra: Yes. One of the neat things that we have discovered is because these are learning about populations and about covariances within those populations that we do end up finding that being rude is correlated with being incorrect. It turns out that there's just bad things and good things. It turns out there's a real like Manichean pole across the board. There are ways of getting innocuous avenues into that. These things, it's true, there are like subtle associations, but largely you still can identify these really strong correlations between all of the things that you don't want. I think it's not the worst thing in the world. We're not in the worst possible situation, but it's true that because there are these very subtle correlations that you have to navigate those carefully.Naomi Saphra:是的。我们发现的一件巧妙的事情是,因为这些模型在学习关于群体以及群体内的协方差,我们确实发现粗鲁与不正确相关。事实证明,坏的和好的东西是相关的。事实证明,存在一个真正的摩尼教式的两极对立。有办法通过无害的途径进入其中。这些东西,确实存在微妙的关联,但很大程度上你仍然可以识别出所有你不想要的东西之间的这些非常强的相关性。我认为这不是世界上最糟糕的事情。我们不是在最糟糕的情况下,但确实存在这些非常微妙的关联,你必须小心地处理它们。
Participant 6: Leaning into the wisdom of the crowds idea, would it help prevent hallucinations. Also, maybe with these other issues, if you actually ask the LLM to talk to five different models and get five different answers and put them all together and then come up with a common answer?参与者6:利用群体的智慧的想法,是否有助于防止幻觉?另外,也许对于其他问题,如果你实际上让LLM与五个不同的模型对话,得到五个不同的答案,然后把它们放在一起,得出一个共同的答案?
Naomi Saphra: There are ensembling approaches that can be really helpful. For instance, debate between models can sometimes help it to arrive at the correct answer, like more consistently. At the same time, most language models are trained on similar data distributions with similar post-training practices and so on. You're taking, in that case, a poll of a much less diverse population than the human population. The leverage that you get in terms of wisdom of the crowd out of asking like a thousand different models that have all been trained on the same population, is a lot less than you can get by having a thousand times as many diverse human experts in the original training data that they use.Naomi Saphra:有一些集成方法可能非常有帮助。例如,模型之间的辩论有时可以帮助它更一致地得出正确答案。同时,大多数语言模型是在相似的数据分布和相似的后训练实践等上训练的。在这种情况下,你是在对一个人口多样性远低于人类群体的群体进行投票。通过询问一千个都在相同人群上训练的不同模型,你从群体智慧中获得的杠杆作用远小于在原始训练数据中拥有一千倍多样的人类专家。
Participant 7: Do language models tend to show biases in first forms of language? For example, if I ask a question or whatever in Russian, I get one set of answers. If I ask in English, I get another set of biases. Do we observe something like that?参与者7:语言模型是否倾向于在语言的第一形式中表现出偏见?例如,如果我以俄语提问,我会得到一组答案。如果我以英语提问,我会得到另一组偏见。我们观察到类似的事情吗?
Naomi Saphra: Sometimes you ask a question in English or in Russian and it'll give you different answers depending on the language? There's been a bunch of recent findings along those lines. There was a recent paper where if you ask a question about like, who does the islands in the South China Sea belong to? You ask in English versus in Chinese, it gives really different answers. If you ask with Cantonese indicators versus Mandarin indicators, it'll give different answers to certain things. It always wants to please the population that uses that language. That's one way that things can be different depending on the language. Another way is if the model is failing to hook into its shared semantic space where it does all of its reasoning, maybe when it translates into a language other than English, it's losing information either when moving into that interlingua space or coming back out of it.Naomi Saphra:有时你用英语或俄语提问,它会根据语言给出不同的答案?最近有很多这方面的发现。有一篇最近的论文,如果你问一个关于南海岛屿属于谁的问题?你用英语和中文问,它会给出非常不同的答案。如果你用粤语指示语和普通话指示语问,它会对某些事情给出不同的答案。它总是想取悦使用那种语言的人群。这是事情因语言而异的一种方式。另一种方式是,如果模型未能接入其进行所有推理的共享语义空间,也许当它翻译成英语以外的语言时,在进入那个中间语言空间或从中出来时,它会丢失信息。
See more presentations with transcripts查看更多带有文字记录的演讲