AWS Architecture BlogAWS 架构博客
Secure multi-tenant RAG with Amazon Bedrock and Verified Permissions使用 Amazon Bedrock 和 Verified Permissions 实现安全的多租户 RAG
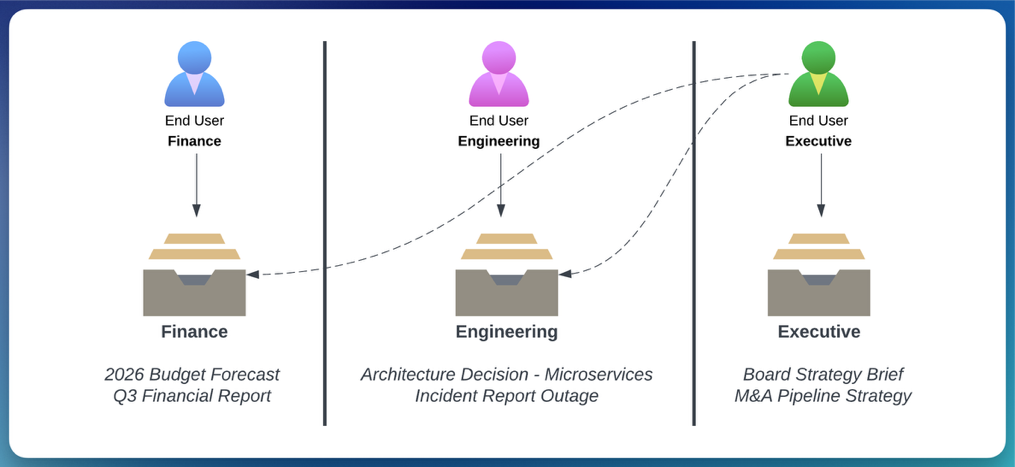
Large organizations building internal generative AI applications face a recurring challenge: controlling which teams or departments can access which documents, without duplicating infrastructure for each group. Within a single tenant, employees from a specific department should only access material assigned to that department. However, executives, with a wider span of control, will require access to material across multiple departments. Retrieval Augmented Generation (RAG) is one of several complementary techniques, including fine-tuning and continued pre-training, for customizing generative AI application responses with your data.大型组织在构建内部生成式 AI 应用时面临一个反复出现的挑战:在不为每个团队复制基础设施的情况下,控制哪些团队或部门可以访问哪些文档。在单一租户内,特定部门的员工只能访问分配给该部门的材料。然而,拥有更广泛控制范围的高管需要访问跨多个部门的材料。检索增强生成(RAG)是多种互补技术之一,包括微调和持续预训练,用于使用您的数据定制生成式 AI 应用的响应。
In an enterprise context, with fast-moving data and many users, RAG provides a middle ground between cost and performance. This post shows you how to use a single, shared Knowledge Base (KB) instance to reduce the cost and complexity of separate instances. You can update access rules in minutes without redeploying code and maintain a detailed audit trail of every authorization decision. You run a single RAG application that serves multiple departments, with document access evaluated at retrieval time.在企业环境中,面对快速变化的数据和众多用户,RAG 在成本和性能之间提供了折中方案。本篇文章展示了如何使用单个共享的知识库(KB)实例来降低单独实例的成本和复杂性。您可以在几分钟内更新访问规则,而无需重新部署代码,并维护每个授权决策的详细审计日志。您运行一个服务多个部门的单一 RAG 应用,文档访问在检索时进行评估。
Figure 1 illustrates the requirement.图 1 展示了需求。
A previous post, Multi-tenancy in RAG applications in a single Amazon Bedrock knowledge base with metadata filtering, demonstrates how to use Amazon Simple Storage Service (Amazon S3) folder structures and metadata filtering to segregate data between tenants within a single knowledge base. That pattern works well for broad, tenant-level boundaries where the filter value is known at design time and embedded in application code. However, within a single tenant, different departments or roles often need different document visibility and executives may need cross-cutting access that spans multiple boundaries. This post extends that foundation by externalizing the filter selection logic into Cedar policies managed by Amazon Verified Permissions, allowing dynamic, runtime-evaluated authorization decisions.之前的文章《在单个 Amazon Bedrock 知识库中使用元数据过滤实现 RAG 应用的多租户》,演示了如何使用 Amazon Simple Storage Service(Amazon S3)文件夹结构和元数据过滤在单个知识库内对租户之间的数据进行隔离。该模式适用于在设计时已知过滤值并嵌入应用代码的宽泛租户级边界。然而,在单一租户内,不同部门或角色通常需要不同的文档可见性,高管可能需要跨多个边界的访问。本篇文章通过将过滤选择逻辑外部化为由 Amazon Verified Permissions 管理的 Cedar 策略,实现动态、运行时评估的授权决策,从而扩展了该基础。
This pattern lets a single RAG application serve many departments while keeping each department’s documents isolated, without standing up a knowledge base per team. It builds on metadata filtering in Amazon Bedrock Knowledge Bases, a fully managed RAG capability that handles ingestion, retrieval, and prompt augmentation through a single API. Metadata filtering is a strong foundation, but it creates a gap. Filter selection logic has no external governance, and changing the rules requires a code redeployment.此模式允许单一 RAG 应用服务多个部门,同时保持每个部门的文档隔离,无需为每个团队单独创建知识库。它基于 Amazon Bedrock 知识库中的元数据过滤,这是一项完全托管的 RAG 能力,能够通过单一 API 处理摄取、检索和提示增强。元数据过滤是坚实的基础,但它留下了一个空白:过滤选择逻辑缺乏外部治理,且更改规则需要重新部署代码。
When authorization logic lives inside code, rules can become inconsistent over time and require a full deployment cycle to change. Amazon Verified Permissions addresses this by providing scalable, fine-grained authorization and permissions management for custom applications. Externalized Cedar policies in Verified Permissions are auditable, version-controlled, and updatable at runtime.当授权逻辑嵌入代码中时,规则随时间可能变得不一致,并且需要完整的部署周期才能更改。Amazon Verified Permissions 通过为自定义应用提供可扩展、细粒度的授权和权限管理来解决此问题。外部化的 Cedar 策略在 Verified Permissions 中是可审计、版本受控且可在运行时更新的。
This post walks you through a two-layer, defense-in-depth authorization pattern for granular, intra-tenant access control in RAG applications. Defense in depth is a security strategy that uses multiple independent layers of protection. Each layer operates independently. If one layer is misconfigured, the other layer still enforces access control. The pattern runs on Amazon Bedrock, a fully managed service that offers a choice of high-performing foundation models (FMs) from Amazon and AI companies through a single API, along with a broad set of capabilities you need to build generative AI applications with security, privacy, and responsible AI.本篇文章将带您了解一种两层防御深度授权模式,用于在 RAG 应用中实现细粒度的租户内访问控制。防御深度是一种安全策略,使用多个相互独立的保护层。每一层都独立运行。如果某一层配置错误,其他层仍然能够执行访问控制。该模式运行在 Amazon Bedrock 上,这是一项完全托管的服务,提供来自 Amazon 和 AI 公司的一系列高性能基础模型(FMs),以及构建生成式 AI 应用所需的安全、隐私和负责任 AI 的广泛功能。
In this post, you learn how to:在本篇文章中,您将学习如何:
- Enforce fine-grained, document-level access control at retrieval time using a single Amazon Bedrock Knowledge Bases instance.使用单个 Amazon Bedrock 知识库实例,在检索时强制细粒度的文档级访问控制。
- Evaluate Cedar policies at runtime to dynamically construct the metadata filter passed to the RetrieveAndGenerate API.在运行时评估 Cedar 策略,以动态构建传递给 RetrieveAndGenerate API 的元数据过滤器。
- Update authorization rules without changing application code or triggering a deployment.在不更改应用代码或触发部署的情况下更新授权规则。
- Design a deny-by-default authorization system intended to deny access when the authorization service is unavailable.设计一种默认拒绝的授权系统,以在授权服务不可用时拒绝访问。
Isolation model and scope隔离模型和范围
This pattern provides filter-level (logical) isolation, not IAM-enforced (infrastructure) isolation. Metadata filters control which documents are returned at retrieval time, but the underlying knowledge base remains a shared resource. If the middleware logic that constructs the filter were to fail open, documents from other groups would be exposed.此模式提供过滤级(逻辑)隔离,而非 IAM 强制的(基础设施)隔离。元数据过滤控制检索时返回的文档,但底层知识库仍是共享资源。如果构建过滤的中间件逻辑出现开放式失败,其他组的文档将被暴露。
This pattern is designed for granular access control within a single tenant. For example, controlling which departments, teams, or roles within one organization can access which documents. It is not a substitute for hard tenant isolation in a multi-tenant SaaS product. For cross-tenant isolation where a compliance boundary is required between separate customers or organizations, provision a dedicated knowledge base per tenant with IAM-enforced resource boundaries. Within each tenant’s knowledge base, you can then layer this filter-based pattern for finer-grained access control.此模式旨在实现单一租户内的细粒度访问控制。例如,控制组织内部的哪些部门、团队或角色可以访问哪些文档。它并不能替代多租户 SaaS 产品中的硬租户隔离。对于需要在不同客户或组织之间设置合规边界的跨租户隔离,请为每个租户提供专用的知识库,并使用 IAM 强制资源边界。在每个租户的知识库内,您可以再叠加此基于过滤的模式,以实现更细粒度的访问控制。
Use this pattern when:在以下情况下使用此模式:
- You need to control document access across departments, teams, or roles within a single organization.您需要在单一组织内部跨部门、团队或角色控制文档访问。
- Access rules change frequently and you want to update them without code redeployment.访问规则频繁变化且您希望在不重新部署代码的情况下更新它们。
- You want a single knowledge base instance to reduce cost and operational overhead for intra-tenant document segregation.您希望使用单一知识库实例来降低租户内文档隔离的成本和运维开销。
Do not use this pattern when:请勿在以下情况下使用此模式:
- You require hard isolation between separate customers or organizations (use a knowledge base per tenant with IAM boundaries instead).您需要在不同客户或组织之间实现硬隔离(请改为为每个租户使用带 IAM 边界的知识库)。
- Your compliance or audit requirements mandate infrastructure-level separation between data sets.您的合规或审计要求要求在基础设施层面对数据集进行分离。
- A failure of the filter mechanism would constitute a regulatory breach (filter-level isolation is a logical boundary, not a physical one).过滤机制的失效会导致监管违规(过滤级隔离是逻辑边界,而非物理边界)。
Residual risk, ingestion race condition: A brief window exists between document upload and sidecar creation. The ingestion safeguard (Step 1) reduces this by excluding documents without sidecars. However, if you modify the ingestion schedule to run continuously or with short intervals, verify that the batching window in Amazon Simple Queue Service (Amazon SQS) (default 30 seconds) provides sufficient time for the tagging Lambda to complete before the next ingestion cycle.残余风险,摄取竞争条件:在文档上传与 sidecar 创建之间存在短暂窗口。摄取保护(步骤 1)通过排除没有 sidecar 的文档来降低此风险。然而,如果您将摄取计划改为持续运行或短间隔,请确认 Amazon Simple Queue Service(Amazon SQS)的批处理窗口(默认 30 秒)能为标记 Lambda 完成提供足够时间,以免在下一个摄取周期前完成。
Prerequisites先决条件
Before implementing this pattern, you need:在实现此模式之前,您需要:
- Familiarity with Python, AWS Lambda, and infrastructure as code concepts.熟悉 Python、AWS Lambda 和基础设施即代码概念。
- An AWS account with AWS Identity and Access Management (AWS IAM) permissions to create AWS Lambda functions, an Amazon API Gateway REST API, Amazon Cognito user pools, Verified Permissions policy stores, and Amazon Bedrock Knowledge Bases.拥有具备创建 AWS Lambda 函数、Amazon API Gateway REST API、Amazon Cognito 用户池、Verified Permissions 策略存储以及 Amazon Bedrock 知识库权限的 AWS 账户。
- Amazon Cognito configured with department-based user groups (such as dept-a, dept-b, dept-c) and cognito:groups included in the JSON Web Token (JWT) issued to clients.已在 Amazon Cognito 中配置基于部门的用户组(如 dept-a、dept-b、dept-c),并在发放给客户端的 JSON Web Token(JWT)中包含 cognito:groups。
- Amazon Bedrock model access for the FMs you plan to use (such as Anthropic Claude 3 Haiku, and Amazon Nova Lite 2).拥有您计划使用的基础模型(如 Anthropic Claude 3 Haiku 和 Amazon Nova Lite 2)的 Amazon Bedrock 模型访问权限。
- A Verified Permissions policy store created and the Cedar schema defined (principals, resources, actions) before deployment.已创建 Verified Permissions 策略存储,并在部署前定义了 Cedar 模式(主体、资源、操作)。
- AWS Cloud Development Kit (AWS CDK) or AWS CloudFormation to deploy the infrastructure described in this walkthrough.使用 AWS Cloud Development Kit(AWS CDK)或 AWS CloudFormation 部署本文所述的基础设施。
- Sample documents prepared with department prefixes (such as docs/dept-a/report.pdf) for upload to Amazon S3.准备好带有部门前缀的示例文档(如 docs/dept-a/report.pdf),以便上传至 Amazon S3。
Important: Implementing this pattern creates billable AWS resources, including Amazon Bedrock Knowledge Bases, AWS Lambda functions, Amazon API Gateway, Amazon S3, Amazon Cognito, Amazon Verified Permissions, Amazon EventBridge, Amazon SQS, Amazon DynamoDB, AWS WAF, and Amazon CloudFront. Costs vary based on usage volume and AWS Region. Review AWS Pricing for each service before deploying and see the Cleaning up section at the end of this post to remove resources when testing is complete.重要提示:实现此模式会创建计费的 AWS 资源,包括 Amazon Bedrock 知识库、AWS Lambda 函数、Amazon API Gateway、Amazon S3、Amazon Cognito、Amazon Verified Permissions、Amazon EventBridge、Amazon SQS、Amazon DynamoDB、AWS WAF 和 Amazon CloudFront。费用取决于使用量和 AWS 区域。部署前请查看各服务的定价,并在测试完成后参考本文末尾的清理章节删除资源。
Solution overview解决方案概览
Serving many departments from one application shouldn’t mean giving every department access to every document. This solution keeps each department’s documents isolated inside a single Amazon Bedrock Knowledge Bases instance, so you avoid the cost and operational overhead of a knowledge base per team within that tenant. Metadata tags logically separate documents, and Verified Permissions acts as an externalized policy enforcement point, deciding which documents a user’s group or role is authorized to see on every request.让一个应用服务多个部门并不意味着让每个部门访问所有文档。此方案在单个 Amazon Bedrock 知识库实例内保持每个部门的文档隔离,从而避免为该租户内的每个团队单独部署知识库所带来的成本和运维负担。元数据标签在逻辑上分离文档,Verified Permissions 充当外部化的策略执行点,决定用户的组或角色在每次请求时有权查看哪些文档。
A key objective is to serve multiple departments within a single tenant from one Knowledge Base instance. If you had to provision a separate instance per department, it would multiply the infrastructure: separate data sources, ingestion pipelines and management overhead. A single knowledge base with metadata filtered access avoids this duplication while providing logical document isolation within the tenant boundary. Documents are logically separated by their metadata tags, and Verified Permissions provides a reliable, externalized policy enforcement point to determine which tags a user, in a specific group or role, is authorized to access.关键目标是使用单个知识库实例为单一租户内的多个部门提供服务。如果为每个部门单独配置实例,将导致基础设施成倍增长:需要单独的数据源、摄取管道和管理开销。通过元数据过滤的单一知识库避免了这种重复,同时在租户边界内提供逻辑文档隔离。文档通过元数据标签进行逻辑分离,Verified Permissions 作为可靠的外部化策略执行点,决定特定组或角色的用户可以访问哪些标签。
The ingestion pipeline tags documents with department metadata. Verified Permissions evaluates Cedar policies at query time to determine which department tags you are permitted to see. A middleware service (implemented as an AWS Lambda function) converts that policy decision into a metadata filter and uses this in the Amazon Bedrock RetrieveAndGenerate API. This API combines the retrieval and generation steps, returning a grounded response based on the filtered document set. The FM only processes documents that passed the filter.摄取管道为文档添加部门元数据标签。Verified Permissions 在查询时评估 Cedar 策略,以确定您被允许查看哪些部门标签。中间件服务(实现为 AWS Lambda 函数)将该策略决策转换为元数据过滤器,并在 Amazon Bedrock RetrieveAndGenerate API 中使用。该 API 将检索和生成步骤合并,返回基于过滤后文档集的可靠响应。基础模型仅处理通过过滤的文档。
Two independent layers enforce authorization:两层独立的授权层负责执行授权:
- Layer 1 (API access): A Lambda Authorizer on Amazon API Gateway calls Verified Permissions to decide whether you can invoke the API at all.层 1(API 访问):Amazon API Gateway 上的 Lambda Authorizer 调用 Verified Permissions,以决定您是否可以调用 API。
- Layer 2 (document access): A middleware Lambda, used to orchestrate the call to the Knowledge Base, also calls Verified Permissions to determine which Knowledge Base resources your department is permitted to query, then constructs a metadata filter accordingly.层 2(文档访问):用于编排对知识库调用的中间件 Lambda 也调用 Verified Permissions,以确定您的部门被允许查询哪些知识库资源,然后相应构建元数据过滤器。
Neither layer depends on the other for correctness. If Layer 1 were bypassed then Layer 2 is designed to enforce document-level isolation at the KB metadata filter.两层互不依赖。如果层 1 被绕过,层 2 仍设计为在 KB 元数据过滤器上强制文档级隔离。
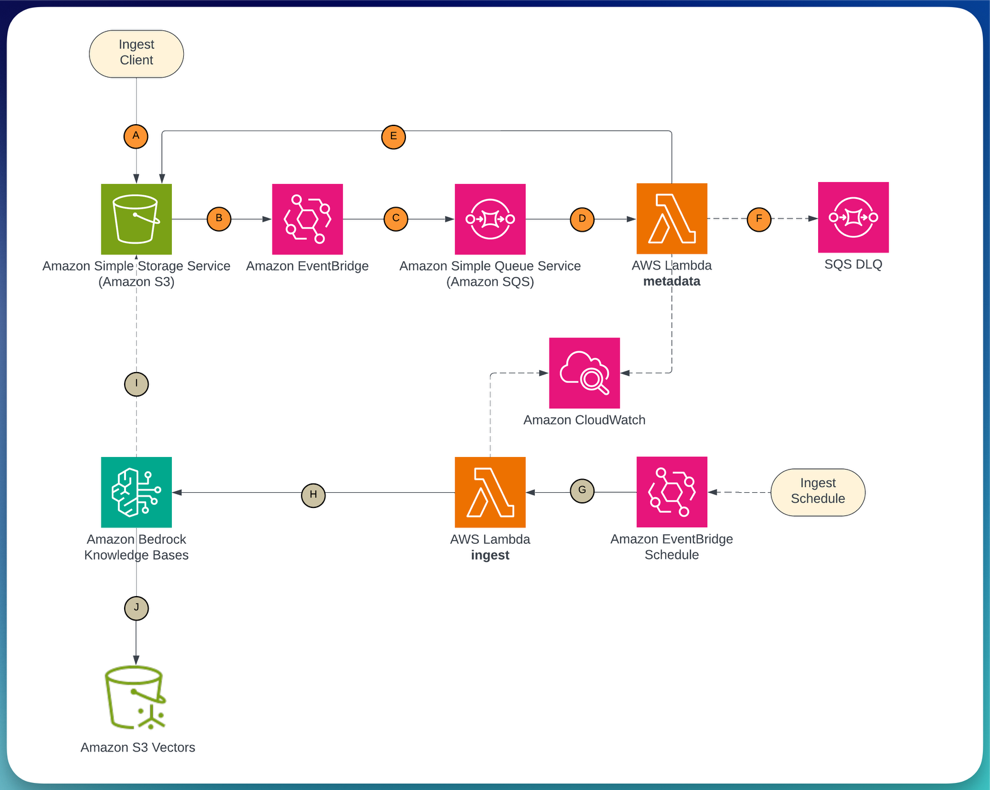
Figure 2 shows the ingestion pipeline: documents uploaded to Amazon Simple Storage Service (Amazon S3) trigger Amazon EventBridge, which routes through Amazon Simple Queue Service (Amazon SQS) to an AWS Lambda function that writes metadata. A scheduled Lambda then triggers the Amazon Bedrock Knowledge Bases ingestion job.图 2 展示了摄取管道:文档上传至 Amazon Simple Storage Service(Amazon S3)触发 Amazon EventBridge,随后通过 Amazon Simple Queue Service(Amazon SQS)路由至写入元数据的 AWS Lambda 函数。计划的 Lambda 再触发 Amazon Bedrock 知识库的摄取作业。
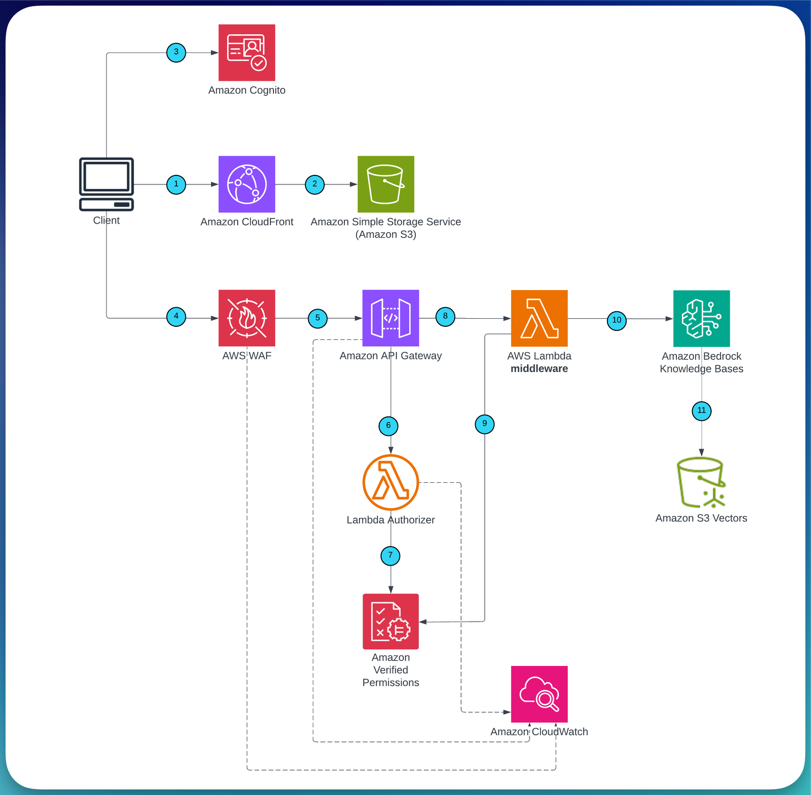
Figure 3 shows the query flow: a user request passes through Amazon CloudFront and AWS WAF to Amazon API Gateway, where the Lambda Authorizer evaluates Layer 1 (API-level) authorization against Verified Permissions. If permitted, the middleware Lambda evaluates Layer 2 (document-level) authorization, constructs the metadata filter, and calls RetrieveAndGenerate.图 3 展示了查询流程:用户请求经由 Amazon CloudFront 和 AWS WAF 进入 Amazon API Gateway,在此 Lambda Authorizer 对层 1(API 级)授权进行评估,调用 Verified Permissions。若获准,中间件 Lambda 评估层 2(文档级)授权,构建元数据过滤器并调用 RetrieveAndGenerate。
Authorization decision flow授权决策流程
| Step | Component | Decision | On deny |
| 1 | AWS WAF | Rate limit and rule check | Request blocked |
| 2 | Lambda Authorizer (Layer 1) | Can you invoke the API? | 403 returned |
| 3 | Middleware Lambda (Layer 2) | Which departments can you access? | Empty result set |
| 4 | Amazon Bedrock Knowledge Bases | Metadata filter applied to retrieval | Unauthorized docs excluded |
| 5 | Guardrails for Amazon Bedrock | Response grounded in retrieved context? | Response blocked or modified |
Key AWS services关键 AWS 服务
| Layer | Service | Role |
| Identity layer | Amazon Cognito | Issues JWTs with department group claims (cognito:groups) from the user pool |
| API security layer | AWS WAF | Applies rate limiting, IP filtering, and managed rule evaluation at the edge |
| Layer 1 authorization | Amazon Verified Permissions | Evaluates Cedar policies for API-level access decisions in the Lambda Authorizer |
| Layer 2 authorization | Amazon Verified Permissions | Evaluates Cedar policies for document-level access and drives metadata filter construction |
| RAG retrieval and FM invocation layer | Amazon Bedrock Knowledge Bases | Fully managed RAG capability that handles retrieval with metadata filtering and FM generation in a single API call |
| Ingestion layer | Amazon EventBridge, Amazon SQS | Event-driven pipeline for metadata sidecar tagging; Amazon SQS buffers upload spikes and routes failures to a dead-letter queue |
Technical implementation技术实现
The walkthrough presents ingestion pipeline first to tag and index your documents. You then move on to the Query Flow which contains the core authorization pattern. Each section following maps to a distinct component in the architecture.本指南首先展示摄取管道,以标记并索引文档。随后进入查询流程,包含核心授权模式。每个后续章节对应架构中的一个独立组件。
Step 1: Set up the event-driven ingestion pipeline with metadata tagging步骤 1:使用元数据标记设置事件驱动的摄取管道
For the metadata filter to work at query time, documents need to be tagged with their department before they are indexed. The ingestion pipeline handles this in two phases.为了让查询时的元数据过滤器生效,文档在索引前必须带有部门标签。摄取管道分两阶段处理。
Phase 1 (event-driven): When a document is uploaded to Amazon S3 under a department prefix (such as docs/dept-a/report.pdf), Amazon EventBridge fires an ObjectCreated event. The event routes through Amazon SQS to an AWS Lambda function that writes a .metadata.json sidecar file alongside the document.阶段 1(事件驱动):当文档上传至带有部门前缀的 Amazon S3(如 docs/dept-a/report.pdf)时,Amazon EventBridge 触发 ObjectCreated 事件。该事件通过 Amazon SQS 路由至 AWS Lambda 函数,在文档旁写入 .metadata.json sidecar 文件。
The Amazon SQS queue buffers bulk uploads and routes failed tagging attempts to a dead-letter queue for retry.Amazon SQS 队列缓冲批量上传,并将标记失败的事件路由至死信队列以供重试。
Phase 2 (scheduled): An Amazon EventBridge schedule triggers an ingestion Lambda every five minutes, which calls the StartIngestionJob API on the Amazon Bedrock Knowledge Bases data source. Amazon Bedrock reads the documents and their sidecars from Amazon S3, chunks them, generates embeddings, and indexes the vectors with the department attribute.阶段 2(计划):Amazon EventBridge 计划每五分钟触发一次摄取 Lambda,该 Lambda 调用 Amazon Bedrock 知识库数据源的 StartIngestionJob API。Amazon Bedrock 从 Amazon S3 读取文档及其 sidecar,进行分块、生成嵌入并使用部门属性对向量进行索引。
Tamper detection for metadata sidecars: Enable S3 Versioning on the document bucket and configure AWS CloudTrail S3 data events to log PutObject and DeleteObject calls. Create an Amazon CloudWatch Alarms metric filter that alerts when a PutObject to a .metadata.json key originates from principals other than the tagging Lambda role. For workloads with strict compliance requirements, consider S3 Object Lock in compliance mode to make sidecars immutable after creation – noting that document re-classification would then require a deliberate workflow to create a new version.元数据 sidecar 的篡改检测:在文档桶上启用 S3 版本控制,并配置 AWS CloudTrail S3 数据事件记录 PutObject 和 DeleteObject 调用。创建 Amazon CloudWatch 警报指标过滤器,当非标记 Lambda 角色的主体向 .metadata.json 键执行 PutObject 时触发警报。对于合规要求严格的工作负载,可考虑在合规模式下使用 S3 Object Lock,使 sidecar 在创建后不可变——但这意味着文档重新分类需要有意的工作流来创建新版本。
Upload prefix enforcement: The metadata tagging Lambda derives the department label from the S3 key prefix (for example, docs/dept-a/ → department: dept-a). To help prevent a user or process from uploading documents under another department’s prefix, scope upload permissions using an IAM policy condition:上传前缀强制:元数据标记 Lambda 从 S3 键前缀(例如 docs/dept-a/ → department: dept-a)派生部门标签。为防止用户或进程将文档上传至其他部门前缀,请使用 IAM 策略条件限制上传权限:
Each upload principal (whether a user role, CI/CD pipeline, or application) should carry a department tag that matches its permitted prefix. This helps prevent the tagging Lambda from being tricked into mislabeling a document by an upload to the wrong path.每个上传主体(无论是用户角色、CI/CD 管道还是应用)都应携带与其允许前缀匹配的部门标签。这有助于防止标记 Lambda 被误导而对错误路径的文档进行错误标记。
Ingestion safeguard: Before triggering the ingestion job, the scheduling Lambda lists objects under each department prefix and verifies that every document has a corresponding .metadata.json sidecar. Documents without a sidecar are excluded from the ingestion scope and logged to CloudWatch as untagged. This helps prevent an untagged document from being indexed without a department attribute, which could cause it to bypass metadata filters at query time. If your workload requires stricter guarantees, move untagged documents to a quarantine prefix and alert via Amazon Simple Notification Service (Amazon SNS).摄取保护:在触发摄取作业前,计划 Lambda 列出每个部门前缀下的对象,并验证每个文档都有对应的 .metadata.json sidecar。没有 sidecar 的文档会被排除在摄取范围之外,并记录到 CloudWatch 作为未标记文档。这可防止未标记文档在没有部门属性的情况下被索引,从而在查询时绕过元数据过滤。如果工作负载需要更严格的保证,可将未标记文档移动到隔离前缀,并通过 Amazon Simple Notification Service(Amazon SNS)发送警报。
S3 write restriction: Restrict s3:PutObject permission on the document bucket to the metadata tagging Lambda’s IAM execution role. All other principals – including application roles, CI/CD pipelines, and human operators should have at most s3:GetObject and s3:ListBucket. This helps prevent accidental or malicious modification of .metadata.json sidecar files, which could re-tag a document under a different department and expose it to unauthorized users on the next ingestion cycle. Use a bucket policy with an explicit deny for s3:PutObject that exempts only the tagging Lambda’s role ARN:S3 写入限制:将文档桶的 s3:PutObject 权限仅限于元数据标记 Lambda 的 IAM 执行角色。所有其他主体——包括应用角色、CI/CD 管道和人工操作员——最多只能拥有 s3:GetObject 和 s3:ListBucket 权限。这有助于防止意外或恶意修改 .metadata.json sidecar 文件,从而将文档重新标记为其他部门并在下次摄取时向未授权用户暴露。使用桶策略显式拒绝 s3:PutObject,仅对标记 Lambda 的角色 ARN 例外:
A 30-second batching window on the Amazon SQS event source means bulk uploads are processed together rather than one document per Lambda invocation. The two-phase separation helps confirm that department metadata sidecars are written before the ingestion job runs, reducing the risk of a race condition where a document might be indexed without a department tag.Amazon SQS 事件源的 30 秒批处理窗口意味着批量上传会一起处理,而不是每个文档单独触发 Lambda。两阶段分离有助于确认在摄取作业运行前已写入部门元数据 sidecar,降低文档在没有部门标签的情况下被索引的竞争风险。
Implementation note: Deploy this as the handler for your metadata tagging AWS Lambda function (Python 3.12 runtime). Set the BUCKET environment variable. The function’s IAM execution role requires s3:PutObject permission on the document bucket.实现说明:将此代码部署为元数据标记 AWS Lambda 函数的处理程序(Python 3.12 运行时)。设置 BUCKET 环境变量。函数的 IAM 执行角色需要对文档桶拥有 s3:PutObject 权限。
Step 2: Configure Amazon Bedrock Knowledge Bases步骤 2:配置 Amazon Bedrock 知识库
With Amazon Bedrock Knowledge Bases, you configure document chunking, embedding model selection, vector indexing, and metadata filtering without managing the underlying infrastructure. You configure a data source backed by the same Amazon S3 bucket as the ingestion pipeline.使用 Amazon Bedrock 知识库,您可以配置文档分块、嵌入模型选择、向量索引和元数据过滤,而无需管理底层基础设施。您需要配置一个数据源,指向与摄取管道相同的 Amazon S3 桶。
Amazon Bedrock Knowledge Bases chunks documents at 300 tokens with 20% overlap (the default, which works well for structured enterprise documents). An embedding model, such as Amazon Titan Text Embeddings V2, generates the embeddings. The metadata attributes defined in the .metadata.json sidecar files are indexed alongside the vectors, making them available as pre-filters on the RetrieveAndGenerate call.Amazon Bedrock 知识库以 300 token 为单位进行文档分块,重叠率为 20%(默认值,适用于结构化企业文档)。嵌入模型可使用 Amazon Titan Text Embeddings V2。.metadata.json sidecar 中定义的元数据属性会与向量一起索引,可在 RetrieveAndGenerate 调用时作为预过滤器使用。
Step 3: Define the Cedar schema and policies in Amazon Verified Permissions步骤 3:在 Amazon Verified Permissions 中定义 Cedar 模式和策略
Verified Permissions provides fine-grained authorization through Cedar, a purpose-built policy language. The Cedar schema defines three entity types for this solution:Verified Permissions 通过 Cedar 提供细粒度授权。Cedar 模式为本方案定义了三种实体类型:
- Principal: GenAIApp::UserGroup (the department group extracted from the JWT)主体:GenAIApp::UserGroup(从 JWT 中提取的部门组)
- Action: query (retrieves documents from a knowledge base) and invokeModel (calls an FM)操作:query(从知识库检索文档)和 invokeModel(调用基础模型)
- Resource: GenAIApp::KnowledgeBase and GenAIApp::Model资源:GenAIApp::KnowledgeBase 和 GenAIApp::Model
The namespace GenAIApp is a custom prefix you define when creating the Cedar schema. You can replace it with your own application namespace (such as MyCompany or RAGApp).命名空间 GenAIApp 是您在创建 Cedar 模式时自定义的前缀。您可以用自己的应用命名空间(如 MyCompany 或 RAGApp)替代。
The following six policies cover the three departments used in this walkthrough. Department C has a cross-department access grant that covers each Knowledge Base resource, which suits a leadership or executive group:以下六个策略覆盖本演练中使用的三个部门。部门 C 拥有跨部门访问授权,覆盖每个知识库资源,适用于领导或高管组:
// dept-a: query own knowledge base + use Claude 3 Haiku
permit(
    principal in GenAIApp::UserGroup::"dept-a",
    action == GenAIApp::Action::"query",
    resource == GenAIApp::KnowledgeBase::"dept-a"
);

permit(
    principal in GenAIApp::UserGroup::"dept-a",
    action == GenAIApp::Action::"invokeModel",
    resource == GenAIApp::Model::"anthropic.claude-3-haiku-20240307-v1:0"
);

// dept-b: query own knowledge base + use Claude 3 Haiku
permit(
    principal in GenAIApp::UserGroup::"dept-b",
    action == GenAIApp::Action::"query",
    resource == GenAIApp::KnowledgeBase::"dept-b"
);

permit(
    principal in GenAIApp::UserGroup::"dept-b",
    action == GenAIApp::Action::"invokeModel",
    resource == GenAIApp::Model::"anthropic.claude-3-haiku-20240307-v1:0"
);

// dept-c: cross-department access + use Amazon Nova Lite 2
permit(
    principal in GenAIApp::UserGroup::"dept-c",
    action == GenAIApp::Action::"query",
    resource
);

permit(
    principal in GenAIApp::UserGroup::"dept-c",
    action == GenAIApp::Action::"invokeModel",
    resource == GenAIApp::Model::"amazon.nova-2-lite-v1:0"
);
To adapt these policies for your organization, replace the department identifiers (dept-a, dept-b, dept-c) with your own group names. The pattern supports multiple access models: per-team, per-project, or hierarchical. For temporary access grants, add a Cedar policy with a when condition that evaluates a time-based attribute, and remove the policy when access should expire.要将这些策略适配到您的组织,请将部门标识符(dept-a、dept-b、dept-c)替换为您自己的组名。该模式支持多种访问模型:按团队、按项目或层级结构。对于临时访问授权,可在 Cedar 策略中添加基于时间属性的 when 条件,并在访问到期时删除策略。
Policy changes take effect on the next API call. You do not need a Lambda redeployment or AWS CDK update.策略更改将在下一个 API 调用时生效。您无需重新部署 Lambda 或更新 AWS CDK。
Policy governance: Because Cedar policy changes take effect immediately, restrict who can modify policies in production. Apply IAM conditions on verifiedpermissions:CreatePolicy, UpdatePolicy, and DeletePolicy so that only a dedicated CI/CD pipeline role or a small set of authorized administrators can mutate the policy store. Enable AWS CloudTrail logging for Verified Permissions API calls and create a CloudWatch Alarm that triggers when policy mutation events occur outside your change management workflow. For production deployments, validate Cedar policies against test scenarios in a non-production policy store before promoting them. Treat policy changes with the same rigor as application code deployments.策略治理:由于 Cedar 策略更改会立即生效,请限制生产环境中谁可以修改策略。对 verifiedpermissions:CreatePolicy、UpdatePolicy 和 DeletePolicy 应用 IAM 条件,仅允许专用的 CI/CD 管道角色或少数授权管理员修改策略存储。为 Verified Permissions API 调用启用 AWS CloudTrail 日志,并创建 CloudWatch 警报,以在策略变更事件发生在变更管理工作流之外时触发。生产部署前,请在非生产策略存储中对 Cedar 策略进行测试场景验证后再推广。将策略更改视同代码部署,保持同等严谨性。
Step 4: Configure Layer 1: API-level authorization (Lambda Authorizer)步骤 4:配置层 1:API 级授权(Lambda Authorizer)
When a request arrives at Amazon API Gateway, the Lambda Authorizer runs before your application logic. It validates the JWT signature against the Amazon Cognito JSON Web Key Set (JWKS) endpoint, then calls Verified Permissions IsAuthorized with your group membership. This is the traditional “authorization/access level” check: it verifies that you are allowed to invoke the API, not which documents you can access.当请求到达 Amazon API Gateway 时,Lambda Authorizer 在业务逻辑之前运行。它使用 Amazon Cognito 的 JSON Web Key Set(JWKS)端点验证 JWT 签名,然后调用 Verified Permissions 的 IsAuthorized 并传入您的组成员信息。这是传统的“授权/访问级别”检查:它验证您是否被允许调用 API,而不是您可以访问哪些文档。
The authorizer denies access by default. If Verified Permissions is unavailable, the function raises an exception and Amazon API Gateway returns a 403.Authorizer 默认拒绝访问。如果 Verified Permissions 不可用,函数会抛出异常,Amazon API Gateway 返回 403。
Implementation note: Deploy this as a Lambda Authorizer (TOKEN type) on your Amazon API Gateway REST API. Set the TTL on the authorizer cache to 0 during testing so that policy changes take effect immediately.实现说明:将此代码部署为您的 Amazon API Gateway REST API 上的 Lambda Authorizer(TOKEN 类型)。在测试期间将 authorizer 缓存的 TTL 设置为 0,以便策略更改立即生效。
Production cache TTL: In production, the API Gateway authorizer cache TTL controls how quickly policy revocations take effect. A TTL of 0 means every request triggers a fresh Verified Permissions evaluation. Revocations are immediate but latency increases. A TTL of 300 seconds (the API Gateway default) improves latency but means a revoked policy could continue to permit access for up to 5 minutes. For workloads where timely revocation matters (for example an employee offboarding or incident response), set the TTL to 0 or a deliberately short value (for example, 30–60 seconds) and accept the additional Verified Permissions API calls. The claim that “policy changes take effect on the next API call” holds true only when the authorizer cache TTL is zero or the cached entry has expired.生产缓存 TTL:在生产环境中,API Gateway authorizer 缓存 TTL 决定策略撤销的生效速度。TTL 为 0 表示每个请求都会触发全新的 Verified Permissions 评估,撤销即时生效但会增加延迟。TTL 为 300 秒(API Gateway 默认)可提升延迟,但撤销的策略可能在最多 5 分钟内仍然有效。对于撤销时效性重要的工作负载(如员工离职或事件响应),请将 TTL 设为 0 或较短值(如 30–60 秒),并接受额外的 Verified Permissions API 调用。只有在 authorizer 缓存 TTL 为零或缓存条目已过期时,“策略更改在下一个 API 调用时生效”才成立。
Multi-group membership: A user may belong to more than one Cognito group. For example, an employee who is a member of both dept-a and a cross-functional leadership group. The authorizer evaluates the group memberships present in the JWT and permits the API call if a group has a matching Cedar permit policy. This helps prevent arbitrary access restrictions based on the order in which groups appear in the token. Document-level access is then determined independently at Layer 2, where the middleware evaluates each department resource against the user’s groups to construct the appropriate metadata filter.多组成员资格:用户可能属于多个 Cognito 组。例如,某员工同时是 dept-a 组和跨职能领导组的成员。Authorizer 会评估 JWT 中的组成员信息,只要任意一个组匹配 Cedar 许可策略,即允许 API 调用。这有助于防止基于组在令牌中出现顺序的任意访问限制。文档级访问随后在层 2 独立决定,middleware 根据用户的组对每个部门资源进行评估,以构建相应的元数据过滤器。
For error handling patterns, implement exponential backoff with jitter on the Verified Permissions API call. Log authorization decisions to Amazon CloudWatch for monitoring and auditing.错误处理模式:对 Verified Permissions API 调用实现带抖动的指数退避。将授权决策记录到 Amazon CloudWatch,以便监控和审计。
Step 5: Configure Layer 2: Document-level authorization (middleware Lambda)步骤 5:配置层 2:文档级授权(middleware Lambda)
Once a request passes Layer 1, the middleware Lambda runs a second, independent Verified Permissions evaluation. This time, it checks which KB resources you are permitted to query based on your group membership, then translates the decision directly into a metadata filter on the RetrieveAndGenerate call.请求通过层 1 后,middleware Lambda 进行第二次独立的 Verified Permissions 评估。这一次,它检查基于您的组成员资格,您被允许查询哪些 KB 资源,然后直接将决策转换为 RetrieveAndGenerate 调用中的元数据过滤器。
Amazon Bedrock Knowledge Bases applies the metadata filter before the vector similarity search runs. This means the FM processes only documents you are authorized to access. The filter helps prevent unauthorized documents from appearing in the retrieval set.Amazon Bedrock 知识库在向量相似度搜索运行前应用元数据过滤器。这意味着基础模型仅处理您被授权访问的文档。过滤器帮助防止未授权文档出现在检索集合中。
Department access model部门访问模型
| Group | Foundation model | Knowledge base access |
| dept-a | Claude 3 Haiku | Department A documents only |
| dept-b | Claude 3 Haiku | Department B documents only |
| dept-c | Amazon Nova Lite 2 | Multiple departments (A, B, and C) |
Implementation note: Deploy this as the handler for your middleware AWS Lambda function (Python 3.12 runtime). Set environment variables POLICY_STORE_ID and KB_ID. The function’s IAM execution role requires verifiedpermissions:IsAuthorized and bedrock:RetrieveAndGenerate permissions.实现说明:将此代码部署为您的 middleware AWS Lambda 函数的处理程序(Python 3.12 运行时)。设置环境变量 POLICY_STORE_ID 和 KB_ID。函数的 IAM 执行角色需要拥有 verifiedpermissions:IsAuthorized 和 bedrock:RetrieveAndGenerate 权限。
The FM selection uses the same Verified Permissions policy store. Cedar policies that grant invokeModel access determine which model ID the middleware passes to Amazon Bedrock, so model access control is driven by the same externalized policies as document access.模型选择同样使用 Verified Permissions 策略存储。授予 invokeModel 访问的 Cedar 策略决定 middleware 向 Amazon Bedrock 传递的模型 ID,因此模型访问控制也由相同的外部化策略驱动。
Security note: The metadata filter excludes unauthorized documents from the retrieval set before the FM processes them. If a user queries for another department’s data, the request returns no relevant results. To monitor for unexpected retrieval behavior, use Amazon CloudWatch logging on the middleware AWS Lambda function.安全说明:元数据过滤器在基础模型处理之前就排除了未授权文档。如果用户查询其他部门的数据,请求将返回无相关结果。为监控异常检索行为,请在 middleware AWS Lambda 函数上启用 Amazon CloudWatch 日志。
Benefits of two independent authorization layers两层独立授权的优势
| Layer 1 (API Gateway) | Layer 2 (Middleware Lambda) | |
| Question answered | Can you invoke the API? | Which documents can your department access? |
| Enforcement point | Before application logic runs | At Amazon Bedrock Knowledge Bases metadata filter |
| Failure mode | 403 returned to you | Empty or filtered result set |
Availability trade-off: Both layers depend on Amazon Verified Permissions. If the service is throttled or unavailable, the deny-by-default design means users are denied access. This is the correct and intended secure behavior. For most workloads, a brief period of denial is preferable to failing open. If your application has strict availability requirements, consider implementing exponential backoff with jitter on all IsAuthorized calls (in both the Lambda Authorizer and the middleware Lambda) to handle transient throttling gracefully. A circuit-breaker that falls back to cached last-known-good authorization decisions can improve availability, but introduces a window where revoked access may still be honored. Document this trade-off explicitly if you adopt it, and make sure cached decisions expire on a short TTL.可用性权衡:两层均依赖 Amazon Verified Permissions。如果服务被限流或不可用,默认拒绝的设计意味着用户被拒绝访问。这是正确且预期的安全行为。对大多数工作负载而言,短暂的拒绝比开放更可取。如果您的应用对可用性要求严格,请在所有 IsAuthorized 调用(包括 Lambda Authorizer 和 middleware Lambda)上实现带抖动的指数退避,以优雅地处理瞬时限流。使用电路断路器回退到缓存的最近一次有效授权决策可以提升可用性,但会引入已撤销访问仍被允许的窗口。若采用此方案,请明确记录权衡,并确保缓存决策具有短 TTL。
Step 6: Add Guardrails for Amazon Bedrock as an output safety layer步骤 6:为 Amazon Bedrock 添加 Guardrails 作为输出安全层
Guardrails for Amazon Bedrock applies contextual source fidelity checks and content filtering as a complementary safety layer. Where Verified Permissions controls which documents the FM accesses, Guardrails evaluates the FM’s response before it’s returned to you.Guardrails for Amazon Bedrock 提供上下文来源可信度检查和内容过滤,作为补充安全层。Verified Permissions 控制基础模型访问哪些文档,Guardrails 则在返回之前评估模型的响应。
Contextual source fidelity checks help confirm that the response stays faithful to the retrieved documents rather than drawing from the FM’s pre-training data. Combine this with the metadata filter from Layer 2 for a complete defense in depth approach: authorization restricts the retrieval set, and Guardrails validates the generated output.上下文来源可信度检查帮助确认响应忠实于检索到的文档,而不是来源于模型的预训练数据。将其与层 2 的元数据过滤相结合,可实现完整的防御深度:授权限制检索集合,Guardrails 验证生成的输出。
The Guardrail configuration in the RetrieveAndGenerate call applies two checks:RetrieveAndGenerate 调用中的 Guardrail 配置包含两项检查:
- Contextual grounding: Helps limit responses that extrapolate beyond the retrieved context. This supports factual accuracy tied to your documents.上下文接地:帮助限制超出检索上下文的响应,支持基于文档的事实准确性。
- Content filtering: Blocks responses containing harmful or inappropriate content based on your configured thresholds.内容过滤:根据您配置的阈值阻止包含有害或不适当内容的响应。
You apply the Guardrail in the RetrieveAndGenerate call by passing the guardrailConfiguration parameter with your Guardrail ID and version. Contextual grounding helps mitigate prompt injection by limiting responses to the retrieved context but does not eliminate all injection vectors. For additional defense, validate input length and sanitize queries before passing them to RetrieveAndGenerate. For more information, see the Guardrails for Amazon Bedrock documentation.您在 RetrieveAndGenerate 调用中通过传入 guardrailConfiguration 参数并指定 Guardrail ID 与版本来应用 Guardrail。上下文接地有助于通过限制响应到检索上下文来缓解提示注入,但并不能消除所有注入向量。为进一步防御,请在将查询传递给 RetrieveAndGenerate 前验证输入长度并对查询进行清理。更多信息请参阅 Guardrails for Amazon Bedrock 文档。
Step 7: Test the end-to-end authorization flow步骤 7:测试端到端授权流程
With the solution deployed, here is what happens when a dept-a user submits a query:部署解决方案后,dept-a 用户提交查询时的流程如下:
- A user submits a query using a web application with Authorization: Bearer through Amazon CloudFront to AWS WAF.用户使用带 Authorization: Bearer 的 Web 应用提交查询,经过 Amazon CloudFront 和 AWS WAF。
- AWS WAF applies rate limiting and managed rules, then forwards clean traffic to Amazon API Gateway.AWS WAF 应用速率限制和托管规则,然后将干净流量转发至 Amazon API Gateway。
- The Lambda Authorizer validates the JWT and calls Verified Permissions. The dept-a group has a query permit policy, so the call is allowed.Lambda Authorizer 验证 JWT 并调用 Verified Permissions。dept-a 组拥有 query 许可策略,调用被允许。
- The middleware Lambda calls Verified Permissions for each Knowledge Base resource. Only dept-a is permitted, so the filter {“equals”: {“key”: “department”, “value”: “dept-a”}} is constructed.middleware Lambda 为每个知识库资源调用 Verified Permissions。仅 dept-a 被允许,于是构建过滤器 {"equals": {"key": "department", "value": "dept-a"}}。
- The middleware calls RetrieveAndGenerate with the metadata filter applied. Amazon Bedrock Knowledge Bases filters the document set before running the vector similarity search.middleware 调用带有元数据过滤器的 RetrieveAndGenerate。Amazon Bedrock 知识库在向量相似度搜索前过滤文档集合。
- Department B and C documents are excluded from the search space. The FM generates a response that stays grounded only in Department A documents.部门 B 和 C 的文档被排除在搜索空间之外。基础模型仅生成基于部门 A 文档的响应。
- The response is checked by Guardrails for Amazon Bedrock before it is returned.响应在返回前由 Guardrails for Amazon Bedrock 检查。
To test, use the following curl command with a valid JWT from Amazon Cognito:测试时,请使用以下 curl 命令并提供有效的 Amazon Cognito JWT:
A successful dept-a request returns a response grounded in Department A documents only. If authorization fails at Layer 1, you receive a 403 response. If Layer 2 finds no permitted resources, the function returns a PermissionError.成功的 dept-a 请求仅返回基于部门 A 文档的响应。如果层 1 授权失败,将收到 403 响应;如果层 2 未找到允许的资源,函数将返回 PermissionError。
Monitor authorization decisions in Amazon CloudWatch Logs for both the Lambda Authorizer and middleware functions. Set up CloudWatch metric filters and alarms for the following:在 Amazon CloudWatch Logs 中监控 Lambda Authorizer 和 middleware 函数的授权决策。为以下项目设置 CloudWatch 指标过滤器和警报:
- Authorization deny rate (Layer 1 and Layer 2) – a spike may indicate credential probing, misconfigured clients, or a policy error.授权拒绝率(层 1 与层 2)——激增可能表明凭证探测、客户端配置错误或策略错误。
- Verified Permissions latency – sustained increases may signal throttling.Verified Permissions 延迟——持续上升可能表明限流。
- SQS dead-letter queue message count – messages in the DLQ indicate failed metadata tagging events that need attention.SQS 死信队列消息计数——DLQ 中的消息表示元数据标记事件失败,需要关注。
- Ingestion job failure rate – alerts you to documents that were not indexed.摄取作业失败率——提醒您有文档未被索引。
AWS CloudTrail automatically logs Verified Permissions IsAuthorized calls, providing an audit trail of every authorization decision without additional configuration.AWS CloudTrail 会自动记录 Verified Permissions IsAuthorized 调用,为每个授权决策提供审计日志,无需额外配置。
To observe the live policy update behavior, grant a dept-a Cedar policy that allows access to dept-b resources, then immediately resubmit the query. The next API call reflects the change. Revoke the policy and the restriction is restored on the following call.要观察实时策略更新行为,授予 dept-a Cedar 策略以访问 dept-b 资源,然后立即重新提交查询。下一个 API 调用会反映更改。撤销策略后,随后的调用将恢复限制。
Single knowledge base with metadata isolation单一知识库的元数据隔离
Adding a department requires adding a Cedar policy and tagging new documents. You do not need to provision additional infrastructure, deploy new stacks, or manage separate ingestion pipelines. The FM is presented with only the authorized document subset based on the applied metadata pre-filter.添加部门只需添加 Cedar 策略并标记新文档。无需再配置额外基础设施、部署新堆栈或管理单独的摄取管道。基础模型仅接收基于元数据预过滤后的授权文档子集。
For session management, use an Amazon DynamoDB table with a session TTL to maintain conversation context across requests. The RetrieveAndGenerate API accepts a sessionId parameter that manages multi-turn context automatically. Generate session IDs using a cryptographically random value (for example, uuid4) and bind each session to the authenticated user’s identity and group at creation time.会话管理可使用带 TTL 的 Amazon DynamoDB 表,以在请求之间维护对话上下文。RetrieveAndGenerate API 接受 sessionId 参数,可自动管理多轮对话。使用加密随机值(例如 uuid4)生成会话 ID,并在创建时将每个会话绑定到已认证用户的身份和组。
On every subsequent request, validate that the bearer token’s subject and group claims match the session owner before continuing the conversation. Invalidate sessions when a user’s group membership changes or their token is revoked and set a TTL appropriate to your use case (for example, 30 minutes of inactivity).在后续每次请求中,验证 bearer token 的 subject 和 group 声明是否与会话所有者匹配后再继续对话。当用户的组成员资格变化或令牌被撤销时,请使会话失效,并根据使用场景设置合适的 TTL(例如 30 分钟不活动)。
Cleaning up清理
If you deployed resources individually, delete them in the following order to avoid dependency errors:如果您单独部署了资源,请按以下顺序删除,以避免依赖错误:
- Amazon CloudFront distribution and AWS WAF web ACL.Amazon CloudFront 分配和 AWS WAF Web ACL。
- Amazon API Gateway REST API (this also removes the Lambda Authorizer association).Amazon API Gateway REST API(这也会移除 Lambda Authorizer 关联)。
- AWS Lambda functions (metadata tagging, authorizer, middleware).AWS Lambda 函数(元数据标记、授权器、中间件)。
- Amazon Bedrock Knowledge Base and its associated data source.Amazon Bedrock 知识库及其关联的数据源。
- Amazon S3 bucket — empty the bucket first. If versioning is enabled, delete all object versions and delete markers before removing the bucket.Amazon S3 存储桶——先清空存储桶。如果已启用版本控制,请在删除存储桶之前删除所有对象版本和删除标记。
- Amazon EventBridge rule and Amazon SQS queue.Amazon EventBridge 规则和 Amazon SQS 队列。
- Amazon DynamoDB table.Amazon DynamoDB 表。
- Amazon Verified Permissions policy store.Amazon Verified Permissions 策略存储。
- Amazon Cognito user pool (if created specifically for this pattern).Amazon Cognito 用户池(如果专门为此模式创建)。
- IAM roles and policies created for the Lambda functions and API Gateway.为 Lambda 函数和 API Gateway 创建的 IAM 角色和策略。
- Amazon CloudWatch log groups for each Lambda function.每个 Lambda 函数的 Amazon CloudWatch 日志组。
Warning: Deleting these resources is irreversible. Back up any documents in S3, DynamoDB data, or Verified Permissions policies you may need before proceeding.警告:删除这些资源是不可逆的。在继续之前,请备份 S3 中的文档、DynamoDB 数据或可能需要的 Verified Permissions 策略。
Conclusion结论
You now have a working defense-in-depth authorization pattern for granular, intra-tenant document access control in RAG applications that you built on Amazon Bedrock. With this approach, you can: change access policies at runtime without redeploying code, maintain logical document-level isolation that remains effective even if the API layer is misconfigured, and audit every authorization decision from a single Verified Permissions policy store.您现在拥有一个可工作的深度防御授权模式,用于在基于 Amazon Bedrock 构建的 RAG 应用中实现细粒度的租户内文档访问控制。通过此方法,您可以:在运行时更改访问策略而无需重新部署代码,保持逻辑上的文档级隔离,即使 API 层配置错误仍然有效,并且可以从单一的 Verified Permissions 策略存储中审计每一次授权决策。
Key takeaways关键要点
- Updates without redeployment. Cedar policies in Verified Permissions are human-readable, version-controlled outside your Lambda code, and take effect on the next API call. You can revoke a department’s access or grant cross-department access to an executive group by updating a policy in the Verified Permissions console.无需重新部署即可更新。Verified Permissions 中的 Cedar 策略是人类可读的,版本受控于 Lambda 代码之外,并在下一个 API 调用时生效。您可以通过在 Verified Permissions 控制台中更新策略,撤销部门的访问权限或为执行团队授予跨部门访问权限。
- Cost-effective document isolation without infrastructure duplication. A single Amazon Bedrock Knowledge Bases instance with metadata pre-filtering delivers logical isolation between departments within a tenant, at a fraction of the cost and operational overhead of separate instances. Note that this is filter-level isolation, not infrastructure-level isolation – for hard tenant boundaries, use a dedicated knowledge base per tenant.成本效益高的文档隔离,无需复制基础设施。单个 Amazon Bedrock 知识库实例通过元数据预过滤实现租户内部门之间的逻辑隔离,成本和运维开销仅为独立实例的一小部分。请注意,这是一种过滤级别的隔离,而非基础设施级别的隔离——如需严格的租户边界,请为每个租户使用专用知识库。
- Independent enforcement layers help reduce the risk of a single point of failure. Layer 1 (Lambda Authorizer) and Layer 2 (middleware Lambda) enforce independent policy checks. Both call Verified Permissions separately, and both fail closed (deny by default).独立的强制执行层有助于降低单点故障的风险。第 1 层(Lambda 授权器)和第 2 层(中间件 Lambda)执行独立的策略检查。两者均单独调用 Verified Permissions,并且均采用闭合失败(默认拒绝)。
Next steps下一步
To extend this pattern further:进一步扩展此模式:
- Recommended first step: Test with your own documents. Replace the sample department documents with your own content, upload them under the appropriate prefix, and verify that the metadata filter isolates them correctly.推荐的第一步:使用您自己的文档进行测试。将示例部门文档替换为您自己的内容,上传到相应前缀下,并验证元数据过滤能够正确隔离它们。
- Add a fourth department. Create a new Cedar policy, add a user group in Amazon Cognito, and upload tagged documents to validate that the pattern scales without code changes.添加第四个部门。创建新的 Cedar 策略,在 Amazon Cognito 中添加用户组,并上传带标签的文档,以验证该模式在无需代码更改的情况下能够扩展。
- Extend to agent tool authorization with Amazon Bedrock AgentCore. The Policy feature uses the same Cedar language to enforce fine-grained authorization on agent tool calls and gateways.将其扩展到使用 Amazon Bedrock AgentCore 的代理工具授权。Policy 功能使用相同的 Cedar 语言,对代理工具调用和网关实施细粒度授权。
- Add attribute-based access control (ABAC). Extend Cedar policies to evaluate user attributes beyond group membership, such as project assignment, clearance level, or geographic location.添加基于属性的访问控制(ABAC)。将 Cedar 策略扩展为评估用户属性,而不仅限于组成员资格,例如项目分配、授权级别或地理位置。
- Integrate with your identity provider. Replace Amazon Cognito with your enterprise identity provider (such as Okta or Microsoft Entra ID) by configuring a Verified Permissions identity source.与您的身份提供商集成。通过配置 Verified Permissions 身份源,将 Amazon Cognito 替换为您的企业身份提供商(如 Okta 或 Microsoft Entra ID)。
- Automate policy testing. Build a Continuous Integration/Continuous Deployment (CI/CD) pipeline that validates Cedar policies against test scenarios before deploying them to the policy store.自动化策略测试。构建持续集成/持续部署(CI/CD)流水线,在将 Cedar 策略部署到策略存储之前,对其进行测试场景验证。
Related resources相关资源
- Multi-tenancy in RAG applications in a single Amazon Bedrock knowledge base with metadata filtering (AWS Machine Learning Blog, April 2025)在单个 Amazon Bedrock 知识库中通过元数据过滤实现 RAG 应用的多租户(AWS Machine Learning Blog,2025 年 4 月)
- Amazon Verified Permissions documentationAmazon Verified Permissions 文档
- Amazon Bedrock Knowledge Bases documentationAmazon Bedrock 知识库文档
- Amazon Bedrock Knowledge Bases with metadata filtering (AWS Machine Learning Blog, July 2024)带元数据过滤的 Amazon Bedrock 知识库(AWS Machine Learning Blog,2024 年 7 月)
- Design secure generative AI application workflows with Amazon Verified Permissions and Amazon Bedrock Agents (AWS Machine Learning Blog, October 2024)使用 Amazon Verified Permissions 和 Amazon Bedrock Agents 设计安全的生成式 AI 应用工作流(AWS Machine Learning Blog,2024 年 10 月)
- Authorizing access to data with RAG implementations (AWS Security Blog, September 2025)通过 RAG 实现对数据的授权访问(AWS Security Blog,2025 年 9 月)
- Cedar policy language documentationCedar 策略语言文档